There is no doubt that the SPS-C01 certification in a popular exam in the industry. And, SPS-C01 is one of the most demanded certifications by the Cisco. We at VCEDumps, provide the money back guarantee on our SPS-C01 practice exam questions and training material. Our SPS-C01 certified professional team continuously works on updated exam content with Latest SPS-C01 Questions. If you want to clear the SPS-C01 exam in the best way, then you can utilize the best quality products and services provided by us. Our SPS-C01 PDF questions have all the updated question answers for SPS-C01 exams.
| Section | Objectives |
|---|---|
| Topic 1: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 2: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 3: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 4: Data Engineering with Snowpark | - Pipeline development
|
| Topic 5: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 6: DataFrame Operations and Data Processing | - Data transformation workflows
|
>> Snowflake SPS-C01 Trusted Exam Resource <<
Don't waste your time with unhelpful study methods. There are plenty of options available, but not all of them are suitable to help you pass the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam. Some resources out there may even do more harm than good by leading you astray. Our Snowflake SPS-C01 Exam Dumps are available with a free demo and up to 1 year of free updates.
NEW QUESTION # 184
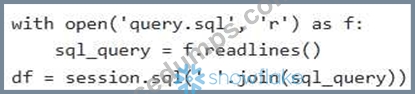
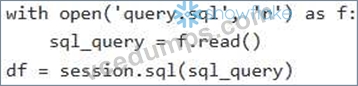
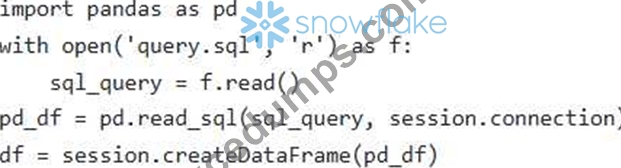
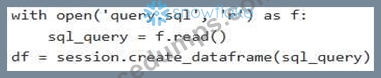
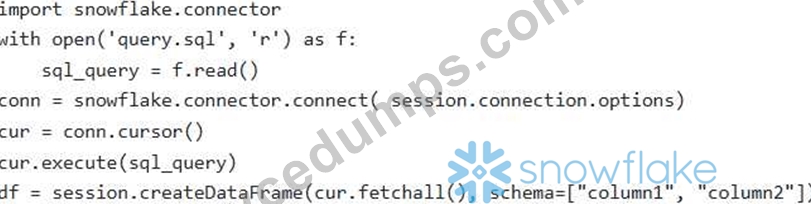
You have a SQL query stored in a file named 'query.sqr which contains several complex analytical calculations. The query depends on a Snowpark 'session' object already established. You want to create a Snowpark DataFrame from the result of this query. Which of the following code snippets achieves this with optimal performance and readability, assuming correct file access permissions?
Answer: B
Explanation:
Option A provides the most straightfomard and efficient approach. It reads the SQL query from the file and directly creates a Snowpark DataFrame using 'session.sql(sql_query)'. Option B introduces Pandas, which is unnecessary and less efficient. Option C uses the Snowflake Connector outside of Snowpark's API, which is generally not the preferred approach. Option D has a non-existent function create_dataframe' , and Option E reads lines separately requiring a join which might be erroneous.
NEW QUESTION # 185
You are developing a Snowpark application that requires secure access to Snowflake. You need to establish a session using Key Pair authentication. You have stored your private key in an encrypted file and have the passphrase available. Assume you've correctly configured your Snowflake user with the public key. Which of the following methods can be used to load the private key, assuming that 'PRIVATE KEY PATH' stores path to encrypted private key and 'PRIVATE KEY PASSPHRASE stores passphrase?





Answer: A,B
Explanation:
The correct answers are B and E. B: This option correctly loads an encrypted private key from a file using the 'cryptography' library, specifying the passphrase and backend. E: Option E directly utilizes snowflake.connector.read_private_key functionality simplifying the process if using snowflake-connector. Option A fails to specify the backend for the serialization, which is necessary for certain key types and may lead to errors. Option C simply reads the key as a string without decryption. Option D assumes the private key is stored in an environment variable, which does not include any decryption.
NEW QUESTION # 186
Consider a Snowflake table 'orders' with columns 'order_id', 'customer_id', 'order_date', and 'status'. You need to update the 'status' of all orders placed before January 1, 2023, to 'Archived'. Which of the following approaches is the most efficient and idiomatic way to achieve this using Snowpark DataFrames, assuming 'orders df DataFrame represents the 'orders' table?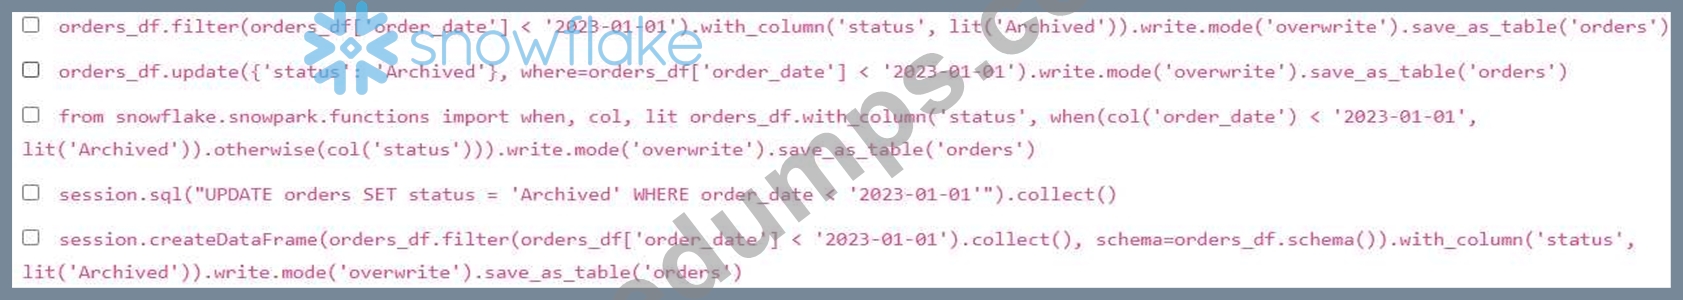
Answer: A,B
Explanation:
Options C and D are both valid and efficient solutions. Option C leverages Snowpark's 'with_column' and 'when' functions to conditionally update the 'status' column within the DataFrame and persists the changes back to the table using 'save_as_table'. Using lit function makes sure that 'Archived' status is passed as a literal. Option D uses a direct SQL update statement executed through the Snowpark session. This bypasses DataFrame operations but directly modifies the table, which can sometimes be more efficient for simple update operations. Option A is almost correct but the with_column and filter are applied separately. Option B doesn't work due to the way update functions are implemented in Snowpark. Option E unnecessarily collects the filtered data back to the driver, creating a new DataFrame from the collected data, then applying 'with_column'. This is an inefficient approach.
NEW QUESTION # 187
You are migrating a Pandas-based data processing pipeline to Snowpark to leverage Snowflake's scalability and performance. One part of the pipeline involves a computationally intensive custom function that is applied row-by-row to a DataFrame using the 'apply' method in Pandas. When migrating this to Snowpark, what are the most effective strategies for achieving similar functionality while maximizing performance within the Snowflake environment?
Answer: C,D
Explanation:
Vectorized operations in Snowpark provide the best performance by leveraging Snowflake's distributed processing. Creating a UDF allows you to push the computation to the Snowflake engine, avoiding the need to transfer large amounts of data to the Python environment. Direct translation to Snowpark 'apply' is not available as Snowpark 'apply' is significantly different, pandas code requires explicit data copying from and to snowflake. Stored procedures do not leverage the parallel processing capabilities of Snowflake as effectively as UDFs or vectorized operations. Pandas API is not the recommended way as UDF or vectorized operation.
NEW QUESTION # 188
You're tasked with loading data representing transactions from a legacy system into Snowflake using Snowpark. The legacy system exports the transaction data as a Python list of tuples, where each tuple contains transaction ID (integer), transaction amount (float), and transaction date (string in 'YYYY-MM-DD' format). The scale of data can be very high and need optimized way to load the data'. Your goal is to create a Snowpark DataFrame from this list of tuples, ensuring the date column is correctly interpreted as a Snowflake Date type. Which of the following approaches would be the most efficient and correct, minimizing data conversion overhead and maximizing Snowpark's capabilities?
Answer: C
Explanation:
Option C is the most efficient and correct way. Correctness : Option C explicitly defines the schema, including the 'DateType' for the transaction date. This ensures that Snowflake correctly interprets the date column without requiring any further casting or conversion. Avoids unnecessary string conversion. Efficiency : By defining the schema upfront, you avoid schema inference during dataframe creation, which can be costly for large datasets. This also avoids the cost of explicit casting after dataframe creation (as in Option A). Maximizing Snowpark Capabilities : Directly using Snowpark API to declare data types takes full advantage of Snowpark capabilities. Option A relies on implicit schema inference, which is not optimal in scenarios with specific data type requirements, and it requires an additional step which can be costly for large data. Option B introduces a dependency on Pandas and involves converting the data to a Pandas DataFrame, then to a Snowpark DataFrame, which creates unnecessary overhead and is not the most efficient approach. Option D, although correct, requires you to create a list of dictionaries, which adds an unneeded step in between and may not be optimized. Option E relies on implicit casting; However, this can lead to failure if date format is wrong.
NEW QUESTION # 189
......
Our exam questions just need students to spend 20 to 30 hours practicing on the platform which provides simulation problems, can let them have the confidence to pass the SPS-C01 exam, so little time great convenience for some workers. It must be your best tool to pass your exam and achieve your target. We provide free download and tryout before your purchase and if you fail in the exam we will refund you in full immediately at one time. Purchasing our SPS-C01 Guide Torrent can help you pass the exam and it costs little time and energy.
Latest SPS-C01 Exam Pdf: https://www.vcedumps.com/SPS-C01-examcollection.html