100% Pass-Rate SPS-C01 Testking - Win Your Snowflake Certificate with Top Score

DOWNLOAD the newest Prep4sures SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1EFN0mLSDd2K7Q5bTbUh1eZbMrDxownRI
Someone around you must be using our SPS-C01 exam questions. The users of our SPS-C01 exam materials are really very extensive. Or, you can consult someone who has participated in the SPS-C01 exam. They must know or use our products. We can confidently say that our products are leading in the products of the same industry. The richness and authority of SPS-C01 Exam Materials are officially certified.
| Section | Objectives |
|---|
| DataFrame Operations and Data Processing | - Data transformation workflows
- 1. Filtering, selecting, and aggregations
- 2. Joins and window functions
|
| Data Engineering with Snowpark | - Pipeline development
- 1. Integration with Snowflake data pipelines
- 2. Batch processing workflows
|
| Testing, Debugging, and Deployment | - Production readiness
- 1. Debugging Snowpark applications
- 2. Deployment strategies
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
- 1. Pushdown optimization concepts
- 2. Resource utilization tuning
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
- 1. Snowpark APIs and supported languages
- 2. Snowflake execution model overview
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
- 1. Python UDFs
- 2. Stored procedures in Snowpark
|
>> SPS-C01 Testking <<
SPS-C01 Braindumps & Latest SPS-C01 Dumps Ppt
All SPS-C01 practice questions you should know are written in them with three versions to choose from: the PDF, the Software and the APP online. At the same time, the experts who compiled the SPS-C01 learning engine are assiduously over so many years in this filed. I can say that our experts have became the authority in this career. And they are good at simplifying the content of the SPS-C01 Exam Braindumps to be understood by our customers all over the world.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q300-Q305):
NEW QUESTION # 300
Given a Snowpark DataFrame 'df with a column named 'data' of VARIANT type, where the VARIANT contains JSON objects with nested fields. You need to extract the value of the nested field 'address.city' as a STRING and the value of as a DOUBLE, handling cases where either 'address' or 'items' might be missing. Which combination of Snowpark functions is best suited to achieve this robustly and efficiently?
Answer: A
Explanation:
Option C is the most robust because it uses 'get_patW combined with and 'get_patm is specifically designed for extracting nested fields from VARIANT data, and handle cases where the path doesn't exist (returning NULL instead of an error).option A will fail if 'address' or 'items' is missing. Option B doesn't handle the NULL cases gracefully and 'to_double' expects a string not a variant. Option D doesn't handle the NULL cases gracefully and used 'to_varchaff which is deprecated. Option E will fail if 'address' or 'items' is missing and doesn't use get_path
NEW QUESTION # 301
You are developing a Snowpark application that utilizes a DataFrame named 'transactions df containing transactional data. You need to apply a series of complex transformations, including window functions and joins with other DataFrames. To optimize performance and manage resources effectively, you want to control how Snowpark executes these operations within Snowflake. Which of the following actions or configurations would have the MOST significant impact on controlling the execution plan and resource utilization of your Snowpark application?
- A. Explicitly cache the 'transactions_df DataFrame using before applying any transformations. This forces Snowpark to materialize the DataFrame in memory.
- B. Implement iterative algorithms within your Snowpark application using imperative Python loops instead of declarative DataFrame operations. This provides finer-grained control over the execution flow.
- C. Configure the 'net.snowflake.snowpark.use_native_execution' parameter to 'true' at the session level. This forces Snowpark to translate DataFrame operations into native Snowflake SQL queries.
- D. Specify the 'num_partitionS parameter when creating or transforming the 'transactions_df DataFrame. This controls the number of partitions used for parallel processing.
- E. Use the 'DataFrame.explain()' method to analyze the generated SQL query plan before executing the transformations. Then, manually optimize the code based on the query plan output.
Answer: E
Explanation:
Option C, using to analyze the query plan and then manually optimizing the Snowpark code, would have the MOST significant impact. Understanding the query plan allows you to identify bottlenecks, skew issues, and inefficient operations. Based on the plan, you can rewrite your Snowpark code to guide Snowflake toward a more efficient execution strategy. Caching (A) can sometimes help, but it's not always beneficial and can consume resources unnecessarily if not used carefully. Enabling native execution (B) generally improves performance, but it doesn't give you direct control over the execution plan. Partitioning (D) can be helpful, but the optimal number of partitions depends on the data and the transformations being performed. Using imperative loops (E) generally defeats the purpose of using Snowpark's declarative DataFrame API, which is designed to leverage Snowflake's query optimizer and parallel processing capabilities. It will most likely be very ineficient. Therefore, analyzing the query plan is crucial for optimizing resource utilization and controlling execution.
NEW QUESTION # 302
You have a Snowpark application that performs machine learning inference on a large dataset of images stored in Snowflake. The inference logic is implemented within a Python UDF that utilizes a pre-trained deep learning model. You notice that the inference process is slow and consumes a significant amount of resources. Which of the following optimization techniques would be MOST effective in improving the performance and reducing the resource consumption of this application?
- A. Leverage the Snowpark Session object to manage the lifecycle and scope of the pre-trained model within the UDF, ensuring it is loaded only once per session.
- B. Use external functions instead of UDFs.
- C. Ensure the virtual warehouse used by Snowpark is configured with auto-scaling to dynamically adjust the compute resources based on the workload.
- D. Persist the pre-trained deep learning model in a database table or stage and load it into the UDF's memory during each invocation to avoid repeated loading.
- E. Optimize the UDF code to use batch processing techniques to process multiple images in a single call, reducing the overhead of UDF invocation.
Answer: A,C,E
Explanation:
Auto-scaling helps manage resources dynamically. Batch processing reduces UDF overhead by processing multiple images in one call. Storing the model in a stage requires repeated loading. Managing the model's lifecycle within the Snowpark Session prevents reloading the model. External functions require data transfer out of Snowflake.
NEW QUESTION # 303
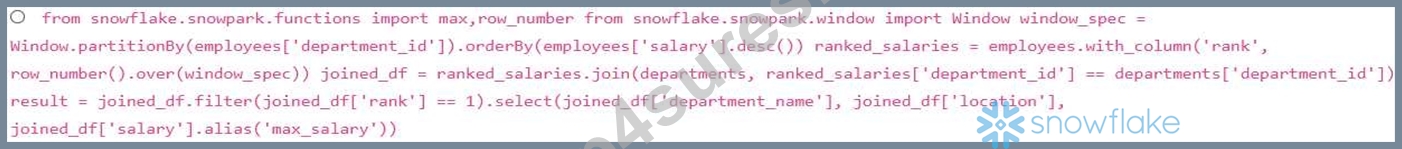
Consider two Snowpark DataFrames, 'employees' and 'departments' , with the following schemas: 'employees': (employee_id: Integer Type, employee_name: StringType, department_id: Integer Type, salary: IntegerType) 'departments': (department_id: Integer Type, department_name: StringType, location: StringType) You want to find the highest salary within each department, along with the department name and location, and display the results in a Snowpark DataFrame. Which of the following Snowpark Python code snippets correctly achieves this?
Answer: B
Explanation:
Option A correctly groups the 'employees' DataFrame by 'department_id' , calculates the maximum salary for each department using and then joins the resulting DataFrame with the 'departments' DataFrame on Finally, it selects the required columns: department name, location, and the calculated maximum salary. Option B is not correct as it calculates the rank of all salaries within each department but it does not aggregate on 'department_id'. Option C incorrectly attempts to group by columns from both tables before joining. Option D incorrectly uses the un-joined employees table where rank_salaries are from department_id. Option E will not work due to table names during select. It tries to use 'joined_df table for columns which doesn't have it.
NEW QUESTION # 304
You have two Snowflake tables, 'customers' and 'orders'. The 'customers' table contains customer information, including a 'customer id' and 'region'. The 'orders' table contains order information, including 'order id', 'customer id', and 'order amount'. You need to create a Snowpark DataFrame that joins these two tables on 'customer id' and calculates the total order amount per region. However, some customers may not have any orders, and you want to include all customers in the result, with a total order amount of 0 for those without orders. Which of the following Snowpark code snippets will achieve this goal MOST efficiently, assuming 'customers_df and 'orders_ff are pre-existing Snowpark DataFrames representing the respective tables?
Answer: E
Explanation:
Option B is the most efficient because it uses 'coalesce' directly within the 'agg' function, avoiding a separate .na.fill' operation which could be less optimized in Snowpark. It handles the null values resulting from the left outer join correctly, ensuring that customers without orders have a 0 total order amount. Options A and C might work in some contexts, but are less idiomatic and potentially less efficient. Options D and E are less concise and may not be the most optimal way to express the desired logic in Snowpark.
NEW QUESTION # 305
......
To do this you just need to pass SPS-C01 exam, which is quite challenging and demands thorough Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam preparation. For the complete, comprehensive and quick SPS-C01 Exam Preparation, the Prep4sures SPS-C01 Dumps questions are ideal. You should not ignore it and must try Prep4sures SPS-C01 exam questions for preparation today.
SPS-C01 Braindumps: https://www.prep4sures.top/SPS-C01-exam-dumps-torrent.html
- Web-Based Practice Exams to Evaluate Snowflake SPS-C01 Exam Preparation 🧲 Search on ▶ www.prepawayete.com ◀ for ➽ SPS-C01 🢪 to obtain exam materials for free download 😵SPS-C01 New Braindumps Free
- SPS-C01 Test Guide - SPS-C01 Actual Exam - SPS-C01 Pass-Sure Torrent 🔚 Search for ⇛ SPS-C01 ⇚ and download exam materials for free through ( www.pdfvce.com ) 🔸SPS-C01 Latest Test Online
- Pass Guaranteed Quiz High Pass-Rate SPS-C01 - Snowflake Certified SnowPro Specialty - Snowpark Testking 🐭 Copy URL ➡ www.prepawayexam.com ️⬅️ open and search for ➤ SPS-C01 ⮘ to download for free 🎄SPS-C01 Vce File
- SPS-C01 Practice Guide 🧵 SPS-C01 New Braindumps Free 🐓 Exam SPS-C01 Vce Format 💕 Download ( SPS-C01 ) for free by simply entering [ www.pdfvce.com ] website 🍄SPS-C01 Latest Test Online
- SPS-C01 Test Study Guide 🧡 Study SPS-C01 Reference ⚫ SPS-C01 Latest Test Online ⚓ Search for ( SPS-C01 ) and easily obtain a free download on ▷ www.torrentvce.com ◁ ⬇SPS-C01 Training Pdf
- SPS-C01 Boot Camp 🩳 Accurate SPS-C01 Prep Material 🕎 Study SPS-C01 Reference 🍷 Search for ▶ SPS-C01 ◀ and download it for free on ➤ www.pdfvce.com ⮘ website 🩳SPS-C01 Free Brain Dumps
- SPS-C01 Actual Test Pdf 🏑 Accurate SPS-C01 Prep Material ↕ SPS-C01 Training Pdf 🏗 Search for 「 SPS-C01 」 and download exam materials for free through ➥ www.vceengine.com 🡄 🕥SPS-C01 Test Dumps.zip
- Pass Guaranteed Quiz High Pass-Rate SPS-C01 - Snowflake Certified SnowPro Specialty - Snowpark Testking ☝ Search for ▶ SPS-C01 ◀ on [ www.pdfvce.com ] immediately to obtain a free download 🕍SPS-C01 Actual Test Pdf
- Reliable SPS-C01 Exam Sample ⛪ Accurate SPS-C01 Prep Material 🐌 SPS-C01 Free Brain Dumps 😭 Search for ➡ SPS-C01 ️⬅️ and download exam materials for free through { www.testkingpass.com } 💒SPS-C01 Training Pdf
- SPS-C01 Braindumps, SPS-C01 Practice Test, SPS-C01 Real Dumps 🦑 Search for “ SPS-C01 ” and easily obtain a free download on 「 www.pdfvce.com 」 ▶Reliable SPS-C01 Exam Sample
- SPS-C01 Braindumps, SPS-C01 Practice Test, SPS-C01 Real Dumps 🌅 The page for free download of ( SPS-C01 ) on ▛ www.validtorrent.com ▟ will open immediately ⚗SPS-C01 Free Brain Dumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BTW, DOWNLOAD part of Prep4sures SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1EFN0mLSDd2K7Q5bTbUh1eZbMrDxownRI