If you are still troubled for the Microsoft AI-103 Certification Exam, then select the PassTorrent's training materials please. PassTorrent's Microsoft AI-103 exam training materials is the best training materials, this is not doubt. Select it will be your best choice. It can guarantee you 100% pass the exam. Come on, you will be the next best IT experts.
| Section | Weight | Objectives |
|---|---|---|
| Implement generative AI and agentic solutions | 30–35% | - Build generative AI applications
|
| Implement text and speech analysis solutions | 10–15% | - Implement speech capabilities
|
| Implement information extraction and knowledge mining | 10–15% | - Extract structured data from documents
|
| Plan and manage Azure AI solutions | 25–30% | - Manage AI solution development lifecycle
|
| Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
>> AI-103 Reliable Test Preparation <<
Now you can think of obtaining any Microsoft certification to enhance your professional career. PassTorrent's AI-103 study guides are your best ally to get a definite success in AI-103 exam. The guides contain excellent information, exam-oriented questions and answers format on all topics of the certification syllabus. If you just make sure learning of the content in the guide, there is no reason of losing the AI-103 Exam.
NEW QUESTION # 105
You are defining an agent in Microsoft Foundry Agent Service. The agent uses a catalogue model for reasoning, a system instruction that sets its goals, and a file search capability that reads a knowledge store. Which three components does this combination represent?
Answer: D
Explanation:
Microsoft Foundry Agent Service defines every agent as the combination of three core components: a model that provides reasoning, instructions that set goals and behaviour, and tools that give access to data or actions. The scenario maps exactly, with the catalogue model, the system instruction, and the file search tool.
NEW QUESTION # 106
You have a Microsoft Foundry project that contains an agent. The agent uses Azure Al Search as the retriever.
You plan to ingest PDFs into an Azure Al Search index to ensure that the agent can ground responses in texts in both documents and embedded images.
Users require citations that link to the source files.
You need to ensure that during indexing, the images are extracted into a structure that can be used as input for the built-in optical character recognition (OCR) skill.
Which indexing approach should you use?
Answer: B
Explanation:
The correct indexing approach is to use an indexer to extract image data into a normalized_images collection . In Azure AI Search enrichment pipelines, embedded images in PDFs are not passed directly from the text content field into OCR. Instead, the indexer must perform document cracking and image extraction by enabling the indexer image action. Microsoft's Azure AI Search documentation states that image-processing skills such as OCR and image analysis expect normalized images, and that enabling imageAction causes embedded images to be extracted and normalized for downstream skills.
The OCR skill is designed to receive image input from /document/normalized_images/*. Microsoft's skillset tutorial specifically states that the OCR skill assumes a normalized_images field exists and that this field is generated by setting the indexer imageAction configuration to generateNormalizedImages. The document extraction skill reference also confirms that generateNormalizedImages creates an array of normalized images during document cracking for OCR and image analysis.
Option A is incorrect because OCR does not run directly against the index content field. Option B maps outputs after enrichment; it does not extract images. Option D reshapes data but does not create the required normalized image collection. Reference topics: Azure AI Search indexers, AI enrichment, OCR skill, imageAction, and normalized_images.
NEW QUESTION # 107
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have a multimodal Al generative model that accepts image uploads and uses extracted image text to generate responses.
You discover that users can upload unsafe images and embed hidden instructions into images to manipulate the model.
You need to implement controls to mitigate the risk.
Solution: You configure a prompt shield for user prompts.
Does this meet the goal?
Answer: A
Explanation:
The solution does not meet the goal. Prompt Shields for user prompts are designed to detect direct attempts by a user to manipulate the model through the prompt itself. In this scenario, the malicious instructions are embedded inside uploaded images and then introduced into the model context through extracted image text.
That pattern is an indirect prompt injection or document attack, not merely a direct user-prompt attack.
Microsoft's Prompt Shields guidance distinguishes between user prompt attacks and document attacks, and states that document attacks involve harmful instructions embedded in supplied documents or third-party content.
The solution is also incomplete because users can upload unsafe images. Azure AI Content Safety includes image APIs that detect harmful content in images and support moderation across modalities. A complete mitigation would combine image moderation for unsafe visual content with Prompt Shields for document attacks, and optionally Spotlighting, so OCR-derived or embedded image text is treated as lower-trust context.
Prompt Shields for user prompts alone would not reliably block unsafe images or hidden instructions extracted from those images. Reference topics: Azure AI Content Safety, Prompt Shields, user prompt attacks, document attacks, image moderation, and multimodal safety.
NEW QUESTION # 108
You have a Microsoft Foundry project that contains a Retrieval Augmented Generation (RAG) chat solution used by customer support agents.
You are adding an automated pre-production evaluation step to a CI/CD pipeline named Pipeline1. The evaluation will run against a labeled test dataset that contains support questions and the expected grounding context.
You need to ensure that Pipeline1 fails if unsupported content or a retrieval mismatch exceeds a defined threshold:
- responses include claims not supported by the retrieved source
content
- retrieved source content does not align with the labeled expected
context
Which two built-in evaluators should you use in Pipeline1? Each correct answer presents pat of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,E
Explanation:
The Groundedness Evaluator evaluator validates that the model's responses include only claims supported by the retrieved source content It flags ungrounded content or hallucinations. If the average score drops below your defined threshold, it triggers a pipeline failure.
The correct additional built-in evaluator appropriate for the pipeline is Retrieval (specifically, the RetrievalEvaluator or DocumentRetrievalEvaluator).
A standard RAG evaluation pipeline assesses both the generator (the LLM producing the answer) and the retriever (the search system pulling documentation). The CI/CD requirements specify two distinct failure thresholds:
Responses including claims not supported by the retrieved source content: This checks for model hallucinations and is handled by the Groundedness Evaluator.
Retrieved source content not aligning with the labeled expected context: This explicitly measures the performance of your search step against your ground-truth data. The built-in Retrieval evaluator maps to this requirement. It computes metrics like context recall to ensure your system successfully retrieves the exact reference documents specified in your labeled test dataset Reference:
https://learn.microsoft.com/en-us/microsoft-365/copilot/extensibility/evaluations-cli-evaluators
NEW QUESTION # 109
Hotspot Question
You have a Python application that redacts sensitive information before sending prompt text to a language model. The application has the following code: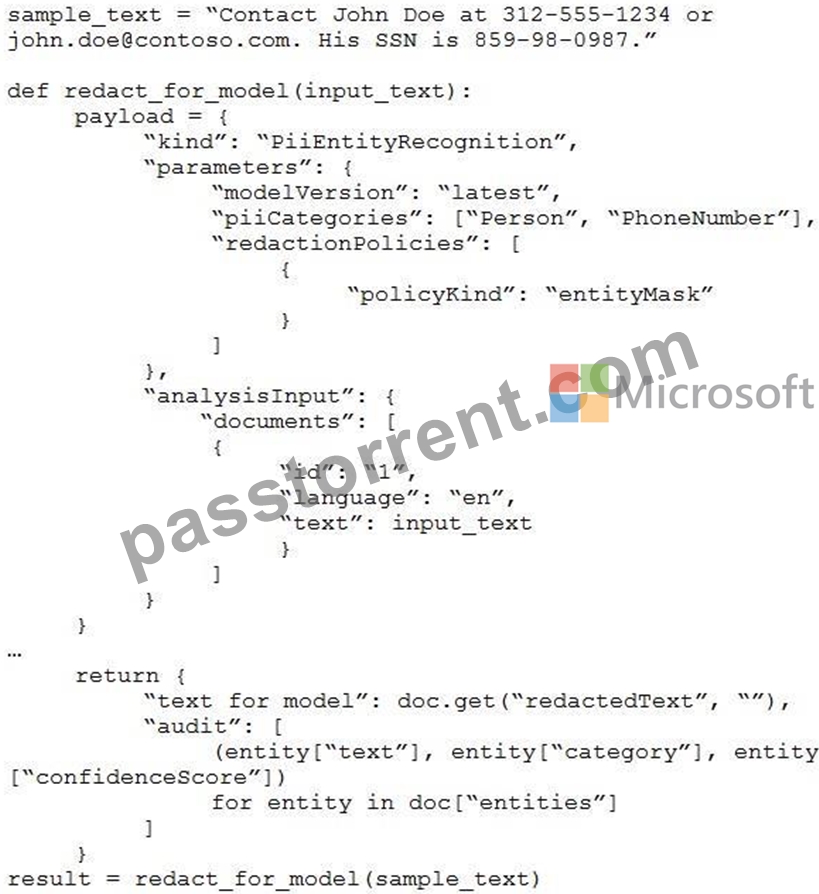
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.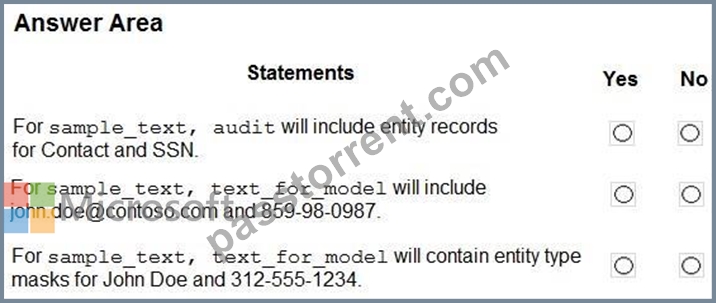
Answer:
Explanation: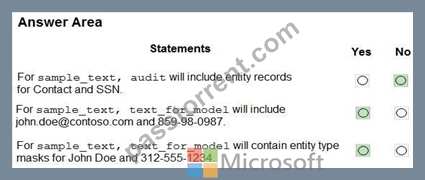
Explanation:
Box 1: No
The audit list will not include entity records for "Contact" and "SSN" because neither word is a target PII entity type defined in the configuration.
The code limits scanning to Person and PhoneNumber via the piiCategories list.
"Contact" Definition: This is a regular English verb/noun, not a person's name or a telephone number.
"SSN" Definition: While "SSN" is a text label that points to sensitive data, it is a descriptor rather than an actual Social Security Number.
Box 2: Yes
For the given sample_text, text_for_model will include both or john.doe@contoso.com and 859-
98-0987 completely unredacted.
The payload explicitly restricts the Personally Identifiable Information (PII) recognition to only two specific categories by setting piiCategories: ["Person", "PhoneNumber"].
Email Address Excluded: Because the Email category is omitted from the configuration list, the service bypasses the email address (john.doe@contoso.com) and leaves it fully intact.
SSN Excluded: Similarly, because the USSSN (or equivalent Social Security Number) category is not specified in the piiCategories array, the SSN (859-98-0987) is completely ignored by the redaction policy and remains visible.
Box 3: Yes
text_for_model will contain entity type masks for "John Doe" and "312-555-1234", but only for those two specific items.
The piiCategories array explicitly requests Person and PhoneNumber.
Applied Redaction: The Azure AI Language service will replace "John Doe" and "312-555-1234" with masks like * or entity labels (depending on exact policy settings).
Skipped Data: The email (john.doe@contoso.com) and the SSN (859-98-0987) will not be redacted because their categories (Email and USSSN) were omitted from your piiCategories list.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/language-service/personally-identifiable-information/concepts/conversations-entity-categories
NEW QUESTION # 110
......
You know, the AI-103 certification is tough and difficult IT certification. In order to get a better life, many people as you still want to chase after it. There is a useful and reliable study material of Microsoft AI-103 actual test for you. The AI-103 Pdf Dumps will teach you the basic technology and tell you how to affectively prepare for the AI-103 real test. In a word, AI-103 updated dumps is the best reference for you preparation.
Exam AI-103 Learning: https://www.passtorrent.com/AI-103-latest-torrent.html