
BONUS!!! Fast2test Data-Engineer-Associate 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1AjS0snYLNkBZbcSyrw4K1naPn7rkZEbq
Fast2test전문가들은Amazon Data-Engineer-Associate인증시험만을 위한 특별학습가이드를 만들었습니다.Amazon Data-Engineer-Associate인증시험을 응시하려면 30분이란 시간만 투자하여 특별학습가이드로 빨리 관련지식을 장악하고,또 다시 복습하고 안전하게Amazon Data-Engineer-Associate인증시험을 패스할 수 잇습니다.자격증취득 많은 시간과 돈을 투자한 분들보다 더 가볍게 이루어졌습니다
| Section | Weight | Objectives |
|---|---|---|
| Data Security and Governance | 18% | - Implement data security controls - Apply governance and compliance best practices |
| Data Operations and Support | 22% | - Monitor and maintain data pipelines - Troubleshoot data workflow issues |
| Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
| Data Store Management | 26% | - Optimize storage performance and cost - Select appropriate data storage solutions |
>> Amazon Data-Engineer-Associate퍼펙트 덤프공부자료 <<
우리Fast2test 사이트에서Amazon Data-Engineer-Associate관련자료의 일부 문제와 답 등 샘플을 제공함으로 여러분은 무료로 다운받아 체험해보실 수 있습니다.체험 후 우리의Fast2test에 신뢰감을 느끼게 됩니다.빨리 우리 Fast2test의 덤프를 만나보세요.
질문 # 12
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?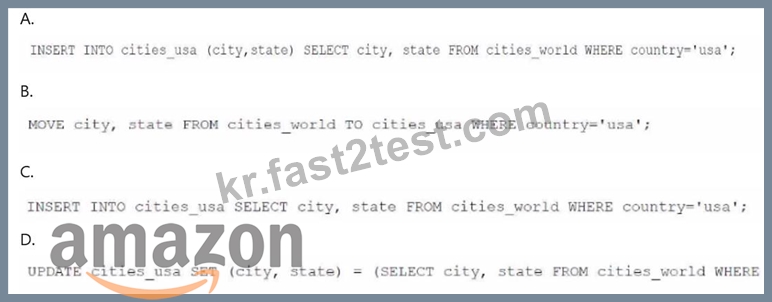
정답:B
설명:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is 'usa'. The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa'; This statement inserts only the cities and states where the country column has a value of 'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
Reference:
Amazon Athena SQL Reference
Creating Tables in Athena
질문 # 13
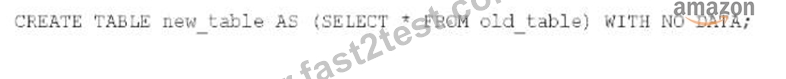
A data engineer needs to create a new empty table in Amazon Athena that has the same schema as an existing table named old-table.
Which SQL statement should the data engineer use to meet this requirement?



정답:A
설명:
* Problem Analysis:
* The goal is to create a new empty table in Athena with the same schema as an existing table (old_table).
* The solution must avoid copying any data.
* Key Considerations:
* CREATE TABLE AS (CTAS) is commonly used in Athena for creating new tables based on an existing table.
* Adding the WITH NO DATA clause ensures only the schema is copied, without transferring any data.
* Solution Analysis:
* Option A: Copies both schema and data. Does not meet the requirement for an empty table.
* Option B: Inserts data into an existing table, which does not create a new table.
* Option C: Creates an empty table but does not copy the schema.
* Option D: Creates a new table with the same schema and ensures it is empty by using WITH NO DATA.
* Final Recommendation:
* Use D. CREATE TABLE new_table AS (SELECT * FROM old_table) WITH NO DATA to create an empty table with the same schema.
Athena CTAS Queries
CREATE TABLE Statement in Athena
질문 # 14
A company is building a new application that ingests CSV files into Amazon Redshift. The company has developed the frontend for the application.
The files are stored in an Amazon S3 bucket. Files are no larger than 5 MB.
A data engineer is developing the extract, transform, and load (ETL) pipeline for the CSV files. The data engineer configured a Redshift cluster and an AWS Lambda function that copies the data out of the files into the Redshift cluster.
Which additional steps should the data engineer perform to meet these requirements?
정답:D
설명:
Option A is the most direct and operationally efficient way to trigger the existing Lambda-based load into Amazon Redshift whenever a new CSV file is uploaded to Amazon S3. The key requirement is event-driven automation on "new object created" events, and the study material explicitly describes using Amazon EventBridge to react to S3 uploads by creating a rule on the default event bus and routing matching events to a target application.
Compared with queue-based designs (Options B and D), Option A reduces components: there is no need to manage an SQS queue, batching/visibility timeout behavior, or retry semantics at the consumer layer. This is especially appropriate because the files are small (# 5 MB) and the Lambda function is already implemented to perform the copy/load step. Using DMS (Option C) is not designed for "S3 object arrival # Lambda # Redshift" event triggering; it introduces unnecessary services and operational work for a simple file-ingestion trigger.
Therefore, integrating S3 event notifications with EventBridge and targeting the Lambda function best meets the requirement with the least added complexity.
질문 # 15
A company uses an Amazon QuickSight dashboard to monitor usage of one of the company's applications.
The company uses AWS Glue jobs to process data for the dashboard. The company stores the data in a single Amazon S3 bucket. The company adds new data every day.
A data engineer discovers that dashboard queries are becoming slower over time. The data engineer determines that the root cause of the slowing queries is long-running AWS Glue jobs.
Which actions should the data engineer take to improve the performance of the AWS Glue jobs? (Choose two.)
정답:A,E
설명:
Partitioning the data in the S3 bucket can improve the performance of AWS Glue jobs by reducing the amount of data that needs to be scanned and processed. By organizingthe data by year, month, and day, the AWS Glue job can use partition pruning to filter out irrelevant data and only read the data that matches the query criteria.
This can speed up the data processing and reduce the cost of running the AWS Glue job. Increasing the AWS Glue instance size by scaling up the worker type can also improve the performance of AWS Glue jobs by providing more memory and CPU resources for the Spark execution engine. This can help the AWS Glue job handle larger data sets and complex transformations more efficiently. The other options are either incorrect or irrelevant, as they do not affect the performance of the AWS Glue jobs. Converting the AWS Glue schema to the DynamicFrame schema class does not improve the performance, but rather provides additional functionality and flexibility for data manipulation. Adjusting the AWS Glue job scheduling frequency does not improve the performance, but rather reduces the frequency of data updates. Modifying the IAM role that grants access to AWS Glue does not improve the performance, but rather affects the security and permissions of the AWS Glue service. References:
Optimising Glue Scripts for Efficient Data Processing: Part 1 (Section: Partitioning Data in S3) Best practices to optimize cost and performance for AWS Glue streaming ETL jobs (Section:
Development tools)
Monitoring with AWS Glue job run insights (Section: Requirements)
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide (Chapter 5, page 133)
질문 # 16
A data engineer is implementing model governance for machine learning (ML) workflows on AWS. The data engineer needs a solution that can track the complete lifecycle of the ML models, including data preparation, model training, and deployment stages. The solution must ensure reproducibility and audit compliance.
정답:A
설명:
Amazon SageMaker ML Lineage Tracking provides a unified mechanism to automatically capture and track the lineage of ML artifacts (datasets, jobs, and models). It supports auditability, reproducibility, and compliance by maintaining metadata for every stage of the ML lifecycle.
"Use Amazon SageMaker Lineage Tracking to automatically record and track the lineage of data, training jobs, models, and endpoints to ensure auditability and reproducibility."
- Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf
질문 # 17
......
Amazon Data-Engineer-Associate시험이 정말 어렵다는 말을 많이 들으신 만큼 저희 Fast2test는Amazon Data-Engineer-Associate덤프만 있으면Amazon Data-Engineer-Associate시험이 정말 쉬워진다고 전해드리고 싶습니다. Amazon Data-Engineer-Associate덤프로 시험패스하고 자격증 한방에 따보세요. 자격증 많이 취득하면 더욱 여유롭게 직장생활을 즐길수 있습니다.
Data-Engineer-Associate덤프자료: https://kr.fast2test.com/Data-Engineer-Associate-premium-file.html
참고: Fast2test에서 Google Drive로 공유하는 무료 2026 Amazon Data-Engineer-Associate 시험 문제집이 있습니다: https://drive.google.com/open?id=1AjS0snYLNkBZbcSyrw4K1naPn7rkZEbq