그 외, Fast2test Databricks-Certified-Professional-Data-Engineer 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1ZE9KfWMam3VO_fh215o9jVGh_35zx148
다른 사이트에서도Databricks Databricks-Certified-Professional-Data-Engineer인증시험관련 자료를 보셨다고 믿습니다.하지만 우리 Fast2test의 자료는 차원이 다른 완벽한 자료입니다.100%통과 율은 물론Fast2test을 선택으로 여러분의 직장생활에 더 낳은 개변을 가져다 드리며 ,또한Fast2test를 선택으로 여러분은 이미 충분한 시험준비를 하였습니다.우리는 여러분이 한번에 통과하게 도와주고 또 일년무료 업데이트서비스도 드립니다.
| Section | Objectives |
|---|---|
| Topic 1: Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads - Implement Unity Catalog governance and access control - Cost optimization and performance tuning |
| Topic 2: Data Modeling and Storage | - Schema evolution and data partitioning strategies - Design scalable data lakehouse architectures - Delta Lake table design and optimization |
| Topic 3: Production Pipelines and Orchestration | - Pipeline reliability and fault tolerance - Automate ETL pipelines and scheduling - Build and manage workflows using Databricks Jobs |
| Topic 4: Data Ingestion and Transformation | - Handle batch and streaming data pipelines - Ingest data using Apache Spark and Databricks - Transform and clean datasets using Spark SQL and DataFrame APIs |
>> Databricks-Certified-Professional-Data-Engineer인기덤프공부 <<
Fast2test 의 엘리트는 다년간 IT업계에 종사한 노하우로 높은 적중율을 자랑하는 Databricks Databricks-Certified-Professional-Data-Engineer덤프를 연구제작하였습니다. 한국어 온라인서비스가 가능하기에 Databricks Databricks-Certified-Professional-Data-Engineer덤프에 관하여 궁금한 점이 있으신 분은 구매전 문의하시면 됩니다. Databricks Databricks-Certified-Professional-Data-Engineer덤프로 시험에서 좋은 성적 받고 자격증 취득하시길 바랍니다.
질문 # 148
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone.
A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
정답:B
설명:
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.References:
Databricks documentation on Delta Lake, particularly the sections on cloning tables (shallow and deep cloning) and data retention with the vacuum command (https://docs.databricks.com/delta/index.html).
질문 # 149
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x-scala2.12' runtime.
Which command should the data engineer use?
정답:B
설명:
The Databricks CLI allows users to manage clusters using command-line commands. The correct command for creating a cluster follows a specific format.
Key Components in the Command:
* Command Type: databricks compute create is the correct syntax for creating a new compute resource (cluster).
* Runtime Version: '14.3.x-scala2.12' specifies the Databricks runtime to use.
* Workers: --num-workers 5 sets the number of worker nodes to 5.
* Node Type: --node-type-id i3.xlarge defines the hardware configuration.
* Cluster Name: --cluster-name DataEngineer_cluster assigns a recognizable name to the cluster.
Evaluation of Options:
* Option A (databricks clusters create ...)
* Incorrect: databricks clusters create is not a valid command in the Databricks CLI v0.205.
* The correct CLI command for cluster creation is databricks compute create.
* Option B (databricks clusters add ...)
* Incorrect: databricks clusters add is not a valid CLI command.
* Option C (databricks compute add ...)
* Incorrect: databricks compute add is not a valid CLI command.
* Option D (databricks compute create ...)
* Correct: databricks compute create is the correct command for creating a cluster.
Conclusion:
The correct command to create a cluster with five workers, an i3.xlarge node type, and Databricks runtime
14.3.x-scala2.12 is:
databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster Thus, the correct answer is D.
References:
Databricks CLI Documentation
질문 # 150
A data engineer has set up a notebook to automatically process using a Job. The data engineer's manager wants
to version control the schedule due to its complexity.
Which of the following approaches can the data engineer use to obtain a version-controllable con-figuration of
the Job's schedule?
정답:C
질문 # 151
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.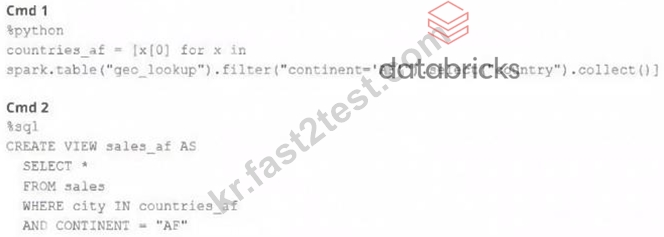
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
정답:C
설명:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view. Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter. Verified Reference: [Databricks Certified Data Engineer Professional], under "Language Interoperability" section; Databricks Documentation, under "Mix languages" section.
질문 # 152
A Delta Lake table was created with the below query: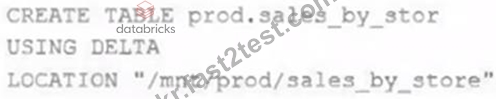
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
정답:B
설명:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "ALTER TABLE RENAME TO" section; Databricks Documentation, under "Metastore" section; Databricks Documentation, under "Managed and external tables" section.
질문 # 153
......
IT업계 종사자라면 누구나 Databricks 인증Databricks-Certified-Professional-Data-Engineer시험을 패스하고 싶어하리라고 믿습니다. 많은 분들이 이렇게 좋은 인증시험은 아주 어렵다고 생각합니다. 네 맞습니다. 패스할 확율은 아주 낮습니다. 노력하지 않고야 당연히 불가능한 일이 아니겠습니까? Databricks 인증Databricks-Certified-Professional-Data-Engineer 시험은 기초 지식 그리고 능숙한 전업지식이 필요 합니다. Fast2test는 여러분들한테Databricks 인증Databricks-Certified-Professional-Data-Engineer시험을 쉽게 빨리 패스할 수 있도록 도와주는 사이트입니다. Fast2test의Databricks 인증Databricks-Certified-Professional-Data-Engineer시험관련 자료로 여러분은 짧은 시간내에 간단하게 시험을 패스할수 있습니다. 시간도 절약하고 돈도 적게 들이는 이런 제안은 여러분들한테 딱 좋은 해결책이라고 봅니다.
Databricks-Certified-Professional-Data-Engineer퍼펙트 덤프데모문제: https://kr.fast2test.com/Databricks-Certified-Professional-Data-Engineer-premium-file.html
참고: Fast2test에서 Google Drive로 공유하는 무료 2026 Databricks Databricks-Certified-Professional-Data-Engineer 시험 문제집이 있습니다: https://drive.google.com/open?id=1ZE9KfWMam3VO_fh215o9jVGh_35zx148