Features of Databricks Databricks-Certified-Data-Engineer-Professional Desktop and Web-based Practice Exams

P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Professional dumps are available on Google Drive shared by ExamCost: https://drive.google.com/open?id=1BqFKbOZl8qh3-j98uNYXsMW8V120s1ql
Our Databricks Certified Data Engineer Professional Exam prep torrent will provide customers with three different versions, including the PDF version, the software version and the online version, each of them has its own advantages. Now I am going to introduce you the PDF version of Databricks-Certified-Data-Engineer-Professional test braindumps which are very convenient. It is well known to us that the PDF version is very convenient and practical. The PDF version of our Databricks-Certified-Data-Engineer-Professional Test Braindumps provide demo for customers; you will have the right to download the demo for free if you choose to use the PDF version.
| Section | Weight | Objectives |
|---|
| Databricks Lakehouse Platform | 24% | - Lakehouse Architecture
- Unity Catalog
- Data Management
- Delta Lake
|
| Data Quality and Governance | 12% | - Data Lineage
- Governance
- Data Quality
|
| Monitoring and Troubleshooting | 16% | - Troubleshooting
- Monitoring
- Performance Optimization
|
| Data Modeling and Storage | 20% | - Data Modeling
- File Formats
- Storage Optimization
|
| Data Processing | 28% | - ETL Pipelines
- Data Transformation
- Structured Streaming
- Spark SQL
|
>> Latest Databricks-Certified-Data-Engineer-Professional Dumps Ebook <<
New Databricks-Certified-Data-Engineer-Professional Practice Materials | Databricks-Certified-Data-Engineer-Professional Valid Test Pattern
You should make progress to get what you want and move fast if you are a man with ambition. At the same time you will find that a wonderful aid will shorten your time greatly. To get the Databricks-Certified-Data-Engineer-Professional certification is considered as the most direct-viewing way to make big change in your professional profile, and we are the exact Databricks-Certified-Data-Engineer-Professional Exam Braindumps vendor. If you have a try on our free demos of our Databricks-Certified-Data-Engineer-Professional study guide, you will choose us!
Databricks Certified Data Engineer Professional Exam Sample Questions (Q132-Q137):
NEW QUESTION # 132
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on task A.
If tasks A and B complete successfully but task C fails during a scheduled run, which statement describes the resulting state?
- A. All logic expressed in the notebook associated with tasks A and B will have been successfully completed; any changes made in task C will be rolled back due to task failure.
- B. Unless all tasks complete successfully, no changes will be committed to the Lakehouse; because task C failed, all commits will be rolled back automatically.
- C. All logic expressed in the notebook associated with task A will have been successfully completed; tasks B and C will not commit any changes because of stage failure.
- D. All logic expressed in the notebook associated with tasks A and B will have been successfully completed; some operations in task C may have completed successfully.
- E. Because all tasks are managed as a dependency graph, no changes will be committed to the Lakehouse until ail tasks have successfully been completed.
Answer: D
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The resulting state after running the second command is that an external table will be created in the storage container mounted to /mnt/finance_eda_bucket with the new name prod.sales_by_store. The command will not change any data or move any files in the storage container; it will only update the table reference in the metastore and create a new Delta transaction log for the renamed table.
NEW QUESTION # 133
Which statement describes Delta Lake Auto Compaction?
- A. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
- B. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
- C. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
- D. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
- E. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
Answer: E
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB. Auto Compaction only compacts files that have not been compacted previously.
NEW QUESTION # 134
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
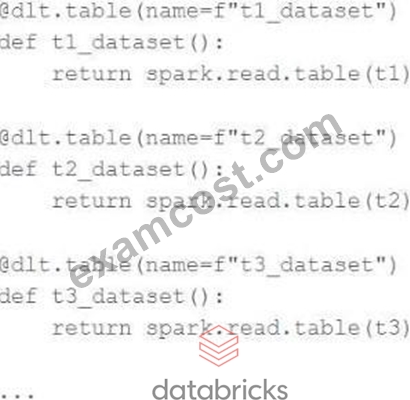
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
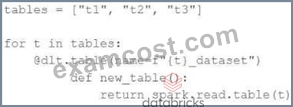
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Move the table definition into a separate function, and make calls to this function using different input parameters inside the for loop.
- B. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- C. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- D. Wrap the for loop inside another table definition, using generalized names and properties to replace with those from the inner table definition.
Answer: A
Explanation:
In the provided refactored code, the for loop dynamically attempts to define multiple tables, but the use of a loop within the DLT (@dlt.table) decorator does not work properly because it results in a single function reference being overwritten for each iteration. This leads to an incorrect DAG because all the table definitions end up pointing to the last iteration of the loop.
NEW QUESTION # 135
A team of data engineer are adding tables to a DLT pipeline that contain repetitive expectations for many of the same data quality checks.
One member of the team suggests reusing these data quality rules across all tables defined for this pipeline.
What approach would allow them to do this?
- A. Use global Python variables to make expectations visible across DLT notebooks included in the same pipeline.
- B. Maintain data quality rules in a separate Databricks notebook that each DLT notebook of file.
- C. Add data quality constraints to tables in this pipeline using an external job with access to pipeline configuration files.
- D. Maintain data quality rules in a Delta table outside of this pipeline's target schema, providing the schema name as a pipeline parameter.
Answer: D
Explanation:
Maintaining data quality rules in a centralized Delta table allows for the reuse of these rules across multiple DLT (Delta Live Tables) pipelines. By storing these rules outside the pipeline's target schema and referencing the schema name as a pipeline parameter, the team can apply the same set of data quality checks to different tables within the pipeline. This approach ensures consistency in data quality validations and reduces redundancy in code by not having to replicate the same rules in each DLT notebook or file.
NEW QUESTION # 136
A data engineer wants to reflector the following DLT code, which includes multiple definition with very similar code:
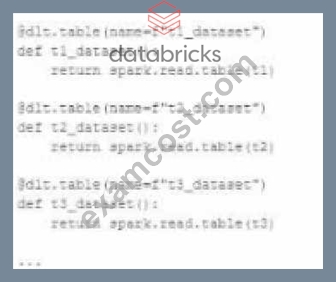
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
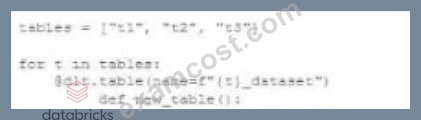
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for tables.
How can the data engineer fix this?
- A. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- B. Convert the list of configuration values to a dictionary of table settings, using different input the for loop.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from - C. Wrap the loop inside another table definition, using generalized names and properties to replace with those from the inner table
- D. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
Answer: D
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names.
Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 137
......
And you can also use the Databricks Databricks-Certified-Data-Engineer-Professional PDF on smart devices like smartphones, laptops, and tablets. The second one is the web-based Databricks Databricks-Certified-Data-Engineer-Professional practice exam which can be accessed through the browsers like Firefox, Safari, and Google Chrome. The customers don't need to download or install excessive plugins or software to get the full advantage from web-based Databricks-Certified-Data-Engineer-Professional Practice Tests.
New Databricks-Certified-Data-Engineer-Professional Practice Materials: https://www.examcost.com/Databricks-Certified-Data-Engineer-Professional-practice-exam.html
- Practical Latest Databricks-Certified-Data-Engineer-Professional Dumps Ebook - Perfect New Databricks-Certified-Data-Engineer-Professional Practice Materials - High-quality Databricks Databricks Certified Data Engineer Professional Exam 👏 Download ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ for free by simply entering ⇛ www.examcollectionpass.com ⇚ website 🦽Valid Databricks-Certified-Data-Engineer-Professional Test Vce
- 100% Pass Quiz 2026 High Pass-Rate Databricks-Certified-Data-Engineer-Professional: Latest Databricks Certified Data Engineer Professional Exam Dumps Ebook 🎃 Search for 《 Databricks-Certified-Data-Engineer-Professional 》 and download exam materials for free through ➡ www.pdfvce.com ️⬅️ 📱Databricks-Certified-Data-Engineer-Professional Valid Test Experience
- Databricks-Certified-Data-Engineer-Professional Valid Exam Blueprint 🎷 Reliable Databricks-Certified-Data-Engineer-Professional Braindumps Pdf 👝 Sample Databricks-Certified-Data-Engineer-Professional Test Online 🛰 Search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ and download it for free immediately on ☀ www.easy4engine.com ️☀️ 🚹Reliable Databricks-Certified-Data-Engineer-Professional Test Simulator
- Free PDF Quiz Databricks First-grade Databricks-Certified-Data-Engineer-Professional - Latest Databricks Certified Data Engineer Professional Exam Dumps Ebook 🎱 Search on ⇛ www.pdfvce.com ⇚ for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ to obtain exam materials for free download 📄Databricks-Certified-Data-Engineer-Professional Reliable Real Exam
- Practical Latest Databricks-Certified-Data-Engineer-Professional Dumps Ebook - Perfect New Databricks-Certified-Data-Engineer-Professional Practice Materials - High-quality Databricks Databricks Certified Data Engineer Professional Exam 🏋 Search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and download it for free on ⇛ www.dumpsquestion.com ⇚ website 🚌Databricks-Certified-Data-Engineer-Professional Exam Test
- Reliable Databricks-Certified-Data-Engineer-Professional Test Simulator 🧺 Valid Databricks-Certified-Data-Engineer-Professional Test Vce 🔉 Databricks-Certified-Data-Engineer-Professional Valid Exam Camp ❎ Download ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ for free by simply entering ➽ www.pdfvce.com 🢪 website 🏝Reliable Databricks-Certified-Data-Engineer-Professional Test Simulator
- 100% Pass Quiz 2026 High Pass-Rate Databricks-Certified-Data-Engineer-Professional: Latest Databricks Certified Data Engineer Professional Exam Dumps Ebook ⌨ Open website ✔ www.troytecdumps.com ️✔️ and search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ for free download 🐐Reasonable Databricks-Certified-Data-Engineer-Professional Exam Price
- 2026 100% Free Databricks-Certified-Data-Engineer-Professional –Perfect 100% Free Latest Dumps Ebook | New Databricks Certified Data Engineer Professional Exam Practice Materials ♥ Open website ▛ www.pdfvce.com ▟ and search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ for free download 👴Databricks-Certified-Data-Engineer-Professional Paper
- Databricks-Certified-Data-Engineer-Professional Valid Test Experience 🌲 Reliable Databricks-Certified-Data-Engineer-Professional Test Simulator 💠 Databricks-Certified-Data-Engineer-Professional Study Reference Ⓜ Download “ Databricks-Certified-Data-Engineer-Professional ” for free by simply entering ☀ www.prep4sures.top ️☀️ website 🔉Databricks-Certified-Data-Engineer-Professional Exam Test
- Marvelous Databricks Latest Databricks-Certified-Data-Engineer-Professional Dumps Ebook 👪 Go to website ⏩ www.pdfvce.com ⏪ open and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ to download for free 🥼Databricks-Certified-Data-Engineer-Professional Valid Exam Question
- Databricks-Certified-Data-Engineer-Professional Paper ❗ Databricks-Certified-Data-Engineer-Professional Reliable Real Exam 📣 Test Databricks-Certified-Data-Engineer-Professional Pattern 💆 Simply search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ for free download on ✔ www.easy4engine.com ️✔️ 🎹Databricks-Certified-Data-Engineer-Professional Exam Test
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Professional dumps are available on Google Drive shared by ExamCost: https://drive.google.com/open?id=1BqFKbOZl8qh3-j98uNYXsMW8V120s1ql