By keeping customer satisfaction in mind, Free4Torrent offers you a free demo of the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions. As a result, it helps you to evaluate the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam dumps before making a purchase. Free4Torrent is steadfast in its commitment to helping you pass the Databricks in Certified-Data-Engineer-Professional Exam. A full refund guarantee (terms and conditions apply) offered by Free4Torrent will save you from fear of money loss.
| Section | Weight | Objectives |
|---|---|---|
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Manage dependencies, libraries, and UDFs - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
>> New Certified-Data-Engineer-Professional Test Objectives <<
The series of Certified-Data-Engineer-Professional measures we have taken is also to allow you to have the most professional products and the most professional services. I believe that in addition to our Certified-Data-Engineer-Professional study materials, you have also used a variety of products. What kind of services on the Certified-Data-Engineer-Professional training engine can be considered professional, you will have your own judgment. But I would like to say that our products study materials must be the most professional of the Certified-Data-Engineer-Professional Exam simulation you have used. And you will find that our Certified-Data-Engineer-Professional exam questions is worthy for your time and money.
NEW QUESTION # 193
Predictive Optimization is an automated Databricks service enabled by default for Unity Catalog Managed tables. It helps maintain Delta tables by continuously optimizing them to ensure optimal performance and costs. Which two operations does Predictive Optimization run to maintain the Delta tables? (Choose two.)
Answer: B,C
Explanation:
Predictive Optimization automatically runs OPTIMIZE to compact small files and improve data layout, and ANALYZE to collect and refresh table statistics. Together, these operations ensure efficient query planning, better data skipping, and optimized performance and cost for Unity Catalog managed Delta tables.
NEW QUESTION # 194
Which statement characterizes the general programming model used by Spark Structured Streaming?
Answer: C
Explanation:
The key idea in Structured Streaming is to treat a live data stream as a table that is being continuously appended. This leads to a new stream processing model that is very similar to a batch processing model. You will express your streaming computation as standard batch-like query as on a static table, and Spark runs it as an incremental query on the unbounded input table. Let's understand this model in more detail.
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html
NEW QUESTION # 195
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
Answer: C
Explanation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration.
Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
NEW QUESTION # 196
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs UI. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
Answer: A
NEW QUESTION # 197
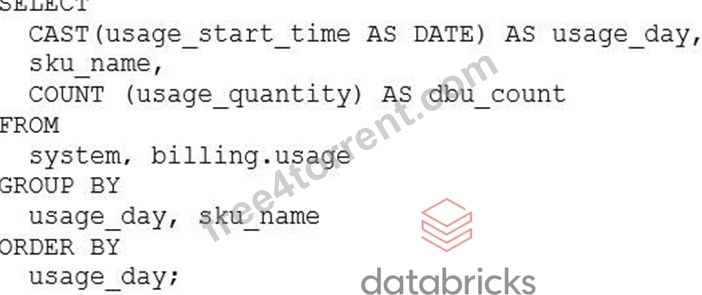
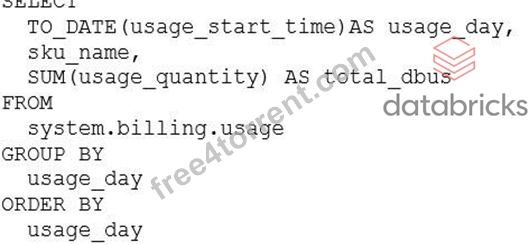
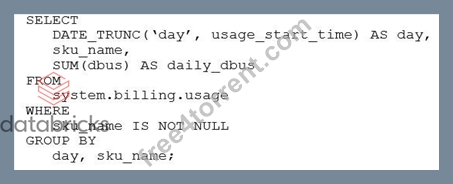
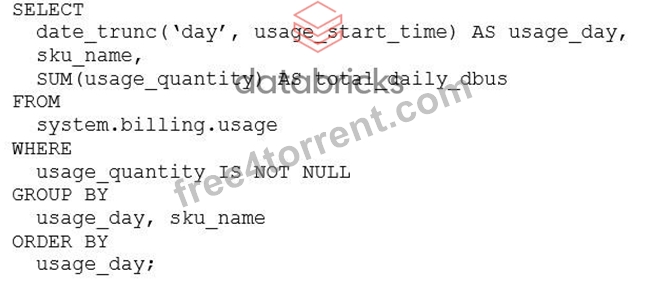
A platform engineer needs to report the resource consumption, categorized by SKU tier, across all workspaces. The engineer decides to use the system.billing.usage system table to create a query. Which SQL query will accurately return the daily usage by product?
Answer: D
Explanation:
This query correctly aggregates usage at a daily granularity by truncating the usage start timestamp to the day and summing the usage quantity, which represents DBUs. Grouping by both the derived daily value and the SKU name ensures usage is accurately categorized by product tier across all workspaces.
NEW QUESTION # 198
......
Our Databricks Certified-Data-Engineer-Professional real test can bring you the most valid and integrated content to ensure that what you study with is totally in accordance with the real Databricks Certified-Data-Engineer-Professional Exam. And we give sincere and suitable after-sales service to all our customers to provide you a 100% success guarantee to pass your exams on your first attempt.
Reliable Certified-Data-Engineer-Professional Dumps Ebook: https://www.free4torrent.com/Certified-Data-Engineer-Professional-braindumps-torrent.html