With the number of people who take the exam increasing, the SPS-C01 exam has become more and more difficult for many people. A growing number of people have had difficulty in preparing for the SPS-C01 exam, and they have a tendency to turn to the study materials. However, a lot of people do not know how to choose the suitable study materials. We are willing to recommend the SPS-C01 Study Materials from our company to you.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API for Python | 30% | - Establishing connections and session management - User-Defined Functions (UDFs) and Stored Procedures - Reading and writing data - DataFrame creation and manipulation - Working with Semi-structured data |
| Topic 2: Data Transformations and DataFrame Operations | 35% | - Filtering, Aggregating, and Joining DataFrames - Complex data pipelines - Using built-in functions - Persisting transformed data - Window functions |
| Topic 3: Performance Optimization and Best Practices | 20% | - Minimizing data transfer - Query pushdown and optimization - Caching strategies - Debugging and explain plans - Warehouse sizing for Snowpark - Vectorized UDFs |
| Topic 4: Snowpark Concepts | 15% | - Transformations vs. Actions - Snowpark Sessions and connection management - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Stored procedures and conditional logic - Client-side vs. Server-side execution |
>> Valid SPS-C01 Exam Materials <<
Customizable Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam conditions in such a way that you can create your desired SPS-C01 exam with pre-determined questions and exam duration. You will be able to see instant results after going through the SPS-C01 Practice Exam To confirm the product licence. For customer satisfaction, ValidBraindumps has also designed a Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) demo version so the candidate can assure the reliability of the Snowflake PDF Dumps.
NEW QUESTION # 67
You are working with two large Snowpark DataFrames: 'transaction_df and 'product df. 'transaction_df contains transaction data including 'transaction id', 'product id', and 'transaction_date'. 'product df contains product details including 'product id', product_name', and 'product category'. You need to join these DataFrames to analyze transaction data by product category. The 'transaction_df is significantly larger than 'product_df. Which of the following strategies can significantly improve the performance of the join operation in Snowpark? (Select all that apply)
Answer: B,D,E
Explanation:
Options A, B, and D are correct. A ensures efficient comparison and join execution. B leverages broadcast join when smaller dataframe is broadcasted to all nodes, reducing data movement. D reduces the size of the larger DataFrame before the join, improving performance. C is incorrect because caching the larger 'transaction_df DataFrame before the join won't significantly improve performance; Snowpark automatically optimizes query execution. E is wrong because Snowflake manages join algorithms efficiently, forcing a specific algorithm might be counterproductive.
NEW QUESTION # 68
You are building a Snowpark application that requires you to connect to Snowflake from an environment where directly specifying credentials in the code is not permitted for security reasons. Which of the following are valid and recommended ways to securely pass authentication information to the Snowpark Session?
Answer: B,D,E
Explanation:
Options A, C, and D represent valid ways to handle credentials securely. Environment variables (A) are a standard practice for configurations. Using a secret management service (C) provides the best security posture for production environments. Using the Snowflake CLI (D) is acceptable for development. Storing credentials in a Snowflake stage (B) adds unnecessary complexity and doesn't inherently improve security over other options. Base64 encoding (E) is not a secure method; it's easily decoded and provides a false sense of security. Hardcoding and obfuscating credentials is not recommended.
NEW QUESTION # 69
A data engineer wants to create a Snowpark session using environment variables defined in a .env' file. The file contains the following: SNOWFLAKE ACCOUNT=myaccount.snowflakecomputing.com SNOWFLAKE USER=snowpark_user SNOWFLAKE SNOWFLAKE DATABASE=mydb SNOWFLAKE SCHEMA=myschema SNOWFLAKE WAREHOUSE=mywarehouse Which code snippet correctly establishes a Snowpark session using these environment variables?





Answer: E
Explanation:
Option E is the most concise and recommended way to create a Snowpark session using environment variables defined in a .env file, by using method. Option B works but requires manual loading of environment variables. Options A and C do not correctly access environment variables. Option D would require the environment variables to be named exactly as the session builder expects and doesn't use the dotenv library which is designed for this purpose.
NEW QUESTION # 70
You are using Snowpark Python to process a large dataset. You need to persist a DataFrame to a Snowflake table but want to ensure the operation is as efficient as possible and minimizes the data transfer overhead. The table already exists with the appropriate schema. Which of the following strategies would be the MOST efficient way to write the DataFrame to the existing table?
Answer: B
Explanation:
is generally the most efficient method for appending data to an existing Snowflake table using Snowpark. It directly inserts the data into the table without the overhead of creating a new table or overwriting the existing one. with the default 'append' mode (A) might work, but 'insertlnto' is more explicit and potentially optimized for this specific scenario. (B) would replace the entire table, which is not efficient if you only want to add new data. Creating a temporary table and then using 'CREATE OR REPLACE TABLE AS SELECT (D) involves unnecessary steps and data transfer. Writing to a stage and then using 'COPY INTO' (E) is also less efficient than directly inserting the data using Snowpark.
NEW QUESTION # 71
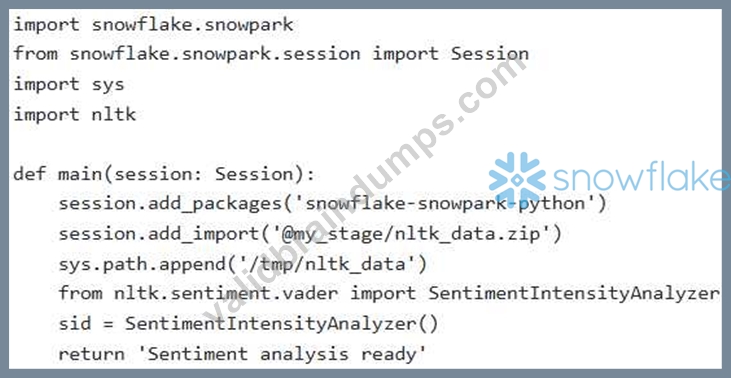
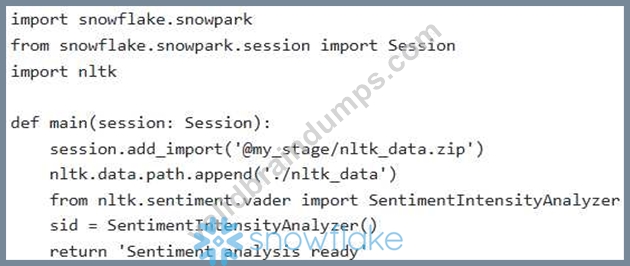
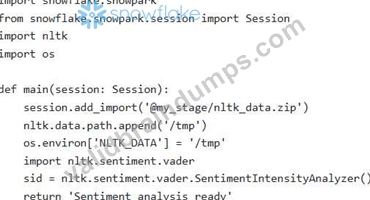
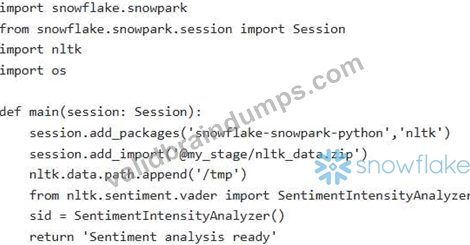
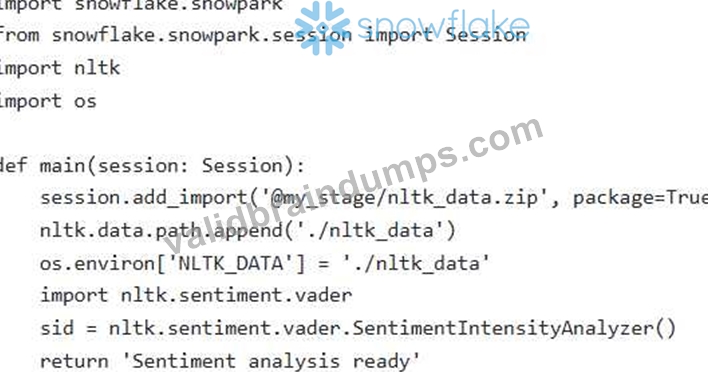
You are developing a Snowpark stored procedure to perform sentiment analysis on customer reviews. You need to use the 'nltk' Python package, which is not a built-in package in Snowflake. You have already created a stage named 'my_stage' in Snowflake and uploaded the necessary nltk data files (e.g., 'vader_lexicon.zip') to the stage. Which of the following code snippets correctly configures the session and imports the required nltk components within the stored procedure?
Answer: C
Explanation:
Option E correctly adds the zipped nltk data file from the stage as an import, and then updates the NLTK_DATA environment variable to point to the /tmp directory where Snowflake unpacks the zip file. This ensures that nltk can find its data files. Option A and D attempt to use './nltk_data' which is incorrect as the file system is read-only, and Option B incorrectly uses sys.path.append and session.add_packages in wrong way as well as hard coded path. Option C fails as well with session.add_packages('snowflake-snowpark-python','nltk') incorrect syntax .
NEW QUESTION # 72
......
All of the traits above are available in this web-based SPS-C01 practice test of ValidBraindumps. The main distinction is that the Snowflake SPS-C01 online practice test works with not only Windows but also Mac, Linux, iOS, and Android. Above all, taking the SPS-C01 web-based practice test while preparing for the examination does not need any software installation. Furthermore, MS Edge, Internet Explorer, Opera, Safari, Chrome, and Firefox support the web-based Snowflake SPS-C01 practice test of ValidBraindumps.
Discount SPS-C01 Code: https://www.validbraindumps.com/SPS-C01-exam-prep.html