Databricks-Generative-AI-Engineer-Associate Latest Exam Guide Help You Pass Exam with High Pass Rate - ExamDiscuss
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by ExamDiscuss: https://drive.google.com/open?id=1hPXLP_mi1GDIaoGwvlRvqipX64vS2Ylp
As a professional website, ExamDiscuss offers you the latest and valid Databricks-Generative-AI-Engineer-Associate test questions and latest learning materials, which are composed by our experienced IT elites and trainers. They have rich experience in the Databricks actual test and are good at making learning strategy for people who want to pass the Databricks-Generative-AI-Engineer-Associate Practice Exam.
| Topic | Details |
|---|
| Topic 1 | - Design Applications: The topic focuses on designing a prompt that elicits a specifically formatted response. It also focuses on selecting model tasks to accomplish a given business requirement. Lastly, the topic covers chain components for a desired model input and output.
|
| Topic 2 | - Application Development: In this topic, Generative AI Engineers learn about tools needed to extract data, Langchain
- similar tools, and assessing responses to identify common issues. Moreover, the topic includes questions about adjusting an LLM's response, LLM guardrails, and the best LLM based on the attributes of the application.
|
| Topic 3 | - Data Preparation: Generative AI Engineers covers a chunking strategy for a given document structure and model constraints. The topic also focuses on filter extraneous content in source documents. Lastly, Generative AI Engineers also learn about extracting document content from provided source data and format.
|
| Topic 4 | - Assembling and Deploying Applications: In this topic, Generative AI Engineers get knowledge about coding a chain using a pyfunc mode, coding a simple chain using langchain, and coding a simple chain according to requirements. Additionally, the topic focuses on basic elements needed to create a RAG application. Lastly, the topic addresses sub-topics about registering the model to Unity Catalog using MLflow.
|
| Topic 5 | - Evaluation and Monitoring: This topic is all about selecting an LLM choice and key metrics. Moreover, Generative AI Engineers learn about evaluating model performance. Lastly, the topic includes sub-topics about inference logging and usage of Databricks features.
|
>> Latest Databricks-Generative-AI-Engineer-Associate Guide Files <<
Databricks-Generative-AI-Engineer-Associate Reliable Practice Questions & Databricks-Generative-AI-Engineer-Associate Exam Training Material & Databricks-Generative-AI-Engineer-Associate Pdf Vce
After purchasing the Databricks-Generative-AI-Engineer-Associate exam dumps from ExamDiscuss, you will have access to three formats designed by ExamDiscuss for the preparation of the Databricks Databricks-Generative-AI-Engineer-Associate exam. These Databricks Certified Generative AI Engineer Associate exam dumps formats will provide actual Databricks Databricks-Generative-AI-Engineer-Associate PDF Questions to help you prepare for the Databricks Databricks-Generative-AI-Engineer-Associate exam.
Databricks Certified Generative AI Engineer Associate Sample Questions (Q87-Q92):
NEW QUESTION # 87
A company has a typical RAG-enabled, customer-facing chatbot on its website.
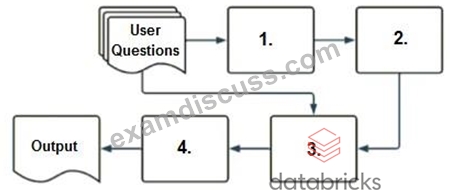
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
- A. 1.response-generating LLM, 2.vector search, 3.context-augmented prompt, 4.embedding model
- B. 1.context-augmented prompt, 2.vector search, 3.embedding model, 4.response-generating LLM
- C. 1.embedding model, 2.vector search, 3.context-augmented prompt, 4.response-generating LLM
- D. 1.response-generating LLM, 2.context-augmented prompt, 3.vector search, 4.embedding model
Answer: C
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
Embedding Model (1):
The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
Vector Search (2):
The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
Context-Augmented Prompt (3):
The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
Response-Generating LLM (4):
Finally, the context-augmented prompt is fed into a response-generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response-generating LLM, which is option A.
NEW QUESTION # 88
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error:
Python
from langchain.chains import LLMChain
from langchain_community.llms import OpenAI
from langchain_core.prompts import PromptTemplate
prompt_template = " Tell me a {adjective} joke "
prompt = PromptTemplate(input_variables=[ " adjective " ], template=prompt_template)
# ... (Error-prone section)
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
- A. (Incorrect structure)
- B. prompt_template = " Tell me a {adjective} joke "
prompt = PromptTemplate(input_variables=[ " adjective " ], template=prompt_template) llm = OpenAI() llm_chain = LLMChain(prompt=prompt, llm=llm) llm_chain.generate([{ " adjective " : " funny " }]) - C. (Incorrect structure)
- D. (Incorrect structure)
Answer: B
NEW QUESTION # 89
A Generative AI Engineer I using the code below to test setting up a vector store:
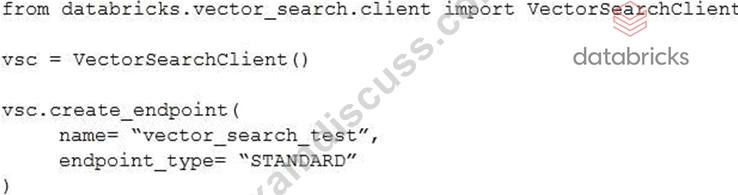
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
- A. vsc.similarity_search()
- B. vsc.get_index()
- C. vsc.create_direct_access_index()
- D. vsc.create_delta_sync_index()
Answer: D
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 90
A Generative AI Engineer has created a RAG application which can help employees retrieve answers from an internal knowledge base, such as Confluence pages or Google Drive. The prototype application is now working with some positive feedback from internal company testers. Now the Generative Al Engineer wants to formally evaluate the system's performance and understand where to focus their efforts to further improve the system.
How should the Generative AI Engineer evaluate the system?
- A. Curate a dataset that can test the retrieval and generation components of the system separately. Use MLflow's built in evaluation metrics to perform the evaluation on the retrieval and generation components.
- B. Use an LLM-as-a-judge to evaluate the quality of the final answers generated.
- C. Use cosine similarity score to comprehensively evaluate the quality of the final generated answers.
- D. Benchmark multiple LLMs with the same data and pick the best LLM for the job.
Answer: A
Explanation:
* Problem Context: After receiving positive feedback for the RAG application prototype, the next step is to formally evaluate the system to pinpoint areas for improvement.
* Explanation of Options:
* Option A: While cosine similarity scores are useful, they primarily measure similarity rather than the overall performance of an RAG system.
* Option B: This option provides a systematic approach to evaluation by testing both retrieval and generation components separately. This allows for targeted improvements and a clear understanding of each component's performance, using MLflow's metrics for a structured and standardized assessment.
* Option C: Benchmarking multiple LLMs does not focus on evaluating the existing system's components but rather on comparing different models.
* Option D: Using an LLM as a judge is subjective and less reliable for systematic performance evaluation.
OptionBis the most comprehensive and structured approach, facilitating precise evaluations and improvements on specific components of the RAG system.
NEW QUESTION # 91
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error:
Python
from langchain.chains import LLMChain
from langchain_community.llms import OpenAI
from langchain_core.prompts import PromptTemplate
prompt_template = "Tell me a {adjective} joke"
prompt = PromptTemplate(input_variables=["adjective"], template=prompt_template)
# ... (Error-prone section)
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
- A. (Incorrect structure)
- B. (Incorrect structure)
- C. (Incorrect structure)
- D. prompt_template = "Tell me a {adjective} joke"
prompt = PromptTemplate(input_variables=["adjective"], template=prompt_template) llm = OpenAI() llm_chain = LLMChain(prompt=prompt, llm=llm) llm_chain.generate([{"adjective": "funny"}])
Answer: D
Explanation:
The error in the original snippet usually stems from the improper instantiation of the LLMChain or the incorrect call to the .generate() method. In LangChain, an LLMChain requires two primary components: an LLM (the engine) and a Prompt (the template). Option C provides the correct syntax: first, the PromptTemplate is defined with the correct input_variables. Second, the OpenAI model is instantiated. Third, the LLMChain binds the model and the prompt together. Finally, the .generate() method expects a list of dictionaries, where each dictionary represents a set of inputs for the prompt variables. Options A, B, and D in the original image contain syntax errors such as passing the variable directly into the chain initialization or missing the dictionary list format required by the standard LangChain API for batch-like generation.
NEW QUESTION # 92
......
Dreaming to be a certified professional in this line? Our Databricks-Generative-AI-Engineer-Associate study materials are befitting choices. We made real test materials in three accessible formats for your inclinations. (PDF, APP, software). Our website is an excellent platform, which provides the questions of these versions of our Databricks-Generative-AI-Engineer-Associate Exam Questions compiled by experts. By browsing this website, all there versions of our Databricks-Generative-AI-Engineer-Associate pratice engine can be chosen according to your taste or preference.
100% Databricks-Generative-AI-Engineer-Associate Correct Answers: https://www.examdiscuss.com/Databricks/exam/Databricks-Generative-AI-Engineer-Associate/
- Accurate Databricks-Generative-AI-Engineer-Associate Test 📏 Databricks-Generative-AI-Engineer-Associate Certification 🎭 Training Databricks-Generative-AI-Engineer-Associate Material 🦑 Search for ▶ Databricks-Generative-AI-Engineer-Associate ◀ and obtain a free download on { www.dumpsmaterials.com } 🙀Databricks-Generative-AI-Engineer-Associate Free Braindumps
- Accurate Databricks-Generative-AI-Engineer-Associate Test 🐊 Databricks-Generative-AI-Engineer-Associate Exam Duration 🕍 Valid Databricks-Generative-AI-Engineer-Associate Exam Materials 📀 Easily obtain ▶ Databricks-Generative-AI-Engineer-Associate ◀ for free download through ⮆ www.pdfvce.com ⮄ 🚇Exams Databricks-Generative-AI-Engineer-Associate Torrent
- New Databricks-Generative-AI-Engineer-Associate Test Testking 🎄 Databricks-Generative-AI-Engineer-Associate New Dumps Files 🔬 Databricks-Generative-AI-Engineer-Associate Hot Questions 🕒 Search for ⮆ Databricks-Generative-AI-Engineer-Associate ⮄ and download exam materials for free through ⇛ www.practicevce.com ⇚ 📦Training Databricks-Generative-AI-Engineer-Associate Material
- Databricks-Generative-AI-Engineer-Associate Reliable Dumps 🎣 Certification Databricks-Generative-AI-Engineer-Associate Questions ⬅ Databricks-Generative-AI-Engineer-Associate Hot Questions 🐒 Search for 【 Databricks-Generative-AI-Engineer-Associate 】 and obtain a free download on ➠ www.pdfvce.com 🠰 👣Valid Databricks-Generative-AI-Engineer-Associate Exam Materials
- Databricks Databricks-Generative-AI-Engineer-Associate Exam Dumps - Smart Way To Get Success 😀 Download ( Databricks-Generative-AI-Engineer-Associate ) for free by simply searching on [ www.prepawaypdf.com ] 🎄Databricks-Generative-AI-Engineer-Associate Reliable Dumps
- Databricks-Generative-AI-Engineer-Associate Certification 🔲 Databricks-Generative-AI-Engineer-Associate Hot Questions 👫 Latest Databricks-Generative-AI-Engineer-Associate Exam Answers 🌐 Download ▶ Databricks-Generative-AI-Engineer-Associate ◀ for free by simply entering 「 www.pdfvce.com 」 website 👉Databricks-Generative-AI-Engineer-Associate Reliable Study Notes
- Accurate Databricks-Generative-AI-Engineer-Associate Test 🕜 Valid Databricks-Generative-AI-Engineer-Associate Exam Materials 🏏 Databricks-Generative-AI-Engineer-Associate Hot Questions ⏫ Search for ⇛ Databricks-Generative-AI-Engineer-Associate ⇚ and download exam materials for free through ⏩ www.testkingpass.com ⏪ ⭕New Databricks-Generative-AI-Engineer-Associate Test Testking
- Relevant Databricks-Generative-AI-Engineer-Associate Questions 💛 Accurate Databricks-Generative-AI-Engineer-Associate Test 🚋 Training Databricks-Generative-AI-Engineer-Associate Material 🦹 Download ⇛ Databricks-Generative-AI-Engineer-Associate ⇚ for free by simply searching on ⏩ www.pdfvce.com ⏪ 🦐Accurate Databricks-Generative-AI-Engineer-Associate Test
- New Databricks-Generative-AI-Engineer-Associate Test Testking 🔛 Databricks-Generative-AI-Engineer-Associate Exam Duration 🚒 Databricks-Generative-AI-Engineer-Associate Certification 🍍 Download ▶ Databricks-Generative-AI-Engineer-Associate ◀ for free by simply searching on ✔ www.troytecdumps.com ️✔️ 🌱Databricks-Generative-AI-Engineer-Associate Latest Exam Papers
- Databricks-Generative-AI-Engineer-Associate Study Guide: Databricks Certified Generative AI Engineer Associate - Databricks-Generative-AI-Engineer-Associate Practice Test - Databricks Certified Generative AI Engineer Associate Learning Materials ✏ Open ➡ www.pdfvce.com ️⬅️ enter “ Databricks-Generative-AI-Engineer-Associate ” and obtain a free download ☃Latest Databricks-Generative-AI-Engineer-Associate Exam Answers
- Updated Databricks-Generative-AI-Engineer-Associate Practice Exam Questions 🦁 Search for ✔ Databricks-Generative-AI-Engineer-Associate ️✔️ on ▷ www.vce4dumps.com ◁ immediately to obtain a free download 🚍Latest Databricks-Generative-AI-Engineer-Associate Exam Answers
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BTW, DOWNLOAD part of ExamDiscuss Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1hPXLP_mi1GDIaoGwvlRvqipX64vS2Ylp