DOWNLOAD the newest Dumpcollection Professional-Data-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1S-JtpUIu7hsMNRePtpk_dYTjeXyvJxOE
We all have the right to pursue happiness. Also, we have the chance to generate a golden bowl for ourselves. Now, our Professional-Data-Engineer practice materials can help you achieve your goals. As we all know, the pace of life is quickly in the modern society. So we must squeeze time to learn and become better. With the Professional-Data-Engineer Certification, your life will be changed thoroughly for you may find better jobs and gain higher incomes to lead a better life style. And our Professional-Data-Engineer exam questions will be your best assistant.
| Section | Weight | Objectives |
|---|---|---|
| Operationalizing machine learning models | 26% | - ML pipeline integration
|
| Ensuring solution quality | 28% | - Reliability and performance
|
| Designing data processing systems | 22% | - Batch and streaming data processing design
|
| Building and operationalizing data processing systems | 24% | - Data ingestion and integration
|
>> Professional-Data-Engineer Pass4sure Dumps Pdf <<
Under the support of our study materials, passing the exam won’t be an unreachable mission. More detailed information is under below. We are pleased that you can spare some time to have a look for your reference about our Professional-Data-Engineer test prep. As long as you spare one or two hours a day to study with our laTest Professional-Data-Engineer Quiz prep, we assure that you will have a good command of the relevant knowledge before taking the exam. What you need to do is to follow the Professional-Data-Engineer exam guide system at the pace you prefer as well as keep learning step by step.
NEW QUESTION # 153
Flowlogistic Case Study
Company Overview
Flowlogistic is a leading logistics and supply chain provider. They help businesses throughout the world
manage their resources and transport them to their final destination. The company has grown rapidly,
expanding their offerings to include rail, truck, aircraft, and oceanic shipping.
Company Background
The company started as a regional trucking company, and then expanded into other logistics market.
Because they have not updated their infrastructure, managing and tracking orders and shipments has
become a bottleneck. To improve operations, Flowlogistic developed proprietary technology for tracking
shipments in real time at the parcel level. However, they are unable to deploy it because their technology
stack, based on Apache Kafka, cannot support the processing volume. In addition, Flowlogistic wants to
further analyze their orders and shipments to determine how best to deploy their resources.
Solution Concept
Flowlogistic wants to implement two concepts using the cloud:
Use their proprietary technology in a real-time inventory-tracking system that indicates the location of
their loads
Perform analytics on all their orders and shipment logs, which contain both structured and unstructured
data, to determine how best to deploy resources, which markets to expand info. They also want to use
predictive analytics to learn earlier when a shipment will be delayed.
Existing Technical Environment
Flowlogistic architecture resides in a single data center:
Databases
8 physical servers in 2 clusters
- SQL Server - user data, inventory, static data
3 physical servers
- Cassandra - metadata, tracking messages
10 Kafka servers - tracking message aggregation and batch insert
Application servers - customer front end, middleware for order/customs
60 virtual machines across 20 physical servers
- Tomcat - Java services
- Nginx - static content
- Batch servers
Storage appliances
- iSCSI for virtual machine (VM) hosts
- Fibre Channel storage area network (FC SAN) - SQL server storage
- Network-attached storage (NAS) image storage, logs, backups
10 Apache Hadoop /Spark servers
- Core Data Lake
- Data analysis workloads
20 miscellaneous servers
- Jenkins, monitoring, bastion hosts,
Business Requirements
Build a reliable and reproducible environment with scaled panty of production.
Aggregate data in a centralized Data Lake for analysis
Use historical data to perform predictive analytics on future shipments
Accurately track every shipment worldwide using proprietary technology
Improve business agility and speed of innovation through rapid provisioning of new resources
Analyze and optimize architecture for performance in the cloud
Migrate fully to the cloud if all other requirements are met
Technical Requirements
Handle both streaming and batch data
Migrate existing Hadoop workloads
Ensure architecture is scalable and elastic to meet the changing demands of the company.
Use managed services whenever possible
Encrypt data flight and at rest
Connect a VPN between the production data center and cloud environment
SEO Statement
We have grown so quickly that our inability to upgrade our infrastructure is really hampering further growth
and efficiency. We are efficient at moving shipments around the world, but we are inefficient at moving
data around.
We need to organize our information so we can more easily understand where our customers are and
what they are shipping.
CTO Statement
IT has never been a priority for us, so as our data has grown, we have not invested enough in our
technology. I have a good staff to manage IT, but they are so busy managing our infrastructure that I
cannot get them to do the things that really matter, such as organizing our data, building the analytics, and
figuring out how to implement the CFO' s tracking technology.
CFO Statement
Part of our competitive advantage is that we penalize ourselves for late shipments and deliveries. Knowing
where out shipments are at all times has a direct correlation to our bottom line and profitability.
Additionally, I don't want to commit capital to building out a server environment.
Flowlogistic's CEO wants to gain rapid insight into their customer base so his sales team can be better
informed in the field. This team is not very technical, so they've purchased a visualization tool to simplify
the creation of BigQuery reports. However, they've been overwhelmed by all the data in the table, and are
spending a lot of money on queries trying to find the data they need. You want to solve their problem in the
most cost-effective way. What should you do?
Answer: A
NEW QUESTION # 154
You've migrated a Hadoop job from an on-prem cluster to dataproc and GCS. Your Spark job is a complicated analytical workload that consists of many shuffing operations and initial data are parquet files (on average
200-400 MB size each). You see some degradation in performance after the migration to Dataproc, so you'd like to optimize for it. You need to keep in mind that your organization is very cost-sensitive, so you'd like to continue using Dataproc on preemptibles (with 2 non-preemptible workers only) for this workload.
What should you do?
Answer: A
NEW QUESTION # 155
You are selecting services to write and transform JSON messages from Cloud Pub/Sub to BigQuery for a data pipeline on Google Cloud. You want to minimize service costs. You also want to monitor and accommodate input data volume that will vary in size with minimal manual intervention. What should you do?
Answer: B
Explanation:
Explanation
NEW QUESTION # 156
The Development and External teams nave the project viewer Identity and Access Management (1AM) role m a folder named Visualization. You want the Development Team to be able to read data from both Cloud Storage and BigQuery, but the External Team should only be able to read data from BigQuery. What should you do?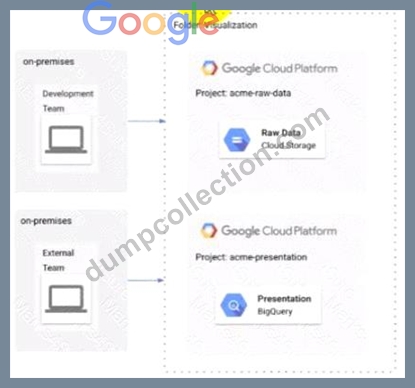
Answer: A
NEW QUESTION # 157
You work for a large real estate firm and are preparing 6 TB of home sales data to be used for machine learning. You will use SQL to transform the data and use BigQuery ML to create a machine learning model. You plan to use the model for predictions against a raw dataset that has not been transformed. How should you set up your workflow in order to prevent skew at prediction time?
Answer: D
Explanation:
Using the TRANSFORM clause, you can specify all preprocessing during model creation. The preprocessing is automatically applied during the prediction and evaluation phases of machine learning.
Reference:
https://cloud.google.com/bigquery-ml/docs/bigqueryml-transform
NEW QUESTION # 158
......
We provide three versions of Professional-Data-Engineer study materials to the client and they include PDF version, PC version and APP online version. Different version boosts own advantages and using methods. The content of Professional-Data-Engineer exam torrent is the same but different version is suitable for different client. For example, the PC version of Professional-Data-Engineer Study Materials supports the computer with Windows system and its advantages includes that it simulates real operation Professional-Data-Engineer exam environment and it can simulates the exam and you can attend time-limited exam on it. Most candidates liked and passed with this version.
Professional-Data-Engineer Exam Answers: https://www.dumpcollection.com/Professional-Data-Engineer_braindumps.html
BTW, DOWNLOAD part of Dumpcollection Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1S-JtpUIu7hsMNRePtpk_dYTjeXyvJxOE