2026年It-Passportsの最新Professional-Machine-Learning-Engineer PDFダンプおよびProfessional-Machine-Learning-Engineer試験エンジンの無料共有:https://drive.google.com/open?id=1vb7I6VC40gPQQSf27cdRzhUQZg08qL-B
It-Passportsが提供した教育資料は真実のテストに非常に近くて、あなたが弊社の短期の特殊訓練問題を通じてすぐにGoogle専門の知識を身につけられます。弊社は君のProfessional-Machine-Learning-Engineer試験の100%合格率を保証いたします。
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Available Languages: | English, Japanese |
| Related Certifications: | Google Cloud Professional Data Engineer Google Cloud Professional Cloud Architect |
| Exam Duration: | 120 minutes |
| Exam Price: | $200 USD (plus tax where applicable) |
| Exam Format: | Multiple select, Multiple choice |
| Real Exam Qty: | 50-60 |
| Certificate Validity Period: | 2 years |
| Passing Score: | Not officially published, approximately 70% |
| Recommended Training: | Official Exam Guide Google Cloud Skills Boost - Professional Machine Learning Engineer Learning Path |
| Exam Registration: | Google Cloud Certification Registration |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online-proctored remote exam or onsite-proctored exam at authorized test centers |
| Pre Condition: | No mandatory prerequisites; recommended 3+ years industry experience including 1+ year designing/managing Google Cloud solutions |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/machine-learning-engineer |
>> Professional-Machine-Learning-Engineer認定資格試験問題集 <<
Professional-Machine-Learning-Engineer問題集はオンライン版、ソフト版、とPDF版がありますので、とても便利です。Professional-Machine-Learning-Engineer問題集を購入すれば、あなたはいつでもどこでも勉強することができます。Professional-Machine-Learning-Engineer問題集はIT専門家が長年の研究したことです。従って、高品質で、Professional-Machine-Learning-Engineer試験の合格率が高いです。毎年、たくさんの人がProfessional-Machine-Learning-Engineer試験に参加し、合格しました。あなたはProfessional-Machine-Learning-Engineer問題集を利用すれば、Professional-Machine-Learning-Engineer試験に合格できますよ。もし、将来に、IT専門家になります。
試験はデータ前処理、モデル選択、特徴量エンジニアリング、ハイパーパラメーターチューニング、モデル展開など、幅広いトピックをカバーしています。試験では、線形回帰、ロジスティック回帰、決定木、ランダムフォレスト、ニューラルネットワーク、ディープラーニングなどの機械学習アルゴリズムに関する候補者の知識もテストされます。試験に合格するためには、これらのトピックについて深い理解を持ち、実世界のシナリオでの実践的な応用を示すことが必要です。
質問 # 85
You work for an online retail company that is creating a visual search engine. You have set up an end-to-end ML pipeline on Google Cloud to classify whether an image contains your company's product. Expecting the release of new products in the near future, you configured a retraining functionality in the pipeline so that new data can be fed into your ML models. You also want to use Al Platform's continuous evaluation service to ensure that the models have high accuracy on your test data set. What should you do?
正解:B
解説:
The test dataset is used to evaluate the performance of the ML model on unseen data. It should reflect the distribution of the data that the model will encounter in production. Therefore, if the retraining data includes new products, the test dataset should also be extended with images of those products to ensure that the model can generalize well to them. Keeping the original test dataset unchanged or replacing it entirely with images of the new products would not capture the diversity of the data that the model needs to handle. Updating the test dataset only when the evaluation metrics drop below a threshold would be reactive rather than proactive, and might result in poor user experience if the model fails to recognize the new products. Reference:
Continuous evaluation documentation
Preparing and using test sets
質問 # 86
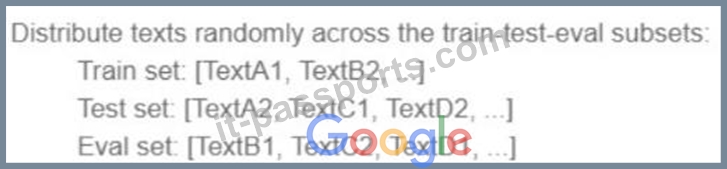
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: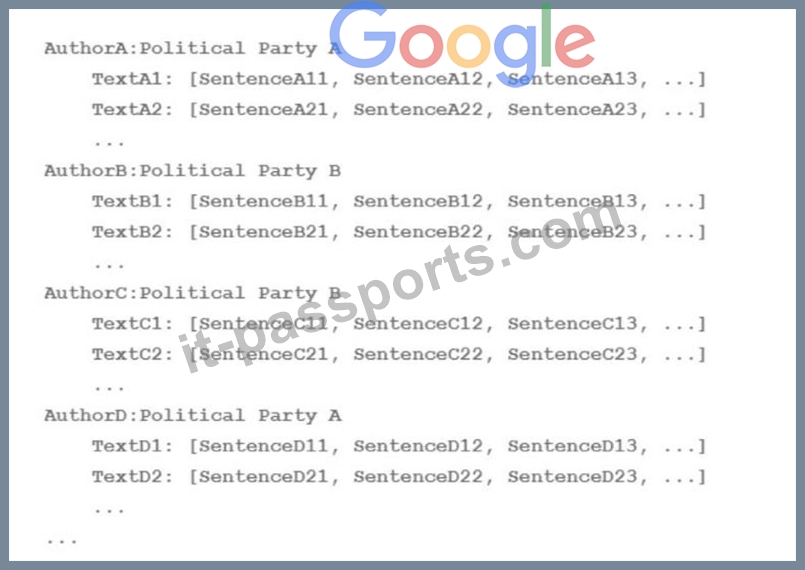
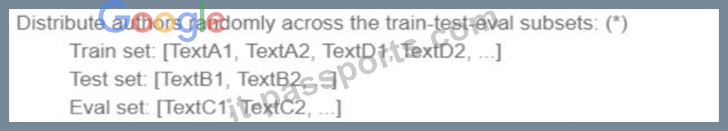
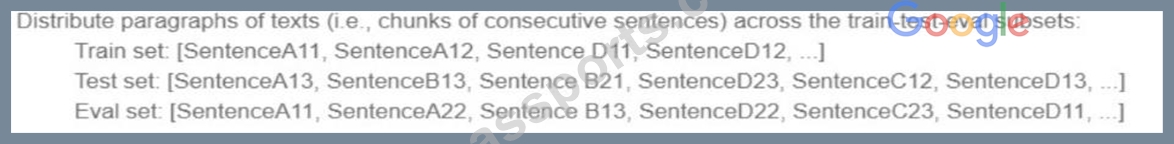
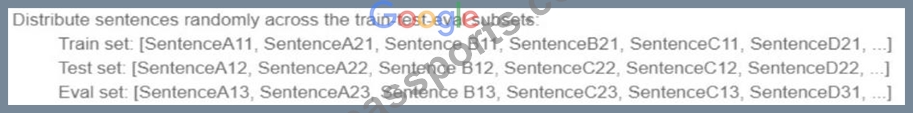
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets. How should you distribute the training examples across the train-test-eval subsets while maintaining the 80-10-10 proportion?
正解:A
解説:
If we just put inside the Training set , Validation set and Test set , randomly Text, Paragraph or sentences the model will have the ability to learn specific qualities about The Author's use of language beyond just his own articles. Therefore the model will mixed up different opinions. Rather if we divided things up a the author level, so that given authors were only on the training data, or only in the test data or only in the validation data. The model will find more difficult to get a high accuracy on the test validation (What is correct and have more sense!). Because it will need to really focus in author by author articles rather than get a single political affiliation based on a bunch of mixed articles from different authors. https://developers.google.com/machine-learning/crash-course/18th-century-literature For example, suppose you are training a model with purchase data from a number of stores. You know, however, that the model will be used primarily to make predictions for stores that are not in the training data. To ensure that the model can generalize to unseen stores, you should segregate your data sets by stores. In other words, your test set should include only stores different from the evaluation set, and the evaluation set should include only stores different from the training set. https://cloud.google.com/automl-tables/docs/prepare#ml-use
質問 # 87
You work for a manufacturing company that owns a high-value machine which has several machine settings and multiple sensors. A history of the machine's hourly sensor readings and known failure event data are stored in BigQuery. You need to predict if the machine will fail within the next 3 days in order to schedule maintenance before the machine fails. Which data preparation and model training steps should you take?
正解:A
解説:
A is not correct because a rolling average is a better feature engineering technique, as it will smooth out the noise and fluctuation in the data to demonstrate whether there is a trend. Using the max value could be an artifact of some noise and may not capture the trend accurately.
B is not correct because a rolling average is a better feature engineering technique, as it will smooth out the noise and fluctuation in the data to demonstrate whether there is a trend. Using the min value could be an artifact of some noise and may not capture the trend accurately.
C is not correct because the model training does not balance class labels for an imbalanced dataset.
D is correct because it uses the rolling average of the sensor data and balances the weights using the BQML auto class weight balance parameter.
https://cloud.google.com/dataprep/docs/html/ROLLINGAVERAGE-Function_57344753
https://cloud.google.com/dataprep/docs/html/AVERAGE-Function_57344661
https://cloud.google.com/bigquery-ml/docs/reference/standard-sql/bigqueryml-syntax-create
https://en.wikipedia.org/wiki/Precision_and_recall
https://en.wikipedia.org/wiki/Sensitivity_and_specificity
https://en.wikipedia.org/wiki/Moving_average
質問 # 88
You are training an LSTM-based model on Al Platform to summarize text using the following job submission script: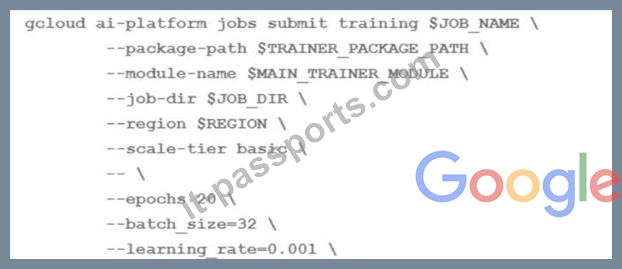
You want to ensure that training time is minimized without significantly compromising the accuracy of your model. What should you do?
正解:B
解説:
The training time of a machine learning model depends on several factors, such as the complexity of the model, the size of the data, the hardware resources, and the hyperparameters. To minimize the training time without significantly compromising the accuracy of the model, one should optimize these factors as much as possible.
One of the factors that can have a significant impact on the training time is the scale-tier parameter, which specifies the type and number of machines to use for the training job on AI Platform. The scale-tier parameter can be one of the predefined values, such as BASIC, STANDARD_1, PREMIUM_1, or BASIC_GPU, or a custom value that allows you to configure the machine type, the number of workers, and the number of parameter servers1 To speed up the training of an LSTM-based model on AI Platform, one should modify the scale-tier parameter to use a higher tier or a custom configuration that provides more computational resources, such as more CPUs, GPUs, or TPUs. This can reduce the training time by increasing the parallelism and throughput of the model training. However, one should also consider the trade-off between the training time and the cost, as higher tiers or custom configurations may incur higher charges2 The other options are not as effective or may have adverse effects on the model accuracy. Modifying the epochs parameter, which specifies the number of times the model sees the entire dataset, may reduce the training time, but also affect the model's convergence and performance. Modifying the batch size parameter, which specifies the number of examples per batch, may affect the model's stability and generalization ability, as well as the memory usage and the gradient update frequency. Modifying the learning rate parameter, which specifies the step size of the gradient descent optimization, may affect the model's convergence and performance, as well as the risk of overshooting or getting stuck in local minima3 References: 1: Using predefined machine types 2: Distributed training 3: Hyperparameter tuning overview
質問 # 89
You are building a predictive maintenance model to preemptively detect part defects in bridges. You plan to use high definition images of the bridges as model inputs. You need to explain the output of the model to the relevant stakeholders so they can take appropriate action. How should you build the model?
正解:A
解説:
According to the official exam guide1, one of the skills assessed in the exam is to "explain the predictions of a trained model". TensorFlow2 is an open source framework for developing and deploying machine learning and deep learning models. TensorFlow supports various model explainability methods, such as Integrated Gradients3, which is a technique that assigns an importance score to each input feature by approximating the integral of the gradients along the path from a baseline input to the actual input. Integrated Gradients can help explain the output of a deep learning-based model by highlighting the most influential features in the input images. Therefore, option C is the best way to build the model for the given use case. The other options are not relevant or optimal for this scenario. References:
* Professional ML Engineer Exam Guide
* TensorFlow
* Integrated Gradients
* Google Professional Machine Learning Certification Exam 2023
* Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
質問 # 90
......
Professional-Machine-Learning-Engineer基礎問題集: https://www.it-passports.com/Professional-Machine-Learning-Engineer.html
無料でクラウドストレージから最新のIt-Passports Professional-Machine-Learning-Engineer PDFダンプをダウンロードする:https://drive.google.com/open?id=1vb7I6VC40gPQQSf27cdRzhUQZg08qL-B