Some candidates may considerate whether the Databricks-Certified-Professional-Data-Engineer exam guide is profession, but it can be sure that the contents of our study materials are compiled by industry experts after them refining the contents of textbooks, they have good knowledge of exam. Databricks-Certified-Professional-Data-Engineer test questions also has an automatic scoring function, giving you an objective rating after you take a mock exam to let you know your true level. With Databricks-Certified-Professional-Data-Engineer Exam Guide, you only need to spend 20-30 hours to study and you can successfully pass the exam. You will no longer worry about your exam because of bad study materials. If you decide to choose and practice our Databricks-Certified-Professional-Data-Engineer test questions, our life will be even more exciting.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Real Exam Qty: | 60-70 |
| Exam Format: | Multiple select, Scenario-based questions, Multiple choice |
| Certificate Validity Period: | 2 years |
| Related Certifications: | Databricks Certified Data Engineer Associate |
| Exam Price: | USD 200 |
| Exam Duration: | 120 minutes |
| Passing Score: | 70% |
| Available Languages: | English |
| Recommended Training: | Databricks Academy |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | Recommended: Databricks Certified Data Engineer Associate or equivalent experience with Spark and Databricks platform. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> New Databricks-Certified-Professional-Data-Engineer Test Bootcamp <<
We stand behind all of our customers, so we provide you with the best valid and useful Databricks Databricks-Certified-Professional-Data-Engineer exam training. Regular and frequent updates for Databricks-Certified-Professional-Data-Engineer dumps are necessary, so you can get hold of the Databricks-Certified-Professional-Data-Engineer updated exam material every time. Besides, we offer the exact questions with correct answers, which can ensure you 100% pass in your Databricks Databricks-Certified-Professional-Data-Engineer Actual Test. We have 100% money back guarantee, in case of failure, we will give you full refund.
Databricks Certified Professional Data Engineer exam consists of multiple-choice questions and is conducted online. Databricks-Certified-Professional-Data-Engineer exam is intended to measure the candidate's proficiency in various areas, such as Spark architecture, Spark programming, data processing, data analysis, and data modeling. Databricks-Certified-Professional-Data-Engineer exam also tests the candidate's ability to optimize Spark performance and troubleshoot Spark applications. It is recommended that individuals who plan to take Databricks-Certified-Professional-Data-Engineer exam have at least two years of hands-on experience in big data technologies and Apache Spark.
The Databricks Databricks-Certified-Professional-Data-Engineer Exam consists of multiple-choice questions and hands-on tasks that test the candidate's practical knowledge of Databricks. Databricks-Certified-Professional-Data-Engineer exam covers a wide range of topics such as data engineering, data processing, ETL, data modeling, data warehousing, data governance, and data security. Databricks-Certified-Professional-Data-Engineer exam is designed to evaluate the candidate's ability to design and implement scalable data pipelines using Databricks.
NEW QUESTION # 85
Given the following PySpark code snippet in a Databricks notebook:
filtered_df = spark.read.format("delta").load("/mnt/data/large_table") \
.filter("event_date > '2024-01-01'")
filtered_df.count()
The data engineer notices from the Query Profiler that the scan operator for filtered_df is reading almost all files, despite the filter being applied.
What is the probable reason for poor data skipping?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Delta Lake's data skipping and file pruning optimizations rely on metadata about columns used in partitioning or Z-ordering. If a filter column (e.g., event_date) is not included in the partition or Z-ordering keys, Spark cannot effectively prune files at query time, resulting in full table scans. The Databricks optimization guide states that "File pruning and data skipping are most effective when queries filter on partition or Z-order columns." This explains why the filter was applied but had no impact on the amount of data read. Options A and B are incorrect because Delta automatically applies file pruning when possible; D is less likely, as date columns are fully supported for skipping.
NEW QUESTION # 86
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone.
A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
Answer: A
Explanation:
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.
Databricks documentation on Delta Lake, particularly the sections on cloning tables (shallow and deep cloning) and data retention with the vacuum command (https://docs.databricks.com/delta/index.html).
NEW QUESTION # 87
While investigating a data issue, you wanted to review yesterday's version of the table using below command, while querying the previous version of the table using time travel you realized that you are no longer able to view the historical data in the table and you could see it the table was updated yesterday based on the table history(DESCRIBE HISTORY table_name) command what could be the reason why you can not access this data?
SELECT * FROM table_name TIMESTAMP AS OF date_sub(current_date(), 1)
Answer: E
Explanation:
Explanation
The answer is, VACUUM table_name RETAIN 0 was ran
The VACUUM command recursively vacuums directories associated with the Delta table and re-moves data files that are no longer in the latest state of the transaction log for the table and are older than a retention threshold. The default is 7 Days.
When VACUUM table_name RETAIN 0 is ran all of the historical versions of data are lost time travel can only provide the current state.
NEW QUESTION # 88
The data engineering team maintains the following code: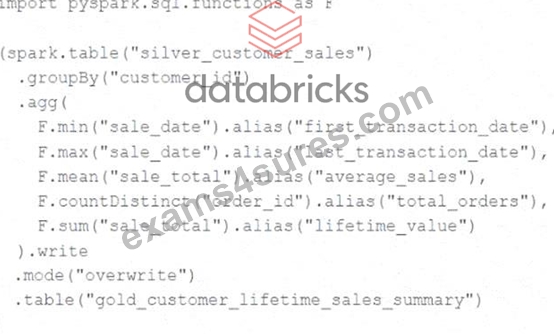
Assuming that this code produces logically correct results and the data in the source table has been de- duplicated and validated, which statement describes what will occur when this code is executed?
Answer: E
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids.
The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed. References:
* https://docs.databricks.com/spark/latest/dataframes-datasets/introduction-to-dataframes-python.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/transforming-data-with-dataframes.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/aggregating-data-with-dataframes.html
NEW QUESTION # 89
Which of the following are stored in the control pane of Databricks Architecture?
Answer: D
Explanation:
Explanation
The answer is Databricks Web Application
Azure Databricks architecture overview - Azure Databricks | Microsoft Docs Databricks operates most of its services out of a control plane and a data plane, please note serverless features like SQL Endpoint and DLT compute use shared compute in Control pane.
Control Plane: Stored in Databricks Cloud Account
* The control plane includes the backend services that Databricks manages in its own Azure account.
Notebook commands and many other workspace configurations are stored in the control plane and encrypted at rest.
Data Plane: Stored in Customer Cloud Account
* The data plane is managed by your Azure account and is where your data resides. This is also where data is processed. You can use Azure Databricks connectors so that your clusters can connect to external data sources outside of your Azure account to ingest data or for storage.
Timeline Description automatically generated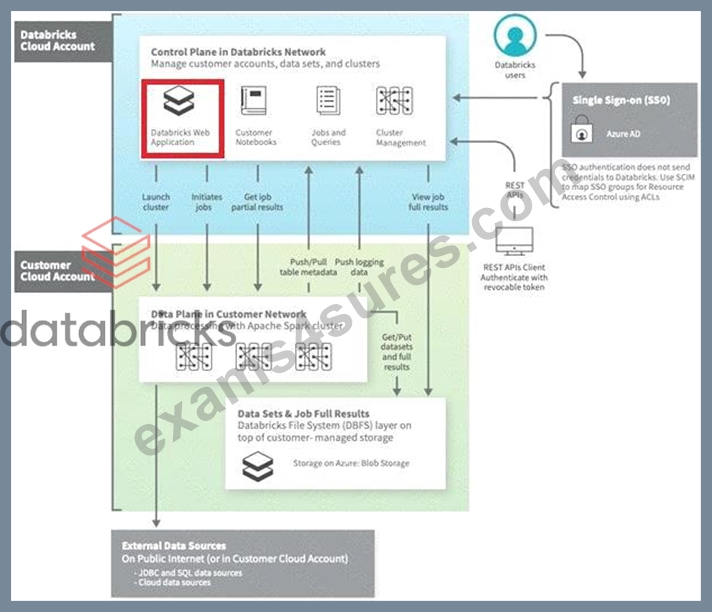
Bottom of Form
Top of Form
NEW QUESTION # 90
......
Latest Databricks-Certified-Professional-Data-Engineer Exam Preparation: https://www.exams4sures.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html