DOWNLOAD the newest iPassleader SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1CQSu3SUKEFrooOGZBWYzK8UdCy6u5gEC
PDF format is pretty much easy to use for the ones who always have their smart devices and love to prepare for Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam from them. Applicants can also make notes of printed SPS-C01 Exam Material so they can use it anywhere in order to pass Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) with a good score.
| Section | Objectives |
|---|---|
| Topic 1: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 2: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 3: Data Engineering with Snowpark | - Pipeline development
|
| Topic 4: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 5: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 6: Snowpark Fundamentals | - Snowpark architecture and concepts
|
Our Snowflake Certified SnowPro Specialty - Snowpark test torrent boost 99% passing rate and high hit rate so you can have a high probability to pass the exam. Our SPS-C01 study torrent is compiled by experts and approved by the experienced professionals and the questions and answers are chosen elaborately according to the syllabus and the latest development conditions in the theory and the practice and based on the real exam. The questions and answers of our SPS-C01 Study Tool have simplified the important information and seized the focus and are updated frequently by experts to follow the popular trend in the industry. Because of these wonderful merits the client can pass the exam successfully with high probability.
NEW QUESTION # 156
You have a Snowpark DataFrame containing customer transaction data'. Your goal is to save this DataFrame as a set of Parquet files in an existing Snowflake stage named , partitioned by the 'transaction_date' column. You want to ensure that the files are automatically compressed using the Zstandard codec and that existing files with the same name are overwritten. Which of the following Snowpark code snippet achieves this with the most optimal approach and respects best practices?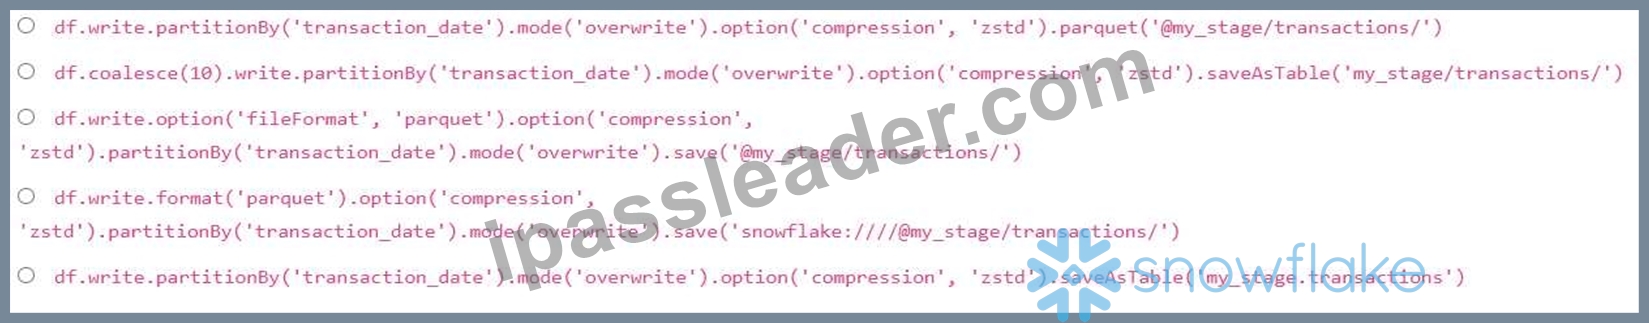
Answer: B
Explanation:
Option A correctly uses the 'parquet' method directly for writing Parquet files to a stage. It specifies partitioning by 'transaction_date', overwrites existing files using , and sets the compression codec to 'zstd' using the 'option' method. The 'saveAsTable' method, used in option B & E, is intended for creating or overwriting tables, not writing files to a stage. Option D uses a fully qualified Snowflake URL to save the DataFrame, but using saveAsTable is not for writing files into stage . The 'option('fileFormat', 'parquet')' in option C is not the most direct way to specify the format; using .parquet()' is more concise and idiomatic.
NEW QUESTION # 157
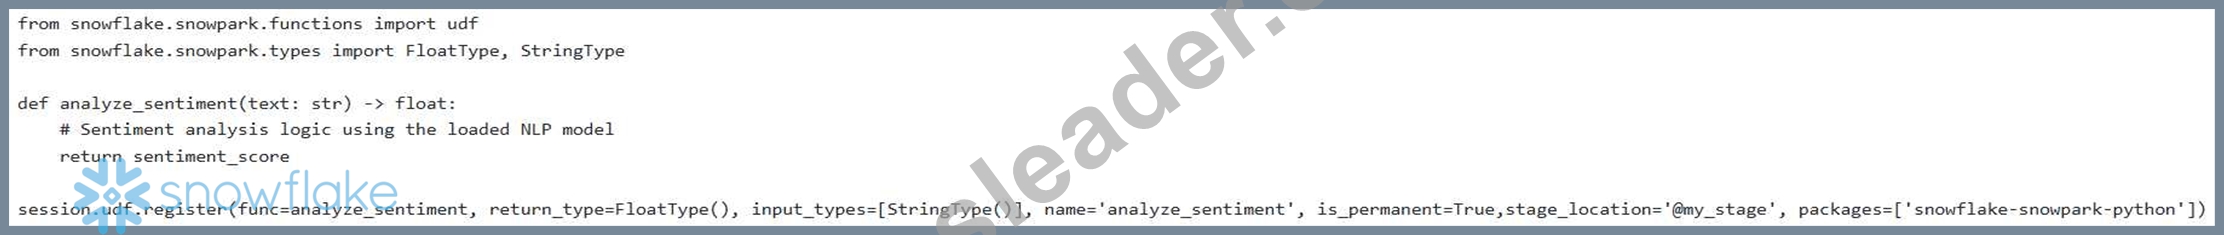
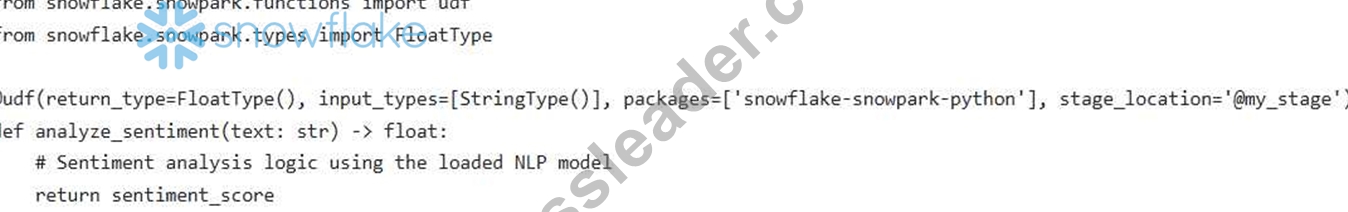
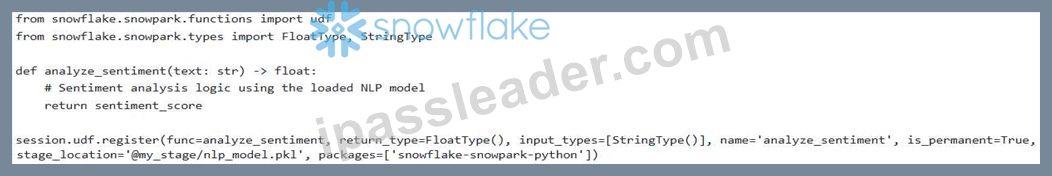
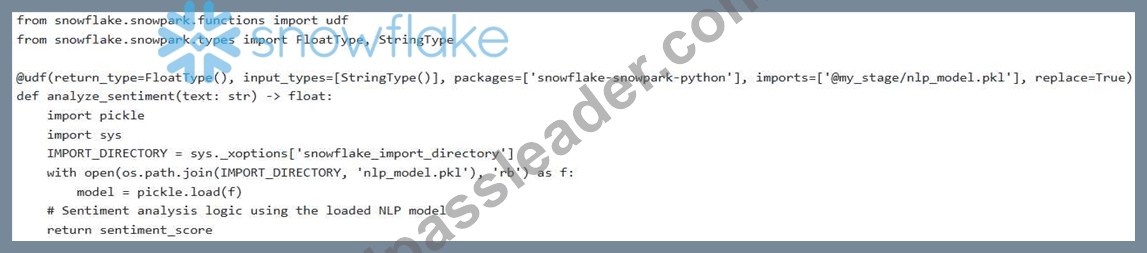
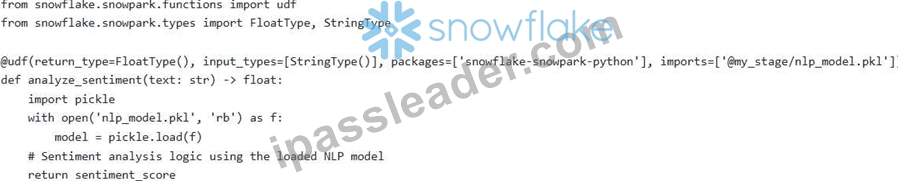
You are developing a Snowpark application to process customer sentiment from text reviews. You have a Python function, , that utilizes a pre-trained NLP model loaded from a file on a Snowflake stage named This function returns a sentiment score (float) between -1 and 1. You need to register this function as a UDF so that it can be used within Snowpark DataFrames. Which of the following code snippets correctly registers the UDF, ensuring the NLP model is available to the function during execution?
Answer: D
Explanation:
Option E correctly uses the '@udf decorator with the 'imports' parameter to specify the location of the pickled model on the stage. It also uses to correctly construct the path to the imported file within the UDF's execution environment. Replace=True prevents errors if the UDF already exists. Options A, C and D don't correctly handle importing the NLP model. Option B has a security issue of loading file without validating the Path.
NEW QUESTION # 158
You have a Python function that calculates a complex statistical measure on a given row of a DataFrame. You want to apply this function to each row of a Snowpark DataFrame in a distributed manner. Which of the following is the MOST efficient way to achieve this?
Answer: C
Explanation:
Pandas UDFs (User-Defined Functions) are designed for efficient row-wise operations on Snowpark DataFrames. The @pandas_udf decorator enables Snowpark to execute the function in a distributed manner across Snowflake's compute resources, maximizing performance for row-by-row calculations. 'apply' method doesn't exist directly on Snowpark DataFrames. Iterating through rows (Option C) is extremely inefficient. Option D involves RDD which is not exposed directly with Snowpark DataFrames. While option E is an alternative it introduces unnecessary overhead.
NEW QUESTION # 159
Consider a Snowpark DataFrame with columns 'DEPARTMENT, 'SALARY , and 'YEAR. You want to find the average salary for each department over all years and then filter the departments to only include those where the average salary is greater than 100000. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark Python?





Answer: E
Explanation:
Options A, B, C, and D are technically valid but use 'avg' or 'col' instead of the recommended 'sf.mean' and 'sf.cor for Snowpark. Option E, is most efficient as it leverages Snowpark's functions ('sf.mean' and 'sf.col') correctly and splits the operation in two steps for clarity and potential optimization. 'col' can be used, 'sf.col' is the recommended way.
NEW QUESTION # 160
A data scientist has developed a Snowpark Python stored procedure named 'model_training'. This procedure utilizes a large machine learning model and requires significant compute resources. The data scientist wants to optimize the cost and performance of running this stored procedure. Which of the following strategies would be the MOST effective for achieving this goal?
Answer: D
Explanation:
Specifying a warehouse size and using auto-suspend and auto-resume provides a balance between performance and cost. Option A might increase costs due to idle time. Option B relies on Snowflake's default warehouse, which might not be optimal. Option D could increase overall execution time due to overhead. Option E may not be feasible or efficient if the logic is heavily dependent on Python libraries. Therefore, specifically assigning an appropriate warehouse size with auto-suspend/resume is the most effective approach.
NEW QUESTION # 161
......
As we all know, the latest SPS-C01 quiz prep has been widely spread since we entered into a new computer era. The cruelty of the competition reflects that those who are ambitious to keep a foothold in the job market desire to get the SPS-C01 certification. It’s worth mentioning that our working staff considered as the world-class workforce, have been persisting in researching SPS-C01 test prep for many years. Our SPS-C01 Exam Guide engage our working staff in understanding customers’ diverse and evolving expectations and incorporate that understanding into our strategies. Our latest SPS-C01 quiz prep aim at assisting you to pass the SPS-C01 exam and making you ahead of others. Under the support of our study materials, passing the exam won’t be an unreachable mission.
SPS-C01 Online Version: https://www.ipassleader.com/Snowflake/SPS-C01-practice-exam-dumps.html
BONUS!!! Download part of iPassleader SPS-C01 dumps for free: https://drive.google.com/open?id=1CQSu3SUKEFrooOGZBWYzK8UdCy6u5gEC