P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by DumpStillValid: https://drive.google.com/open?id=1xa-8dgFi5ntaDryJ_Tk6LN5k8296oC3t
The Databricks-Generative-AI-Engineer-Associate study guide in order to allow the user to form a complete system of knowledge structure, the qualification Databricks-Generative-AI-Engineer-Associate examination of test interpretation and supporting course practice organic reasonable arrangement together, the Databricks-Generative-AI-Engineer-Associate simulating materials let the user after learning the section of the new curriculum can through the way to solve the problem to consolidate, and each section between cohesion and is closely linked, for users who use the Databricks-Generative-AI-Engineer-Associate Exam Prep to build a knowledge of logical framework to create a good condition.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Exam Databricks-Generative-AI-Engineer-Associate Reference <<
All of the traits above are available in this web-based Databricks-Generative-AI-Engineer-Associate practice test of DumpStillValid. The main distinction is that the Databricks Databricks-Generative-AI-Engineer-Associate online practice test works with not only Windows but also Mac, Linux, iOS, and Android. Above all, taking the Databricks-Generative-AI-Engineer-Associate web-based practice test while preparing for the examination does not need any software installation. Furthermore, MS Edge, Internet Explorer, Opera, Safari, Chrome, and Firefox support the web-based Databricks Databricks-Generative-AI-Engineer-Associate practice test of DumpStillValid.
NEW QUESTION # 93
A Generative AI Engineer has deployed a RAG application to production. Its Vector Search index is built from a Delta table that receives incremental updates every hour from an upstream ETL pipeline. The team wants the index to automatically reflect source-table changes without manual re-indexing and without changing the endpoint used by downstream applications.
Which approach should the engineer use?
Answer: C
Explanation:
D identifies the index type designed to synchronize with a source Delta table. Delta Sync supports incremental maintenance, avoiding a custom process that repeatedly rebuilds the complete index or manually pushes every changed vector. A Direct Vector Access index transfers update responsibility to the application.
However, this question has a configuration ambiguity: Delta Sync also has a synchronization mode.
Continuous mode processes arriving changes automatically, while triggered mode requires an explicit synchronization request, which can be scheduled after ETL. If the existing index is already a triggered Delta Sync index, B is the relevant configuration change. D is therefore the intended architectural answer, with continuous synchronization or an automated trigger needed to deliver the requested operational behavior.
Databricks API documentation
NEW QUESTION # 94
A Generative AI Engineer is creating an LLM-powered application that will need access to up-to-date news articles and stock prices.
The design requires the use of stock prices which are stored in Delta tables and finding the latest relevant news articles by searching the internet.
How should the Generative AI Engineer architect their LLM system?
Answer: D
Explanation:
To build an LLM-powered system that accesses up-to-date news articles and stock prices, the best approach is to create an agent that has access to specific tools (option D).
Agent with SQL and Web Search Capabilities:
By using an agent-based architecture, the LLM can interact with external tools. The agent can query Delta tables (for up-to-date stock prices) via SQL and perform web searches to retrieve the latest news articles. This modular approach ensures the system can access both structured (stock prices) and unstructured (news) data sources dynamically.
Why This Approach Works:
SQL Queries for Stock Prices: Delta tables store stock prices, which the agent can query directly for the latest data.
Web Search for News: For news articles, the agent can generate search queries and retrieve the most relevant and recent articles, then pass them to the LLM for processing.
Why Other Options Are Less Suitable:
A (Summarizing News for Stock Prices): This convoluted approach would not ensure accuracy when retrieving stock prices, which are already structured and stored in Delta tables.
B (Stock Price Volatility Queries): While this could retrieve relevant information, it doesn't address how to obtain the most up-to-date news articles.
C (Vector Store): Storing news articles and stock prices in a vector store might not capture the real-time nature of stock data and news updates, as it relies on pre-existing data rather than dynamic querying.
Thus, using an agent with access to both SQL for querying stock prices and web search for retrieving news articles is the best approach for ensuring up-to-date and accurate responses.
NEW QUESTION # 95
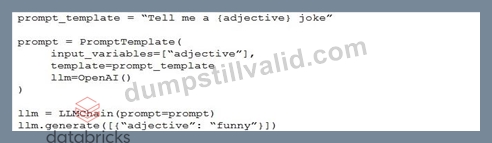
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.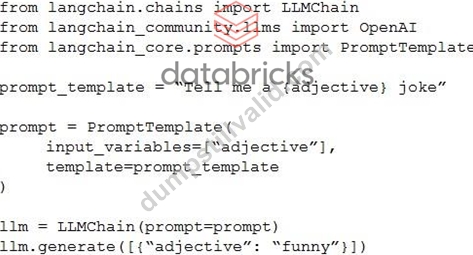
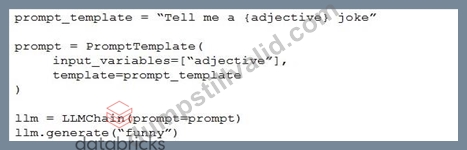
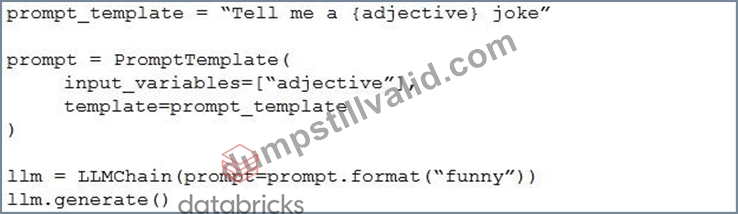
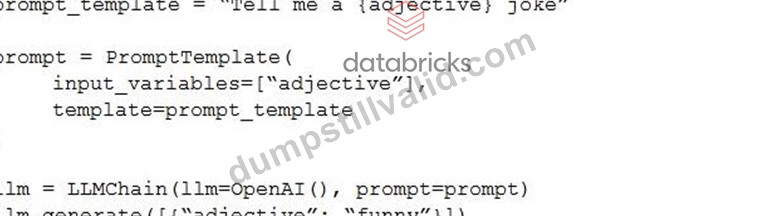
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: D
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
Correct Use of Classes and Methods:
The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 96
A Generative AI Engineer is building a Generative AI system that suggests the best matched employee team member to newly scoped projects. The team member is selected from a very large team. Thematch should be based upon project date availability and how well their employee profile matches the project scope. Both the employee profile and project scope are unstructured text.
How should the Generative Al Engineer architect their system?
Answer: C
Explanation:
* Problem Context: The problem involves matching team members to new projects based on two main factors:
* Availability: Ensure the team members are available during the project dates.
* Profile-Project Match: Use the employee profiles (unstructured text) to find the best match for a project's scope (also unstructured text).
The two main inputs are theemployee profilesandproject scopes, both of which are unstructured. This means traditional rule-based systems (e.g., simple keyword matching) would be inefficient, especially when working with large datasets.
* Explanation of Options: Let's break down the provided options to understand why D is the most optimal answer.
* Option Asuggests embedding project scopes into a vector store and then performing retrieval using team member profiles. While embedding project scopes into a vector store is a valid technique, it skips an important detail: the focus should primarily be on embedding employee profiles because we're matching the profiles to a new project, not the other way around.
* Option Binvolves using a large language model (LLM) to extract keywords from the project scope and perform keyword matching on employee profiles. While LLMs can help with keyword extraction, this approach is too simplistic and doesn't leverage advanced retrieval techniques like vector embeddings, which can handle the nuanced and rich semantics of unstructured data. This approach may miss out on subtle but important similarities.
* Option Csuggests calculating a similarity score between each team member's profile and project scope. While this is a good idea, it doesn't specify how to handle the unstructured nature of data efficiently. Iterating through each member's profile individually could be computationally expensive in large teams. It also lacks the mention of using a vector store or an efficient retrieval mechanism.
* Option Dis the correct approach. Here's why:
* Embedding team profiles into a vector store: Using a vector store allows for efficient similarity searches on unstructured data. Embedding the team member profiles into vectors captures their semantics in a way that is far more flexible than keyword-based matching.
* Using project scope for retrieval: Instead of matching keywords, this approach suggests using vector embeddings and similarity search algorithms (e.g., cosine similarity) to find the team members whose profiles most closely align with the project scope.
* Filtering based on availability: Once the best-matched candidates are retrieved based on profile similarity, filtering them by availability ensures that the system provides a practically useful result.
This method efficiently handles large-scale datasets by leveragingvector embeddingsandsimilarity search techniques, both of which are fundamental tools inGenerative AI engineeringfor handling unstructured text.
* Technical References:
* Vector embeddings: In this approach, the unstructured text (employee profiles and project scopes) is converted into high-dimensional vectors using pretrained models (e.g., BERT, Sentence-BERT, or custom embeddings). These embeddings capture the semantic meaning of the text, making it easier to perform similarity-based retrieval.
* Vector stores: Solutions likeFAISSorMilvusallow storing and retrieving large numbers of vector embeddings quickly. This is critical when working with large teams where querying through individual profiles sequentially would be inefficient.
* LLM Integration: Large language models can assist in generating embeddings for both employee profiles and project scopes. They can also assist in fine-tuning similarity measures, ensuring that the retrieval system captures the nuances of the text data.
* Filtering: After retrieving the most similar profiles based on the project scope, filtering based on availability ensures that only team members who are free for the project are considered.
This system is scalable, efficient, and makes use of the latest techniques inGenerative AI, such as vector embeddings and semantic search.
NEW QUESTION # 97
A Generative AI Engineer is building an LLM to generate article summaries in the form of a type of poem, such as a haiku, given the article content. However, the initial output from the LLM does not match the desired tone or style.
Which approach will NOT improve the LLM's response to achieve the desired response?
Answer: A
Explanation:
The task at hand is to improve the LLM's ability to generate poem-like article summaries with the desired tone and style. Using a neutralizer to normalize the tone and style of the underlying documents (option B) will not help improve the LLM's ability to generate the desired poetic style. Here's why:
Neutralizing Underlying Documents:
A neutralizer aims to reduce or standardize the tone of input data. However, this contradicts the goal, which is to generate text with a specific tone and style (like haikus). Neutralizing the source documents will strip away the richness of the content, making it harder for the LLM to generate creative, stylistic outputs like poems.
Why Other Options Improve Results:
A (Explicit Instructions in the Prompt): Directly instructing the LLM to generate text in a specific tone and style helps align the output with the desired format (e.g., haikus). This is a common and effective technique in prompt engineering.
C (Few-shot Examples): Providing examples of the desired output format helps the LLM understand the expected tone and structure, making it easier to generate similar outputs.
D (Fine-tuning the LLM): Fine-tuning the model on a dataset that contains examples of the desired tone and style is a powerful way to improve the model's ability to generate outputs that match the target format.
Therefore, using a neutralizer (option B) is not an effective method for achieving the goal of generating stylized poetic summaries.
NEW QUESTION # 98
......
DumpStillValid offers you a free demo version of the Databricks Databricks-Generative-AI-Engineer-Associate dumps. This way candidates can easily check the validity and reliability of the Databricks-Generative-AI-Engineer-Associate exam products without having to spend time. This relieves any sort of anxiety in the candidate's mind before the purchase of Databricks Certified Generative AI Engineer Associate certification exam preparation material. This Databricks-Generative-AI-Engineer-Associate Exam study material is offered to you at a very low price. We also offer up to 1 year of free updates on Databricks Databricks-Generative-AI-Engineer-Associate dumps after the date of purchase. Going through our Databricks Certified Generative AI Engineer Associate exam prep material there remains no chance of failure in the Databricks Databricks-Generative-AI-Engineer-Associate exam.
New Databricks-Generative-AI-Engineer-Associate Test Cram: https://www.dumpstillvalid.com/Databricks-Generative-AI-Engineer-Associate-prep4sure-review.html
BTW, DOWNLOAD part of DumpStillValid Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1xa-8dgFi5ntaDryJ_Tk6LN5k8296oC3t