P.S. Free & New DP-600 dumps are available on Google Drive shared by CertkingdomPDF: https://drive.google.com/open?id=10mIjoj3Rr4iqYoqu73YsIEe8pBfUrjaE
Our DP-600 study braindumps are comprehensive that include all knowledge you need to learn necessary knowledge, as well as cope with the test ahead of you. With convenient access to our website, you can have an experimental look of free demos before get your favorite DP-600 prep guide downloaded. You can both learn useful knowledge and pass the exam with efficiency with our DP-600 Real Questions easily. We are on the way of meeting our mission and purposes of helping exam candidates to consider the exam as a campaign of success and pass the exam successfully.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
As is known to all, practice makes perfect. This proverb also can be replied into the exam. We have the DP-600 Study Materials with good reputation in the market. The DP-600 exam dumps not only contains the quality, but also have the quantity, therefore it will meet your needs. Just think that you just need to practice it for some time, a certificate will be obtained by your own efforts, it will be a quite delightful thing. So act now, you will be very happy to see it come true.
NEW QUESTION # 160
You have a Fabric warehouse named Warehouse1 that contains a table named dbo.Product. dbo.Product contains the following columns.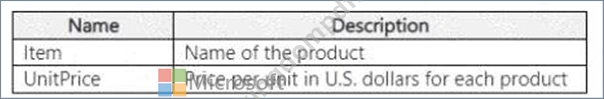
You need to use a T-SQL query to add a column named PriceRange to dbo.Product. The column must categorize each product based on UnitPrice. The solution must meet the following requirements:
* If UnitPrice is 0, PriceRange is " Not for resale " .
* If UnitPrice is less than 50, PriceRange is " Under $50 " .
* If UnitPrice is between 50 and 250, PriceRange is " Under $250 " .
* In all other instances, PriceRange is " $250+ " .
How should you complete the query? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.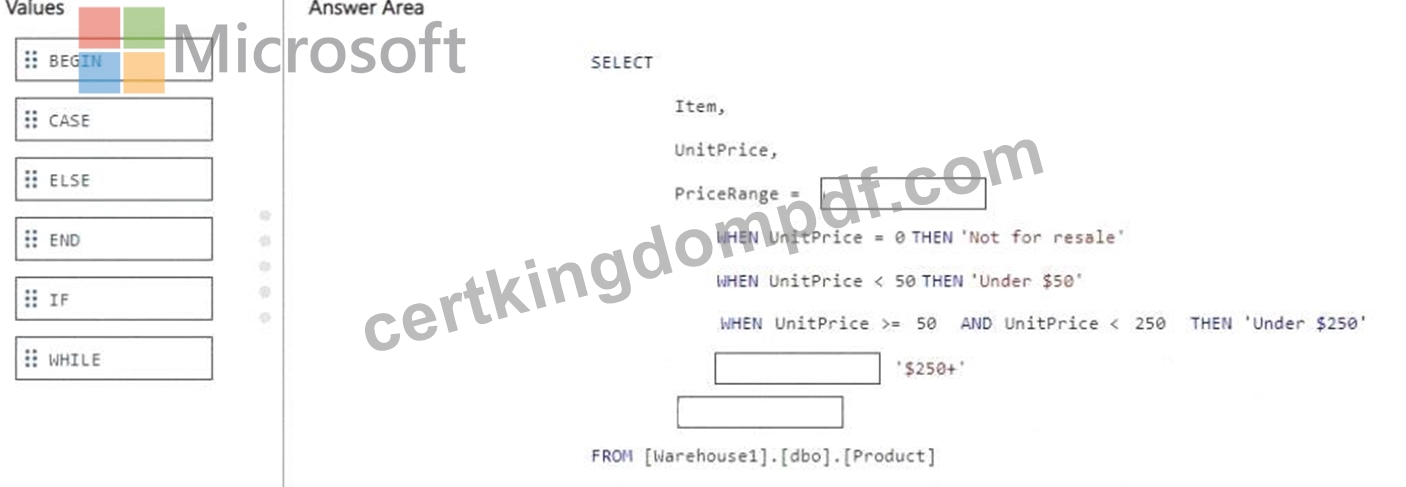
Answer:
Explanation: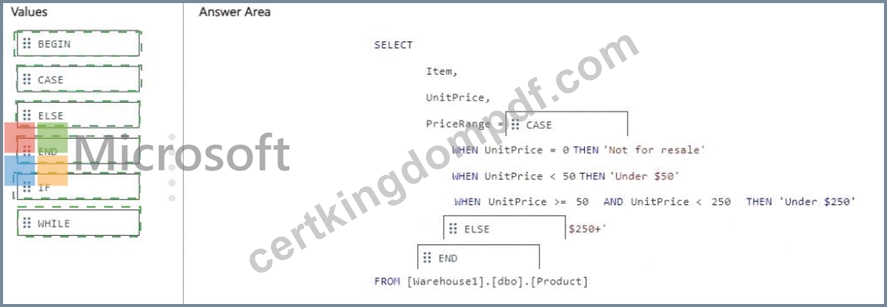
Explanation: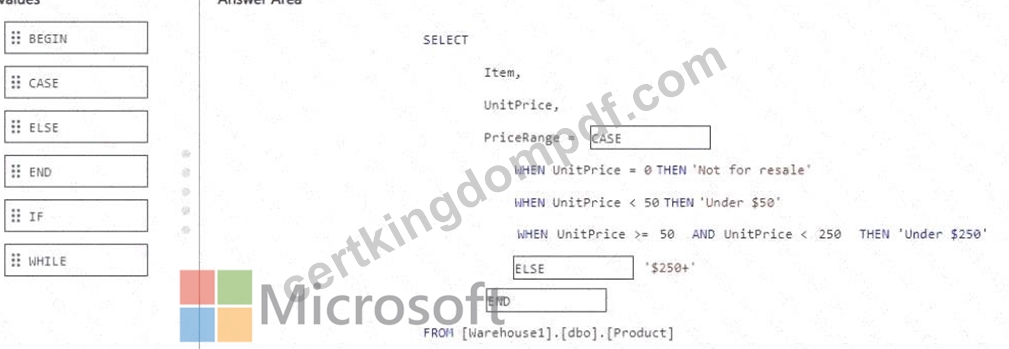
Comprehensive Detailed Explanation
We need to create a computed column PriceRange based on the UnitPrice column in the dbo.Product table.
Step 1: Requirements
If UnitPrice = 0 # " Not for resale "
If UnitPrice < 50 # " Under $50 "
If UnitPrice > = 50 AND UnitPrice < 250 # " Under $250 "
Otherwise # " $250+ "
This matches a CASE expression in T-SQL.
Step 2: CASE Expression Structure
The syntax is:
CASE
WHEN condition THEN result
WHEN condition THEN result
ELSE result
END
Step 3: Apply to Problem
SELECT
Item,
UnitPrice,
PriceRange = CASE
WHEN UnitPrice = 0 THEN ' Not for resale '
WHEN UnitPrice < 50 THEN ' Under $50 '
WHEN UnitPrice > = 50 AND UnitPrice < 250 THEN ' Under $250 '
ELSE ' $250+ '
END
FROM [Warehouse1].[dbo] .[Product];
Step 4: Why This is Correct
CASE starts the conditional evaluation.
ELSE handles the default branch ( $250+ ).
END closes the expression.
Meets all requirements exactly.
References
CASE expression in T-SQL
Computed columns in T-SQL
NEW QUESTION # 161
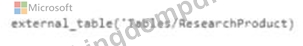
Which syntax should you use in a notebook to access the Research division data for Productlinel?



Answer: B
Explanation:
Comprehensive Detailed Explanation
The question asks: Which syntax should you use in a Fabric notebook to access the Research division data for Productline1?
Key Background from the Case
In Productline1ws, a lakehouse named Lakehouse1 is created.
In Lakehouse1, a shortcut is created to storage1, named ResearchProduct.
Storage1 contains the Research division data for Productline1 in Delta format.
Requirement: All data in lakehouses must be presented as managed tables in Lakehouse explorer.
Analyzing the Syntax Options
Option A:
spark.sql( " SELECT * FROM Lakehouse1.ResearchProduct " )
This syntax directly queries the ResearchProduct shortcut within Lakehouse1 using Spark SQL.
Since the shortcut points to Delta data, Spark can directly query it.
This is the correct way to retrieve Productline1 data from Lakehouse1.
Option B:
spark.sql( " SELECT * FROM Lakehouse1.productline1.ResearchProduct " )
This introduces an extra schema-like path (productline1) that is not part of the shortcut name.
Incorrect, because the shortcut was created as ResearchProduct inside Lakehouse1, not under another schema.
Option C:
external_table( ' Tables/ResearchProduct ' )
external_table is not the correct way to access a Lakehouse shortcut.
Shortcuts in Lakehouses appear as tables and can be queried using Spark SQL directly.
Option D:
spark.sql( " SELECT * FROM Lakehouse1.productline1.ResearchProduct " )
Same issue as Option B, includes a schema path that does not exist.
Correct Choice
Since the shortcut to ResearchProduct was created inside Lakehouse1, and Spark SQL can query it directly, the correct syntax is:
spark.sql( " SELECT * FROM Lakehouse1.ResearchProduct " )
That matches Option A.
References
Microsoft Fabric Lakehouse - Shortcuts
Query data in a lakehouse using Spark SQL
Delta format support in Microsoft Fabric
NEW QUESTION # 162
You have a Fabric tenant.
You are creating a Fabric Data Factory pipeline.
You have a stored procedure that returns the number of active customers and their average sales for the current month.
You need to add an activity that will execute the stored procedure in a warehouse. The returned values must be available to the downstream activities of the pipeline.
Which type of activity should you add?
Answer: B
NEW QUESTION # 163
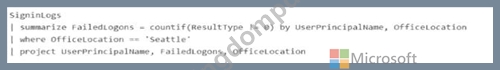
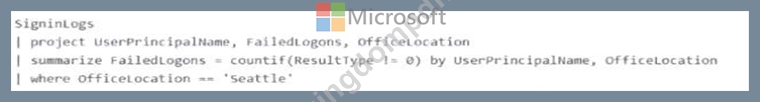
You have the following KQL query named Query1.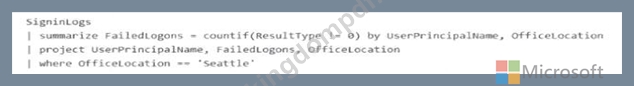
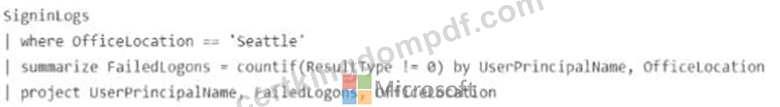
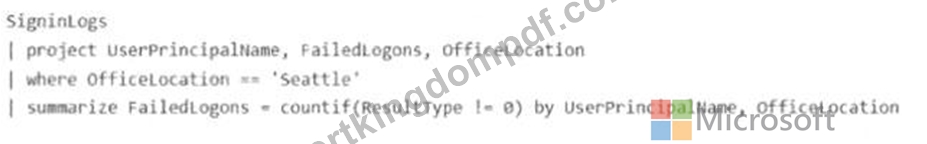
You need to improve the performance of Query1.
The solution must minimize resource use How should you restructure Query1?
Answer: A
NEW QUESTION # 164
You have a Microsoft Power Bl project that contains a file named definition.pbir. definition.pbir contains the following JSON.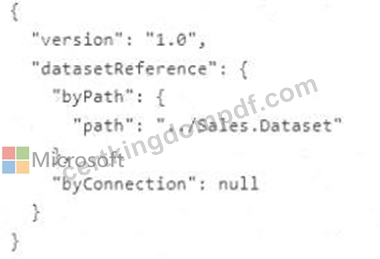
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.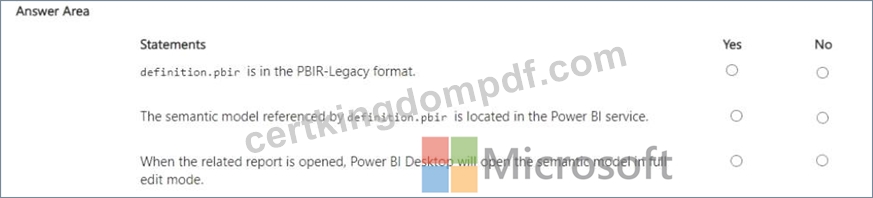
Answer:
Explanation:
Explanation: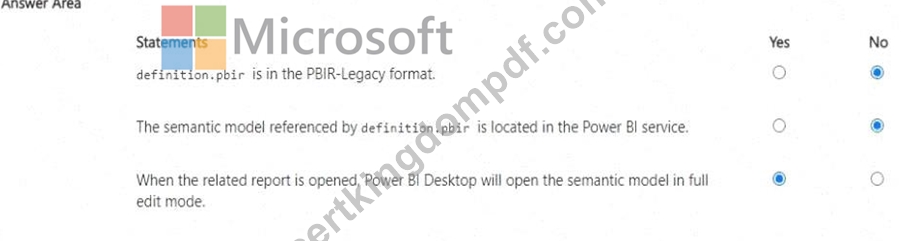
Topic 2, Litware. Inc. Case Study
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.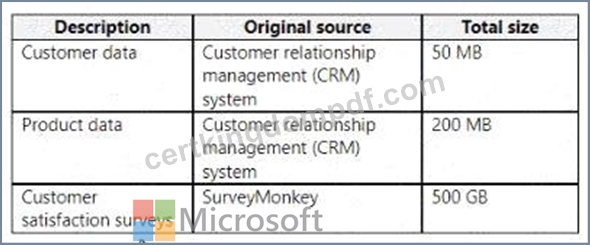
The Product data contains a single table and the following columns.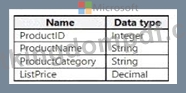
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
NEW QUESTION # 165
......
n modern society, whether to obtain DP-600 certification has become a standard to test the level of personal knowledge. Many well-known companies require the DP-600 certification at the time of recruitment. Whether you're a student or a white-collar worker, you're probably trying to get the certification in order to get more job opportunities or wages. If you are one of them, our DP-600 Exam Guide will effectively give you a leg up.
DP-600 Valid Exam Answers: https://www.certkingdompdf.com/DP-600-latest-certkingdom-dumps.html
BTW, DOWNLOAD part of CertkingdomPDF DP-600 dumps from Cloud Storage: https://drive.google.com/open?id=10mIjoj3Rr4iqYoqu73YsIEe8pBfUrjaE