You only need 20-30 hours to learn our Databricks-Certified-Professional-Data-Engineer test torrents and prepare for the exam. Anybody, whether he or she is an in-service staff or a student, must spend much time on their jobs, family lives and the learning. After buying our Databricks-Certified-Professional-Data-Engineer exam questions you only need to spare several hours to learn our Databricks-Certified-Professional-Data-Engineer test torrent s and commit yourselves mainly to the jobs, the family lives and the learning. Our answers and questions of Databricks-Certified-Professional-Data-Engineer Exam Questions are chosen elaborately and seize the focus of the exam so you can save much time to learn and prepare the exam. Because the passing rate is high you can reassure yourselves to buy our Databricks-Certified-Professional-Data-Engineer guide torrent.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Monitoring and Alerting | 10% | - Performance and health monitoring - Pipeline observability and logging - Setting up alerts and notifications |
| Topic 2: Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Standardization and normalization - Handling missing or inconsistent data |
| Topic 3: Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Topic 4: Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Schema inference and evolution - Auto Loader and streaming ingestion |
| Topic 5: Data Governance | 7% | - Data lineage and metadata tracking - Unity Catalog management - Policy enforcement |
| Topic 6: Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices |
| Topic 7: Data Modelling | 6% | - Medallion Architecture implementation - Schema design and management - Delta Lake table design |
| Topic 8: Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Data transformation and aggregation - Integration with Databricks APIs and tools |
| Topic 9: Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Data encryption and masking - Access control and permissions |
| Topic 10: Cost & Performance Optimisation | 13% | - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling |
>> Exam Databricks-Certified-Professional-Data-Engineer Success <<
When preparing to take the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam dumps, knowing where to start can be a little frustrating, but with Databricks Databricks-Certified-Professional-Data-Engineer practice questions, you will feel fully prepared. Using our Databricks Databricks-Certified-Professional-Data-Engineer practice test ExamTorrent, you can prepare for the increased difficulty on Databricks-Certified-Professional-Data-Engineer Exam day. Plus, we have various question types and difficulty levels so that you can tailor your Databricks Databricks-Certified-Professional-Data-Engineer exam dumps preparation to your requirements.
NEW QUESTION # 51
Which of the following is true, when building a Databricks SQL dashboard?
Answer: A
Explanation:
Explanation
the answer is, More than one visualization can be developed using a single query result.
In the query editor pane + Add visualization tab can be used for many visualizations for a single query result.
Graphical user interface, text, application Description automatically generated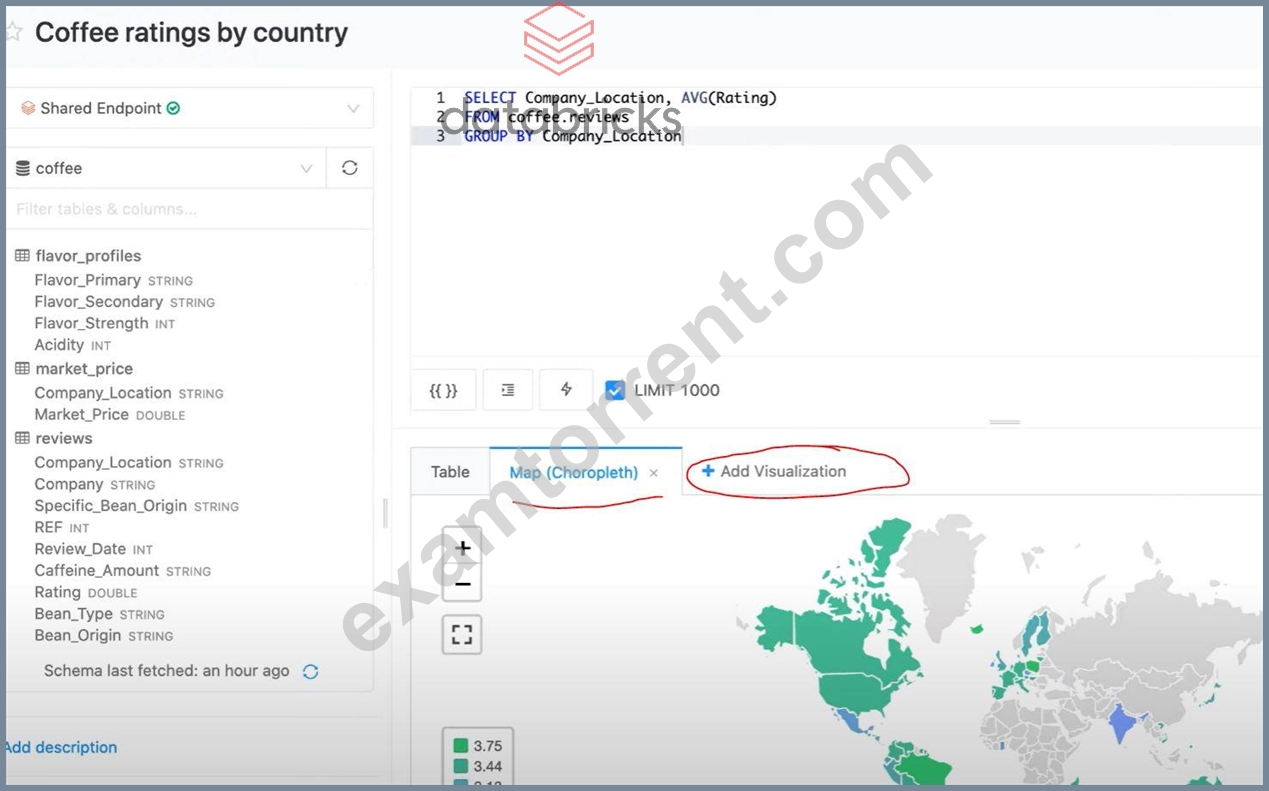
NEW QUESTION # 52
A nightly job ingests data into a Delta Lake table using the following code: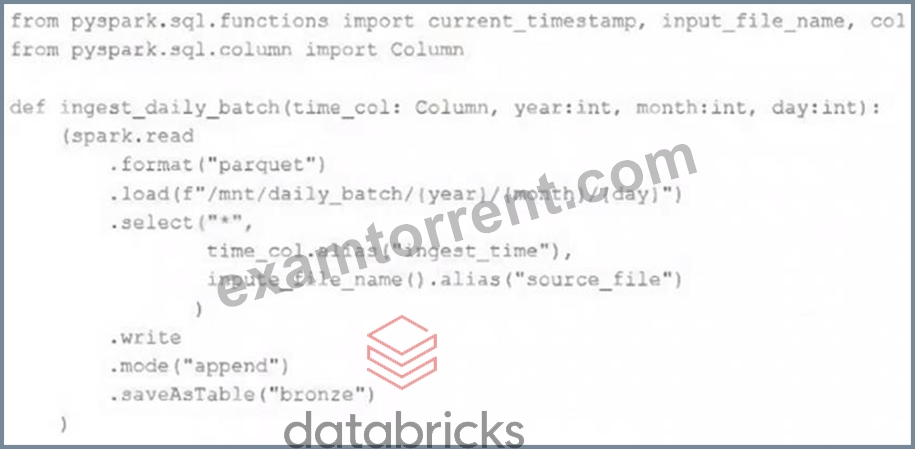
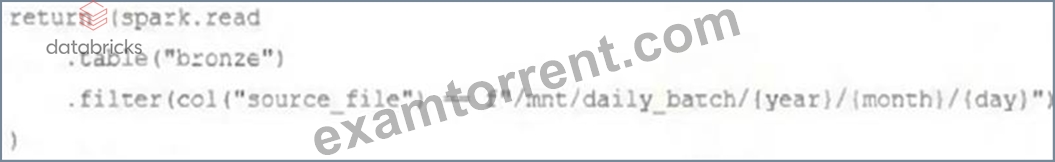
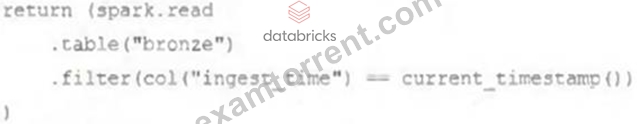
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
Answer: A
Explanation:
Explanation
This is the correct answer because it completes the function definition that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline. The object returned by this function is a DataFrame that contains all change events from a Delta Lake table that has enabled change data feed. The readChangeFeed option is set to true to indicate that the DataFrame should read changes from the table, and the table argument specifies the name of the table to read changes from. The DataFrame will have a schema that includes four columns: operation, partition, value, and timestamp. The operation column indicates the type of change event, such as insert, update, or delete. The partition column indicates the partition where the change event occurred. The value column contains the actual data of the change event as a struct type. The timestamp column indicates the time when the change event was committed. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Read changes in batch queries" section.
NEW QUESTION # 53
Which statement describes Delta Lake Auto Compaction?
Answer: D
Explanation:
Explanation
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB.
Auto Compaction only compacts files that have not been compacted previously. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Auto Compaction for Delta Lake on Databricks" section.
"Auto compaction occurs after a write to a table has succeeded and runs synchronously on the cluster that has performed the write. Auto compaction only compacts files that haven't been compacted previously."
https://learn.microsoft.com/en-us/azure/databricks/delta/tune-file-size
NEW QUESTION # 54
The research team has put together a funnel analysis query to monitor the customer traffic on the e-commerce platform, the query takes about 30 mins to run on a small SQL endpoint cluster with max scaling set to 1 cluster. What steps can be taken to improve the performance of the query?
Answer: D
Explanation:
Explanation
The answer is, They can increase the cluster size anywhere from 2X-Small to 4XL(Scale Up) to review the performance and select the size that meets your SLA. If you are trying to improve the performance of a single query at a time having additional memory, additional worker nodes mean that more tasks can run in a cluster which will improve the performance of that query.
The question is looking to test your ability to know how to scale a SQL Endpoint(SQL Warehouse) and you have to look for cue words or need to understand if the queries are running sequentially or concurrently. if the queries are running sequentially then scale up(Size of the cluster from 2X-Small to 4X-Large) if the queries are running concurrently or with more users then scale out(add more clusters).
SQL Endpoint(SQL Warehouse) Overview: (Please read all of the below points and the below diagram to understand )
1.A SQL Warehouse should have at least one cluster
2.A cluster comprises one driver node and one or many worker nodes
3.No of worker nodes in a cluster is determined by the size of the cluster (2X -Small ->1 worker, X-Small ->2 workers.... up to 4X-Large -> 128 workers) this is called Scale Up
4.A single cluster irrespective of cluster size(2X-Smal.. to ...4XLarge) can only run 10 queries at any given time if a user submits 20 queries all at once to a warehouse with 3X-Large cluster size and cluster scaling (min
1, max1) while 10 queries will start running the remaining 10 queries wait in a queue for these 10 to finish.
5.Increasing the Warehouse cluster size can improve the performance of a query, example if a query runs for 1 minute in a 2X-Small warehouse size, it may run in 30 Seconds if we change the warehouse size to X-Small.
this is due to 2X-Small has 1 worker node and X-Small has 2 worker nodes so the query has more tasks and runs faster (note: this is an ideal case example, the scalability of a query performance depends on many factors, it can not always be linear)
6.A warehouse can have more than one cluster this is called Scale Out. If a warehouse is configured with X-Small cluster size with cluster scaling(Min1, Max 2) Databricks spins up an additional cluster if it detects queries are waiting in the queue, If a warehouse is configured to run 2 clusters(Min1, Max 2), and let's say a user submits 20 queries, 10 queriers will start running and holds the remaining in the queue and databricks will automatically start the second cluster and starts redirecting the 10 queries waiting in the queue to the second cluster.
7.A single query will not span more than one cluster, once a query is submitted to a cluster it will remain in that cluster until the query execution finishes irrespective of how many clusters are available to scale.
Please review the below diagram to understand the above concepts: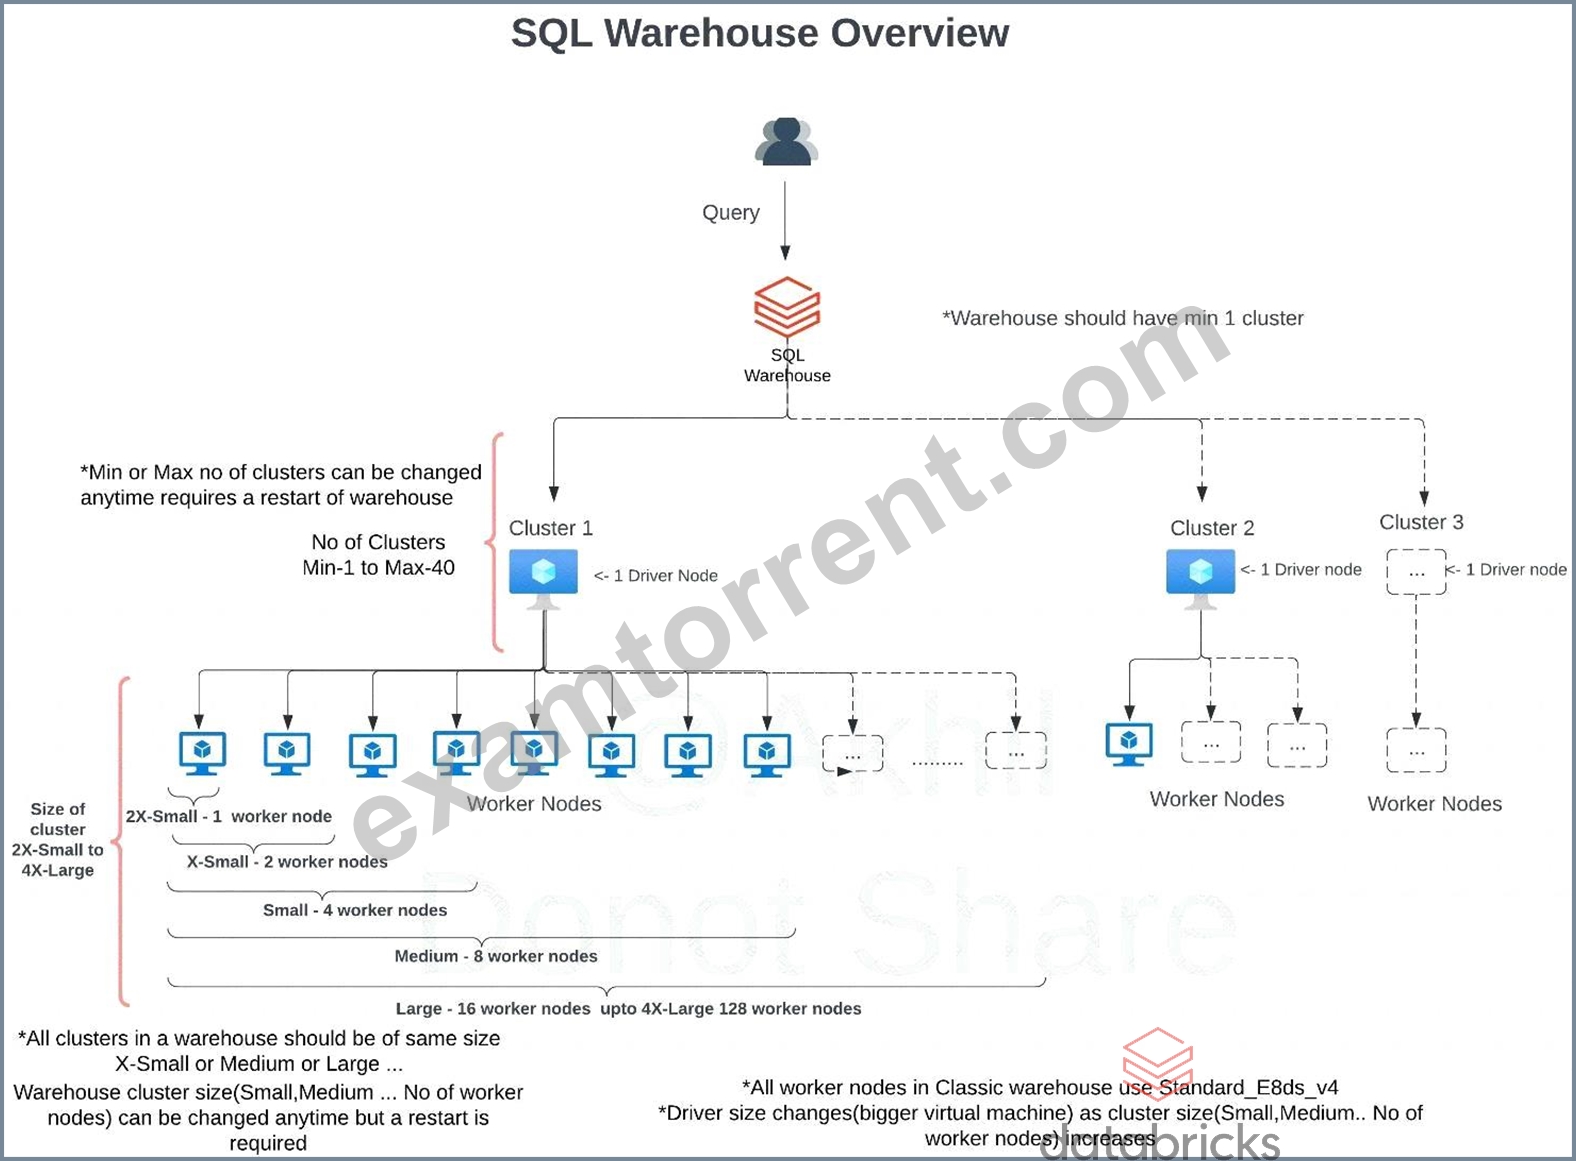
Scale-up-> Increase the size of the SQL endpoint, change cluster size from 2X-Small to up to 4X-Large If you are trying to improve the performance of a single query having additional memory, additional worker nodes and cores will result in more tasks running in the cluster will ultimately improve the performance.
During the warehouse creation or after, you have the ability to change the warehouse size (2X-Small....to
...4XLarge) to improve query performance and the maximize scaling range to add more clusters on a SQL Endpoint(SQL Warehouse) scale-out if you are changing an existing warehouse you may have to restart the warehouse to make the changes effective.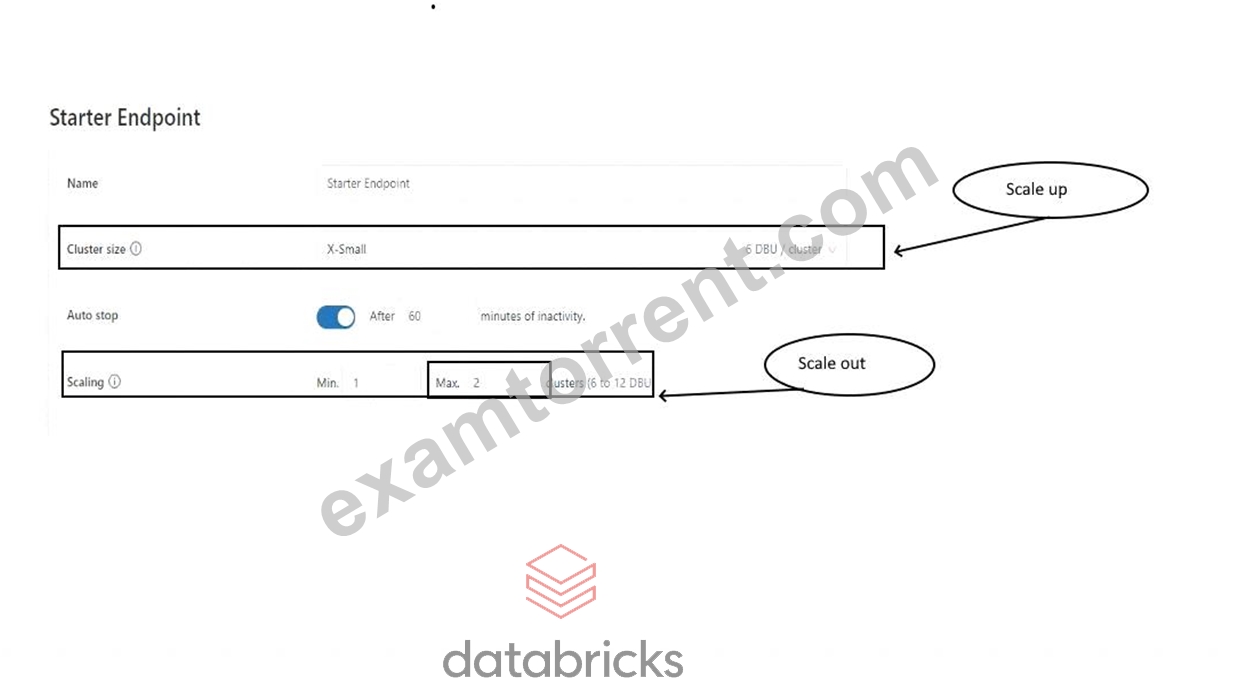
NEW QUESTION # 55
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
(spark.readStream
.format("parquet")
.load("/mnt/raw_orders/")
.withWatermark("time", "2 hours")
.dropDuplicates(["customer_id", "order_id"])
.writeStream
.trigger(once=True)
.table("orders")
)
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system. If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "dropDuplicates with watermark performs stateful deduplication on the keys within the watermark delay." Exact extract: "Records older than the event-time watermark are considered late and may be dropped." Exact extract: "trigger(once) processes all available data once and then stops."
NEW QUESTION # 56
......
By purchasing our ExamTorrent Databricks Databricks-Certified-Professional-Data-Engineer dumps, you will finish the exam preparation. And then, you will get high quality tests questions and test answers. ExamTorrent Databricks Databricks-Certified-Professional-Data-Engineer test is your friend which is worth trusting forever. Our ExamTorrent Databricks Databricks-Certified-Professional-Data-Engineer Dumps Torrent provide certification training materials to the IT people in the world. It includes test questions and test answers. Quality product rate is 100% and customer rate also 100%.
Databricks-Certified-Professional-Data-Engineer Latest Braindumps Book: https://www.examtorrent.com/Databricks-Certified-Professional-Data-Engineer-valid-vce-dumps.html