You will get a lot of personal and professional benefits after passing the Microsoft AI-200 test. The Microsoft AI-200 exam is a valuable credential that will assist you to advance your career. The Microsoft AI-200 is a way to increase your knowledge and skills. You can also trust on BraindumpStudy and start Developing AI Cloud Solutions on Azure AI-200 test preparation with Microsoft AI-200 practice test material.
| Section | Objectives |
|---|---|
| Topic 1: Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
| Topic 2: Implement Azure AI solutions | - Implement natural language processing solutions - Implement computer vision solutions - Implement knowledge mining with Azure AI Search - Implement generative AI solutions using Azure OpenAI |
| Topic 3: Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Plan security and compliance requirements - Monitor and optimize AI solutions |
>> AI-200 Latest Practice Questions <<
When you first contact our software, different people will have different problems. Maybe you are not comfortable with our AI-200 exam question and want to know more about our products and operations. As long as you have questions, you can send e-mail to us, we have online staff responsible for ensuring 24-hour service to help you solve all the problems about our AI-200 test prep. After you purchase our AI-200 quiz guide, we will still provide you with considerate services. Maybe you will ask whether we will charge additional service fees. We assure you that we are focused on providing you with guidance about our AI-200 Exam Question, but all services are free. If you encounter installation problems, we will have professionals to provide you with remote assistance. Of course, we will humbly accept your opinions on our AI-200 quiz guide. If you have good suggestions to make better use of our AI-200 test prep, we will accept your proposal and make improvements. Each of your progress is our driving force. We sincerely serve for you any time.
NEW QUESTION # 64
You store embeddings in a property named embedding in an Azure Cosmos DB for NoSQL container.
You must construct a vector similarity query that orders documents by similarity to the input embedding and returns only the top five results.
You need to construct the similarity query.
What should you do?
Answer: D
Explanation:
The query should limit the number of returned results by using TOP 5 together with ORDER BY VectorDistance(...) . Azure Cosmos DB for NoSQL provides the VectorDistance() system function for comparing a stored vector with an input query vector. Microsoft documents that a vector similarity query should order the results by VectorDistance so that the nearest matches are returned first.
A representative query is:
SELECT TOP 5
c.id,
VectorDistance(c.embedding, @embedding) AS SimilarityScore
FROM c
ORDER BY VectorDistance(c.embedding, @embedding)
Microsoft specifically recommends using a TOP N clause for vector search queries because returning more results than necessary increases RU consumption and latency. In this scenario, TOP 5 directly satisfies the requirement to return only the five most similar documents.
GROUP BY is used for aggregation and does not rank vectors by similarity. DISTINCT removes duplicate projected values but does not restrict results to the five nearest vectors. Offset pagination is unnecessary and can introduce additional query cost when only the highest-ranked five results are required.
Therefore, the correct action is to limit the number of results .
Study Guide references: Azure Cosmos DB for NoSQL # VectorDistance() ; vector search; ORDER BY ; TOP N ; RU and latency optimization.
NEW QUESTION # 65
Hotspot Question
You are developing a Retrieval-Augmented Generation (RAG) solution for a company.
AI responses and embedding vectors are cached in Redis.
The solution must meet the following requirements:
- AI responses must expire exactly 24 hours after they are cached.
- Cached embeddings must always reflect the current source data.
You need to configure Redis to meet the requirements.
NOTE: Each correct selection is worth one point.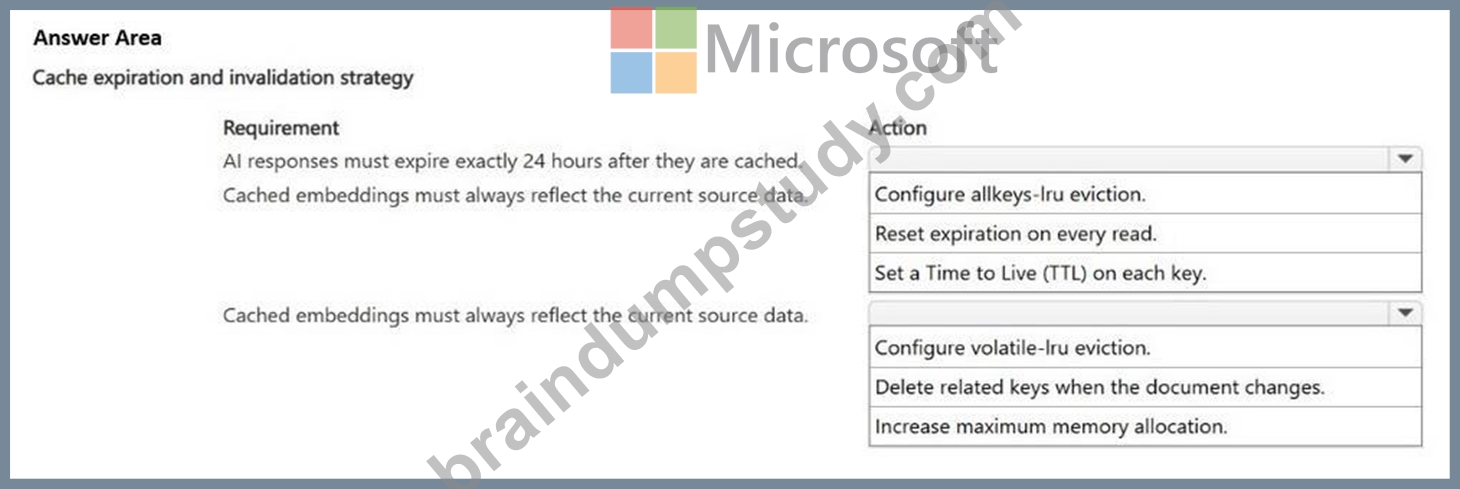
Answer:
Explanation: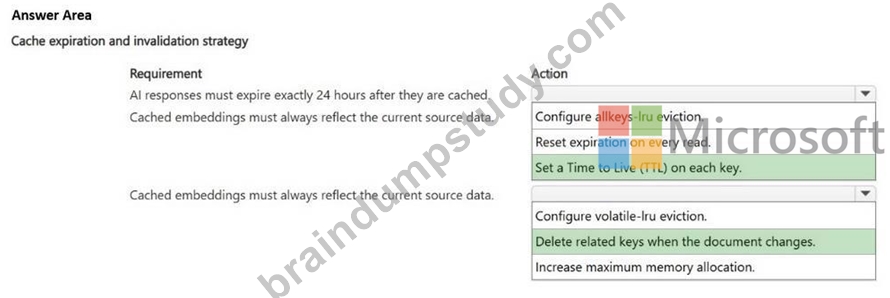
Explanation:
Box 1: Set a Time for Live (TTL) on each key.
To configure Redis to expire your AI responses exactly 24 hours after caching, you must apply a Time-To-Live (TTL) of 86,400 seconds to the specific keys holding those responses.
Box 2: Delete related keys when the document changes
You must invalidate or update those cached keys when source data changes to prevent your RAG system from retrieving stale information.
Incorrect:
Configuring allkeys-lru (Least Recently Used) is not recommended to ensure your cached embeddings or AI responses reflect current source data.allkeys-lru is an eviction policy. It only deletes data when Redis reaches its maximum memory limit, and it targets keys that haven't been accessed recently. It does not verify if the underlying source data has changed, meaning users will get dangerously outdated (hallucinated) AI responses if the source document is updated but the cached response remains in memory.
Reference:
https://zenvanriel.com/ai-engineer-blog/ai-caching-strategies/
NEW QUESTION # 66
An Azure Storage Blob upload must trigger backend processing.
The solution must:
- Avoid polling.
- Minimize latency.
- Trigger automatically when the upload occurs.
You need to ensure that processing starts as soon as a file is uploaded.
Which trigger should you implement?
Answer: D
Explanation:
Azure Event Grid is the best trigger type to use because it pushes real-time event notifications with minimal latency and completely avoids polling.
Push-based model: Sends events instantly as blobs are created.
Lowest latency: Delivers notifications in milliseconds.
No polling overhead: Saves resources compared to timer or queue polling.
How It Works
A user uploads a file to Azure Blob Storage.Blob Storage fires an Microsoft.Storage.BlobCreated event.
Event Grid pushes this event directly to your backend endpoint (such as an Azure Function or Webhook).Processing starts right away.
Reference:
https://damle-amit075.medium.com/azure-databricks-auto-loader-plugging-the-gap-for-batch-loads-72585b0f158e
NEW QUESTION # 67
You need to address the known issue resulting from vector similarity queries.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Detailed Explanation: The objective is to reduce RU consumption from vector similarity queries. Microsoft guidance identifies vector numeric precision and vector-index selection as major cost and performance levers.
Using a lower supported vector precision can reduce storage and processing cost, while quantizedFlat and DiskANN are designed to reduce latency and RU consumption compared with flat search for appropriate data sizes. Strong consistency would increase resource cost rather than solve vector-search efficiency. A regular composite index is not a substitute for the vector index. Option B should be read as reducing vector numeric precision, not changing a generic "indexing precision" setting.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector search in Azure Cosmos DB | Optimize Cosmos DB vector search performance
NEW QUESTION # 68
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to configure Azure Functions to generate vector embeddings according to planned environment application architecture.
Which trigger type should you use?
Answer: A
Explanation:
The most appropriate trigger type for this architecture is the Azure Cosmos DB Trigger.
This trigger monitors your NoSQL container's underlying change feed. When a document is created or modified, the function fires automatically, processes the data, generates the embedding, and places a message in Azure Service Bus.
Scenario, Planned Application Architecture
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/integrated-embeddings
NEW QUESTION # 69
......
If you are also facing the same problem then you are at the trusted spot. BraindumpStudy offers updated and real Microsoft AI-200 Exam Dumps for Developing AI Cloud Solutions on Azure (AI-200) test takers who want to prepare quickly for the Developing AI Cloud Solutions on Azure (AI-200) examination. These actual AI-200 exam questions have been compiled by a team of professionals after a thorough analysis of past papers and current content of the AI-200 test. If students prepare with these valid Developing AI Cloud Solutions on Azure (AI-200) questions, they will surely become capable of clearing the Developing AI Cloud Solutions on Azure (AI-200) examination within a few days.
Reliable AI-200 Exam Testking: https://www.braindumpstudy.com/AI-200_braindumps.html