ちなみに、MogiExam DP-100の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1U1Jou0JUVKmWi23_GEH8JMqpsFlVS2pQ
Microsoftシラバスの変更と理論と実践の最新の開発状況に応じて、DP-100試験のブレインダンプが改訂および更新されます。 DP-100試験トレントは、経験豊富な専門家によって高品質で精巧にまとめられています。 DP-100ガイドの質問の内容は簡単に習得でき、重要な情報を簡素化します。より重要な情報を少ない回答と質問で伝えるため、学習は簡単で効率的です。この言語は理解しやすいため、学習者がDP-100試験に合格して合格するための障害はありません。
試験は、データの探索と準備、モデリング、Azure上でのデータサイエンスソリューションの展開と管理など、幅広いトピックをカバーしています。また、データの取り込み、特徴量エンジニアリング、機械学習アルゴリズムなどのトピックも含まれます。この試験は、これらのトピックに対する理解と実世界のシナリオに適用する能力をテストするよう設計されています。
MicrosoftのDP-100試験クイズを選択するのは賢明な決定です。この決定は将来の開発に大きな影響を与える可能性があるためです。 証明書を持っていることは、あなたが常に夢見ていたことかもしれません。 DP-100試験問題は、MogiExam質の高いサービスを提供し、証明書の取得に役立ちます。 当社のDP-100学習教材は、長年の実践的な努力の後に作成されており、そのDesigning and Implementing a Data Science Solution on Azure品質は実践テストに耐えることができます。 そして、あなたはDP-100学習ガイドのためだけにDP-100認定を取得します。
Microsoft DP-100 試験は、Azure 上でのデータサイエンスソリューションの設計と実装に焦点を当てています。この認定試験は、Microsoft Azure を使用したデータソリューションの設計と実装に興味があるデータプロフェッショナルを対象としています。試験は、データエンジニアリング、データ分析、機械学習、データ可視化など、データサイエンスに関連するさまざまな分野での候補者のスキルを検証します。
Microsoft DP-100試験は、Azure上でデータサイエンスソリューションを設計および実装するスキルを証明するためのプロフェッショナル向けの認定試験であり、MicrosoftのAzure認定プログラムの一部です。この試験は、データサイエンティスト、機械学習エンジニア、およびデータサイエンスに関与するその他のプロフェッショナルを対象としています。
質問 # 355
You manage are Azure Machine Learning workspace by using the Python SDK v2.
You must create an automated machine learning job to generate a classification model by using data files stored in Parquet format. You must configure an auto scaling compute target and a data asset for the job.
You need to configure the resources for the job.
Which resource configuration should you use? to answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.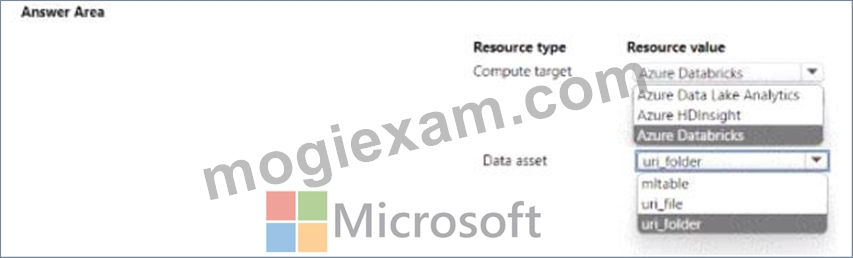
正解:
解説: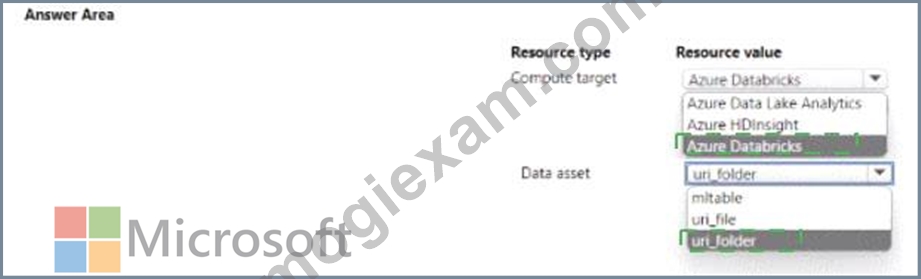
Explanation
質問 # 356
You train a machine learning model by using Aunt Machine Learning.
You use the following training script m Python to log an accuracy value.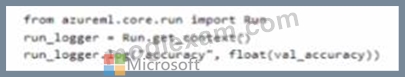
You must use a Python script to define a sweep job.
You need to provide the primary metric and goal you want hyper parameter tuning to optimize.
How should you complete the Python script? To answer select the appropriate options in the answer area NOTE: Each correct selection is worth one point.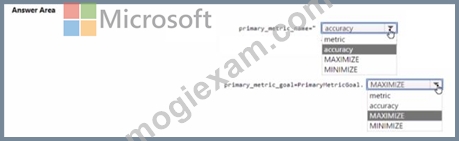
正解:
解説: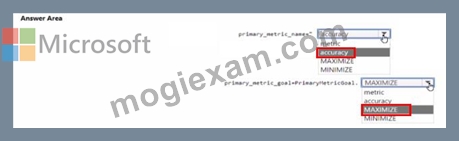
質問 # 357
You need to configure the Edit Metadata module so that the structure of the datasets match.
Which configuration options should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.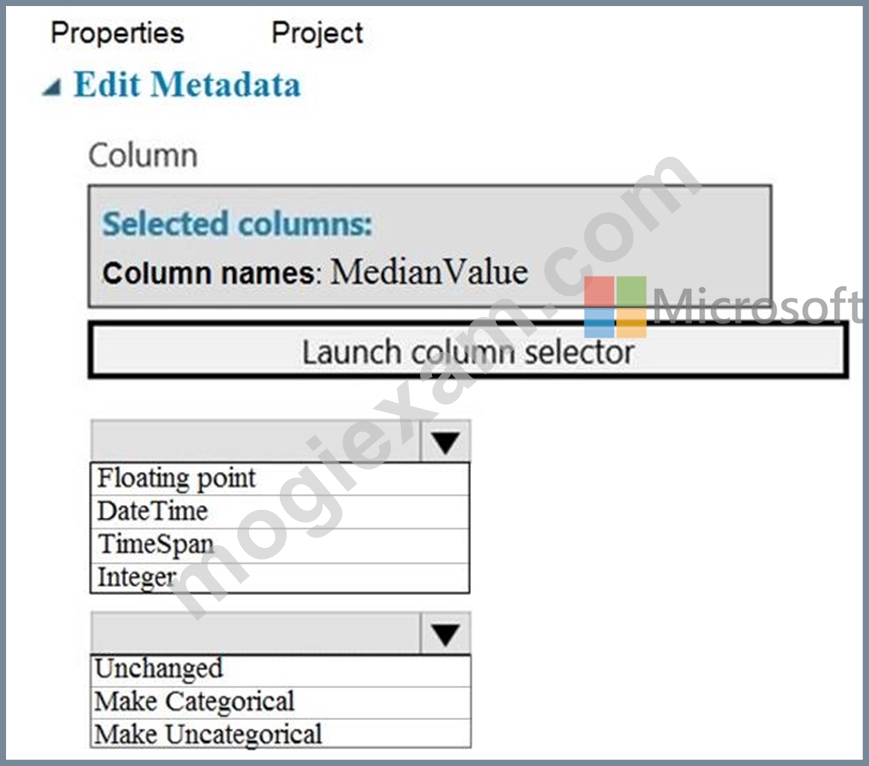
正解:
解説: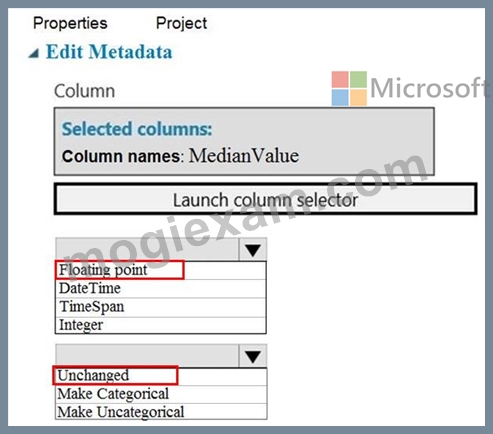
質問 # 358
You are evaluating a Python NumPy array that contains six data points defined as follows:
data = [10, 20, 30, 40, 50, 60]
You must generate the following output by using the k-fold algorithm implantation in the Python Scikit-learn machine learning library:
train: [10 40 50 60], test: [20 30]
train: [20 30 40 60], test: [10 50]
train: [10 20 30 50], test: [40 60]
You need to implement a cross-validation to generate the output.
How should you complete the code segment? To answer, select the appropriate code segment in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.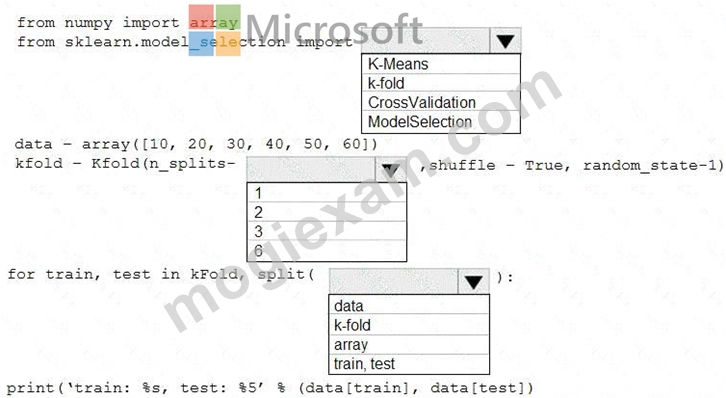
正解:
解説: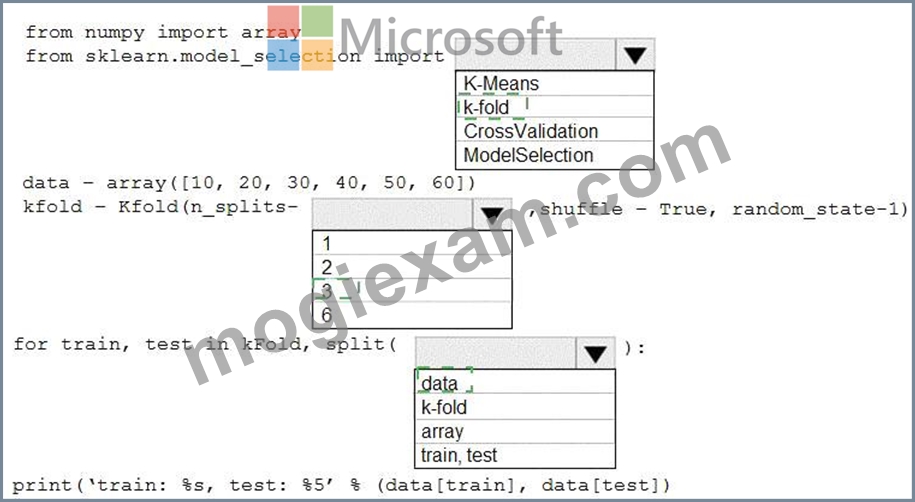
Explanation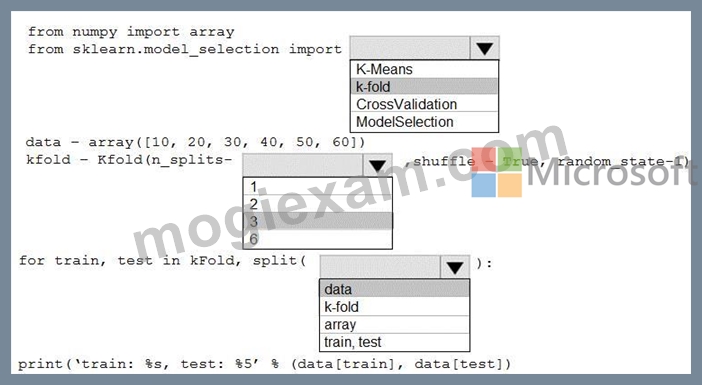
Box 1: k-fold
Box 2: 3
K-Folds cross-validator provides train/test indices to split data in train/test sets. Split dataset into k consecutive folds (without shuffling by default).
The parameter n_splits ( int, default=3) is the number of folds. Must be at least 2.
Box 3: data
Example: Example:
>>>
>>> from sklearn.model_selection import KFold
>>> X = np.array([[1, 2], [3, 4], [1, 2], [3, 4]])
>>> y = np.array([1, 2, 3, 4])
>>> kf = KFold(n_splits=2)
>>> kf.get_n_splits(X)
2
>>> print(kf)
KFold(n_splits=2, random_state=None, shuffle=False)
>>> for train_index, test_index in kf.split(X):
print("TRAIN:", train_index, "TEST:", test_index)
X_train, X_test = X[train_index], X[test_index]
y_train, y_test = y[train_index], y[test_index]
TRAIN: [2 3] TEST: [0 1]
TRAIN: [0 1] TEST: [2 3]
References:
https://scikit-learn.org/stable/modules/generated/sklearn.model_selection.KFold.html
質問 # 359
You manage an Azure Machine Learning workspace named workspace1.
You must register an Azure Blob storage datastore in workspace1 by using an access key. You develop Python SDK v2 code to import all modules required to register the datastore.
You need to complete the Python SDK v2 code to define the datastore.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.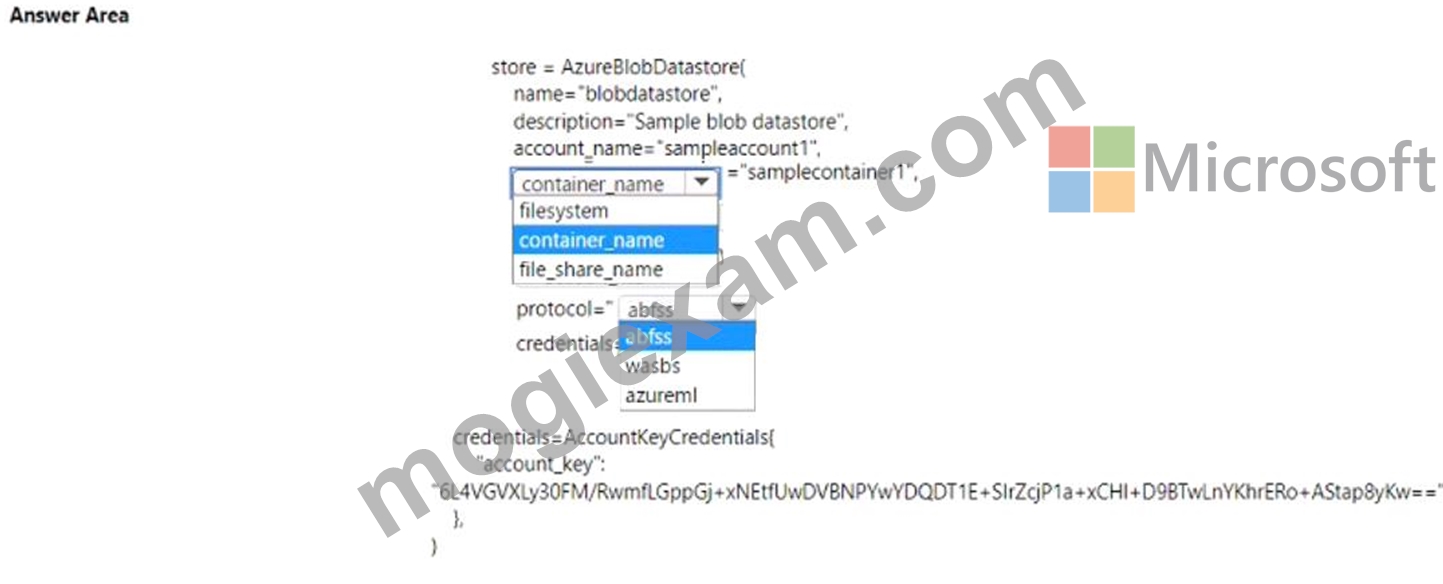
正解:
解説: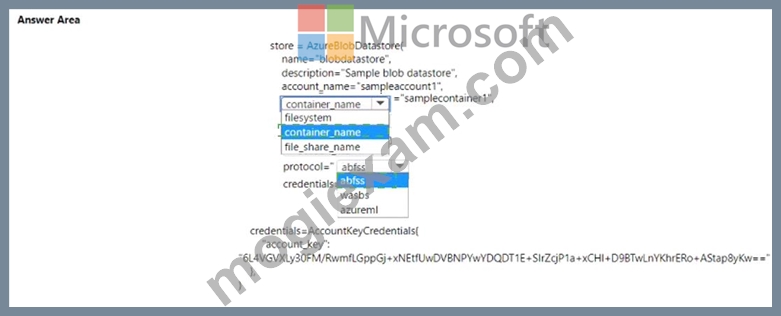
Explanation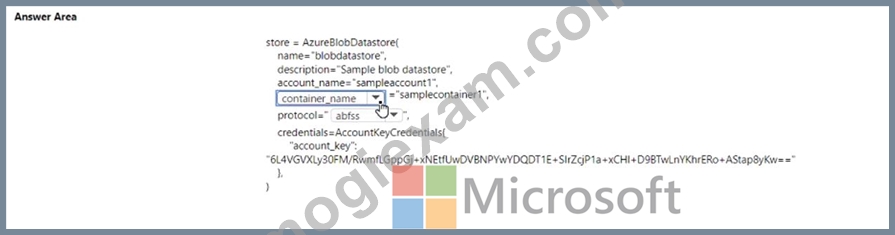
質問 # 360
......
DP-100認定資格: https://www.mogiexam.com/DP-100-exam.html
無料でクラウドストレージから最新のMogiExam DP-100 PDFダンプをダウンロードする:https://drive.google.com/open?id=1U1Jou0JUVKmWi23_GEH8JMqpsFlVS2pQ