Laden Sie die neuesten Zertpruefung DP-600 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1Ev14UtGxcDDwXOcQ4vzh8ennC9gM5Pi8
Wir Zertpruefung bieten Ihnen die freundlichsten Kundendienst. Nach der Kauf der Microsoft DP-600 Prüfungssoftware, bieten wir Ihnen kostenlosen Aktualisierungsdienst für ein voll Jahr, um Sie die neusten und die umfassendsten Unterlagen der Microsoft DP-600 wissen zu lassen. Darum werden Sie sehr sicher sein, die Zertifizierungstest der Microsoft DP-600 zu bestehen. Falls Sie unglücklich die Test der Microsoft DP-600 nicht bei der ersten Proben bestehen, geben wir Ihnen die vollständige Gebühren zurück, um Iheren finanziellen Verlust zu entschädigen.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
>> DP-600 Pruefungssimulationen <<
In der Gesellschaft, wo es so viele Talent gibt, stehen Sie unter dem Druck? Egal welche hohe Qualifikation Sie besitzen, kann die Qualifikation doch Ihre Fähigkeiten nicht bedeuten. Qualifikationen ist nur ein Sprungbrett und Stärke ist der Eckpfeiler, der Ihre Position verstärkt. Die Microsoft DP-600 Zertifizierungsprüfung ist eine beliebte IT-Zertifizierung. Viele Leute wollen das DP-600 Zertifikat bekommen, so dass sie ihre Karriere machen können. Die Schulungsunterlagen zur Microsoft DP-600 Zertifizierungsprüfung von Zertpruefung sind ein gutes Schulungsinstrument, das Ihnen hilft, die Microsoft DP-600 Zertifizierungsprüfung zu bestehen. Mit diesem Zertifikat können Sie international akzeptiert werden. Dann brauchen Sie sich nicht mehr zu fürchten, vom Boss gekündigt zu werden.
102. Frage
You have a Fabric eventhouse named Eventhousel that contains a table named Weatherdata. A sample of the data in Weatherdata is shown in the following table.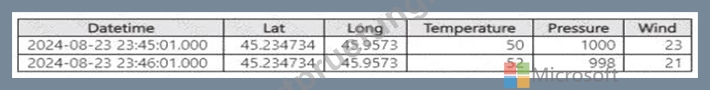
You plan to use a KQL queryset to manipulate the data in Eventhouse1. The result set must have the following columns.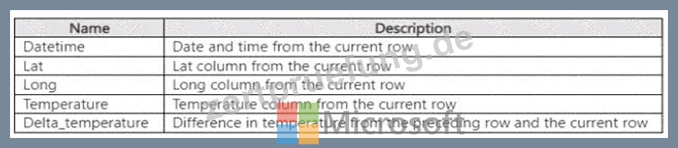
You need to build the query.
Which four KQL statements should you use in sequence? To answer, move the appropriate statements from the list of statements to the answer area and arrange them in the correct order.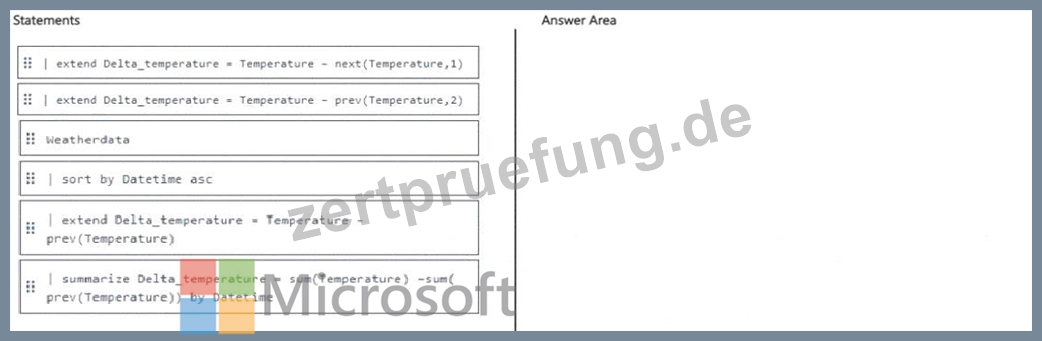
Antwort:
Begründung: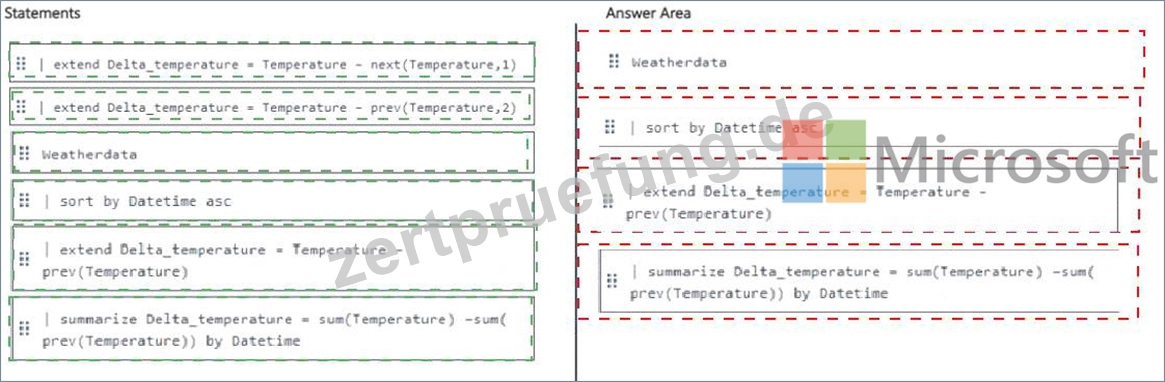
Explanation: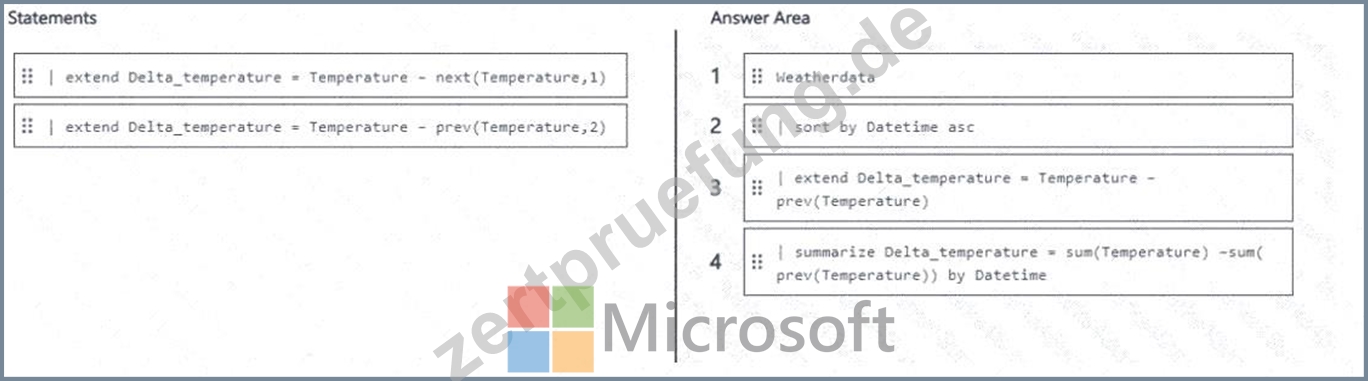
Comprehensive Detailed Explanation
Step 1: Understanding the requirement
We need a KQL query that:
Reads data from Weatherdata .
Orders by Datetime .
Calculates Delta_temperature as the difference between the current row and the preceding row .
Returns the final columns: Datetime, Lat, Long, Temperature, Delta_temperature .
Step 2: Evaluate the provided statements
Weatherdata # Starts the query with the source table.
| sort by Datetime asc # Ensures chronological order, required for prev() to work correctly.
| extend Delta_temperature = Temperature - prev(Temperature) # Computes difference between the current row and the previous row's temperature.
| project Datetime, Lat, Long, Temperature, Delta_temperature # Selects the required output columns.
Step 3: Incorrect choices (to avoid)
next(Temperature,1) # Would calculate the difference with the next row , not the previous.
prev(Temperature,2) # Would skip one row, giving the difference with two rows back, which is not needed.
summarize ... by Datetime # Aggregates the data; not required here since we just need row-level differences.
Step 4: Final Correct Sequence
Weatherdata
| sort by Datetime asc
| extend Delta_temperature = Temperature - prev(Temperature)
| project Datetime, Lat, Long, Temperature, Delta_temperature
References
prev() function in KQL
extend operator in KQL
project operator in KQL
103. Frage
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.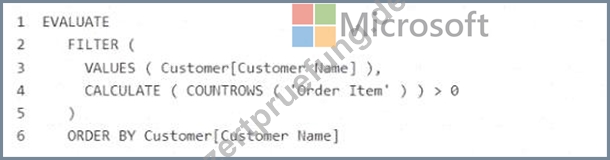
You need to reduce the execution time of the query.
Solution: You replace line 4 by using the following code:
Does this meet the goal?
Antwort: A
Begründung:
The command:
DESCRIBE DETAIL Customer
Returns metadata about the Delta table, such as format, schema, partitioning, size, number of files, and creation/modification timestamps.
However, it does not provide information about whether maintenance tasks (such as OPTIMIZE, VACUUM, or Z-Ordering) were performed on the table.
To check maintenance history, you would typically use:
DESCRIBE HISTORY Customer
which shows operations executed on the table (e.g., OPTIMIZE, VACUUM, MERGE).
Since DESCRIBE DETAIL does not satisfy the requirement, the solution does not meet the goal.
Reference:
DESCRIBE DETAIL in Delta Lake
DESCRIBE HISTORY in Delta Lake
104. Frage
You are implementing a medallion architecture in a single Fabric workspace.
You have a lakehouse that contains the 8ronze and Silver layers and a warehouse that contains the Gold layer.
You create the items required to populate the layers as shown in the following table.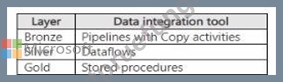
You need to ensure that the layers are populated daily in sequential order such that Silver is populated only after Bronze is complete, and Gold is populated only after Silver is complete. The solution must minimize development effort and complexity.
What should you use to execute each set of items? To answer, drag the appropriate options to the correct items. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.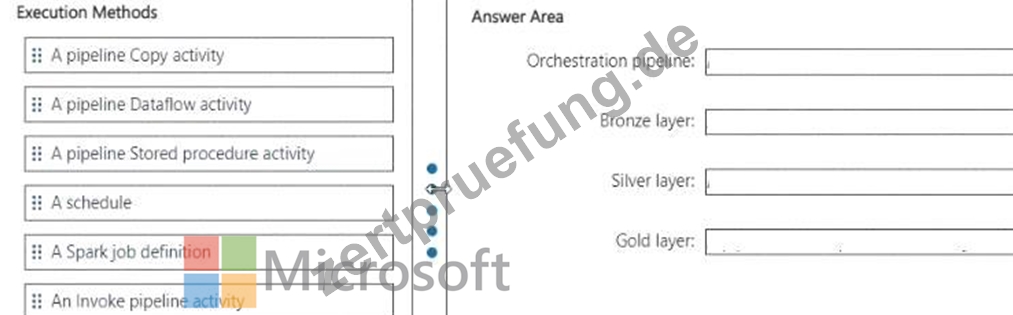
Antwort:
Begründung: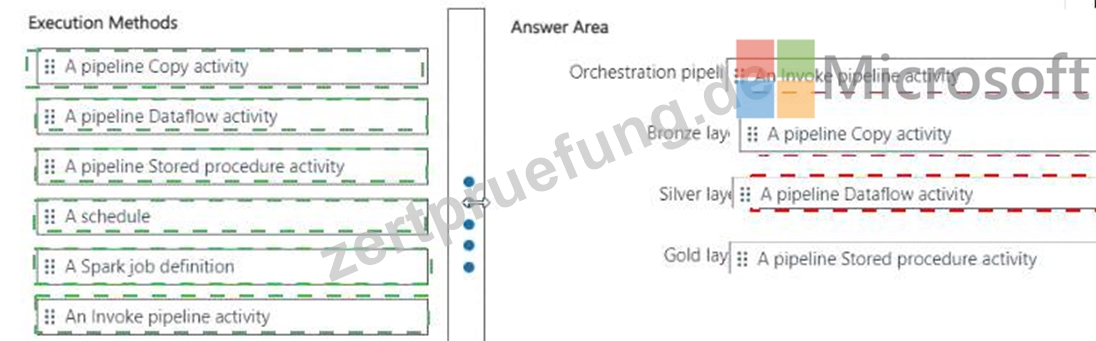
Explanation:
To execute each set of items in sequential order with minimized development effort and complexity, you should use the following options:
* Orchestration pipeline: Use a pipeline with an Invoke pipeline activity. This allows for orchestrating and scheduling the execution of other pipelines, ensuring they run in the correct sequence.
* Bronze layer: Implement a pipeline Copy activity. This aligns with the table indicating that the Bronze layer uses pipelines with Copy activities for data integration.
* Silver layer: Implement a pipeline Dataflow activity. The table specifies that Dataflows are used for the Silver layer.
* Gold layer: Implement a pipeline Stored procedure activity. Stored procedures are specified for the Gold layer according to the table.
105. Frage
You have a Fabric tenant that contains customer churn data stored as Parquet files in OneLake.
The data contains details about customer demographics and product usage.
You create a Fabric notebook to read the data into a Spark DataFrame. You then create column charts in the notebook that show the distribution of retained customers as compared to lost customers based on geography, the number of products purchased, age, and customer tenure.
Which type of analytics are you performing?
Antwort: A
Begründung:
Descriptive analytics tells what happened in the past, presenting it as numbers and visuals in reports and dashboards.
Diagnostic analytics gives the reason why something happened.
Predictive analytics determines the potential outcomes of present and past actions and trends.
Prescriptive analytics offers decision support for the best course of action.
Given the scenario in the question where data is read into a Spark DataFrame and column charts are created to show the distribution of retained customers compared to lost customers based on various factors, this falls under the definition of descriptive analytics. No future predictions or prescriptions are made, nor are reasons for the past events provided.
106. Frage
You have a Fabric workspace that contains a warehouse named Warehouse!. Warehousel contains the following data.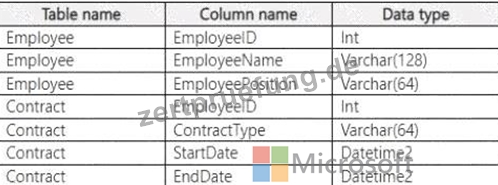
You need to create a T-SQL statement that will denormalize the tables and include the ContractType and StartDate attributes in the results. The solution must meet the following requirements:
* Include attributes from matching rows in the Contract table.
* Ensure that all the rows from the Employee table are preserved.
* Return the total number of employees per contract type for all the contract types that have more than two employees.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.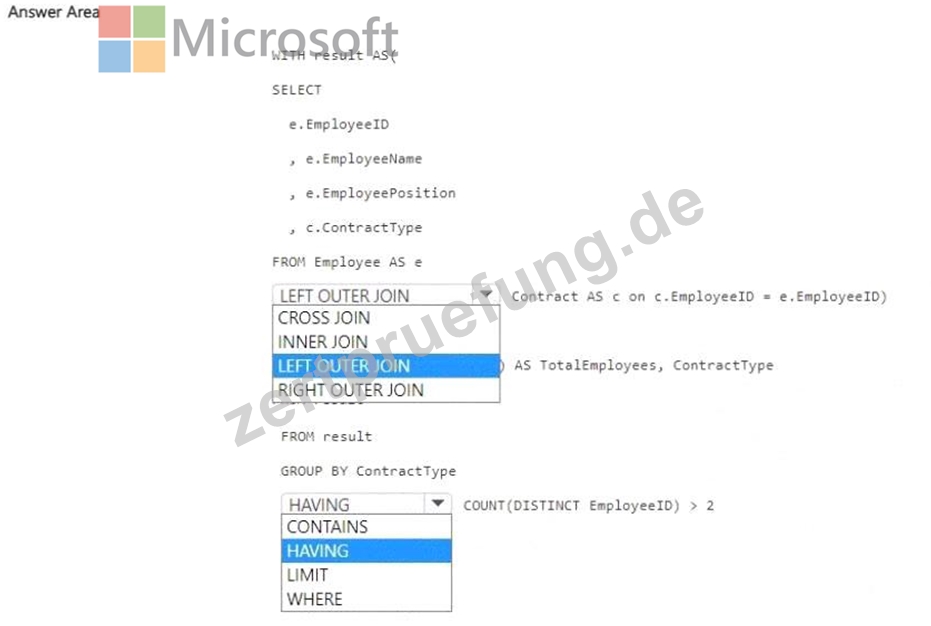
Antwort:
Begründung: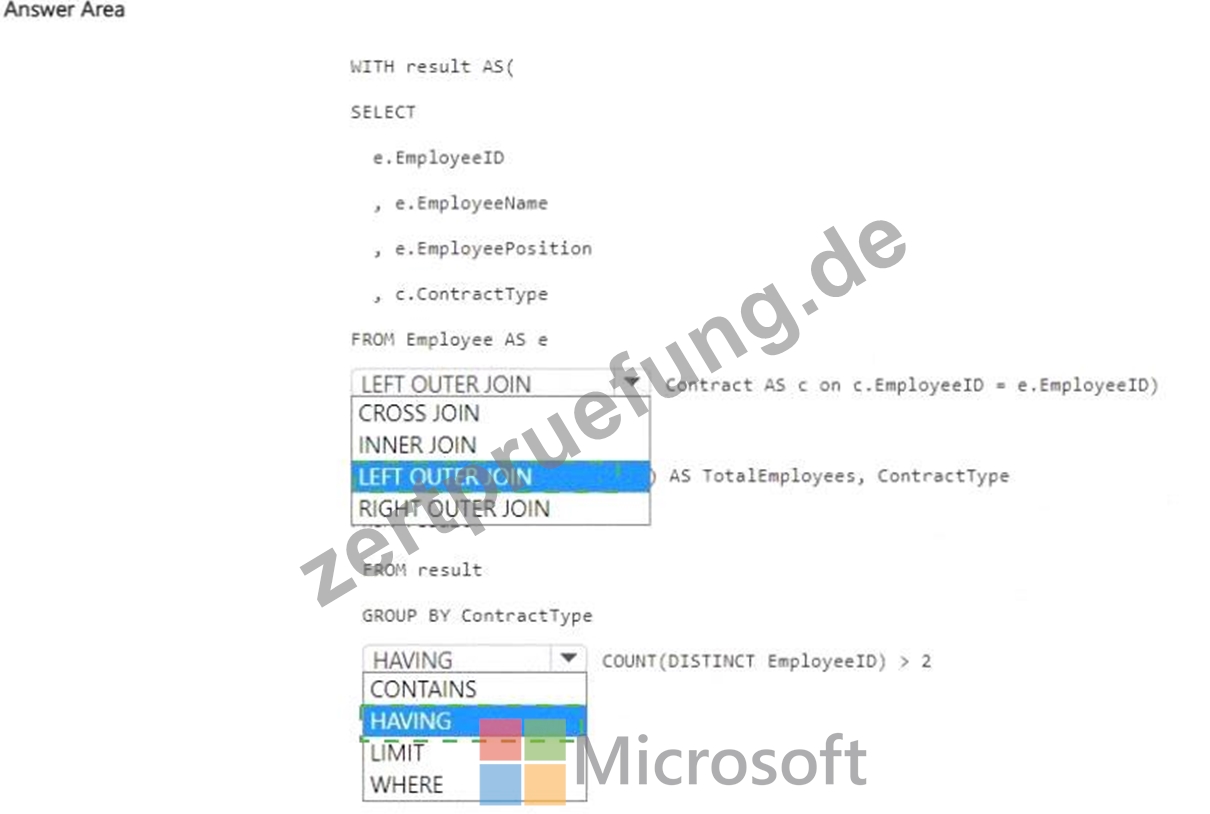
Explanation: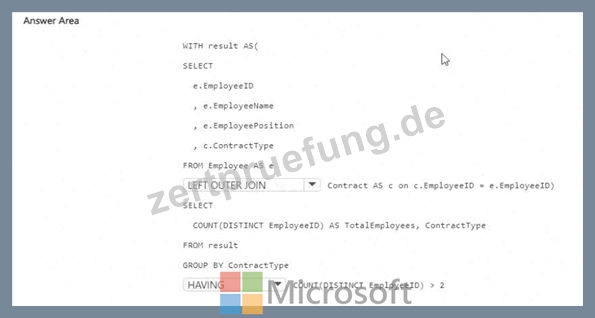
Comprehensive Detailed Explanation
We are tasked with writing a T-SQL query to denormalize the tables Employee and Contract in a Fabric warehouse.
Requirements Breakdown
Include attributes from matching rows in the Contract table
This means we must join Employee and Contract on EmployeeID .
Ensure that all rows from the Employee table are preserved
This requires a LEFT OUTER JOIN from Employee to Contract. If an employee has no contract, we still want the employee record included.
Return the total number of employees per contract type for all contract types that have more than two employees This means we need to:
Group by ContractType
Count distinct EmployeeID
Filter groups where that count > 2.
To filter aggregated results, we use HAVING , not WHERE.
Completed Query
WITH result AS (
SELECT
e.EmployeeID,
e.EmployeeName,
e.EmployeePosition,
c.ContractType,
c.StartDate
FROM Employee AS e
LEFT OUTER JOIN Contract AS c
ON c.EmployeeID = e.EmployeeID
)
SELECT
ContractType,
COUNT ( DISTINCT EmployeeID) AS TotalEmployees
FROM result
GROUP BY ContractType
HAVING COUNT ( DISTINCT EmployeeID) > 2 ;
Why This is Correct
LEFT OUTER JOIN ensures all employees are included, regardless of contracts.
HAVING allows filtering aggregated groups by employee counts.
The query returns ContractType , StartDate (as requested in denormalization), and aggregated employee counts.
References
T-SQL JOINs in Microsoft Fabric
Aggregate functions and HAVING clause
Denormalization best practices in Fabric warehouses
107. Frage
......
In diesem Zeitalter des Internets gibt es viele Möglichkeiten, Microsoft DP-600 Zertifizierungsprüfung vorzubereiten. Zertpruefung bietet die zuverlässigsten Zertifizierungsfragen und Antworten, die Ihnen helfen, Microsoft DP-600 Zertifizierungsprüfung zu bestehen. Zertpruefung haben eine Vielzahl von Microsoft DP-600 Zertifizierungsprüfungen. Wir werden alle Ihrer Wünsche über IT-Zertifizierungen erfüllen.
DP-600 Dumps: https://www.zertpruefung.de/DP-600_exam.html
Übrigens, Sie können die vollständige Version der Zertpruefung DP-600 Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1Ev14UtGxcDDwXOcQ4vzh8ennC9gM5Pi8