All these three Microsoft DP-800 exam questions formats contain the real, valid, and error-free Developing AI-Enabled Database Solutions (DP-800) exam practice test questions that are ideal study material for quick Microsoft DP-800 Exam Preparation. Just choose the right VCE4Dumps Developing AI-Enabled Database Solutions Questions formats and download quickly and start Developing AI-Enabled Database Solutions (DP-800) exam preparation without wasting further time.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Passing Score: | 700 |
| Exam Price: | $165 USD |
| Certificate Validity Period: | 1 year |
| Real Exam Qty: | 40-60 |
| Exam Format: | Drag and drop, Multiple choice, Build list, Multiple select, Case studies |
| Related Certifications: | Microsoft Certified: SQL AI Developer Associate |
| Exam Duration: | 100 minutes |
| Available Languages: | Portuguese (Brazil), Chinese (Traditional), Arabic (Saudi Arabia), German, Korean, Japanese, French, Italian, English, Indonesian (Indonesia), Chinese (Simplified), Spanish |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or in-person at a testing center |
| Pre Condition: | No specific prerequisites, but candidates should have experience with SQL and a basic understanding of Azure services. Familiarity with AI or machine learning concepts is recommended. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-800/ |
We are quite confident that all these Microsoft DP-800 exam dumps feature you will not find anywhere. Just download the Microsoft DP-800 and start this journey right now. For the well and quick DP-800 exam dumps preparation, you can get help from Microsoft DP-800 which will provide you with everything that you need to learn, prepare and pass the Developing AI-Enabled Database Solutions (DP-800) certification exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 15
Hotspot Question
You have an Azure SQL database that contains a table named stores. stores contains a column named description and a vector column named embedding.
You need to implement a hybrid search query that meets the following requirements:
- Uses full-text search on description for the keyword portion
- Returns the top 20 results based on a combined score that uses a
weighted formula of 60% vector distance and 40% full-text rank
How should you configure the query components? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.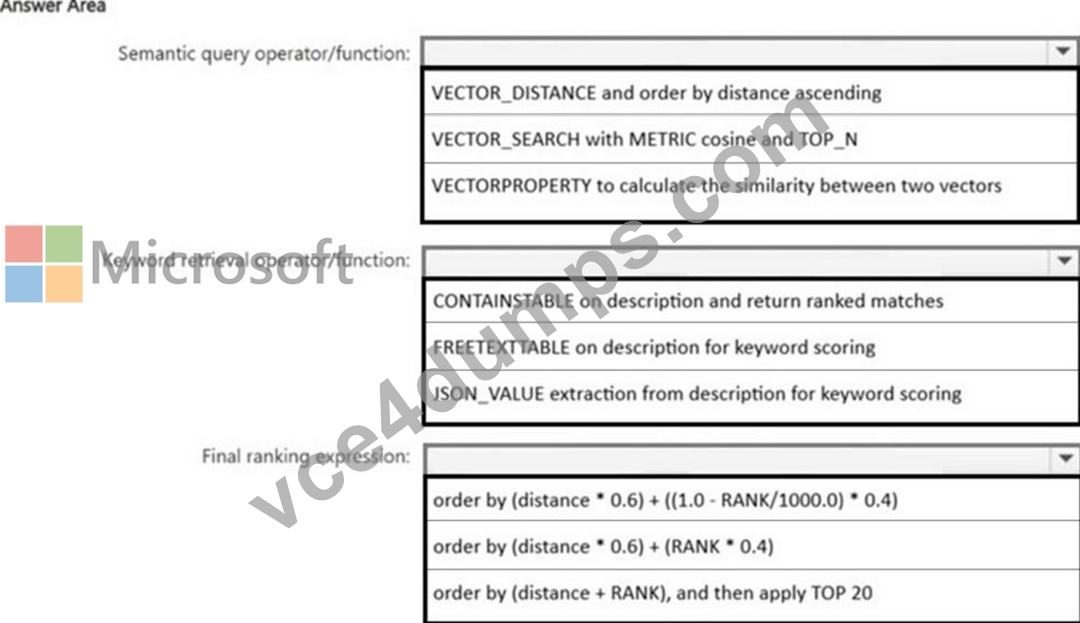
Answer:
Explanation: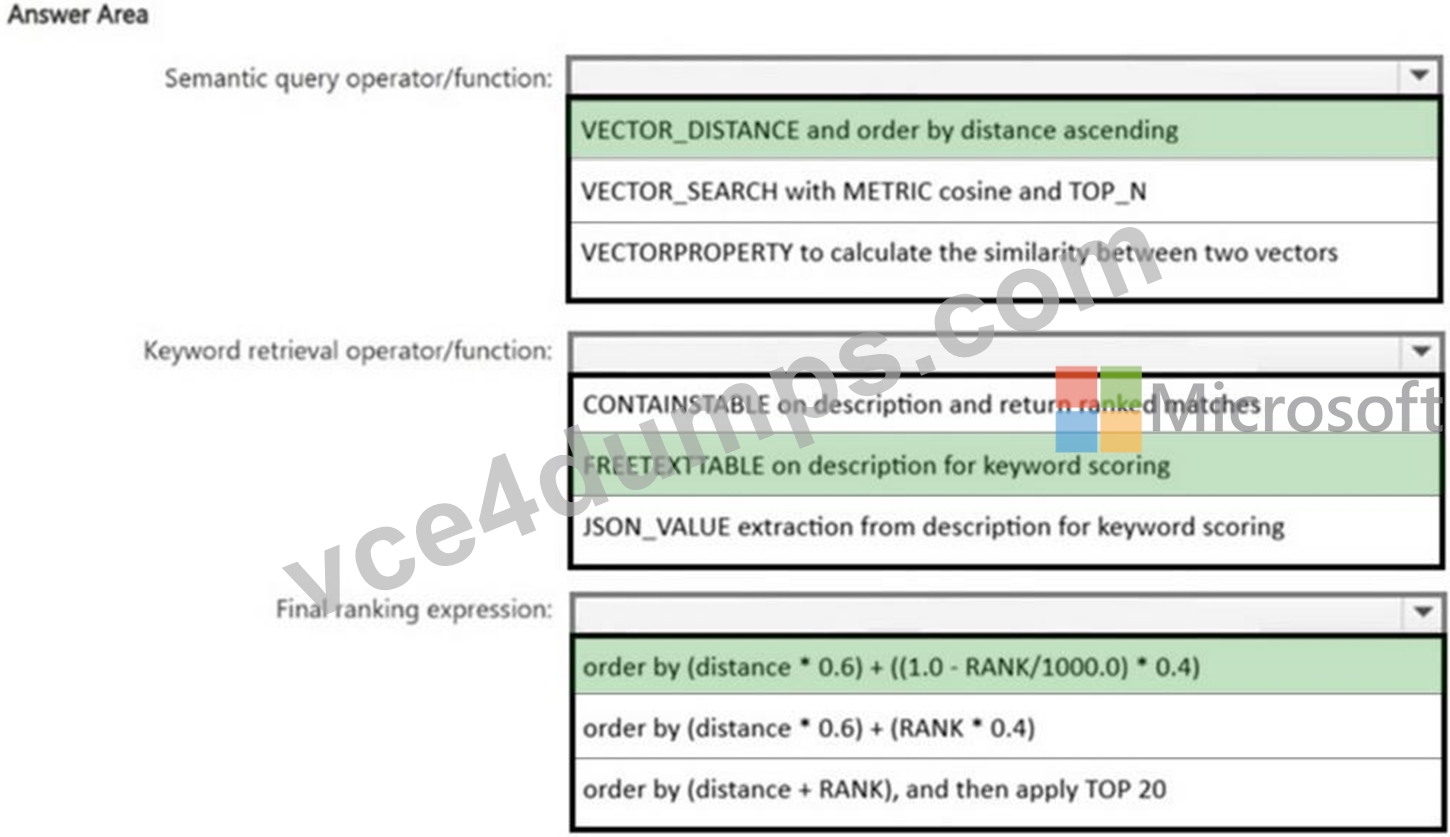
NEW QUESTION # 16
You have an Azure SQL database named ToDo that contains a table named dbo.ToDo.
Your company plans to develop an Azure Functions app to run whenever the rows in dbo.ToDo change. The app will process INSERT, UPDATE, and DELETE events by using the Azure SQL trigger binding.
You need to configure ToDo to support the planned app.
What should you do?
Answer: A
Explanation:
To use the Azure SQL trigger for Azure Functions, your database table must have Change Tracking enabled. This is the underlying mechanism the trigger uses to monitor row-level modifications.
Required Table Configuration
To facilitate the app, you must follow these three steps:
1. Enable Change Tracking on the Database
Before the table can be tracked, the feature must be turned on at the database level.
2. Enable Change Tracking on the Table
The specific table the Function monitors must have tracking enabled.
3. Define a Primary Key
The Azure SQL trigger requires the table to have a Primary Key.
The trigger uses the Primary Key to identify which specific rows were changed.
If your table lacks a Primary Key, the Function will fail to start.
Reference:
https://demiliani.com/2025/05/08/azure-function-sql-trigger-how-to-use-it-and-why-it-can-be- useful-in-your-business-central-projects/
NEW QUESTION # 17
You have an Azure SQL database that contains a table named dbo.ManualChunks. dbo.HonualChunks contains product manuals A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpomt for chat completions. The request body must include both the user question and theretiieved chunks.
You write the following Transact-SQL code.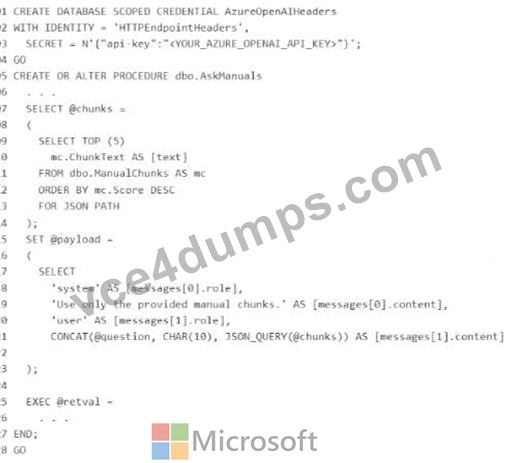
What should you insert at line 22?
Answer: C
Explanation:
The correct insertion at line 22 is FOR JSON PATH, WITHOUT_ARRAY_WRAPPER .
The request body for the Azure OpenAI chat completions call must be a single JSON object containing the messages array with both the system/user content and the retrieved chunks. Microsoft documents that FOR JSON PATH is the preferred way to shape JSON output, especially when you want precise control over nested property names like messages[0].role and messages[1] .content.
The key detail is WITHOUT_ARRAY_WRAPPER . By default, FOR JSON returns results enclosed in square brackets as a JSON array. Microsoft documents that WITHOUT_ARRAY_WRAPPER removes those brackets so a single JSON object is produced instead. That is exactly what is needed here for @payload, because the stored procedure is building one request body, not an array of request bodies.
NEW QUESTION # 18
You have an Azure SQL database named SalesDB that contains a table named dbo. Articles, dbo.Articles contains two million articles with embeddmgs. The articles are updated frequently throughout the day.
You query the embeddings by using VECTOR_SEARQi
Users report that semantic search results do NOT reflect the updates until the following day.
Vou need to ensure that the embeddings are updated whenever the articles change. The solution must minimize CPU usage on SalesDB Which embedding maintenance method should you implement?
Answer: A
Explanation:
The correct answer is B because the problem is not the vector search operator itself. The problem is that embeddings are becoming stale when article content changes . Microsoft documents that change data capture (CDC) tracks insert, update, and delete operations on source tables, which makes it the right mechanism to identify only the rows that changed.
This also best satisfies the requirement to minimize CPU usage on SalesDB . With CDC, the database only records the row changes, and the embedding regeneration work can be moved to an external process such as an Azure Functions app. That avoids running embedding generation inline inside the database for every update and avoids repeatedly recalculating embeddings for unchanged rows. In contrast, an hourly full-table regeneration would be extremely wasteful on a table with two million frequently updated articles, and a trigger that calls embedding generation per row would push expensive AI work into the transactional path of the database.
Option A is incorrect because changing from VECTOR_SEARCH to VECTOR_DISTANCE does not regenerate embeddings; it only changes the retrieval method. Microsoft states that VECTOR_SEARCH is the ANN search function, while VECTOR_DISTANCE performs exact distance calculation, so neither option addresses stale embedding data.
So the right design is:
* use CDC to detect only changed articles,
* process those changes outside the database,
* regenerate embeddings only for changed rows,
* write back the refreshed embeddings for current semantic search results.
NEW QUESTION # 19
You have an Azure SQL table that contains the following data.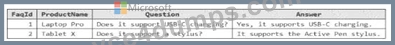
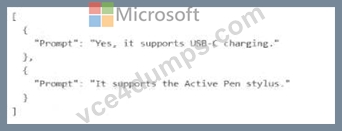
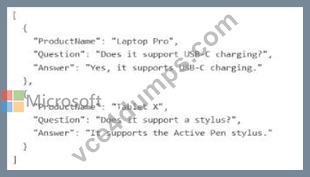
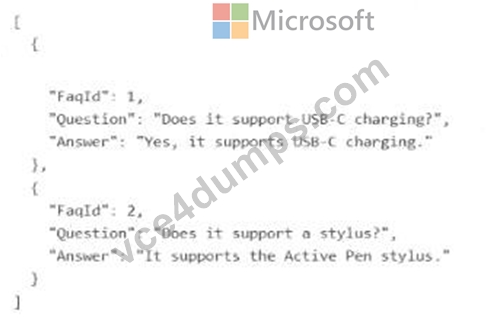
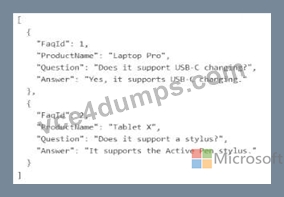
You need to retrieve data to be used as context for a large language model (LLM). The solution must minimize token usage.
Which formal should you use to send the data to the LLM?
Answer: B
Explanation:
The correct choice is Option A because it provides the relevant semantic context the LLM needs while avoiding an unnecessary field that would add tokens without improving answer quality.
For LLM grounding and RAG-style context, Microsoft guidance emphasizes mapping and sending the fields that contain text pertinent to the use case . In this FAQ scenario, the useful context is the ProductName , the Question , and the Answer . Those three fields help the model understand both the subject domain and the actual Q & A pair. By contrast, FaqId is just a technical identifier and generally adds no semantic value for response generation, so including it wastes tokens.
That is why Option A is better than the others:
* Option A keeps the meaningful text fields and removes the low-value identifier.
* Option B is too minimal because it includes only the answer text as Prompt, which strips away the product and question context the LLM may need for accurate grounding.
* Option C keeps FaqId but omits ProductName, which can be important disambiguating context.
* Option D includes everything, but that does not minimize token usage because it keeps the unnecessary FaqId.
NEW QUESTION # 20
......
DP-800 Regualer Update: https://www.vce4dumps.com/DP-800-valid-torrent.html