Databricks-Machine-Learning-Professional퍼펙트덤프데모 & Databricks-Machine-Learning-Professional최신시험

그리고 DumpTOP Databricks-Machine-Learning-Professional 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1W9Nc3N4UwWAH4Xi7aUOD-pO-qpOT3NmQ
DumpTOP는 IT업계에서 유명한 IT인증자격증 공부자료를 제공해드리는 사이트입니다. 이는DumpTOP 의 IT전문가가 오랜 시간동안 IT인증시험을 연구한 끝에 시험대비자료로 딱 좋은 덤프를 제작한 결과입니다. Databricks인증 Databricks-Machine-Learning-Professional덤프는 수많은 덤프중의 한과목입니다. 다른 덤프들과 같이Databricks인증 Databricks-Machine-Learning-Professional덤프 적중율과 패스율은 100% 보장해드립니다. Databricks인증 Databricks-Machine-Learning-Professional시험에 도전하려는 분들은DumpTOP 의Databricks인증 Databricks-Machine-Learning-Professional덤프로 시험을 준비할것이죠?
Databricks Databricks-Machine-Learning-Professional 시험요강:
| 주제 | 소개 |
|---|
| 주제 1 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| 주제 2 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| 주제 3 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| 주제 4 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| 주제 5 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| 주제 6 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| 주제 7 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| 주제 8 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| 주제 9 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| 주제 10 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| 주제 11 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
>> Databricks-Machine-Learning-Professional퍼펙트 덤프데모 <<
Databricks-Machine-Learning-Professional최신시험 - Databricks-Machine-Learning-Professional인증덤프 샘플문제
DumpTOP의 Databricks인증 Databricks-Machine-Learning-Professional시험덤프는 실제시험의 기출문제와 예상문제를 묶어둔 공부자료로서 시험문제커버율이 상당히 높습니다.IT업계에 계속 종사하려는 IT인사들은 부단히 유력한 자격증을 취득하고 자신의 자리를 보존해야 합니다. DumpTOP의 Databricks인증 Databricks-Machine-Learning-Professional시험덤프로 어려운 Databricks인증 Databricks-Machine-Learning-Professional시험을 쉽게 패스해보세요. IT자격증 취득이 여느때보다 여느일보다 쉬워져 자격증을 많이 따는 꿈을 실현해드립니다.
최신 ML Data Scientist Databricks-Machine-Learning-Professional 무료샘플문제 (Q178-Q183):
질문 # 178
A machine learning engineer has a machine learning pipeline where predictions are updated annually. The final prediction dataset contains millions of rows, and that dataset is irregularly accessed. Which solution should the machine learning engineer use to maintain cost efficiency?
- A. Cloud-based low latency database
- B. On-premises low-latency database
- C. Cloud-based object storage
- D. Cloud-based in-memory instance of a Spark DataFrame
정답:C
설명:
For data that is large in size, infrequently accessed, and updated only periodically, cloud-based object storage (such as AWS S3, Azure Blob Storage, or Google Cloud Storage) is the most cost- efficient option. It offers durable, scalable, and inexpensive storage compared to in-memory or low-latency databases, which are optimized for frequent access and real-time performance rather than long-term, infrequent retrieval.
질문 # 179
A data scientist has run the following line of code to create a Feature Store table:
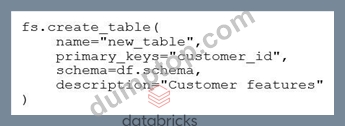
Which statement correctly describes the data in the Feature Store table new_table?
- A. The data in new_table is the customer-related features from df
- B. The data in new_table is the values in column customer_id from df
- C. The data in new_table is exactly the same as the data in df
- D. There is no data in new_table
정답:D
설명:
The fs.create_table() command defines metadata for a Feature Store table, such as its name, primary key, schema, and description - but it does not insert any data into the table. This command simply registers an empty table structure based on the provided schema (df.schema).
To populate the table with data, a separate fs.write_table() or equivalent write operation must be executed afterward.
질문 # 180
A Machine Learning Engineer is tasked with implementing a simple solution, requiring as little code as possible, to monitor a regression model and ensure that the R2 score does not exceed a certain threshold. If the threshold is exceeded, the solution needs to send an email to a distribution list. Which proposed solution meets the criteria?
- A. Configure Lakehouse Monitoring using the Inference profile type. Create a SQL Query that runs on a schedule and evaluates if the R2 score in the profile table exceeds the threshold. If so, the Alert should send an email to the configured email notification destination.
- B. Configure Lakehouse Monitoring using the Inference profile type. Create a SQL Alert that runs on a schedule and evaluates if the R2 score in the profile table exceeds the threshold. If so, the Alert should send an email to the configured email notification destination.
- C. Configure Lakehouse Monitoring using the Inference profile type. Create a Workflow that runs on a schedule and executes a SQL query that evaluates the R2 score in the profile table. Use Workflow If/Else condition to execute a Notebook Task that sends the email if the R2 score threshold is exceeded.
- D. Create a Workflow that runs on a schedule. The Workflow executes a SQL Query that calculates the R2 score. Use Workflow If/Else condition to execute a Notebook Task that sends the email if the R2 score threshold is exceeded.
정답:B
설명:
Lakehouse Monitoring with the Inference profile already computes regression performance metrics such as R2 and stores them in Delta tables. A Databricks SQL Alert can directly evaluate the R2 value against a threshold on a schedule and send an email notification when the condition is met. This requires minimal code and avoids additional workflows or custom logic, making it the simplest and most maintainable solution.
질문 # 181
A Data Scientist is developing a model training pipeline on Databricks and needs to track custom performance metrics during training. They want to log a custom evaluation score (team_score), a single hyperparameter, and a confusion matrix plot as part of their MLflow experiment. Which code snippet correctly logs all three types of information in MLflow?
- A. mlflow.log_param("max_depth", "5")
mlflow.log_metric("team_score", "0.92")
mlflow.log_artifact("confusion_matrix.png") - B. mlflow.log_param("max_depth", 5)
mlflow.log_metric("team_score", 0.92)
mlflow.log_artifact(open("confusion_matrix.png")) - C. mlflow.log_metric({"team_score": 0.92})
mlflow.log_param(["max_depth", 5])
mlflow.log_file("confusion_matrix.png") - D. mlflow.log_param("max_depth", 5)
mlflow.log_metric("team_score", 0.92)
mlflow.log_artifact("confusion_matrix.png")
정답:D
설명:
This snippet correctly uses MLflow's APIs to log each item in its expected form: a single hyperparameter with log_param, a numeric custom metric with log_metric, and a file-based artifact such as a confusion matrix image by passing its file path to log_artifact. This is the standard and correct way to track parameters, metrics, and artifacts in an MLflow experiment.
질문 # 182
A machine learning engineer is migrating a machine learning pipeline to use Databricks Machine Learning. They have programmatically identified the best run from an MLflow Experiment and stored its URI in the model_uri variable and its Run ID in the run_id variable. They have also determined that the model was logged with the name "model". Now, the machine learning engineer wants to register that model in the MLflow Model Registry with the name "best_model".
Which line of code can they use to register the model to the MLflow Model Registry?
- A. mlflow.register_model(run_id, "best_model")
- B. mlflow.register_model(f"runs:/{run_id}/model")
- C. mlflow.register_model(f"runs:/{run_id}/best_model", "model")
- D. mlflow.register_model(model_uri, "best_model")
- E. mlflow.register_model(model_uri, "model")
정답:D
질문 # 183
......
Databricks Databricks-Machine-Learning-Professional 덤프구매전 한국어 온라인상담서비스부터 구매후 덤프 무료 업데이트버전제공 , Databricks Databricks-Machine-Learning-Professional시험불합격시 덤프비용 전액환불 혹은 다른 과목으로 교환 등 저희는 구매전부터 구매후까지 철저한 서비스를 제공해드립니다. Databricks Databricks-Machine-Learning-Professional 덤프는 인기덤프인데 지금까지 덤프를 구매한후 환불신청하신 분은 아직 없었습니다.
Databricks-Machine-Learning-Professional최신시험: https://www.dumptop.com/Databricks/Databricks-Machine-Learning-Professional-dump.html
- 시험패스 가능한 Databricks-Machine-Learning-Professional퍼펙트 덤프데모 덤프공부문제 🛌 ⇛ www.pass4test.net ⇚웹사이트를 열고{ Databricks-Machine-Learning-Professional }를 검색하여 무료 다운로드Databricks-Machine-Learning-Professional퍼펙트 최신 덤프공부
- Databricks-Machine-Learning-Professional퍼펙트 덤프데모 완벽한 시험덤프 데모문제 다운로드 ⏭ 오픈 웹 사이트{ www.itdumpskr.com }검색⮆ Databricks-Machine-Learning-Professional ⮄무료 다운로드Databricks-Machine-Learning-Professional최신 시험 최신 덤프자료
- Databricks Databricks-Machine-Learning-Professional덤프가 고객님께 드리는 약속 Databricks Certified Machine Learning Professional ♻ 무료 다운로드를 위해【 Databricks-Machine-Learning-Professional 】를 검색하려면➡ www.dumptop.com ️⬅️을(를) 입력하십시오Databricks-Machine-Learning-Professional높은 통과율 시험대비 덤프공부
- Databricks-Machine-Learning-Professional높은 통과율 시험대비 덤프공부 😢 Databricks-Machine-Learning-Professional덤프문제모음 🚖 Databricks-Machine-Learning-Professional높은 통과율 시험대비자료 🐏 무료로 다운로드하려면⇛ www.itdumpskr.com ⇚로 이동하여▷ Databricks-Machine-Learning-Professional ◁를 검색하십시오Databricks-Machine-Learning-Professional시험대비 최신버전 덤프
- Databricks-Machine-Learning-Professional높은 통과율 시험대비 덤프공부 🐹 Databricks-Machine-Learning-Professional덤프문제모음 🎥 Databricks-Machine-Learning-Professional최신 인증시험 공부자료 🚇 시험 자료를 무료로 다운로드하려면⮆ www.itdumpskr.com ⮄을 통해⇛ Databricks-Machine-Learning-Professional ⇚를 검색하십시오Databricks-Machine-Learning-Professional공부문제
- Databricks-Machine-Learning-Professional높은 통과율 시험대비 덤프공부 📻 Databricks-Machine-Learning-Professional퍼펙트 최신 덤프문제 📗 Databricks-Machine-Learning-Professional시험대비 최신버전 덤프 🙄 ▛ Databricks-Machine-Learning-Professional ▟를 무료로 다운로드하려면《 www.itdumpskr.com 》웹사이트를 입력하세요Databricks-Machine-Learning-Professional자격증참고서
- 퍼펙트한 Databricks-Machine-Learning-Professional퍼펙트 덤프데모 최신버전 덤프데모 문제 다운 👕 무료 다운로드를 위해 지금➡ www.koreadumps.com ️⬅️에서▶ Databricks-Machine-Learning-Professional ◀검색Databricks-Machine-Learning-Professional인증공부문제
- 시험패스 가능한 Databricks-Machine-Learning-Professional퍼펙트 덤프데모 덤프공부문제 🍝 무료로 다운로드하려면➥ www.itdumpskr.com 🡄로 이동하여➡ Databricks-Machine-Learning-Professional ️⬅️를 검색하십시오Databricks-Machine-Learning-Professional인증시험대비자료
- Databricks-Machine-Learning-Professional시험대비 최신버전 덤프 🌸 Databricks-Machine-Learning-Professional최신 업데이트 시험덤프 🃏 Databricks-Machine-Learning-Professional인증공부문제 🟤 ⮆ www.koreadumps.com ⮄을(를) 열고➤ Databricks-Machine-Learning-Professional ⮘를 검색하여 시험 자료를 무료로 다운로드하십시오Databricks-Machine-Learning-Professional인증공부문제
- 시험패스에 유효한 Databricks-Machine-Learning-Professional퍼펙트 덤프데모 최신버전 덤프샘플 👤 ⇛ www.itdumpskr.com ⇚웹사이트에서✔ Databricks-Machine-Learning-Professional ️✔️를 열고 검색하여 무료 다운로드Databricks-Machine-Learning-Professional높은 통과율 시험대비 덤프공부
- Databricks-Machine-Learning-Professional시험대비 덤프데모문제 다운 🌋 Databricks-Machine-Learning-Professional최신 업데이트 시험덤프 🅱 Databricks-Machine-Learning-Professional덤프문제모음 🍗 ➥ www.koreadumps.com 🡄에서 검색만 하면⇛ Databricks-Machine-Learning-Professional ⇚를 무료로 다운로드할 수 있습니다Databricks-Machine-Learning-Professional퍼펙트 최신 덤프공부
- www.ganjingworld.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
참고: DumpTOP에서 Google Drive로 공유하는 무료, 최신 Databricks-Machine-Learning-Professional 시험 문제집이 있습니다: https://drive.google.com/open?id=1W9Nc3N4UwWAH4Xi7aUOD-pO-qpOT3NmQ