Databricks Certified-Data-Engineer-Professional테스트자료 & Certified-Data-Engineer-Professional시험덤프자료

KoreaDumps는Databricks Certified-Data-Engineer-Professional시험을 패스할 수 있는 아주 좋은 사이트입니다. KoreaDumps은 아주 알맞게 최고의Databricks Certified-Data-Engineer-Professional시험문제와 답 내용을 만들어 냅니다. 덤프는 기존의 시험문제와 답과 시험문제분석 등입니다. KoreaDumps에서 제공하는Databricks Certified-Data-Engineer-Professional시험자료의 문제와 답은 실제시험의 문제와 답과 아주 비슷합니다.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure Databricks-to-Databricks Sharing
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use Query Profiler and Spark UI to monitor workloads
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 2. Use control flow operators in pipeline components
- 3. Compare streaming tables and materialized views
- 4. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 5. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 6. Configure environments, dependencies, memory, and retry behavior
- 7. Use APPLY CHANGES APIs for change data capture
- 8. Develop unit and integration tests for data processing code
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
|
>> Databricks Certified-Data-Engineer-Professional테스트자료 <<
Certified-Data-Engineer-Professional테스트자료 100% 유효한 최신 덤프자료
KoreaDumps의Databricks인증Certified-Data-Engineer-Professional자료는 제일 적중률 높고 전면적인 덤프임으로 여러분은 100%한번에 응시로 패스하실 수 있습니다. 그리고 우리는 덤프를 구매 시 일년무료 업뎃을 제공합니다. 여러분은 먼저 우리 KoreaDumps사이트에서 제공되는Databricks인증Certified-Data-Engineer-Professional시험덤프의 일부분인 데모 즉 문제와 답을 다운받으셔서 체험해보실 수 잇습니다.
최신 Databricks Certification Certified-Data-Engineer-Professional 무료샘플문제 (Q123-Q128):
질문 # 123
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use a grouped_agg Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
- B. Use a SCALAR_ITER Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
- C. Use a SCALAR Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
- D. Use applyInPandas() on a Spark DataFrame that receives all rows for each stock symbol as a Pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
정답:D
설명:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
질문 # 124
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
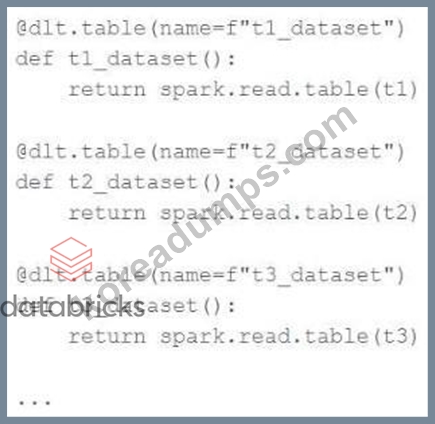
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
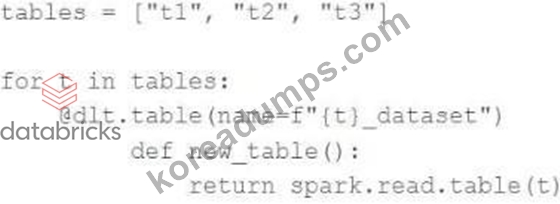
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- B. Convert the list of configuration values to a dictionary of table settings, using different input the for loop.
- C. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- D. Wrap the loop inside another table definition, using generalized names and properties to replace with those from the inner table
정답:C
설명:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names.
Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
질문 # 125
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. A data engineer has been asked to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing. Which role must be in place to perform these actions across the metastore?
- A. Account Admin, because account admins can only create metastores but cannot change ownership of catalogs.
- B. Metastore Admin, because metastore admins can transfer ownership and manage privileges across all metastore objects, including shares and recipients.
- C. Workspace Admin, because workspace admins can transfer ownership of any Unity Catalog object.
- D. Catalog Owner, because catalog owners can transfer any object in any catalog in the metastore.
정답:B
질문 # 126
When monitoring a complex workload, being able to see the query plan is critical to understanding what the workload is doing. Where can the visualization of the query plan be found?
- A. In the Query Profiler, under Query Source
- B. In the Spart UI, under the Jobs tab
- C. In the Query Profiler, under the Stages tab
- D. In the Spark UI, under the SQL/DataFrame tab
정답:D
설명:
The Spark UI provides detailed visibility into how queries are executed. The SQL/DataFrame tab displays the logical and physical query plans, allowing engineers to visualize execution details and understand how the workload is processed across stages and operators.
질문 # 127
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs UI. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
- A. Can Run
- B. Can Read
- C. No permissions
- D. Can Edit
- E. Can Manage
정답:B
질문 # 128
......
KoreaDumps는 Databricks인증관련덤프를 제공하는 최고의 업체입니다, 덤프들은 KoreaDumps의 베터랑의 전문가들이 오랜 풍부한 경험과 Certified-Data-Engineer-Professional지식으로 만들어낸 최고의 제품입니다. 그리고 우리는 온라인무료 서비스도 제공되어 제일 빠른 시간에 소통 상담이 가능합니다.
Certified-Data-Engineer-Professional시험덤프자료: https://www.koreadumps.com/Certified-Data-Engineer-Professional_exam-braindumps.html
- 최신 업데이트버전 Certified-Data-Engineer-Professional테스트자료 공부문제 👽 【 www.dumptop.com 】에서 검색만 하면➠ Certified-Data-Engineer-Professional 🠰를 무료로 다운로드할 수 있습니다Certified-Data-Engineer-Professional퍼펙트 인증덤프
- Certified-Data-Engineer-Professional덤프샘플문제 다운 😛 Certified-Data-Engineer-Professional합격보장 가능 덤프자료 🎨 Certified-Data-Engineer-Professional덤프샘플문제 다운 🔘 검색만 하면▷ www.itdumpskr.com ◁에서⇛ Certified-Data-Engineer-Professional ⇚무료 다운로드Certified-Data-Engineer-Professional덤프내용
- 최신 Certified-Data-Engineer-Professional시험덤프, Certified-Data-Engineer-Professional시험자료, 최강 Certified-Data-Engineer-Professional 인증시험문제 🙊 검색만 하면《 www.dumptop.com 》에서▶ Certified-Data-Engineer-Professional ◀무료 다운로드Certified-Data-Engineer-Professional최고덤프샘플
- Certified-Data-Engineer-Professional인기공부자료 ⏺ Certified-Data-Engineer-Professional덤프샘플문제 다운 ⬜ Certified-Data-Engineer-Professional높은 통과율 덤프샘플 다운 🅰 지금⮆ www.itdumpskr.com ⮄에서《 Certified-Data-Engineer-Professional 》를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional합격보장 가능 덤프자료
- 시험패스 가능한 Certified-Data-Engineer-Professional테스트자료 덤프 최신문제 🌸 ➤ Certified-Data-Engineer-Professional ⮘를 무료로 다운로드하려면➤ www.koreadumps.com ⮘웹사이트를 입력하세요Certified-Data-Engineer-Professional시험대비 최신 덤프자료
- Certified-Data-Engineer-Professional퍼펙트 인증덤프 🔧 Certified-Data-Engineer-Professional최고덤프샘플 💥 Certified-Data-Engineer-Professional최신 기출자료 🦲 《 www.itdumpskr.com 》에서《 Certified-Data-Engineer-Professional 》를 검색하고 무료 다운로드 받기Certified-Data-Engineer-Professional인증덤프데모문제
- Certified-Data-Engineer-Professional인증덤프데모문제 📪 Certified-Data-Engineer-Professional유효한 시험덤프 😢 Certified-Data-Engineer-Professional시험대비 최신 덤프자료 🍬 ⇛ www.pass4test.net ⇚을 통해 쉽게{ Certified-Data-Engineer-Professional }무료 다운로드 받기Certified-Data-Engineer-Professional높은 통과율 시험대비 공부자료
- 최신 Certified-Data-Engineer-Professional시험덤프, Certified-Data-Engineer-Professional시험자료, 최강 Certified-Data-Engineer-Professional 인증시험문제 🏝 [ www.itdumpskr.com ]웹사이트에서➠ Certified-Data-Engineer-Professional 🠰를 열고 검색하여 무료 다운로드Certified-Data-Engineer-Professional시험대비 최신 덤프자료
- 최신 Certified-Data-Engineer-Professional테스트자료 인증덤프문제 📻 ✔ Certified-Data-Engineer-Professional ️✔️를 무료로 다운로드하려면【 www.dumptop.com 】웹사이트를 입력하세요Certified-Data-Engineer-Professional적중율 높은 시험덤프자료
- 최신 Certified-Data-Engineer-Professional테스트자료 인증덤프 데모문제 다운 💢 시험 자료를 무료로 다운로드하려면➤ www.itdumpskr.com ⮘을 통해( Certified-Data-Engineer-Professional )를 검색하십시오Certified-Data-Engineer-Professional시험대비 최신 덤프자료
- Certified-Data-Engineer-Professional유효한 시험덤프 🎸 Certified-Data-Engineer-Professional최신 기출자료 🖌 Certified-Data-Engineer-Professional적중율 높은 인증덤프자료 🏚 ⮆ www.koreadumps.com ⮄을(를) 열고⇛ Certified-Data-Engineer-Professional ⇚를 입력하고 무료 다운로드를 받으십시오Certified-Data-Engineer-Professional최고덤프샘플
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes