Itexamdump 3V0-25.25 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1-toMnPmBlXl3N33ZaOGYn3O1OzWor8_7
VMware인증3V0-25.25시험덤프공부자료는Itexamdump제품으로 가시면 자격증취득이 쉬워집니다. Itexamdump에서 출시한 VMware인증3V0-25.25덤프는 이미 사용한 분들에게 많은 호평을 받아왔습니다. 시험적중율 최고에 많은 공부가 되었다고 희소식을 전해올때마다 Itexamdump는 더욱 완벽한VMware인증3V0-25.25시험덤프공부자료로 수정하고기 위해 최선을 다해왔습니다. 최고품질으VMware인증3V0-25.25덤프공부자료는Itexamdump에서만 찾아볼수 있습니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
| 주제 5 |
|
인재도 많고 경쟁도 많은 이 사회에, 업계인재들은 인기가 아주 많습니다.하지만 팽팽한 경쟁률도 무시할 수 없습니다.많은 VMware인재들도 어려운 인증시험을 패스하여 자기만의 자리를 지키고 있습니다.우리Itexamdump에서는 마침 전문적으로 이러한 VMware인사들에게 편리하게 시험을 3V0-25.25패스할수 있도록 유용한 자료들을 제공하고 있습니다.
질문 # 23
An NSX Manager cluster has failed. The administrator deployed a new NSX Manager using the latest version and attempted to restore from a backup, but the restore operation failed. What would an administrator do to recover the cluster?
정답:C
설명:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
A critical requirement for the backup and restore process inVMware NSX(and by extension, VCF) is version parity. The NSX Manager backup contains the database schema, configuration files, and state information specific to the version of the software that was running at the time the backup was taken.
When performing a restore into a "clean" environment, the NSX documentation explicitly states that the target NSX Manager appliancemust be of the exact same build versionas the appliance that generated the backup.
If an administrator attempts to restore a backup from version 4.1.x onto a newly deployed manager running version 4.2.x or 9.0 (as implies by "latest version"), the restore process will fail because the database schema of the newer version is incompatible with the older data structure.
In aVCF environment, whileSDDC Manager(Option B) handles the lifecycle and replacement of failed nodes, the actual "Restore from Backup" workflow is an NSX-native operation. If the entire cluster is lost, the recovery procedure involves:
* Identifying the build number from the backup metadata.
* Deploying a single "Discovery" node of that exact build.
* Pointing that node to the backup repository (SFTP/FTP).
* Executing the restore.
Once the primary node is restored to the correct version, the administrator can then add additional nodes to reform the cluster. Attempting to use the API (Option C) or changing the passphrase (Option A) will not bypass the fundamental requirement for version alignment between the backup file and the installed binary.
질문 # 24
An administrator is responsible for managing a VMware Cloud Foundation (VCF) Private Cloud consisting of a single VCF Fleet with a single Workload Domain.
The administrator has been tasked with configuring NSX to support the new Virtual Desktop Infrastructure (VDI) solution that allows users to securely access a mainframe- based application located on the physical network. The VDI solution will use a dedicate DHCP solution for each of the the desktop pool segments and static addresses for all VDI management components.
The administrator completes the following steps towards configuring DHCP:
1. Creates a new tier-1 gateway (vdi-tier-1) and links it to the tier-0 gateway (gw-tier-0).
2. Creates one new segment for vdi management (vdi-seg-01) and connects it to vdi-tier-1.
3. Creates two new segments for virtual desktops (vdi-seg-02 and vdi-seg-03) and connects them to vdi-tier-1.
Drag and drop the six steps from the list of Possible Steps on the left and place them in order in to the Solution Steps. (Choose six.)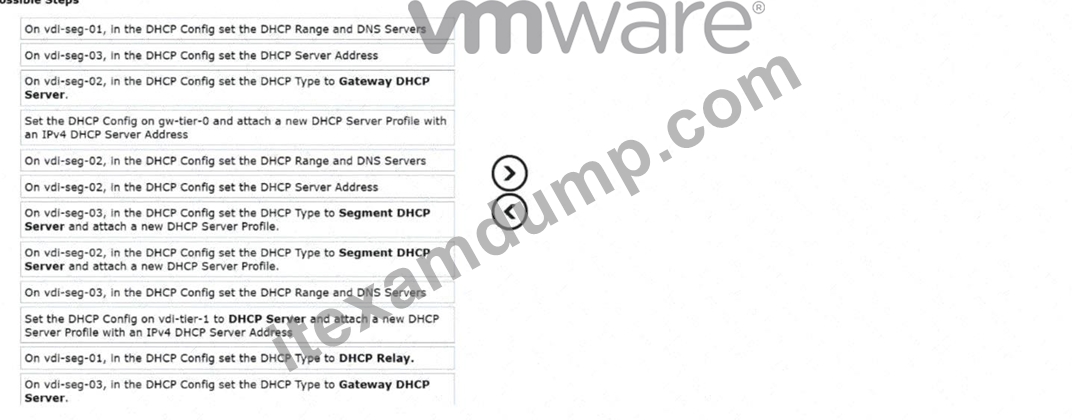
정답:
설명: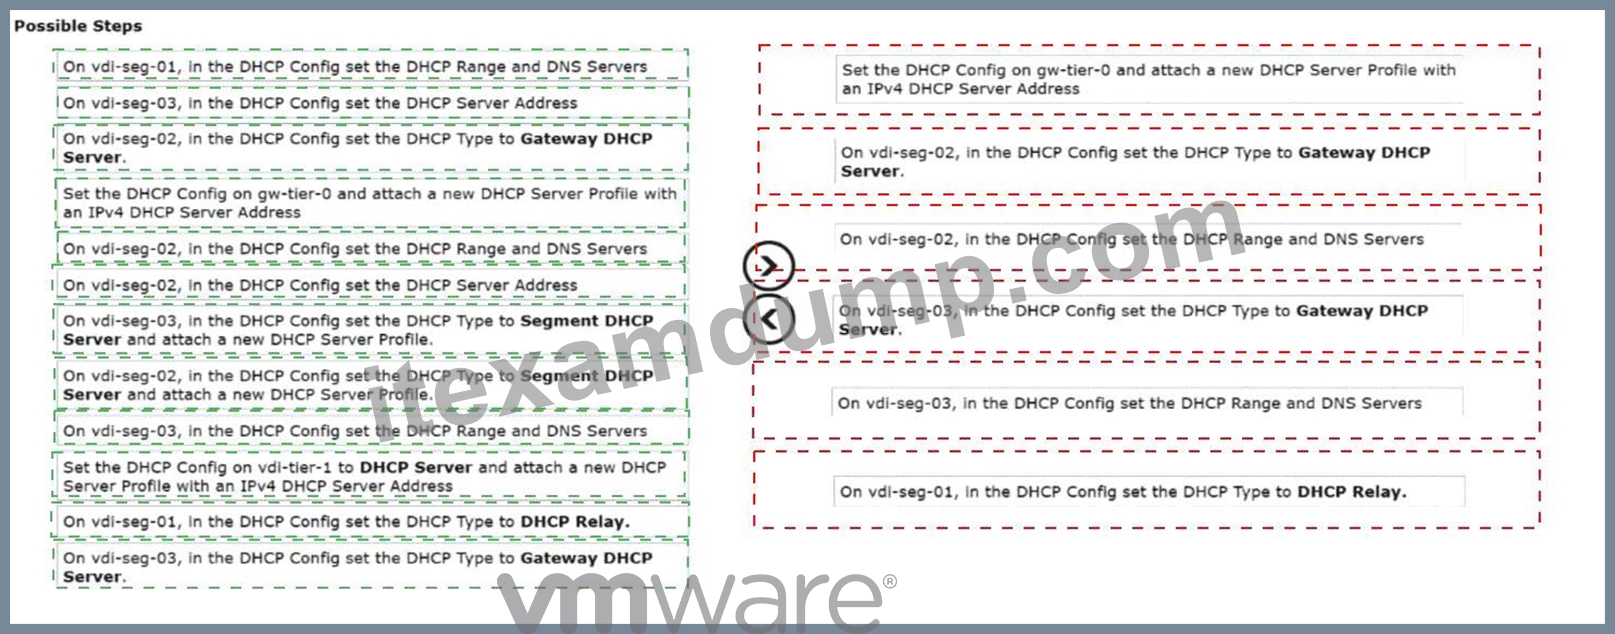
Explanation:
For the VDI solution requiring dedicated DHCP for desktop pool segments and static addresses for management components, the correct sequence of steps to configure DHCP is as follows:
* Set the DHCP Config on vdi-tier-1 to DHCP Server and attach a new DHCP Server Profile with an IPv4 DHCP Server Address.This establishes the Tier-1 gateway as the local DHCP service provider for its attached segments.
* On vdi-seg-02, in the DHCP Config set the DHCP Type to Gateway DHCP Server.This instructs the segment to use the DHCP server service configured on its parent Tier-1 gateway.
* On vdi-seg-02, in the DHCP Config set the DHCP Range and DNS Servers.Defines the specific IP pool and network settings for the first desktop pool.
* On vdi-seg-03, in the DHCP Config set the DHCP Type to Gateway DHCP Server.Instructs the second desktop segment to also leverage the Tier-1 DHCP service.
* On vdi-seg-03, in the DHCP Config set the DHCP Range and DNS Servers.Defines the IP pool for the second desktop pool.
* On vdi-seg-01, in the DHCP Config set the DHCP Type to DHCP Relay.Since management components use static addresses provided by an external mainframe-based solution or dedicated physical infrastructure, a relay is used rather than a local server to ensure proper network isolation and policy enforcement for the physical mainframe application.
질문 # 25
An administrator has noticed that both the active and standby Global Managers have gone offline.
What is the correct sequence of events to restore the Global Managers?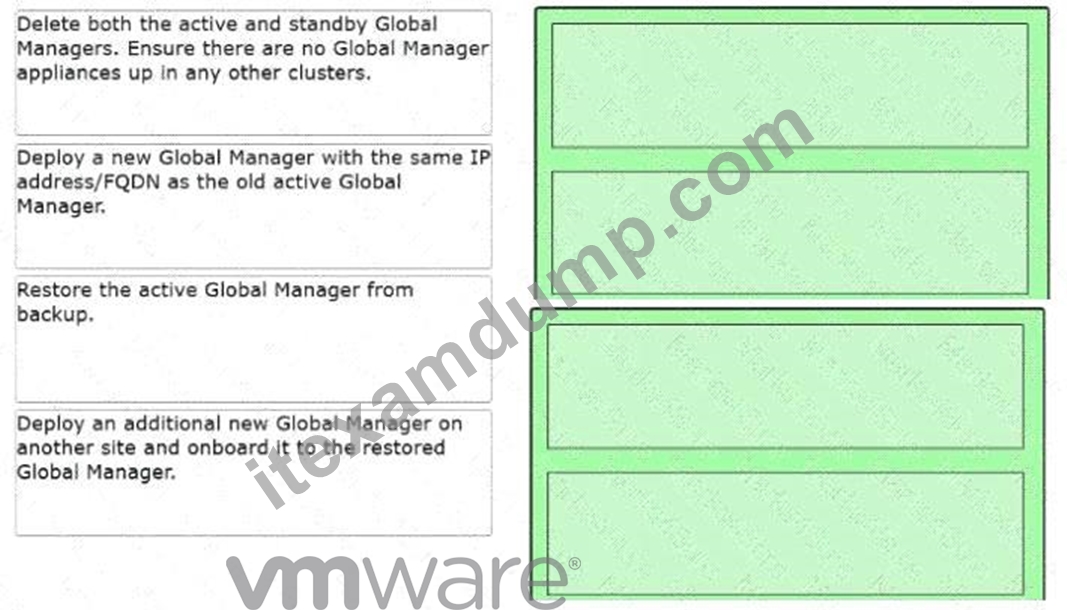
정답:
설명: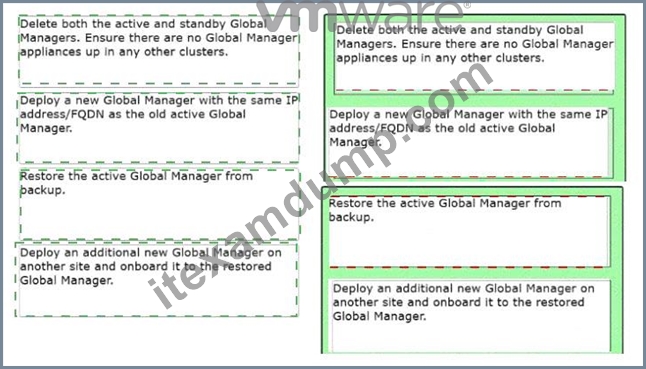
Explanation:
* Step 1: Delete both the active and standby Global Managers. Ensure there are no Global Manager appliances up in any other clusters.
* Step 2: Deploy a new Global Manager with the same IP address/FQDN as the old active Global Manager.
* Step 3: Restore the active Global Manager from backup.
* Step 4: Deploy an additional new Global Manager on another site and onboard it to the restored Global Manager.
In aVMware Cloud Foundationmulti-site deployment usingNSX Federation, the Global Manager (GM) manages the global networking configuration across multiple sites. If the entire GM cluster (Active and Standby) fails, the following architectural principles apply:
* Cleanup (Step 1):Before initiating a restore, the environment must be "cleaned." If old, failed VMs remain in the inventory or on the hosts, they can cause IP address conflicts or UUID mismatches during the deployment of the new appliance. You must ensure the management plane is clear of the original failed nodes.
* Identity Consistency (Step 2):When restoring an NSX appliance (Local or Global) from backup, the new appliancemustbe deployed with the exact sameIP address and FQDNas the original active node.
This is critical because the existing Local Managers (LMs) at each site already have established thumbprints and communication channels tied to that specific identity.
* The Restore Operation (Step 3):Once the "seed" appliance is deployed, the restore process is triggered through the NSX Manager UI/API. This process re-populates the database with the global segments, firewall rules, and Tier-0/Tier-1 configurations.
* Restoring Redundancy (Step 4):The backup only contains the configuration of the cluster. It does not
"restore" the standby VM itself. High Availability (HA) must be manually re-established by deploying a second GM appliance at the secondary site and joining it to the newly restored Global Manager cluster to act as the standby.
질문 # 26
An administrator is troubleshooting an issue where workloads connected to a Tier-1 Gateway named T1-App can no longer reach external North/South destinations.
* The Tier-1 is connected to an Active/Standby Tier-0 Gateway named T0-Prod.
Symptoms observed:
* VMs on segments attached to T1-App can ping each other.
* VMs on T1-App cannot reach any external IP outside T0-Prod.
* From a VM on the segment, ping to the T1-App Distributed Router (DR) IP succeeds.
* Ping from the VM to the T1-App Service Router (SR) fails.
* The Edge cluster hosting the T1-App SR shows both Edge nodes Up and Healthy.
* No failover has occurred - the same Edge node is still shown as Active for T1-App.
What is the most likely cause of this issue?
정답:B
설명:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In theNSXmulti-tier routing architecture used by VCF, aTier-1 Gatewayis composed of two primary components: theDistributed Router (DR)and theService Router (SR). The DR runs as a kernel module on every ESXi host in the transport zone, facilitating East-West traffic. The SR resides on the NSX Edge nodes and provides centralized services like North-South connectivity and stateful services.
Communication between the DR (on the ESXi host) and the SR (on the Edge node) occurs over a hidden internal segment known as theRouter Link. This link is encapsulated inGenevejust like VM-to-VM traffic.
When a VM attempts to reach an external destination, the packet is first routed by the DR on the local host.
The DR then encapsulates the packet and sends it across the overlay to the TEP (Tunnel Endpoint) of the Edge node hosting the SR.
If theMTU (Maximum Transmission Unit)is misconfigured on the physical network or the virtual switches, large encapsulated packets will be dropped. However, small packets (like pings between VMs on the same host) might still succeed. In this scenario, the fact that the VM can ping the local DR butcannot reach the SR
-and therefore cannot reach external networks-points to a failure in the transport between the host and the Edge.
If the Geneve-encapsulated packet containing the ping request to the SR's internal interface exceeds the physical network's MTU, it will fail. Since VCF 5.x/9.0 requires a minimum MTU of1600(ideally9000) for the overlay to account for the Geneve overhead, a mismatch anywhere in the fabric will break the DR-to-SR
"backplane" communication. This prevents the Tier-1 from passing any traffic to its Tier-0 uplink, effectively isolating the workloads from North-South traffic.
질문 # 27
An administrator has observed an NSX Local Manager (LM) outage at the secondary Site. However, the NSX Global Manager (GM) in secondary Site remains operational. What happens to data plane operations and policy enforcement at the secondary site?
정답:C
설명:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
The architecture ofNSX Federationwithin a VCF Multi-Site design is built upon a separation of theControl Planeand theData Plane. This "decoupled" architecture ensures high availability and resiliency even when management components become unavailable.
In NSX Federation, theGlobal Manager (GM)handles the configuration of objects that span multiple locations, while theLocal Manager (LM)is responsible for pushing those configurations down to the local Transport Nodes (ESXi hosts and Edges) within its specific site. When a configuration is pushed, the Local Manager communicates with theCentral Control Plane (CCP)and subsequently theLocal Control Plane (LCP)on the hosts.
If an NSX Local Manager goes offline, the "Management Plane" for that site is lost. This means no new segments, routers, or firewall rules can be created or modified at that site. However, the existing configuration is already programmed into theData Plane(the kernels of the ESXi hosts and the DPDK process of the Edge nodes).
According to VMware's "NSX Multi-Location Design Guide," the data plane remains fully operational during a Management Plane outage. Existing VMs will continue to communicate, BGP sessions on the Edges will remain established, and Distributed Firewall (DFW) rules will continue to be enforced based on the last known good configuration state cached on the hosts. The data plane does not require constant heartbeats from the Local Manager to forward traffic. Therefore, operations continue normally "headless" until the LM is restored and can resume synchronization with the Global Manager and local hosts. Failover to a primary site (Option D) is only necessary if the actual data plane (hosts/storage) fails, not just the management components.
질문 # 28
......
우리는 여러분이 시험패스는 물론 또 일년무료 업데이트서비스를 제공합니다.만약 시험에서 실패했다면 우리는 덤프비용전액 환불을 약속 드립니다.하지만 이런 일은 없을 것입니다.우리는 우리덤프로 100%시험패스에 자신이 있습니다. 여러분은 먼저 우리 Itexamdump사이트에서 제공되는VMware인증3V0-25.25시험덤프의 일부분인 데모 즉 문제와 답을 다운받으셔서 체험해보실 수 잇습니다.
3V0-25.25덤프최신버전: https://www.itexamdump.com/3V0-25.25.html
참고: Itexamdump에서 Google Drive로 공유하는 무료 2026 VMware 3V0-25.25 시험 문제집이 있습니다: https://drive.google.com/open?id=1-toMnPmBlXl3N33ZaOGYn3O1OzWor8_7