Pass Your Google Associate-Data-Practitioner Exam with Confidence

What's more, part of that FreePdfDump Associate-Data-Practitioner dumps now are free: https://drive.google.com/open?id=1_Hqo2k8OIbdRE8tw2u9BPiHJ5du_4sF9
Being anxious for the exam ahead of you? Have a look of our Associate-Data-Practitioner practice materials please. Presiding over the line of Associate-Data-Practitioner practice materials over ten years, our experts are proficient as elites who made our Associate-Data-Practitioner practice materials, and it is their job to officiate the routines of offering help for you. All points are predominantly related with the exam ahead of you. Every page is full of well-turned words for your reference related wholly with the real exam.
Google Associate-Data-Practitioner Exam Overview:
| Certification Vendor: | Google Cloud |
|---|
| Exam Name: | Google Cloud Certified - Associate Data Practitioner |
|---|
| Exam Number: | Associate-Data-Practitioner |
|---|
| Exam Price: | USD 125 |
|---|
| Exam Format: | Multiple select, Multiple choice |
|---|
| Real Exam Qty: | 50-60 |
|---|
| Available Languages: | English, French, Portuguese (Brazil), Spanish, Japanese, German |
|---|
| Exam Duration: | 90 minutes |
|---|
| Certificate Validity Period: | 3 years |
|---|
| Related Certifications: | Google Cloud Professional Data Engineer
Google Cloud Associate Cloud Engineer
Google Cloud Digital Leader |
|---|
| Recommended Training: | Google Cloud Skills Boost |
|---|
| Exam Registration: | Google Cloud Certification Registration |
|---|
| Sample Questions: | Google Associate-Data-Practitioner Sample Questions |
|---|
| Exam Way: | Online proctored exam or test center delivery |
|---|
| Pre Condition: | No formal prerequisites required, but familiarity with basic data concepts and Google Cloud services is recommended. |
|---|
| Official Syllabus URL: | https://cloud.google.com/certification |
|---|
>> Associate-Data-Practitioner Certificate Exam <<
Associate-Data-Practitioner Reliable Braindumps Sheet & Associate-Data-Practitioner Real Brain Dumps
Google certification Associate-Data-Practitioner exams has become more and more popular in the fiercely competitive IT industry. Although more and more people sign up to attend this examination of, the official did not reduce its difficulty and it is still difficult to pass the exam. After all, this is an authoritative test to inspect the computer professional knowledge and information technology ability. In order to pass the Google Certification Associate-Data-Practitioner Exam, generally, many people need to spend a lot of time and effort to review.
| Topic | Details |
|---|
| Topic 1 | - Data Management: This domain measures the skills of Google Database Administrators in configuring access control and governance. Candidates will establish principles of least privilege access using Identity and Access Management (IAM) and compare methods of access control for Cloud Storage. They will also configure lifecycle management rules to manage data retention effectively. A critical skill measured is ensuring proper access control to sensitive data within Google Cloud services
|
| Topic 2 | - Data Analysis and Presentation: This domain assesses the competencies of Data Analysts in identifying data trends, patterns, and insights using BigQuery and Jupyter notebooks. Candidates will define and execute SQL queries to generate reports and analyze data for business questions.| Data Pipeline Orchestration: This section targets Data Analysts and focuses on designing and implementing simple data pipelines. Candidates will select appropriate data transformation tools based on business needs and evaluate use cases for ELT versus ETL.
|
| Topic 3 | - Data Preparation and Ingestion: This section of the exam measures the skills of Google Cloud Engineers and covers the preparation and processing of data. Candidates will differentiate between various data manipulation methodologies such as ETL, ELT, and ETLT. They will choose appropriate data transfer tools, assess data quality, and conduct data cleaning using tools like Cloud Data Fusion and BigQuery. A key skill measured is effectively assessing data quality before ingestion.
|
Google Cloud Associate Data Practitioner Sample Questions (Q30-Q35):
NEW QUESTION # 30
You are predicting customer churn for a subscription-based service. You have a 50 PB historical customer dataset in BigQuery that includes demographics, subscription information, and engagement metrics. You want to build a churn prediction model with minimal overhead. You want to follow the Google-recommended approach. What should you do?
- A. Create a Looker dashboard that is connected to BigQuery. Use LookML to predict churn.
- B. Use the BigQuery Python client library in a Jupyter notebook to query and preprocess the data in BigQuery. Use the CREATE MODEL statement in BigQueryML to train the churn prediction model.
- C. Use Dataproc to create a Spark cluster. Use the Spark MLlib within the cluster to build the churn prediction model.
- D. Export the data from BigQuery to a local machine. Use scikit-learn in a Jupyter notebook to build the churn prediction model.
Answer: B
Explanation:
Using the BigQuery Python client library to query and preprocess data directly in BigQuery and then leveraging BigQueryML to train the churn prediction model is the Google-recommended approach for this scenario. BigQueryML allows you to build machine learning models directly within BigQuery using SQL, eliminating the need to export data or manage additional infrastructure. This minimizes overhead, scales effectively for a dataset as large as 50 PB, and simplifies the end-to-end process of building and training the churn prediction model.
NEW QUESTION # 31
You are responsible for managing Cloud Storage buckets for a research company. Your company has well- defined data tiering and retention rules. You need to optimize storage costs while achieving your data retention needs. What should you do?
- A. Configure a lifecycle management policy on each bucket to downgrade the storage class and remove objects based on age.
- B. Configure the buckets to use the Autoclass feature.
- C. Configure the buckets to use the Standard storage class and enable Object Versioning.
- D. Configure the buckets to use the Archive storage class.
Answer: A
Explanation:
Configuring alifecycle management policyon each Cloud Storage bucket allows you to automatically transition objects to lower-cost storage classes (such as Nearline, Coldline, or Archive) based on their age or other criteria. Additionally, the policy can automate the removal of objects once they are no longer needed, ensuring compliance with retention rules and optimizing storage costs. This approach aligns well with well- defined data tiering and retention needs, providing cost efficiency and automation.
Extract from Google Documentation: From "Object Lifecycle Management" (https://cloud.google.com
/storage/docs/lifecycle):"Use lifecycle management policies to automatically transition objects to lower-cost storage classes (e.g., Nearline, Coldline) and delete them based on age, optimizing costs according to your specific tiering and retention requirements."
NEW QUESTION # 32
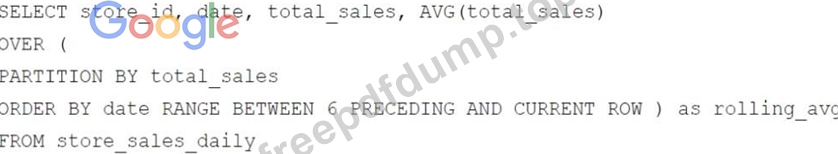
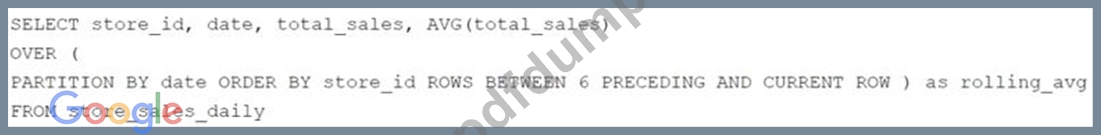
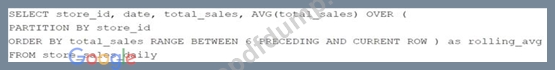
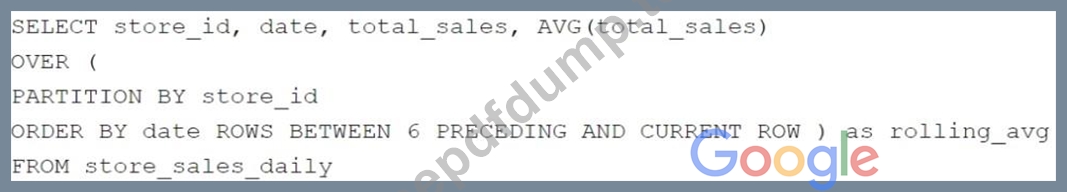
Your company has several retail locations. Your company tracks the total number of sales made at each location each day. You want to use SQL to calculate the weekly moving average of sales by location to identify trends for each store. Which query should you use?
Answer: D
Explanation:
To calculate the weekly moving average of sales by location:
* The query must group bystore_id(partitioning the calculation by each store).
* TheORDER BY dateensures the sales are evaluated chronologically.
* TheROWS BETWEEN 6 PRECEDING AND CURRENT ROWspecifies a rolling window of 7 rows (1 week if each row represents daily data).
* TheAVG(total_sales)computes the average sales over the defined rolling window.
Chosen querymeets these requirements:
PARTITION BY store_idgroups the calculation by each store.
ORDER BY dateorders the rows correctly for the rolling average.
ROWS BETWEEN 6 PRECEDING AND CURRENT ROWensures the 7-day moving average.
Extract from Google Documentation: From "Analytic Functions in BigQuery" (https://cloud.google.com
/bigquery/docs/reference/standard-sql/analytic-function-concepts):"Use ROWS BETWEEN n PRECEDING AND CURRENT ROW with ORDER BY a time column to compute moving averages over a fixed number of rows, such as a 7-day window, partitioned by a grouping key like store_id."
NEW QUESTION # 33
You have a Cloud SQL for PostgreSQL database that stores sensitive historical financial data. You need to ensure that the data is uncorrupted and recoverable in the event that the primary region is destroyed. The data is valuable, so you need to prioritize recovery point objective (RPO) over recovery time objective (RTO). You want to recommend a solution that minimizes latency for primary read and write operations. What should you do?
- A. Configure the Cloud SQL for PostgreSQL instance for regional availability (HA) with synchronous replication to a secondary instance in a different zone.
- B. Configure the Cloud SQL for PostgreSQL instance for regional availability (HA) with asynchronous replication to a secondary instance in a different region.
- C. Configure the Cloud SQL for PostgreSQL instance for multi-region backup locations.
- D. Configure the Cloud SQL for PostgreSQL instance for regional availability (HA). Back up the Cloud SQL for PostgreSQL database hourly to a Cloud Storage bucket in a different region.
Answer: A
Explanation:
Comprehensive and Detailed in Depth Explanation:
Why D is correct:Synchronous replication ensures that data is written to both the primary and secondary instances at the same time, minimizing data loss (RPO).
Regional availability (HA) within different zones provides redundancy within the same region, minimizing latency.
Why other options are incorrect:A: Asynchronous replication has a potential for data loss.
B: Multiregion backups are for disaster recovery, not minimizing latency.
C: Hourly backups do not provide the lowest possible RPO.
NEW QUESTION # 34
You work for a home insurance company. You are frequently asked to create and save risk reports with charts for specific areas using a publicly available storm event dataset. You want to be able to quickly create and re-run risk reports when new data becomes available. What should you do?
- A. Reference and query the storm event dataset using SQL in BigQuery Studio. Export the results to Google Sheets, and use cell data in the worksheets to create charts.
- B. Copy the storm event dataset into your BigQuery project. Use BigQuery Studio to query and visualize the data in Looker Studio.
- C. Reference and query the storm event dataset using SQL in a Colab Enterprise notebook. Display the table results and document with Markdown, and use Matplotlib to create charts.
- D. Export the storm event dataset as a CSV file. Import the file to Google Sheets, and use cell data in the worksheets to create charts.
Answer: B
Explanation:
Copying the storm event dataset into your BigQuery project and using BigQuery Studio to query and visualize the data in Looker Studio is the best approach. This solution allows you to create reusable and automated workflows for generating risk reports. BigQuery handles the querying efficiently, and Looker Studio provides powerful tools for creating and sharing dynamic charts and dashboards. This setup ensures that reports can be easily re-run with updated data, minimizing manual effort and providing a scalable, interactive solution for visualizing risk reports.
NEW QUESTION # 35
......
Associate-Data-Practitioner Reliable Braindumps Sheet: https://www.freepdfdump.top/Associate-Data-Practitioner-valid-torrent.html
- 2026 High Hit-Rate Associate-Data-Practitioner Certificate Exam | Google Cloud Associate Data Practitioner 100% Free Reliable Braindumps Sheet 😏 Search for ( Associate-Data-Practitioner ) on 《 www.examcollectionpass.com 》 immediately to obtain a free download 🕍Test Associate-Data-Practitioner Tutorials
- Latest Associate-Data-Practitioner Exam Objectives 👳 Valid Associate-Data-Practitioner Vce Dumps 🐭 Latest Associate-Data-Practitioner Test Materials 😚 Search for 【 Associate-Data-Practitioner 】 and download it for free on { www.pdfvce.com } website 🍧Valid Associate-Data-Practitioner Torrent
- 2026 High Hit-Rate Associate-Data-Practitioner Certificate Exam | Google Cloud Associate Data Practitioner 100% Free Reliable Braindumps Sheet 🪓 Simply search for ▷ Associate-Data-Practitioner ◁ for free download on ⏩ www.vce4dumps.com ⏪ 🧔Test Associate-Data-Practitioner Lab Questions
- Valid Associate-Data-Practitioner Vce Dumps 📝 Valid Associate-Data-Practitioner Torrent 🦈 Associate-Data-Practitioner Valid Exam Topics 🍓 Search for ➥ Associate-Data-Practitioner 🡄 and download it for free on 「 www.pdfvce.com 」 website 👷Associate-Data-Practitioner Valid Exam Topics
- Pass Guaranteed Quiz Associate-Data-Practitioner - Trustable Google Cloud Associate Data Practitioner Certificate Exam 😑 Search for 「 Associate-Data-Practitioner 」 and obtain a free download on ➥ www.prepawayexam.com 🡄 🧢Latest Associate-Data-Practitioner Exam Objectives
- By Achieving the Google Associate-Data-Practitioner Certification You will Get the Job 🏏 Search for “ Associate-Data-Practitioner ” and download exam materials for free through ➤ www.pdfvce.com ⮘ 🤦Certification Associate-Data-Practitioner Exam Infor
- Valid Associate-Data-Practitioner Test Pattern 👦 Associate-Data-Practitioner Valid Exam Topics 🚚 Latest Associate-Data-Practitioner Cram Materials 🛹 Enter ➤ www.troytecdumps.com ⮘ and search for 《 Associate-Data-Practitioner 》 to download for free 🖱Latest Associate-Data-Practitioner Exam Objectives
- Why Practicing With Pass4Future Google Associate-Data-Practitioner Dumps is Necessary? 🦺 Immediately open ➡ www.pdfvce.com ️⬅️ and search for ( Associate-Data-Practitioner ) to obtain a free download 💄Valid Associate-Data-Practitioner Test Sims
- Quiz Google Marvelous Associate-Data-Practitioner Certificate Exam 🍄 Easily obtain ➽ Associate-Data-Practitioner 🢪 for free download through 「 www.examcollectionpass.com 」 🍻Test Associate-Data-Practitioner Lab Questions
- Certification Associate-Data-Practitioner Exam Infor 🔅 Latest Associate-Data-Practitioner Exam Fee 🏢 Associate-Data-Practitioner Reliable Exam Question 🧂 Open ▷ www.pdfvce.com ◁ enter ⇛ Associate-Data-Practitioner ⇚ and obtain a free download 🍚Latest Associate-Data-Practitioner Exam Objectives
- Latest Associate-Data-Practitioner Exam Tips 🧏 Latest Associate-Data-Practitioner Exam Fee 🦺 Latest Associate-Data-Practitioner Test Materials 🔂 Search for ➽ Associate-Data-Practitioner 🢪 and obtain a free download on ✔ www.pdfdumps.com ️✔️ 📇Dumps Associate-Data-Practitioner Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, divisionmidway.org, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that FreePdfDump Associate-Data-Practitioner dumps now are free: https://drive.google.com/open?id=1_Hqo2k8OIbdRE8tw2u9BPiHJ5du_4sF9