New Databricks-Certified-Data-Engineer-Professional Test Prep, Training Databricks-Certified-Data-Engineer-Professional Online

Propulsion occurs when using our Databricks-Certified-Data-Engineer-Professional preparation quiz. They can even broaden amplitude of your horizon in this line. Of course, knowledge will accrue to you from our Databricks-Certified-Data-Engineer-Professional training guide. There is no inextricably problem within our Databricks-Certified-Data-Engineer-Professional Learning Materials. Motivated by them downloaded from our website, more than 98 percent of clients conquered the difficulties. So can you as long as you buy our Databricks-Certified-Data-Engineer-Professional exam braindumps.
| Section | Weight | Objectives |
|---|
| Topic 1: Databricks Lakehouse Platform | 24% | - Lakehouse Architecture
- Unity Catalog
- Delta Lake
- Data Management
|
| Topic 2: Data Processing | 28% | - Structured Streaming
- ETL Pipelines
- Spark SQL
- Data Transformation
|
| Topic 3: Data Quality and Governance | 12% | - Data Lineage
- Governance
- Data Quality
|
| Topic 4: Data Modeling and Storage | 20% | - Data Modeling
- File Formats
- Storage Optimization
|
| Topic 5: Monitoring and Troubleshooting | 16% | - Troubleshooting
- Monitoring
- Performance Optimization
|
>> New Databricks-Certified-Data-Engineer-Professional Test Prep <<
Free Demo: 100% Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions
When you have a lot of eletronic devices, you definitly will figure out the way to study and prepare your Databricks-Certified-Data-Engineer-Professional exam with them. It is so cool even to think about it. As we all know that the electronic equipment provides the convenience out of your imagination.With our APP online version of our Databricks-Certified-Data-Engineer-Professionalpractice materials, your attempt will come true. Our Databricks-Certified-Data-Engineer-Professional exam dumps can be quickly downloaded to the eletronic devices.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q204-Q209):
NEW QUESTION # 204
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance. How should the data engineer create the patient_encounters table?
- A. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, schedule jobs to run OPTIMIZE and VACUUM commands daily to achieve best performance.
- B. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
- C. Create an external table in Unity Catalog, specifying an S3 location for the data files. Enable predictive optimization through table properties, and configure Unity Catalog permissions for access controls.
- D. Create a managed table in Hive Metastore. Configure Hive Metastore permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
Answer: B
Explanation:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog.
Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
NEW QUESTION # 205
A DLT pipeline includes the following streaming tables:
Raw_lot ingest raw device measurement data from a heart rate tracking device.
Bpm_stats incrementally computes user statistics based on BPM measurements from raw_lot.
How can the data engineer configure this pipeline to be able to retain manually deleted or updated records in the raw_iot table while recomputing the downstream table when a pipeline update is run?
- A. Set the SkipChangeCommits flag to true raw_lot
- B. Set the skipChangeCommits flag to true on bpm_stats
- C. Set the pipelines, reset, allowed property to false on raw_iot
- D. Set the pipelines, reset, allowed property to false on bpm_stats
Answer: C
Explanation:
In Databricks Lakehouse, to retain manually deleted or updated records in the raw_iot table while recomputing downstream tables when a pipeline update is run, the property pipelines.reset.allowed should be set to false. This property prevents the system from resetting the state of the table, which includes the removal of the history of changes, during a pipeline update. By keeping this property as false, any changes to the raw_iot table, including manual deletes or updates, are retained, and recomputation of downstream tables, such as bpm_stats, can occur with the full history of data changes intact.
NEW QUESTION # 206
Which distribution does Databricks support for installing custom Python code packages?
- A. nom
- B. sbt
- C. Wheels
- D. jars
- E. CRAN
- F. CRAM
Answer: A
Explanation:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from Explanation:
https://learn.microsoft.com/en-us/azure/databricks/workflows/jobs/how-to/use-python-wheels-in- workflows
NEW QUESTION # 207
Which of the following is true of Delta Lake and the Lakehouse?
- A. Because Parquet compresses data row by row. strings will only be compressed when a character is repeated multiple times.
- B. Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.
- C. Z-order can only be applied to numeric values stored in Delta Lake tables
- D. Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.
- E. Delta Lake automatically collects statistics on the first 32 columns of each table which are leveraged in data skipping based on query filters.
Answer: E
Explanation:
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters. Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer. By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan. This can significantly improve the query performance and reduce the I/O cost.
NEW QUESTION # 208
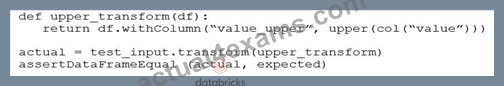
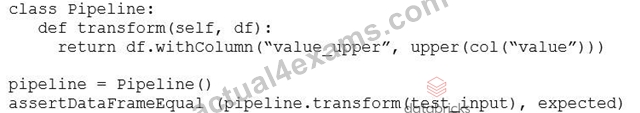
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer: A
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 209
......
Our clients come from all around the world and our company sends the products to them quickly. The clients only need to choose the version of the product, fill in the correct mails and pay for our Databricks-Certified-Data-Engineer-Professional study materials. Then they will receive our mails in 5-10 minutes. Once the clients click on the links they can use our Databricks-Certified-Data-Engineer-Professional Study Materials immediately. If the clients can’t receive the mails they can contact our online customer service and they will help them solve the problem. Finally the clients will receive the mails successfully. The purchase procedures are simple and the delivery of our Databricks-Certified-Data-Engineer-Professional study materials is fast.
Training Databricks-Certified-Data-Engineer-Professional Online: https://www.actual4exams.com/Databricks-Certified-Data-Engineer-Professional-valid-dump.html
- Databricks-Certified-Data-Engineer-Professional Trustworthy Dumps 🤫 Databricks-Certified-Data-Engineer-Professional Trustworthy Dumps 🥛 Databricks-Certified-Data-Engineer-Professional Exam Fees ↪ Immediately open ▶ www.torrentvce.com ◀ and search for ( Databricks-Certified-Data-Engineer-Professional ) to obtain a free download 🛅Exam Databricks-Certified-Data-Engineer-Professional Simulator
- Exam Databricks-Certified-Data-Engineer-Professional Questions Answers 🎥 Databricks-Certified-Data-Engineer-Professional Valid Dumps Questions 🥯 Databricks-Certified-Data-Engineer-Professional Latest Exam Practice ⚡ Immediately open { www.pdfvce.com } and search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ to obtain a free download 🦌Exam Databricks-Certified-Data-Engineer-Professional Questions Answers
- Pass Guaranteed Quiz Databricks - Latest New Databricks-Certified-Data-Engineer-Professional Test Prep 🍍 Immediately open ▛ www.practicevce.com ▟ and search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ to obtain a free download 🥴Exam Dumps Databricks-Certified-Data-Engineer-Professional Demo
- Free PDF Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Newest New Test Prep 🦯 Immediately open ➥ www.pdfvce.com 🡄 and search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ to obtain a free download 👷Databricks-Certified-Data-Engineer-Professional Trustworthy Dumps
- Databricks-Certified-Data-Engineer-Professional Valid Exam Blueprint 🐳 Reliable Databricks-Certified-Data-Engineer-Professional Test Syllabus 📅 Exam Databricks-Certified-Data-Engineer-Professional Simulator 🛕 The page for free download of ➠ Databricks-Certified-Data-Engineer-Professional 🠰 on ✔ www.pdfdumps.com ️✔️ will open immediately 🔦Exam Databricks-Certified-Data-Engineer-Professional Questions Answers
- Cost Effective Databricks-Certified-Data-Engineer-Professional Dumps 🛤 Study Materials Databricks-Certified-Data-Engineer-Professional Review 🥗 Databricks-Certified-Data-Engineer-Professional Pdf Torrent 💭 Simply search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 for free download on ➤ www.pdfvce.com ⮘ 🚨Databricks-Certified-Data-Engineer-Professional Latest Dumps Files
- Databricks-Certified-Data-Engineer-Professional Test Online 🛕 Exam Databricks-Certified-Data-Engineer-Professional Questions Answers 🥟 Exam Databricks-Certified-Data-Engineer-Professional Questions Answers 👶 Immediately open ▷ www.practicevce.com ◁ and search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ to obtain a free download ⌛Databricks-Certified-Data-Engineer-Professional Reliable Exam Book
- Pass-Sure New Databricks-Certified-Data-Engineer-Professional Test Prep Offer You The Best Training Online | Databricks Certified Data Engineer Professional Exam 🏑 Download ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ for free by simply entering ▷ www.pdfvce.com ◁ website 🧿Exam Databricks-Certified-Data-Engineer-Professional Questions Answers
- Exam Dumps Databricks-Certified-Data-Engineer-Professional Demo 👭 Exam Databricks-Certified-Data-Engineer-Professional Simulator 😑 Databricks-Certified-Data-Engineer-Professional Valid Dumps Questions ⛺ Search for 【 Databricks-Certified-Data-Engineer-Professional 】 and download it for free immediately on 《 www.prep4away.com 》 🥱Databricks-Certified-Data-Engineer-Professional Test Online
- Pass Guaranteed Quiz 2026 Databricks-Certified-Data-Engineer-Professional: High Hit-Rate New Databricks Certified Data Engineer Professional Exam Test Prep 🧈 Search for 「 Databricks-Certified-Data-Engineer-Professional 」 and download it for free on { www.pdfvce.com } website ❔Databricks-Certified-Data-Engineer-Professional Reliable Exam Pass4sure
- Databricks-Certified-Data-Engineer-Professional Pdf Torrent 😬 Exam Dumps Databricks-Certified-Data-Engineer-Professional Demo ⛴ Databricks-Certified-Data-Engineer-Professional Test Online ✏ Easily obtain free download of ( Databricks-Certified-Data-Engineer-Professional ) by searching on ⇛ www.prepawayete.com ⇚ 🟤Latest Databricks-Certified-Data-Engineer-Professional Test Practice
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes