Databricks-Certified-Professional-Data-Engineer Study Questions are Most Powerful Weapon to Help You Pass the Databricks Certified Professional Data Engineer Exam exam - ActualtestPDF

The Databricks modern job market is becoming more and more competitive and challenging and if you are not ready for it then you cannot pursue a rewarding career. Take a smart move right now and enroll in the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification exam and strive hard to pass the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification exam.
Databricks Databricks-Certified-Professional-Data-Engineer Exam Overview:
>> Databricks-Certified-Professional-Data-Engineer Valid Test Cram <<
Databricks-Certified-Professional-Data-Engineer Instant Discount - Reliable Databricks-Certified-Professional-Data-Engineer Dumps Ebook
Computers have made their appearance providing great speed and accuracy for our work. IT senior engine is very much in demand in all over the world. Now Databricks Databricks-Certified-Professional-Data-Engineer latest dumps files will be helpful for your career. ActualtestPDF produces the best products with high quality and high passing rate. Our valid Databricks-Certified-Professional-Data-Engineer Latest Dumps Files help a lot of candidates pass exam and obtain certifications, so that we are famous and authoritative in this filed.
Databricks Certified Professional Data Engineer certification is a valuable credential for data engineers who want to demonstrate their expertise in using the Databricks platform. It provides employers with a way to identify and verify the skills of candidates and employees, and it can help data engineers advance their careers by demonstrating their proficiency in using the Databricks platform to build and maintain scalable and reliable data pipelines.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q88-Q93):
NEW QUESTION # 88
Projecting a multi-dimensional dataset onto which vector has the greatest variance?
- A. second principal component
- B. first eigenvector
- C. second eigenvector
- D. first principal component
- E. not enough information given to answer
Answer: D
Explanation:
Explanation
The method based on principal component analysis (PCA) evaluates the features according to the projection of
the largest eigenvector of the correlation matrix on the initial dimensions, the method based on Fisher's linear
discriminant analysis evaluates. Them according to the magnitude of the components of the discriminant
vector.
The first principal component corresponds to the greatest variance in the data, by definition. If we project the
data onto the first principal component line, the data is more spread out (higher variance) than if projected onto
any other line, including other principal components.
NEW QUESTION # 89
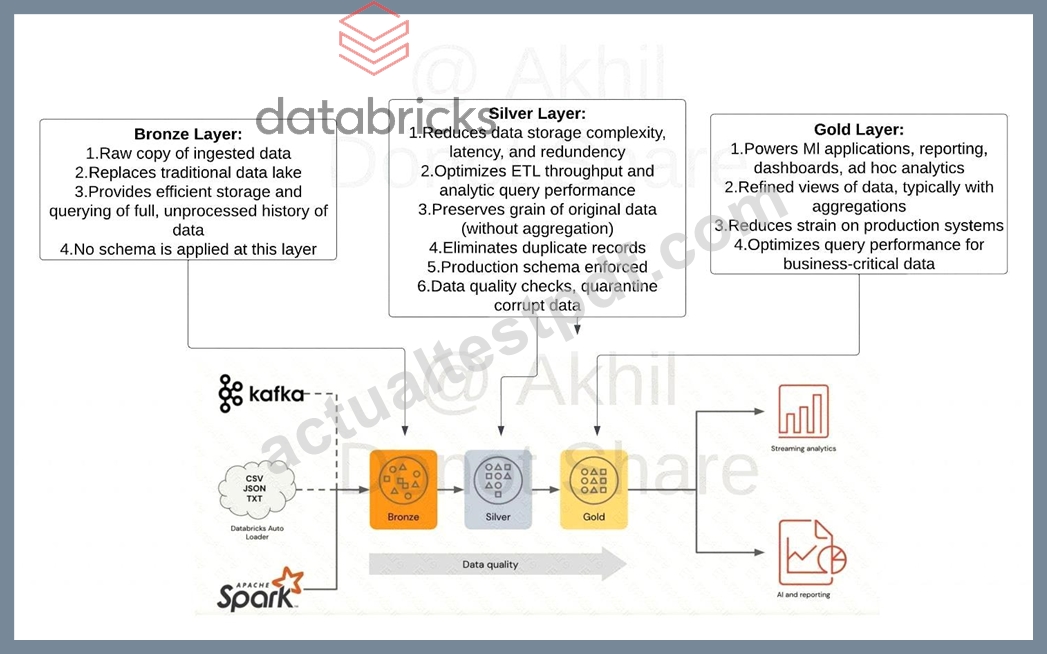
What is the main difference between the silver layer and the gold layer in medalion architecture?
- A. Gold may contain aggregated data
- B. Data quality checks are applied in gold
- C. God is a copy of silver data
- D. Silver is a copy of bronze data
- E. Silver may contain aggregated data
Answer: A
Explanation:
Explanation
Medallion Architecture - Databricks
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.
A diagram of a house Description automatically generated with low confidence
NEW QUESTION # 90
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
" claims " : [
{ " name " : " valid_patient_id " , " constraint " : " patient_id IS NOT NULL " },
{ " name " : " non_negative_amount " , " constraint " : " claim_amount > = 0 " }
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
- A. Invoke an external API to validate records against the metadata rules.
- B. Use a SQL CONSTRAINT block referencing the JSON file path.
- C. Reference each expectation with @dlt.expect decorators in the table declaration.
- D. Load the JSON metadata, loop through its entries, and apply expectations using dlt.expect_all.
Answer: D
Explanation:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable. Other options are incorrect: invoking an external API introduces unnecessary complexity, individual decorators require hardcoding, and SQL constraints cannot dynamically reference external JSON.
NEW QUESTION # 91
Which of the following SQL statements can replace python variables in Databricks SQL code, when the notebook is set in SQL mode?
1.%python
2.table_name = "sales"
3.schema_name = "bronze"
4.
5.%sql
6.SELECT * FROM ____________________
- A. SELECT * FROM schema_name.table_name
- B. SELECT * FROM f{schema_name.table_name}
- C. SELECT * FROM ${schema_name}.${table_name}
- D. SELECT * FROM {schem_name.table_name}
Answer: C
Explanation:
Explanation
The answer is, SELECT * FROM ${schema_name}.${table_name}
%python
table_name = "sales"
schema_name = "bronze"
%sql
SELECT * FROM ${schema_name}.${table_name}
${python variable} -> Python variables in Databricks SQL code
NEW QUESTION # 92
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE This table is partitioned by the date column. A query is run with the following filter:
longitude < 20 & longitude > -20
Which statement describes how data will be filtered?
- A. Statistics in the Delta Log will be used to identify data files that might include records in the filtered range.
- B. The Delta Engine will scan the parquet file footers to identify each row that meets the filter criteria.
- C. The Delta Engine will use row-level statistics in the transaction log to identify the flies that meet the filter criteria.
- D. Statistics in the Delta Log will be used to identify partitions that might Include files in the filtered range.
- E. No file skipping will occur because the optimizer does not know the relationship between the partition column and the longitude.
Answer: A
Explanation:
Explanation
This is the correct answer because it describes how data will be filtered when a query is run with the following filter: longitude < 20 & longitude > -20. The query is run on a Delta Lake table that has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE. This table is partitioned by the date column. When a query is run on a partitioned Delta Lake table, Delta Lake uses statistics in the Delta Log to identify data files that might include records in the filtered range. The statistics include information such as min and max values for each column in each data file. By using these statistics, Delta Lake can skip reading data files that do not match the filter condition, which can improve query performance and reduce I/O costs. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Data skipping" section.
NEW QUESTION # 93
......
Databricks-Certified-Professional-Data-Engineer Instant Discount: https://www.actualtestpdf.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html
- Databricks-Certified-Professional-Data-Engineer Certification Training - Databricks-Certified-Professional-Data-Engineer Exam Dumps - Databricks-Certified-Professional-Data-Engineer Study Guide 🏐 Enter ➡ www.dumpsmaterials.com ️⬅️ and search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ to download for free 💼Test Databricks-Certified-Professional-Data-Engineer Registration
- Realistic Databricks-Certified-Professional-Data-Engineer Valid Test Cram – Pass Databricks-Certified-Professional-Data-Engineer First Attempt 🔙 Search for ➥ Databricks-Certified-Professional-Data-Engineer 🡄 and download it for free immediately on ➠ www.pdfvce.com 🠰 🥿Reliable Test Databricks-Certified-Professional-Data-Engineer Test
- HOT Databricks-Certified-Professional-Data-Engineer Valid Test Cram - High-quality Databricks Databricks Certified Professional Data Engineer Exam - Databricks-Certified-Professional-Data-Engineer Instant Discount ⭐ Search for 「 Databricks-Certified-Professional-Data-Engineer 」 and download exam materials for free through ⮆ www.practicevce.com ⮄ ⏹Latest Databricks-Certified-Professional-Data-Engineer Exam Practice
- Pass-Sure Databricks Databricks-Certified-Professional-Data-Engineer Valid Test Cram - Databricks-Certified-Professional-Data-Engineer Free Download 🍑 Open { www.pdfvce.com } and search for 【 Databricks-Certified-Professional-Data-Engineer 】 to download exam materials for free 🦽Regualer Databricks-Certified-Professional-Data-Engineer Update
- Databricks-Certified-Professional-Data-Engineer Reliable Test Price 🔯 Test Databricks-Certified-Professional-Data-Engineer Registration 🥡 New Soft Databricks-Certified-Professional-Data-Engineer Simulations 📔 Search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ and obtain a free download on ⇛ www.pass4test.com ⇚ 📯Updated Databricks-Certified-Professional-Data-Engineer Demo
- Latest Databricks-Certified-Professional-Data-Engineer Valid Test Cram, Ensure to pass the Databricks-Certified-Professional-Data-Engineer Exam 🥄 Easily obtain ▛ Databricks-Certified-Professional-Data-Engineer ▟ for free download through 「 www.pdfvce.com 」 🚅Databricks-Certified-Professional-Data-Engineer Test Fee
- Latest Databricks-Certified-Professional-Data-Engineer Valid Test Cram, Ensure to pass the Databricks-Certified-Professional-Data-Engineer Exam 👦 Search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ and obtain a free download on ⮆ www.troytecdumps.com ⮄ 🏕Databricks-Certified-Professional-Data-Engineer Valid Exam Dumps
- Latest Databricks-Certified-Professional-Data-Engineer Exam Practice 🚣 Databricks-Certified-Professional-Data-Engineer Valid Exam Dumps 😞 Databricks-Certified-Professional-Data-Engineer Vce Torrent 🍑 Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and obtain a free download on ⇛ www.pdfvce.com ⇚ 🙅Regualer Databricks-Certified-Professional-Data-Engineer Update
- Valid Databricks-Certified-Professional-Data-Engineer Exam Test 👱 Databricks-Certified-Professional-Data-Engineer Test Fee ✳ Reliable Test Databricks-Certified-Professional-Data-Engineer Test 🧸 { www.examcollectionpass.com } is best website to obtain ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ for free download 🎫Latest Databricks-Certified-Professional-Data-Engineer Exam Price
- 100% Pass Databricks Databricks-Certified-Professional-Data-Engineer Realistic Valid Test Cram 🌑 Download ➥ Databricks-Certified-Professional-Data-Engineer 🡄 for free by simply entering ☀ www.pdfvce.com ️☀️ website 🍁Databricks-Certified-Professional-Data-Engineer Test Fee
- Test Databricks-Certified-Professional-Data-Engineer Registration 🏸 Valid Databricks-Certified-Professional-Data-Engineer Exam Test 🤡 Pdf Databricks-Certified-Professional-Data-Engineer Braindumps ➡️ Easily obtain ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ for free download through ▷ www.pdfdumps.com ◁ 🏙Databricks-Certified-Professional-Data-Engineer Valid Test Question
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes