Exam Databricks-Machine-Learning-Professional Topics - Databricks-Machine-Learning-Professional Test Simulator Online
DOWNLOAD the newest VCEEngine Databricks-Machine-Learning-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=12piLcDNj2XC6EOfuSrEnK1NAhHuGRBYd
The supremacy of VCEEngine in the tech sector solely relies on its competency to offer its users updated and real Databricks-Machine-Learning-Professional exam dumps. Our dedicated team takes feedback from experts all around the world to update its Databricks-Machine-Learning-Professional actual dumps. This practice material will make your preparation for the Databricks Databricks-Machine-Learning-Professional examination super easy and effective.
| Topic | Details |
|---|
| Topic 1 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 2 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 3 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 4 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 5 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 6 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 7 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
>> Exam Databricks-Machine-Learning-Professional Topics <<
Databricks-Machine-Learning-Professional Test Simulator Online, Databricks-Machine-Learning-Professional Valid Test Simulator
There are a lot of experts and professors in or company in the field. In order to meet the demands of all people, these excellent experts and professors from our company have been working day and night. They tried their best to design the best Databricks-Machine-Learning-Professional Study Materials from our company for all people. By our study materials, all people can prepare for their Databricks-Machine-Learning-Professional exam in the more efficient method.
Databricks Certified Machine Learning Professional Sample Questions (Q156-Q161):
NEW QUESTION # 156
Which MLflow function logs files like plots or datasets?
- A. mlflow.log_metric()
- B. mlflow.log_artifact()
- C. mlflow.save_model()
- D. mlflow.log_param()
Answer: B
Explanation:
Artifacts include:
charts
model files
datasets.
NEW QUESTION # 157
A Machine Learning Engineer is setting up a cluster for a deep learning training run, but has a number of settings options to choose from. Their cluster will be reused by other engineers on their team and their datasets vary in size from hundreds of MBs to hundreds of GBs. They need to choose a configuration that allows for performant, stable deep learning training without excessive costs. Which configuration will do this?
- A. Using ML Runtime, use a large single node, GPU-enabled VM with auto termination set to 20 minutes to reduce costs
- B. Using ML Runtime, use a moderately sized CPU VM for the driver and a variable number of GPU enabled VMs for the workers with autoscale enabled
- C. Using Databricks Runtime, use a moderately sized CPU VM for the driver and a variable number of GPU enabled VMs for the workers with autoscale enabled
- D. Using ML Runtime, use a moderate sized GPU VM for the driver and a variable number of memory optimized CPU VMs for the workers with autoscale enabled
Answer: B
Explanation:
Using the ML Runtime ensures deep learning frameworks and GPU drivers are preconfigured and optimized. A moderately sized CPU driver is sufficient for coordination, while GPU-enabled worker nodes handle the computationally intensive training workload. Enabling autoscaling allows the cluster to efficiently adapt to datasets ranging from hundreds of megabytes to hundreds of gigabytes, providing strong performance without overprovisioning and controlling costs in a shared team environment.
NEW QUESTION # 158
A machine learning engineer has found drift in a production machine learning application. The engineer has determined that retraining and deploying a new model is necessary. Which statement must be true prior to deploying the new model?
- A. The new model must perform better than the original model on a random subset of the available data
- B. The now model must perform better than the original model on all of the available data
- C. All of these statements must be true prior to deploying the new model
- D. The new model must perform better than the original model on the most recently available data
Answer: D
Explanation:
When drift is detected, it indicates that the data distribution has changed. Therefore, the new model must perform better than the original model on the most recently available data, as that data reflects current conditions. This ensures the new model is well-adapted to the current environment and will deliver more reliable predictions.
NEW QUESTION # 159
A Machine Learning Engineer has deployed a fraud detection model in Databricks Model Serving to detect fraudulent transactions. The engineer wants to compare the model's predictions with the actual fraud classifications from the Fraud Ops team to monitor model performance. The Fraud Ops team uses a unique transaction_id to investigate fraudulent activity and persist their findings to a fraud_findings table. The engineer enabled inference tables on the endpoint, but they are not sure how to map the models' predictions to the Fraud Ops team's classifications. How can the engineer uniquely join the models' prediction to the fraud_findings table with the fewest code changes?
- A. Populate the client_request_id field with the transaction_id in the model serving request body.
Join the inference table with the fraud_findings table using client_request_id (which contains the transaction_id) as the join key. - B. Modify the model to include an additional input: transaction_id. Log, register and deploy the new model. In the model serving request body, add transaction_id as an additional input feature. Join the inference table with the fraud_findings table using transaction_id as the join key.
- C. Store databricks_request_id returned from each model serving request and persist it to the fraud_findings table. Join the inference table with the fraud_findings table using databricks_request_id as the join key.
- D. Join the inference table with the fraud_findings table using timestamp_ms as the join key.
Answer: A
Explanation:
Databricks Model Serving inference tables automatically log the client_request_id field for each request. By populating this field with the existing transaction_id in the request body, the engineer can directly and uniquely join inference predictions with the fraud_findings table using the same identifier, achieving accurate performance monitoring with minimal code changes and no model retraining or redeployment.
NEW QUESTION # 160
A machine learning engineer has developed the following custom model class with preprocessing logic to combine two columns:
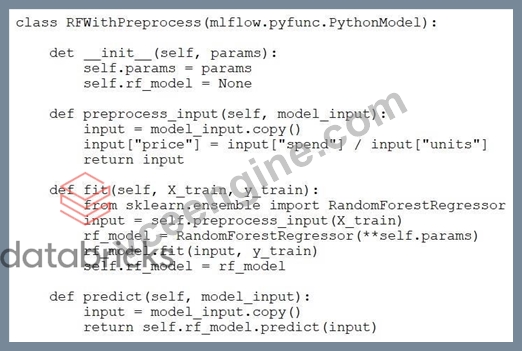
However, instances of this class are unable to compute predictions.
Which set of changes will update the class so predictions can be computed while continuing to apply the preprocessing logic?
- A. Replace model_input.copy() with self.preprocess_input(model_input.copy()) in the predict method
- B. Replace model_input.copy() with self.preprocess_input(model_input.copy()) in the preprocess_input method
- C. Replace self.rf_model.predict(input) with self.predict(input) in the predict method
- D. Remove the self.rf_model = rf_model line from the fit method
Answer: A
Explanation:
The issue is that the predict() method does not apply the same preprocessing as the fit() method.
During training, the model uses preprocessed data (via self.preprocess_input()), but during prediction, it directly uses raw input. This mismatch causes prediction errors because the model expects preprocessed input.
By updating the predict() method to call self.preprocess_input(model_input.copy()), both training and prediction use consistent feature transformations, allowing predictions to be computed successfully.
NEW QUESTION # 161
......
VCEEngine's pledge to customers is that we can help customers 100% pass their IT certification exams. The quality of VCEEngine's product has been recognized by many IT experts. The most important characteristic of our products is their pertinence. It only takes 20 hours for you to complete the training course and then easily pass your first time to attend Databricks Certification Databricks-Machine-Learning-Professional Exam. You will not regret to choose VCEEngine, because choosing it represents the success.
Databricks-Machine-Learning-Professional Test Simulator Online: https://www.vceengine.com/Databricks-Machine-Learning-Professional-vce-test-engine.html
- Pass Guaranteed Quiz 2026 Reliable Databricks Databricks-Machine-Learning-Professional: Exam Databricks Certified Machine Learning Professional Topics 🚰 Immediately open ➽ www.practicevce.com 🢪 and search for ➥ Databricks-Machine-Learning-Professional 🡄 to obtain a free download 🏙Latest Databricks-Machine-Learning-Professional Test Guide
- New Databricks-Machine-Learning-Professional Exam Online 🔊 Latest Databricks-Machine-Learning-Professional Test Guide 😡 Valid Databricks-Machine-Learning-Professional Study Materials 🎌 Search for [ Databricks-Machine-Learning-Professional ] and obtain a free download on ( www.pdfvce.com ) 🍉Databricks-Machine-Learning-Professional Exam Test
- New Databricks-Machine-Learning-Professional Exam Online 🚋 Test Databricks-Machine-Learning-Professional Testking 🚚 Answers Databricks-Machine-Learning-Professional Real Questions 🛐 Search for ⮆ Databricks-Machine-Learning-Professional ⮄ and download exam materials for free through ➠ www.prepawaypdf.com 🠰 🍜Answers Databricks-Machine-Learning-Professional Real Questions
- Test Databricks-Machine-Learning-Professional Testking 💰 Answers Databricks-Machine-Learning-Professional Real Questions 🏮 Questions Databricks-Machine-Learning-Professional Exam 🎥 Search for { Databricks-Machine-Learning-Professional } and download exam materials for free through ( www.pdfvce.com ) ✉Databricks-Machine-Learning-Professional Pass Guaranteed
- 2026 Efficient 100% Free Databricks-Machine-Learning-Professional – 100% Free Exam Topics | Databricks Certified Machine Learning Professional Test Simulator Online 🍴 Go to website 【 www.vceengine.com 】 open and search for ⇛ Databricks-Machine-Learning-Professional ⇚ to download for free 🦃Databricks-Machine-Learning-Professional Exam Cram Review
- 100% Pass Databricks-Machine-Learning-Professional - Fantastic Exam Databricks Certified Machine Learning Professional Topics 🔹 Search for ▶ Databricks-Machine-Learning-Professional ◀ and download exam materials for free through ➤ www.pdfvce.com ⮘ 🥖Databricks-Machine-Learning-Professional Training Courses
- Databricks-Machine-Learning-Professional Pass Guaranteed 🚢 Databricks-Machine-Learning-Professional Training Courses 📼 Databricks-Machine-Learning-Professional Reliable Test Testking 🐰 Open ➡ www.troytecdumps.com ️⬅️ enter ➤ Databricks-Machine-Learning-Professional ⮘ and obtain a free download 😝Databricks-Machine-Learning-Professional Exam Fee
- Updated And Free Databricks Databricks-Machine-Learning-Professional PDF Dumps Are Hassle-Free Preparation With Pdfvce ☔ Download ▷ Databricks-Machine-Learning-Professional ◁ for free by simply entering 【 www.pdfvce.com 】 website 🦰Test Databricks-Machine-Learning-Professional Testking
- Relevant Databricks-Machine-Learning-Professional Exam Dumps 🎠 Test Databricks-Machine-Learning-Professional Testking 📦 Relevant Databricks-Machine-Learning-Professional Exam Dumps 📮 The page for free download of { Databricks-Machine-Learning-Professional } on [ www.verifieddumps.com ] will open immediately 🃏Dump Databricks-Machine-Learning-Professional Collection
- Pass Guaranteed Quiz Databricks - Databricks-Machine-Learning-Professional - Efficient Exam Databricks Certified Machine Learning Professional Topics 🎧 Open ▶ www.pdfvce.com ◀ and search for ▷ Databricks-Machine-Learning-Professional ◁ to download exam materials for free 🦅Answers Databricks-Machine-Learning-Professional Real Questions
- 100% Pass Databricks-Machine-Learning-Professional - Fantastic Exam Databricks Certified Machine Learning Professional Topics ⚠ Easily obtain ➤ Databricks-Machine-Learning-Professional ⮘ for free download through ➠ www.testkingpass.com 🠰 🍍Valid Databricks-Machine-Learning-Professional Study Materials
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
DOWNLOAD the newest VCEEngine Databricks-Machine-Learning-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=12piLcDNj2XC6EOfuSrEnK1NAhHuGRBYd