2026 Latest RealVCE AI-500 PDF Dumps and AI-500 Exam Engine Free Share: https://drive.google.com/open?id=154pURJXgJYALsbRanvRQVg03Y0KWBXF7
Nowadays passing the test AI-500 certification is extremely significant for you and can bring a lot of benefits to you. Passing the test AI-500 certification does not only prove that you are competent in some area but also can help you enter in the big company and double your wage. Buying our AI-500 Study Materials can help you pass the test easily and successfully. We provide the study materials which are easy to be mastered, professional expert team and first-rate service to make you get an easy and efficient learning and preparation for the AI-500 test.
| Section | Weight | Objectives |
|---|---|---|
| Develop multi-agent solutions in Azure | 30-35% | - Implement agent memory, context management, and knowledge integration
|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
>> Reliable AI-500 Exam Preparation <<
The Designing and Implementing Multi-Agent AI Solutions (AI-500) prep material is available in three versions. AI-500 Practice exams and PDF questions are available at RealVCE so that users can meet their training needs and pass the Designing and Implementing Multi-Agent AI Solutions (AI-500) exam on the first try. The philosophy of RealVCE behind offering Designing and Implementing Multi-Agent AI Solutions (AI-500) prep material in three formats is helping students meet their unique learning needs.
NEW QUESTION # 12
You are validating the outcome of the consultant proposal for the Patient Intake agent.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.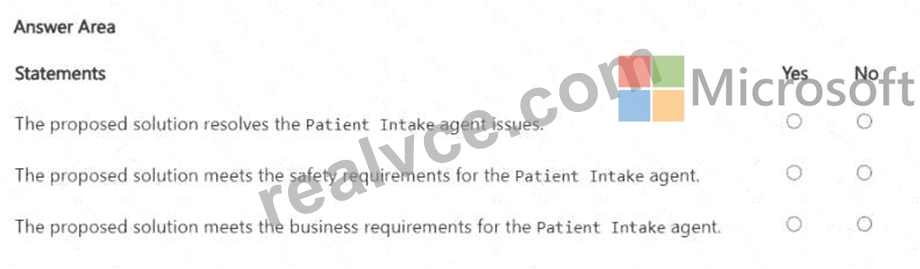
Answer:
Explanation: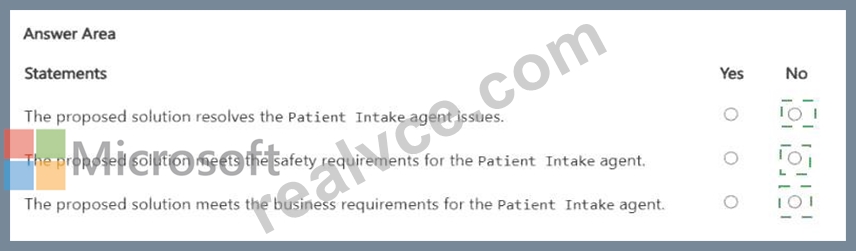
Explanation:
No / No / No
All three consultant-proposal statements should be rejected. Applying the highest sensitivity to every guardrail control is not automatically safer because it can increase false positives and unnecessarily block legitimate clinical interactions; controls should be tuned to the actual risk and tested. Telling the model in a system prompt to ignore hate speech is not equivalent to enabling the platform content-safety controls required for public-facing agents. Finally, repeatedly prompting patients to verify symptoms does not address long-context growth and can worsen token usage and latency. Microsoft guidance separates deterministic safety controls, evaluation, and context-management mechanisms from ordinary prompt instructions. The proposal also hardcodes medical behavior in prompts, contrary to the requirement to avoid embedding new clinical logic in the core prompt. A robust design would use appropriate content-safety/guardrail controls, validated intervention points, and a deliberate memory/compaction strategy rather than relying on increasingly restrictive or repetitive prompt text. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: AI-500 Study Guide - guardrails, context management, and evaluation
NEW QUESTION # 13
You have a Microsoft Foundry ticket-triage solution that uses connected agents. Each subagent prompt includes instructions for allowed tools and a JSON handoff.
You need to add automated prompt evaluations. The solution must identify changes that cause the subagents to do the following:
* Skip mandated evidence gathering.
* Return payloads that downstream agents cannot process.
* Handle work outside their assigned responsibilities.
How should you configure the evaluation suite? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.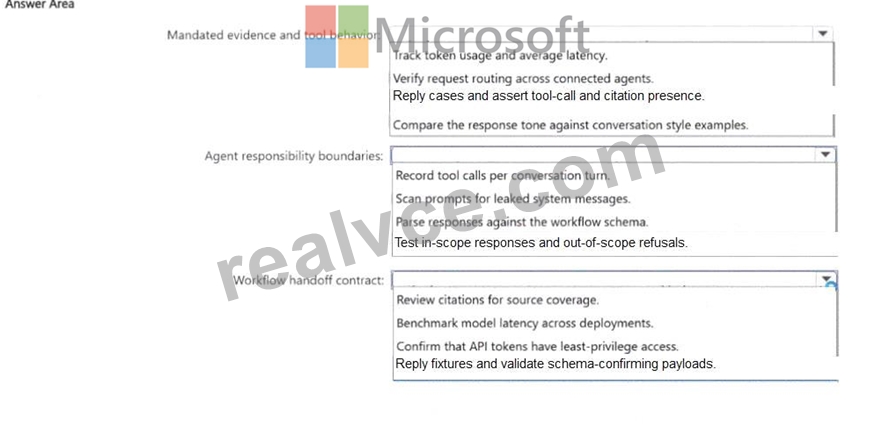
Answer:
Explanation: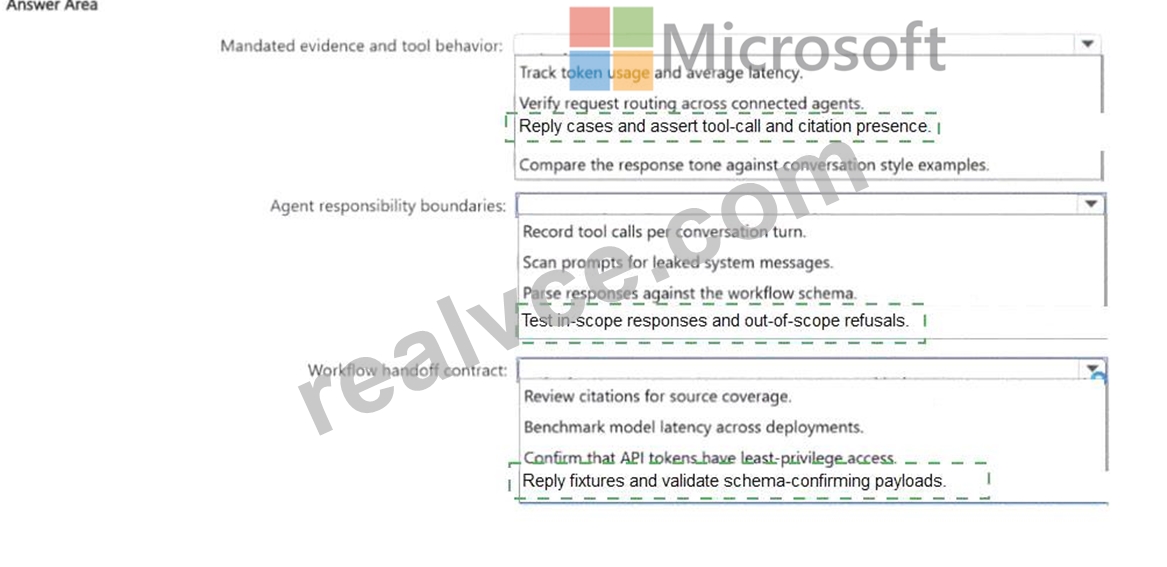
Explanation:
Mandated evidence/tool behavior: Replay cases and assert tool-call and citation presence; Agent responsibility boundaries: Test in-scope responses and out-of-scope refusals; Workflow handoff contract: Replay fixtures and validate schema-conforming payloads.
The three regressions target different interfaces and should be evaluated with tests that directly observe those interfaces. Required evidence gathering is a process behavior, so replayed cases should assert that mandated tool calls and citations occur. Responsibility boundaries are best tested with both positive and negative prompts: in-scope cases must be handled, while out-of-scope work should be refused or redirected. The JSON handoff is an interface contract, so replay fixtures should be validated against the expected schema to catch missing fields, renamed properties, and type changes before downstream agents fail. Microsoft Foundry ' s agent evaluators and evaluation datasets support process-level tool checks, task-adherence checks, and structured regression testing. The supplied mappings therefore correctly align each evaluation technique with the failure it is intended to detect. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - built-in evaluators and evaluation datasets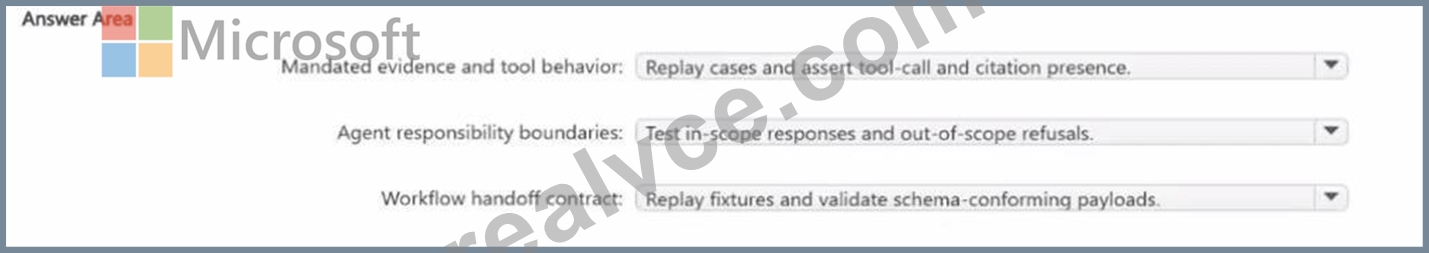
NEW QUESTION # 14
You have a Microsoft Foundry multi-agent customer support solution that routes requests from an intake agent to a retrieval agent, and then to a resolution agent. A custom guardrail is assigned to the agents.
You discover that some legitimate support requests are blocked, and some injected instructions in retrieved documents are allowed.
You need to validate the updated guardrail. The solution must meet the following requirements:
* Identify false positives and false negatives.
* Verify policy coverage across the agent solution
* Prevent changing the production agent behavior during testing
* Measure intervention accuracy by using a control and intervention point.
What should you do?
Answer: C
Explanation:
The updated guardrail must be evaluated with known benign and adversarial cases so false positives and false negatives can be measured explicitly. Running labeled cases through every relevant workflow path also tests whether the guardrail is applied consistently at the intended intervention points. Microsoft AI-500 guidance includes guardrail testing with synthetic or curated data and emphasizes evaluation before production rollout.
Playground-only spot checks are too narrow to establish coverage. Switching production to annotate-only would change live behavior and use customers as the test population, violating the requirement to avoid production changes. A compliance configuration review verifies that a policy exists but does not measure whether it correctly detects or misses real inputs. Option B is therefore the only approach that produces repeatable evidence of intervention accuracy and policy coverage without changing production behavior. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: AI-500 Study Guide - guardrail testing and evaluation
NEW QUESTION # 15
You need to recommend a memory retrieval strategy to support the planned changes for claim Approval.
What should you recommend? To answer, drag the appropriate resources to the correct requirements. Each resource may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.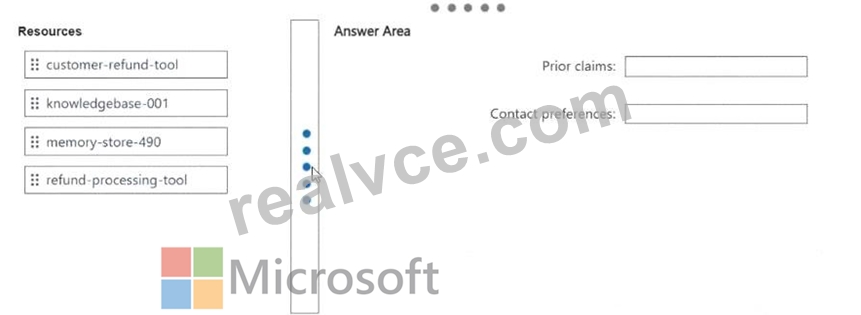
Answer:
Explanation: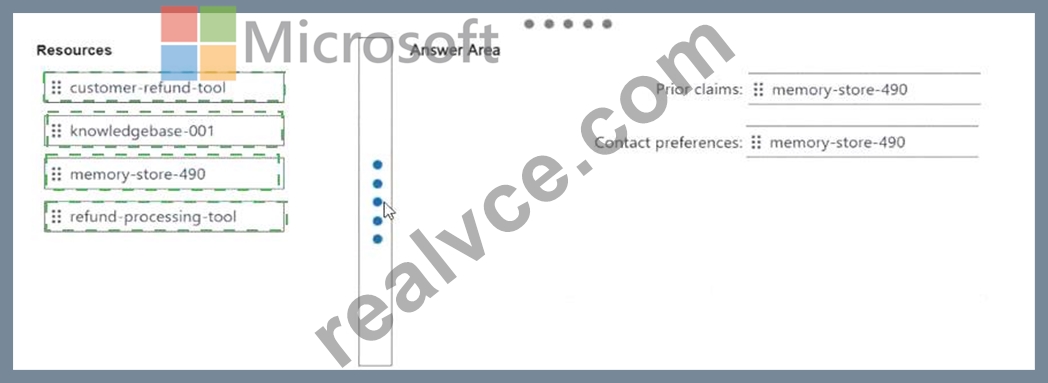
Explanation:
Prior claims: memory-store-490; Contact preferences: memory-store-490.
Both requirements describe information that should persist across conversations for the same customer:
previous claim information and stable contact preferences. Microsoft Foundry Memory is intended for durable, cross-session facts and summaries that agents can retrieve later, while a knowledge base is for shared reference content rather than user-specific history. The refund-processing and customer-refund tools are operational interfaces, not persistence layers. Using the existing memory store for both categories therefore matches the scenario ' s design objective. In production, the memory search tool should also be scoped to the end user so one customer ' s memory cannot be retrieved for another customer. Microsoft documents scope- based isolation for memory stores and supports a user-derived scope such as `{{$userId}}`. The key distinction is that the same memory store can hold multiple kinds of durable customer memory as long as retrieval is correctly scoped; there is no need to create separate tools or knowledge indexes for these two user- specific memory categories.
Official Microsoft reference: Create and use memory in Foundry Agent Service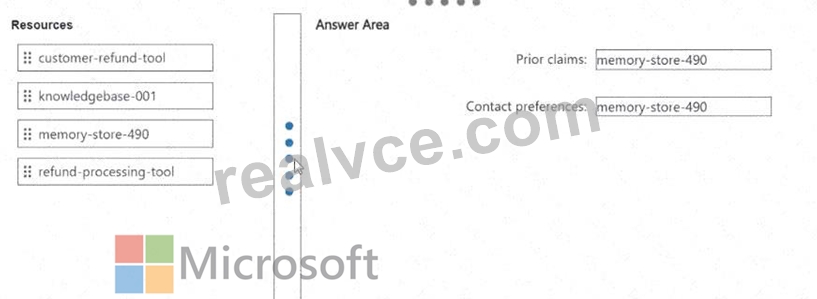
NEW QUESTION # 16
You have a Microsoft Foundry multi-agent solution that includes a orchestrator and agents named Agent1 and Agent2. The solution has the following characteristics:
* The orchestrator routes tasks to both agents.
* The agents invoice Model Context Protocol (MCP)-hosted tools.
* Agent? sends model-generated JSON parameters directly to tool endpoints.
* The agents use a shared managed identity that has contributor access to the resource group that contains the tool-backed Azure resources.
You need to implement a guardrail strategy for tool calls. The solution must meet the following requirements:
* Prevent invalid or out-of-range tool parameters from reaching the tool endpoints.
* Scope each agent ' s permissions to its assigned tools
* Limit Agent? to refund-processing tools only.
* Log tool invocations for audit purposes.
What should you do?
Answer: B
Explanation:
The solution needs deterministic validation before model-generated tool arguments reach MCP endpoints, per- agent authorization boundaries, tool scoping, and audit logging. Validating typed payload schemas at the tool boundary prevents malformed or out-of-range arguments before execution, which is stronger than validating outputs after a tool has already run. Per-agent managed identities and scoped RBAC roles reduce lateral movement and contain the impact of a compromised agent. A per-agent tool-access policy also ensures the refund-focused agent cannot invoke unrelated tools. Finally, Azure Monitor/trace logging provides an auditable record of tool invocations. A2A capability cards describe remote-agent capabilities rather than validate tool arguments. System instructions are not an authorization boundary, and shared Contributor access leaves an excessive blast radius. Option D is therefore the only answer that satisfies all four requirements at enforceable platform boundaries. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: AI-500 Study Guide - tool scopes, permission boundaries, and auditing
NEW QUESTION # 17
......
Our company made these AI-500 practice materials with accountability. We understand you can have more chances being accepted by other places and getting higher salary or acceptance. Our Designing and Implementing Multi-Agent AI Solutions training materials are made by our responsible company which means you can gain many other benefits as well. We offer AI-500 free demos for your reference, and send you the new updates if our experts make them freely. If you fail the exam after using our AI-500 exam prep unfortunately, we will switch other versions for you or return full refund.
Valid AI-500 Exam Bootcamp: https://www.realvce.com/AI-500_free-dumps.html
DOWNLOAD the newest RealVCE AI-500 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=154pURJXgJYALsbRanvRQVg03Y0KWBXF7