Many candidates may think that it will take a long time to prapare for the AI-500 exam. Actually, it only takes you about twenty to thirty hours to practice our AI-500 exam simulation. We believe that the professional guidance will help you absorb the knowledge quickly. You will have a wide range of chance after obtaining the AI-500 certificate. You need to have a brave attempt. Our AI-500 training engine will help you realize your dreams.
| Section | Weight | Objectives |
|---|---|---|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Develop multi-agent solutions in Azure | 30-35% | - Build and integrate tool ecosystems
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize prompt and model performance
|
First and foremost, we have high class operation system so we can assure you that you can start to prepare for the AI-500 exam with our study materials only 5 to 10 minutes after payment. Fortunately, you need not to worry about this sort of question any more, since you can find the best solution in this website--our AI-500 Training Materials. With our continued investment in technology, people and facilities, the future of our company has never looked so bright. There are so many advantages of our AI-500 practice test and I would like to give you a brief introduction now.
NEW QUESTION # 42
You have a Microsoft Foundry multi-agent solution that includes a planning agent and an execution agent You are designing a fixed order process where executions can run for several hours and can be interrupted by worker restarts.
You need to implement orchestration for the process. The solution must meet the following requirements
* Pause at predefined points.
* Resume from the last saved state after an interruption.
Which mechanisms should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.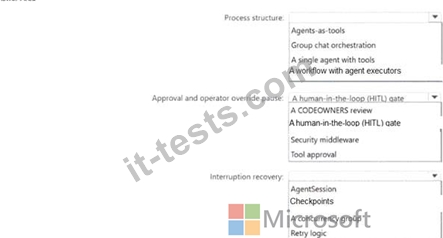
Answer:
Explanation: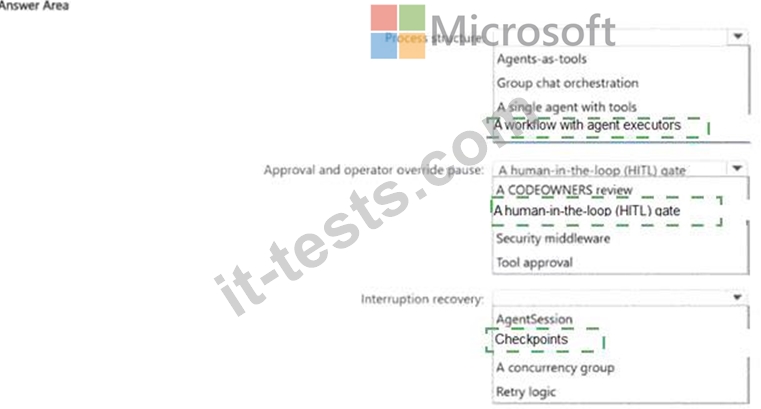
Explanation:
Process structure: A workflow with agent executors; Pause mechanism: A human-in-the-loop (HITL) gate; Interruption recovery: Checkpoints.
The process has a fixed execution order and can run for several hours, so an explicit workflow with agent executors is preferable to free-form agent delegation. The requirement to pause at predefined points is a human-in-the-loop requirement: the workflow must be able to suspend and emit a request for approval or operator input. The requirement to resume after worker restarts is addressed by checkpoints. Microsoft Agent Framework checkpoints persist workflow progress, executor state, pending messages, shared state, and outstanding requests so execution can be restored from the last saved point. A retry policy alone re-executes operations but does not reconstruct the complete workflow state after a process interruption. The three selected mechanisms therefore cover structure, controlled pause, and durable recovery as separate but complementary workflow concerns. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Checkpoints and Human-in-the-loop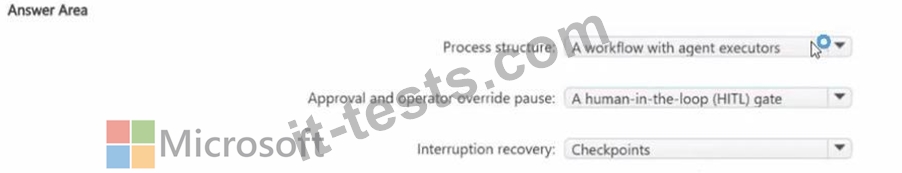
NEW QUESTION # 43
You have a Microsoft Foundry ticket-triage solution that uses connected agents. Each subagent prompt includes instructions for allowed tools and a JSON handoff.
You need to add automated prompt evaluations. The solution must identify changes that cause the subagents to do the following:
* Skip mandated evidence gathering.
* Return payloads that downstream agents cannot process.
* Handle work outside their assigned responsibilities.
How should you configure the evaluation suite? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.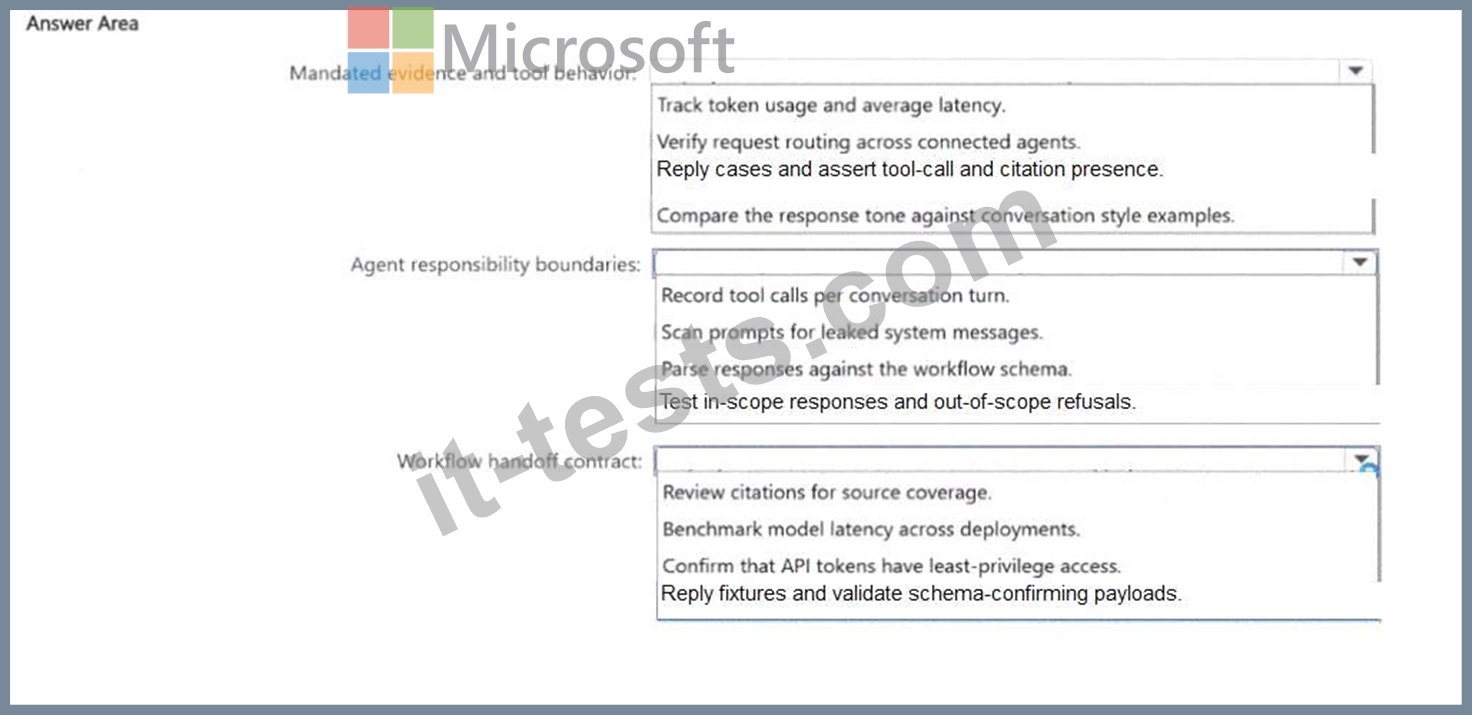
Answer:
Explanation: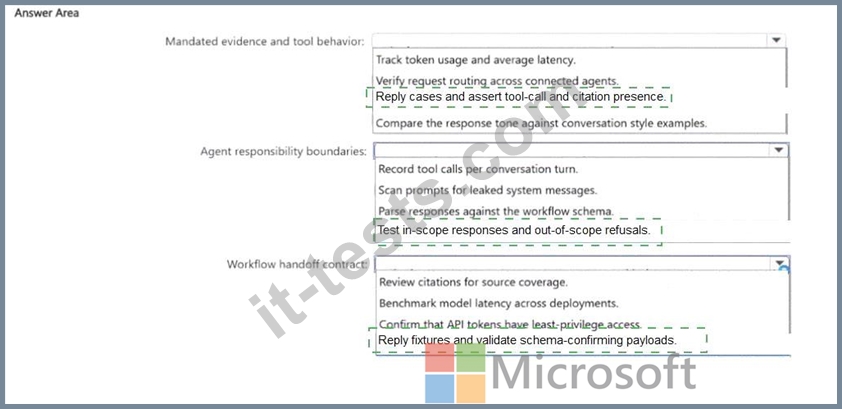
Explanation:
Mandated evidence/tool behavior: Replay cases and assert tool-call and citation presence; Agent responsibility boundaries: Test in-scope responses and out-of-scope refusals; Workflow handoff contract: Replay fixtures and validate schema-conforming payloads.
The three regressions target different interfaces and should be evaluated with tests that directly observe those interfaces. Required evidence gathering is a process behavior, so replayed cases should assert that mandated tool calls and citations occur. Responsibility boundaries are best tested with both positive and negative prompts: in-scope cases must be handled, while out-of-scope work should be refused or redirected. The JSON handoff is an interface contract, so replay fixtures should be validated against the expected schema to catch missing fields, renamed properties, and type changes before downstream agents fail. Microsoft Foundry ' s agent evaluators and evaluation datasets support process-level tool checks, task-adherence checks, and structured regression testing. The supplied mappings therefore correctly align each evaluation technique with the failure it is intended to detect. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - built-in evaluators and evaluation datasets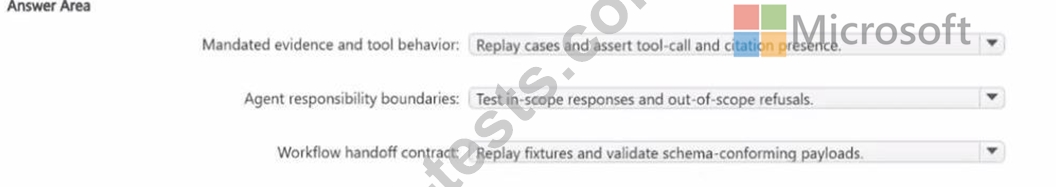
NEW QUESTION # 44
You have a multi-agent solution in a Microsoft Foundry project. The project connects to an Azure Storage account named stgaudit.
You plan to enable a storage-backed tool for the agent The tool will read and write blobs to stgaudit.
You need to create a role assignment for the agent. The solution must follow the principle of least privilege.
Which role should you use?
Answer: D
Explanation:
The tool only needs to read and write blob data in the `stgaudit` storage account. Storage Blob Data Contributor is the built-in data-plane role that grants the required blob read/write capabilities without granting unnecessary ownership or broad resource-management authority. Storage Account Contributor and the generic Contributor role operate at the management plane and are wider than necessary for this data-access requirement. Storage Blob Data Owner also exceeds the stated need by including additional control over blob data permissions/ownership. Microsoft ' s Azure Storage RBAC guidance separates data-plane blob roles from management roles and recommends choosing the narrowest role that supports the required operation.
Because the agent must both read and write blob content, D is the least-privilege role among the options. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Azure Storage - assign Azure roles for blob data access
NEW QUESTION # 45
You have a Microsoft Foundry agent built by using LangGraph. The agent retrieves policy content from a vector store. The LangGraph orchestration runs in Azure Container Apps, and the operations team uses Azure Monitor to inspect agent runs.
You discover that the vector store is sometimes unreachable during Azure regional maintenance windows You need to configure the tool ecosystem to ensure that the agent can answer policy questions during outages The solution must meet the following requirements:
* Use the project vector store without adding a local retrieval node for the primary path.
* Run the cached-policy lookup in the same compute environment as the LangGraph code.
* Emit agent, model, and tool spans that can be inspected in Azure Monitor How should you configure the tool ecosystem? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.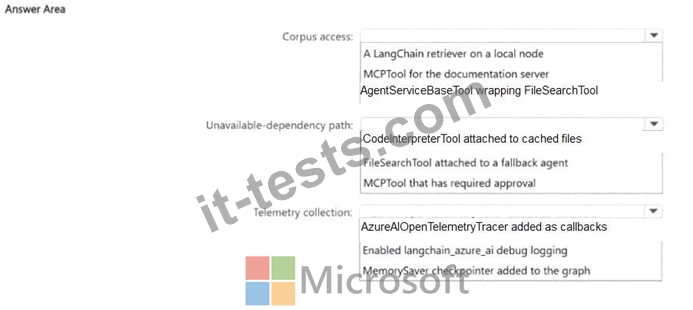
Answer:
Explanation: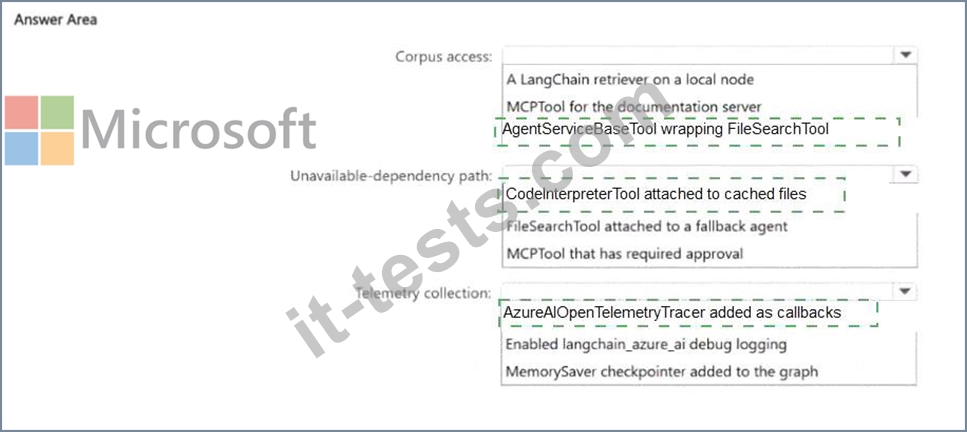
Explanation:
Corpus access: AgentServiceBaseTool wrapping FileSearchTool; Outage fallback: No listed option fully satisfies the requirement to run the cached-policy lookup in the same Azure Container Apps compute; Telemetry: AzureAIOpenTelemetryTracer added as callbacks.
Current Microsoft LangGraph integration guidance supports wrapping Foundry ' s FileSearchTool through AgentServiceBaseTool for the primary project-vector-store path and attaching AzureAIOpenTelemetryTracer through LangGraph callbacks for OpenTelemetry traces. The problematic part is the proposed outage fallback. Code Interpreter is a Foundry-hosted built-in tool, so it does not execute in the same Azure Container Apps compute environment as the LangGraph application. That means a CodeInterpreterTool- based fallback cannot satisfy the explicit same-compute requirement. A technically correct design would use a local LangGraph/LangChain callable or tool over cached policy content mounted or stored with the Container Apps workload. Because that local-tool option is absent from the answer set, there is no fully valid listed selection for the fallback row. The updated answer therefore preserves the two valid selections and explicitly identifies the missing valid option rather than endorsing an inconsistent one. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents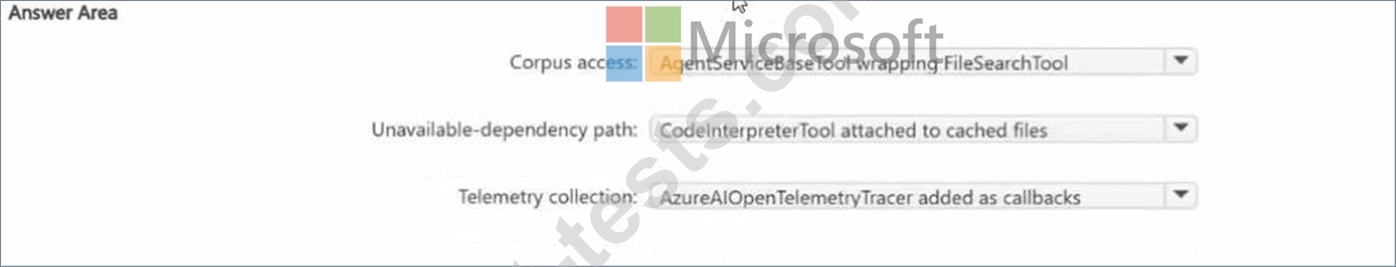
NEW QUESTION # 46
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.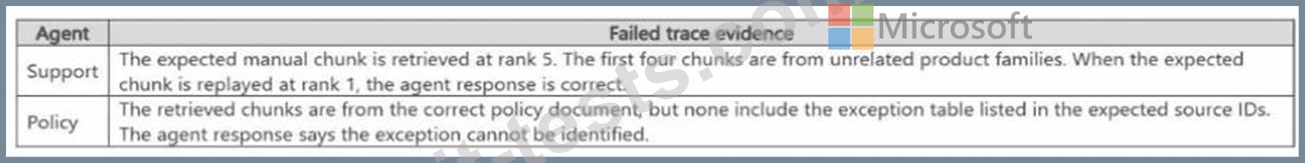
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.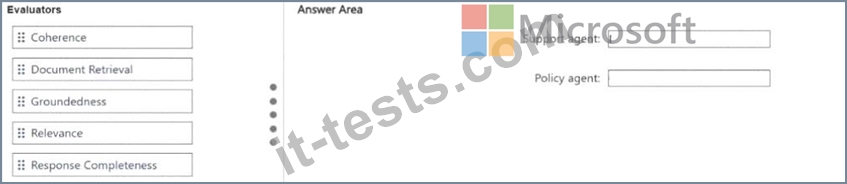
Answer:
Explanation: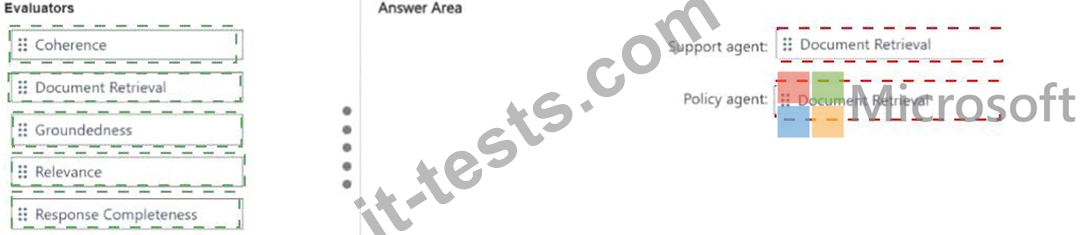
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 47
......
Our AI-500 exam torrent has three versions which people can choose according to their actual needs. The vision of PDF is easy to download, so people can learn AI-500 guide torrent anywhere if they have free time. People learn through fragmentation and deepen their understanding of knowledge through repeated learning. As for PC version, it can simulated real operation of test environment, users can test themselves in mock exam in limited time. This version of our AI-500 exam torrent is applicable to windows system computer. Based on Web browser, the version of APP can be available as long as there is a browser device can be used. At the meantime, not only do AI-500 Study Tool own a mock exam, and limited-time exam function, but also it has online error correction and other functions. The characteristic that three versions all have is that they have no limit of the number of users, so you don’t encounter failures anytime you want to learn our AI-500 guide torrent.
AI-500 Positive Feedback: https://www.it-tests.com/AI-500.html