There is no need to worry about virus on buying electronic products. For Actualtests4sure have created an absolutely safe environment and our exam question are free of virus attack. We make endless efforts to assess and evaluate our Databricks-Generative-AI-Engineer-Associate exam question’ reliability for a long time and put forward a guaranteed purchasing scheme. If there is any doubt about it, professional personnel will handle this at first time, and you can also have their remotely online guidance to install and use our Databricks-Generative-AI-Engineer-Associate Test Torrent.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Technical Databricks-Generative-AI-Engineer-Associate Training <<
Forget your daydream! Forget living in cloud-cuckoo-land! Just be down-to-earth to prepare for an IT certification. Databricks Databricks-Generative-AI-Engineer-Associate latest exam sample questions on our website are free to download for your reference. If you still want to find a valid dump, our website will be your beginning. Our Databricks Databricks-Generative-AI-Engineer-Associate Latest Exam sample questions are a small part of our real products. If you think the free version is excellent, you can purchase our complete version.
NEW QUESTION # 30
A Generative Al Engineer is developing a RAG application and would like to experiment with different embedding models to improve the application performance.
Which strategy for picking an embedding model should they choose?
Answer: D
Explanation:
The task involves improving a Retrieval-Augmented Generation (RAG) application's performance by experimenting with embedding models. The choice of embedding model impacts retrieval accuracy, which is critical for RAG systems. Let's evaluate the options based on Databricks Generative AI Engineer best practices.
Option A: Pick an embedding model trained on related domain knowledge
Embedding models trained on domain-specific data (e.g., industry-specific corpora) produce vectors that better capture the semantics of the application's context, improving retrieval relevance. For RAG, this is a key strategy to enhance performance.
Databricks Reference: "For optimal retrieval in RAG systems, select embedding models aligned with the domain of your data" ("Building LLM Applications with Databricks," 2023).
Option B: Pick the most recent and most performant open LLM released at the time LLMs are not embedding models; they generate text, not embeddings for retrieval. While recent LLMs may be performant for generation, this doesn't address the embedding step in RAG. This option misunderstands the component being selected.
Databricks Reference: Embedding models and LLMs are distinct in RAG workflows: "Embedding models convert text to vectors, while LLMs generate responses" ("Generative AI Cookbook").
Option C: Pick the embedding model ranked highest on the Massive Text Embedding Benchmark (MTEB) leaderboard hosted by HuggingFace The MTEB leaderboard ranks models across general tasks, but high overall performance doesn't guarantee suitability for a specific domain. A top-ranked model might excel in generic contexts but underperform on the engineer's unique data.
Databricks Reference: General performance is less critical than domain fit: "Benchmark rankings provide a starting point, but domain-specific evaluation is recommended" ("Databricks Generative AI Engineer Guide").
Option D: Pick an embedding model with multilingual support to support potential multilingual user questions Multilingual support is useful only if the application explicitly requires it. Without evidence of multilingual needs, this adds complexity without guaranteed performance gains for the current use case.
Databricks Reference: "Choose features like multilingual support based on application requirements" ("Building LLM-Powered Applications").
Conclusion: Option A is the best strategy because it prioritizes domain relevance, directly improving retrieval accuracy in a RAG system-aligning with Databricks' emphasis on tailoring models to specific use cases.
NEW QUESTION # 31
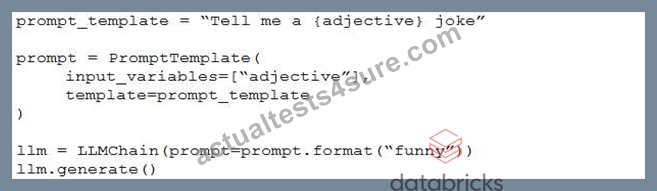
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.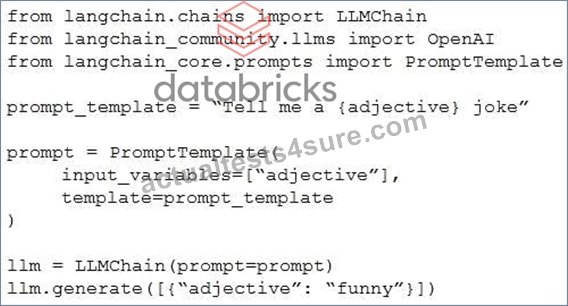
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: A
Explanation:
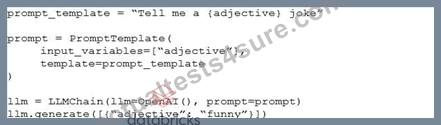
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
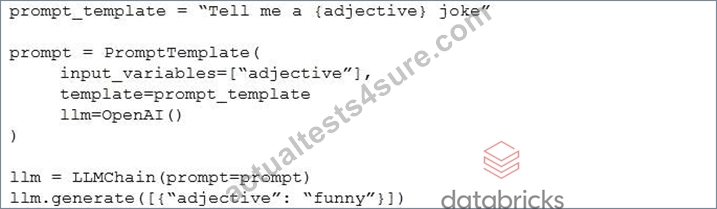
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
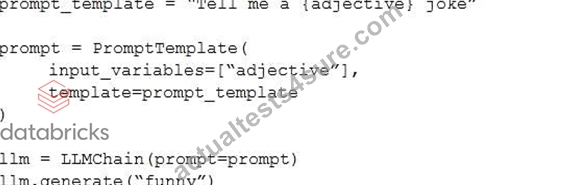
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 32
A Generative AI Engineer is building an interactive catalog for a company's inventory system that allows users to search for any item using a plain-text description. There are currently about 17,000 items, and new items are not frequently added. They need a solution that will be the most cost-effective and easy for the company to maintain.
Which solution should the engineer choose?
Answer: B
Explanation:
Option D best matches the small catalog, infrequent updates, and maintenance requirements. Databricks- managed embeddings remove the need to build and maintain a separate embedding-generation pipeline. A Delta Sync index connects the searchable content to its source Delta table. Triggered synchronization updates the index when explicitly invoked, making it suitable when inventory changes are occasional. Continuous synchronization maintains a running streaming pipeline and therefore introduces additional synchronization costs that this scenario does not justify. Self-managed embeddings add engineering responsibilities without a stated benefit. Storage-optimized endpoints primarily address much larger vector collections. Triggered synchronization reduces synchronization overhead; it does not eliminate the separate costs of serving the vector index or computing embeddings. Databricks documentation
NEW QUESTION # 33
A Generative AI Engineer is integrating Mosaic AI Vector Search into a Retrieval-Augmented Generation (RAG) system. The source data, comprising simple text entries, is stored in a Delta table. To simplify the workflow, the engineer plans to use an embedding model served via a Mosaic AI Model Serving endpoint to automatically compute embeddings during data synchronization from the Delta table to the vector search index.
Which method should the engineer use to achieve this integration?
Answer: D
Explanation:
A Delta Sync index with managed embeddings supports the workflow described. The engineer identifies the source text column and configures the embedding model endpoint. Databricks computes embeddings as part of synchronization and maintains the corresponding searchable index. This removes the requirement to calculate vectors independently and write them into the source table before indexing. With self-managed embeddings, the application or upstream pipeline must already provide the embedding vectors. A Direct Vector Access index requires explicit updates through an API or SDK and does not automatically synchronize with the source Delta table. "Hybrid embedding computing" is not the relevant index configuration; hybrid search combines retrieval techniques. Managed embeddings and Delta synchronization therefore address both automatic vector generation and source-data integration. Databricks documentation
NEW QUESTION # 34
A Generative Al Engineer is building an LLM-based application that has an important transcription (speech-to-text) task. Speed is essential for the success of the application Which open Generative Al models should be used?
Answer: B
Explanation:
The task requires an open generative AI model for a transcription (speech-to-text) task where speed is essential. Let's assess the options based on their suitability for transcription and performance characteristics, referencing Databricks' approach to model selection.
* Option A: Llama-2-70b-chat-hf
* Llama-2 is a text-based LLM optimized for chat and text generation, not speech-to-text. It lacks transcription capabilities.
* Databricks Reference:"Llama models are designed for natural language generation, not audio processing"("Databricks Model Catalog").
* Option B: MPT-30B-Instruct
* MPT-30B is another text-based LLM focused on instruction-following and text generation, not transcription. It's irrelevant for speech-to-text tasks.
* Databricks Reference: No specific mention, but MPT is categorized under text LLMs in Databricks' ecosystem, not audio models.
* Option C: DBRX
* DBRX, developed by Databricks, is a powerful text-based LLM for general-purpose generation.
It doesn't natively support speech-to-text and isn't optimized for transcription.
* Databricks Reference:"DBRX excels at text generation and reasoning tasks"("Introducing DBRX," 2023)-no mention of audio capabilities.
* Option D: whisper-large-v3 (1.6B)
* Whisper, developed by OpenAI, is an open-source model specifically designed for speech-to-text transcription. The "large-v3" variant (1.6 billion parameters) balances accuracy and efficiency, with optimizations for speed via quantization or deployment on GPUs-key for the application's requirements.
* Databricks Reference:"For audio transcription, models like Whisper are recommended for their speed and accuracy"("Generative AI Cookbook," 2023). Databricks supports Whisper integration in its MLflow or Lakehouse workflows.
Conclusion: OnlyD. whisper-large-v3is a speech-to-text model, making it the sole suitable choice. Its design prioritizes transcription, and its efficiency (e.g., via optimized inference) meets the speed requirement, aligning with Databricks' model deployment best practices.
NEW QUESTION # 35
......
We strongly advise you to buy our windows software of the Databricks-Generative-AI-Engineer-Associate study materials, which can simulate the real test environment. There is no doubt that you will never feel bored on learning our Databricks-Generative-AI-Engineer-Associate practice materials because of the smooth operation. You will find that learning is becoming interesting and easy. During the operation of the Databricks-Generative-AI-Engineer-Associate Study Materials on your computers, the running systems of the Databricks-Generative-AI-Engineer-Associate study guide will be flexible, which saves you a lot of troubles and help you concentrate on study.
Databricks-Generative-AI-Engineer-Associate Valid Test Testking: https://www.actualtests4sure.com/Databricks-Generative-AI-Engineer-Associate-test-questions.html