Die Microsoft DP-750 Dumps von PrüfungFrage sind die Unterlagen, die von vielen Kadidaten geprüft sind. Und es kann die sehr hohe Durchlaufrate garantieren. Wenn Sie nach der Nutzung der Dumps bei der Microsoft DP-750 Zertifizierung durchgefallen sind, geben wir PrüfungFrage Ihnen voll Geld zurück. Oder können Sie auch die kostlosen aktualisierten Dumps bekommen. Mit der Garantie sorgen Sie sich bitte nicht.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
Um immer die besten IT-Zertifizierung Dumps für Sie zu bieten, verbessern wir PrüfungFrage immer die Qualität der Microsoft DP-750 Dumps und aktualisieren sie nach den neuesten Prüfungsvorschriften. PrüfungFrage ist Ihre beste Wahl auf dem heutigen Markt. Wenn Sie nicht glauben, können Sie nach anderen erkündigen. Es gibt unbedingt jemanden, der unsere PrüfungFrage Prüfungsunterlagen früher benutzt hat. Wir versprechen Ihnen die beste Nachschläge, einmal die Microsoft DP-750 Prüfung zu bestehen.
96. Frage
You have an Azure Databricks workspace that contains a cluster named Cluster1. Cluster1 has the following characteristics:
* Configured as a single node cluster
* Uses a general purpose virtual machine node type
The cluster runtime environment has the following configurations:
* Uses Databricks Runtime for Machine Learning (Databricks Runtime Ml)
* Includes common machine learning libraries
* Supports Python workloads
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.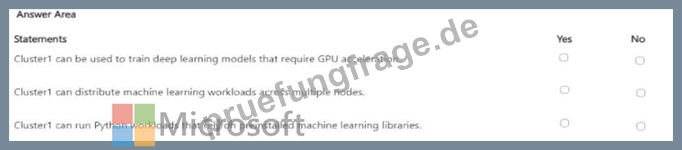
Antwort:
Begründung:
Explanation: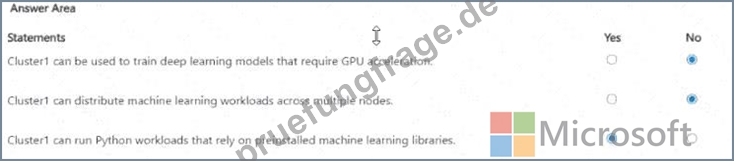
The first statement is No . Although Databricks Runtime ML includes machine learning and deep-learning libraries, GPU acceleration also requires a GPU-enabled virtual machine node type and a compatible GPU runtime. Cluster1 uses a general-purpose node type, which provides CPU-based compute rather than GPU acceleration. Microsoft Learn The second statement is No . A single-node cluster has no separate worker nodes. The driver operates as both the master and worker, and Spark runs locally. Consequently, Cluster1 cannot distribute machine learning processing across multiple nodes. A multi-node cluster would be required for distributed workloads.
Microsoft Learn
The third statement is Yes . Databricks Runtime ML provides a ready-to-use machine learning environment containing commonly used libraries such as scikit-learn, TensorFlow, PyTorch, XGBoost, and MLflow.
Because Cluster1 supports Python, Python workloads can import and use these preinstalled libraries without requiring each package to be installed separately.
97. Frage
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.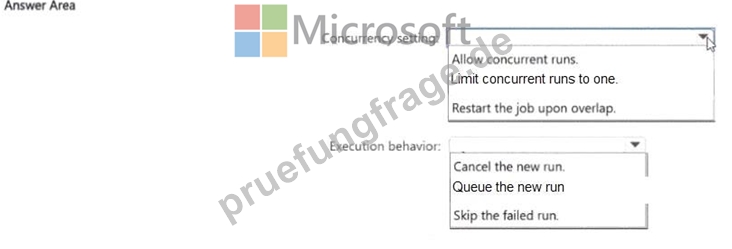
Antwort:
Begründung: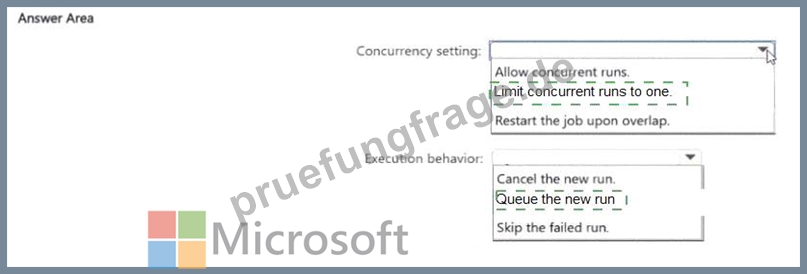
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to 'Skip' (or 'Allow only one concurrent run'). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to 'Skip' is 'Wait' (queue the new run), which ensures every scheduled run eventually executes
- but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
98. Frage
You have an Azure Databricks account that contains a single workspace named Workspace1. Workspace1 is enabled for Unity Catalog.
You discover that data access events for Unity Catalog tables fail to appear in the logs.
You need to ensure that all the data access events are captured centrally for auditing purposes. The log data must be available for analysis as quickly as possible.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Antwort:
Begründung: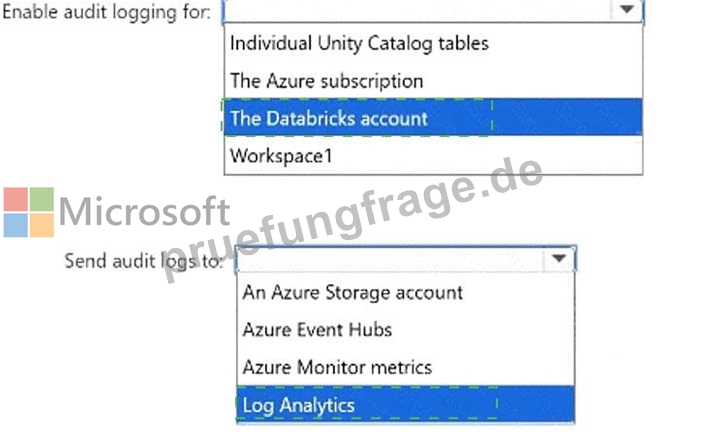
Explanation:
Enable audit logging for: The Databricks account
Send audit logs to: Log Analytics
Enabling audit logging at the Databricks account level provides centralized coverage of account and workspace activities, including Unity Catalog data-access events. Enabling logging only for Workspace1 would provide a narrower configuration and would not offer the same centralized account-level auditing model. Individual Unity Catalog tables and the Azure subscription are not the appropriate Databricks audit- log scope selections. Log Analytics is the suitable destination because it supports rapid ingestion and immediate querying of log records through Azure Monitor Logs. Auditors can search, filter, correlate, and analyze the captured events without first developing a separate data-processing solution. An Azure Storage account is more suitable for inexpensive archival, while Event Hubs is primarily a streaming transport that normally requires an additional consumer before investigators can analyze the records.
99. Frage
You have an Azure Databricks workspace that contains multiple all-purpose clusters. You discover that some clusters remain idle for long periods after users finish their work. You need to reduce compute costs without affecting active workloads. What should you do?
Antwort: B
Begründung:
The correct answer is D - configure automatic termination.
The problem is specific: clusters sit idle after users finish working but nobody manually shuts them down.
Automatic termination solves this directly - once a cluster has been idle for the configured period (no running commands, no attached notebooks with active execution), it shuts itself down. You eliminate the idle cost without any manual intervention and without affecting any workload that is actually running.
Option A (convert to job clusters) would force users off interactive all-purpose clusters, disrupting their development workflow. Option B (spot instances) reduces the hourly rate while a cluster is running but does nothing about the idle-time problem - a cheaper idle cluster is still waste. Option C (enable autoscaling) reduces the number of workers during light load but keeps the cluster alive at the minimum node count. It saves some cost but doesn't fully eliminate idle spend the way auto-termination does.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#auto-termination
100. Frage
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Antwort: A
Begründung:
You should enable schema evolution to resolve this problem. In Lakeflow Spark Declarative Pipelines (SDP)-formerly known as Delta Live Tables (DLT)-schema evolution automatically updates the schema of your managed Delta tables when new columns are detected in the source data.
Prevents Pipeline Failures: By default, Delta Lake applies strict schema enforcement to prevent bad or mismatched data from corrupting your tables. When the source data layout changes (e.g., column creep), the pipeline will throw a runtime error and fail the write operation.
Automates Ingestion Flexibility: Activating schema evolution allows Delta Lake to automatically adapt by adding the new columns to the target managed table layout dynamically, eliminating manual intervention or explicit ALTER TABLE operations.
Reference:
https://learn.microsoft.com/en-us/azure/databricks/ldp/unity-catalog
101. Frage
......
Aufgrund der großen Übereinstimmung mit den echten Prüfungsfragen- und Antworten können wir Ihnen 100%-Pass-Garantie versprechen. Wir aktualisieren jeden Tag nach den Informationen von Prüfungsabsolventen oder Mitarbeiter von Testcentern. unsere Prüfungsfragen und Antworten zu Microsoft DP-750 (Implementing Data Engineering Solutions Using Azure Databricks). Wir extrahieren jeden Tag die Informationen der tatsächlichen Prüfungen und integrieren in unsere Produkte integrieren.
DP-750 Echte Fragen: https://www.pruefungfrage.de/DP-750-dumps-deutsch.html