P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by SureTorrent: https://drive.google.com/open?id=12cIVvAmvIhjGzhWrIAzzMRrzmNNz3jRM
Databricks-Generative-AI-Engineer-Associate Exam Dumps add vivid examples and accurate charts to stimulate those exceptional cases you may be confronted with. Databricks-Generative-AI-Engineer-Associate Guide Torrent has been known as one of the world’s leading providers of exam materials. Databricks-Generative-AI-Engineer-Associate Test Questions free updating for one year and half price for further partnerships.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Generative AI Engineer Associate |
| Exam Duration: | 90 minutes |
| Available Languages: | English, Korean, Portuguese (Brazil), Japanese |
| Exam Price: | $200 USD |
| Related Certifications: | Databricks Certified Data Engineer Associate Databricks Certified Machine Learning Associate |
| Real Exam Qty: | 45 |
| Certificate Validity Period: | 2 years |
| Passing Score: | Scaled Score (approx. 70%) |
| Exam Format: | Multiple Choice, Multiple Select |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online (Proctored) or Test Center |
| Pre Condition: | None (Recommended: 6+ months hands-on experience) |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Reliable Databricks-Generative-AI-Engineer-Associate Test Price <<
The Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) prep material is available in three versions. Databricks-Generative-AI-Engineer-Associate Practice exams and PDF questions are available at SureTorrent so that users can meet their training needs and pass the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam on the first try. The philosophy of SureTorrent behind offering Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) prep material in three formats is helping students meet their unique learning needs.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 11
Databricks offers a number of built-in AI judges that provide metrics and rationale for different types of quality issues a Generative AI application may have.
Which of the following pairs of judges both require a ground-truth label in the evaluation dataset field expected_response to execute?
Answer: A
Explanation:
In the Agent Evaluation terminology used by this question, correctness compares the generated response with the expected answer, while context_sufficiency determines whether the retrieved context contains enough information to produce that expected answer. Both therefore depend on ground-truth information supplied through expected_response. Groundedness instead examines whether the response is supported by the retrieved context; it does not inherently need a reference answer. Chunk relevance and relevance to the query assess alignment with the user's request, while guideline adherence evaluates compliance with specified instructions. Databricks explicitly distinguishes the ground-truth-dependent judges in its migration documentation. In MLflow 3, names and schemas have evolved, including expectations.expected_response and explicitly selected scorers, so the question should be interpreted using its stated legacy judge terminology.
Databricks documentation
NEW QUESTION # 12
A team wants to serve a code generation model as an assistant for their software developers. It should support multiple programming languages. Quality is the primary objective.
Which of the Databricks Foundation Model APIs, or models available in the Marketplace, would be the best fit?
Answer: A
Explanation:
For a code generation model that supports multiple programming languages and where quality is the primary objective, CodeLlama-34B is the most suitable choice. Here's the reasoning:
Specialization in Code Generation:
CodeLlama-34B is specifically designed for code generation tasks. This model has been trained with a focus on understanding and generating code, which makes it particularly adept at handling various programming languages and coding contexts.
Capacity and Performance:
The "34B" indicates a model size of 34 billion parameters, suggesting a high capacity for handling complex tasks and generating high-quality outputs. The large model size typically correlates with better understanding and generation capabilities in diverse scenarios.
Suitability for Development Teams:
Given that the model is optimized for code, it will be able to assist software developers more effectively than general-purpose models. It understands coding syntax, semantics, and the nuances of different programming languages.
Why Other Options Are Less Suitable:
A (Llama2-70b): While also a large model, it's more general-purpose and may not be as fine-tuned for code generation as CodeLlama.
B (BGE-large): This model may not specifically focus on code generation.
C (MPT-7b): Smaller than CodeLlama-34B and likely less capable in handling complex code generation tasks at high quality.
Therefore, for a high-quality, multi-language code generation application, CodeLlama-34B (option D) is the best fit.
NEW QUESTION # 13
A Generative AI Engineer is designing a chatbot for a gaming company that aims to engage users on its platform while its users play online video games.
Which metric would help them increase user engagement and retention for their platform?
Answer: C
Explanation:
In the context of designing a chatbot to engage users on a gaming platform, diversity of responses (option B) is a key metric to increase user engagement and retention. Here's why:
Diverse and Engaging Interactions:
A chatbot that provides varied and interesting responses will keep users engaged, especially in an interactive environment like a gaming platform. Gamers typically enjoy dynamic and evolving conversations, and diversity of responses helps prevent monotony, encouraging users to interact more frequently with the bot.
Increasing Retention:
By offering different types of responses to similar queries, the chatbot can create a sense of novelty and excitement, which enhances the user's experience and makes them more likely to return to the platform.
Why Other Options Are Less Effective:
A (Randomness): Random responses can be confusing or irrelevant, leading to frustration and reducing engagement.
C (Lack of Relevance): If responses are not relevant to the user's queries, this will degrade the user experience and lead to disengagement.
D (Repetition of Responses): Repetitive responses can quickly bore users, making the chatbot feel uninteresting and reducing the likelihood of continued interaction.
Thus, diversity of responses (option B) is the most effective way to keep users engaged and retain them on the platform.
NEW QUESTION # 14
A Generative Al Engineer needs to design an LLM pipeline to conduct multi-stage reasoning that leverages external tools. To be effective at this, the LLM will need to plan and adapt actions while performing complex reasoning tasks.
Which approach will do this?
Answer: B
Explanation:
The task requires an LLM pipeline for multi-stage reasoning with external tools, necessitating planning, adaptability, and complex reasoning. Let's evaluate the options based on Databricks' recommendations for advanced LLM workflows.
* Option A: Train the LLM to generate a single, comprehensive response without interacting with any external tools, relying solely on its pre-trained knowledge
* This approach limits the LLM to its static knowledge base, excluding external tools and multi- stage reasoning. It can't adapt or plan actions dynamically, failing the requirements.
* Databricks Reference:"External tools enhance LLM capabilities beyond pre-trained knowledge" ("Building LLM Applications with Databricks," 2023).
* Option B: Implement a framework like ReAct which allows the LLM to generate reasoning traces and perform task-specific actions that leverage external tools if necessary
* ReAct (Reasoning + Acting) combines reasoning traces (step-by-step logic) with actions (e.g., tool calls), enabling the LLM to plan, adapt, and execute complex tasks iteratively. This meets all requirements: multi-stage reasoning, tool use, and adaptability.
* Databricks Reference:"Frameworks like ReAct enable LLMs to interleave reasoning and external tool interactions for complex problem-solving"("Generative AI Cookbook," 2023).
* Option C: Encourage the LLM to make multiple API calls in sequence without planning or structuring the calls, allowing the LLM to decide when and how to use external tools spontaneously
* Unstructured, spontaneous API calls lack planning and may lead to inefficient or incorrect tool usage. This doesn't ensure effective multi-stage reasoning or adaptability.
* Databricks Reference: Structured frameworks are preferred:"Ad-hoc tool calls can reduce reliability in complex tasks"("Building LLM-Powered Applications").
* Option D: Use a Chain-of-Thought (CoT) prompting technique to guide the LLM through a series of reasoning steps, then manually input the results from external tools for the final answer
* CoT improves reasoning but relies on manual tool interaction, breaking automation and adaptability. It's not a scalable pipeline solution.
* Databricks Reference:"Manual intervention is impractical for production LLM pipelines" ("Databricks Generative AI Engineer Guide").
Conclusion: Option B (ReAct) is the best approach, as it integrates reasoning and tool use in a structured, adaptive framework, aligning with Databricks' guidance for complex LLM workflows.
NEW QUESTION # 15
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: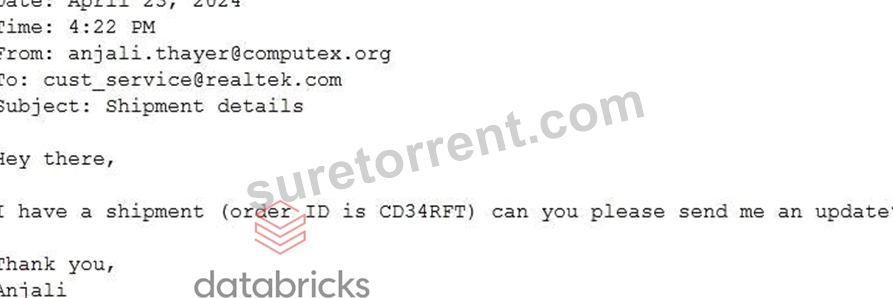
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: D
Explanation:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 16
......
Databricks-Generative-AI-Engineer-Associate Latest Exam Forum: https://www.suretorrent.com/Databricks-Generative-AI-Engineer-Associate-exam-guide-torrent.html
DOWNLOAD the newest SureTorrent Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=12cIVvAmvIhjGzhWrIAzzMRrzmNNz3jRM