ユニークなDatabricks-Certified-Data-Engineer-Professional模擬試験問題集 &合格スムーズDatabricks-Certified-Data-Engineer-Professional教育資料 |大人気Databricks-Certified-Data-Engineer-Professional真実試験

ちなみに、MogiExam Databricks-Certified-Data-Engineer-Professionalの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1GBnJMCA7YQUOP-_ouAJh6O7V-WxjWPA5
もし、あなたもDatabricks-Certified-Data-Engineer-Professional試験に合格したいです。しかし、どんな資料を選択したらいいですか?お勧めしたいのはDatabricks-Certified-Data-Engineer-Professional試験問題集です。購入する前に、DatabricksのウエブサイトでDatabricks-Certified-Data-Engineer-Professional試験問題集のデモをダウンロードしてみると、あなたはきっとDatabricks-Certified-Data-Engineer-Professional試験問題集に魅了されます。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Data Modeling and Storage | 20% | - File Formats
- Storage Optimization
- Data Modeling
|
| Topic 2: Databricks Lakehouse Platform | 24% | - Unity Catalog
- Delta Lake
- Lakehouse Architecture
- Data Management
|
| Topic 3: Data Processing | 28% | - Spark SQL
- Data Transformation
- Structured Streaming
- ETL Pipelines
|
| Topic 4: Monitoring and Troubleshooting | 16% | - Troubleshooting
- Performance Optimization
- Monitoring
|
| Topic 5: Data Quality and Governance | 12% | - Governance
- Data Lineage
- Data Quality
|
>> Databricks-Certified-Data-Engineer-Professional模擬試験問題集 <<
人気のあるDatabricks-Certified-Data-Engineer-Professional模擬試験問題集 | 素晴らしい合格率のDatabricks-Certified-Data-Engineer-Professional Exam | 信頼できるDatabricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam
Databricks-Certified-Data-Engineer-Professional認定は、特定の知識分野の習熟度を示すことができます。これは、認定として一般大衆に国際的に認められ、受け入れられています。 Databricks-Certified-Data-Engineer-Professional認定は非常に高いため、取得が容易ではありません。時間とエネルギーを投資する必要があります。自分で厳密にリクエストできるかどうかわからない場合は、Databricks-Certified-Data-Engineer-Professionalテスト資料が役立ちます。 Databricks-Certified-Data-Engineer-Professional試験の高い合格率で98%以上の場合、Databricks-Certified-Data-Engineer-Professional試験は簡単に合格します。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q96-Q101):
質問 # 96
Which statement describes Delta Lake Auto Compaction?
- A. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
- B. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
- C. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
- D. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
- E. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
正解:A
解説:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB. Auto Compaction only compacts files that have not been compacted previously.
質問 # 97
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats. After converting a subset of data to Delta Lake, they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join, whereas queries on legacy formats used Sort Merge Joins. The queries reading Delta Lake data also scanned less data. Which reason could be attributed to the difference in query performance?
- A. The queries against the ORC tables leveraged the dynamic data skipping optimization but not the dynamic file pruning optimization.
- B. The queries against the Delta Lake tables were able to leverage the dynamic file pruning optimization.
- C. Delta Lake enables data skipping and file pruning using a vectorized Parquet reader.
- D. Shuffle Hash Joins are always more efficient than Sort Merge Joins.
正解:C
解説:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage, data skipping, and file pruning. According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters, a process called data skipping and file pruning. Additionally, Delta uses a vectorized Parquet reader, which reduces I/O and CPU overhead. Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
質問 # 98
A data engineer is configuring a pipeline that will potentially see late-arriving, duplicate records.
In addition to de-duplicating records within the batch, which of the following approaches allows the data engineer to deduplicate data against previously processed records as it is inserted into a Delta table?
- A. Perform a full outer join on a unique key and overwrite existing data.
- B. VACUUM the Delta table after each batch completes.
- C. Set the configuration delta.deduplicate = true.
- D. Rely on Delta Lake schema enforcement to prevent duplicate records.
- E. Perform an insert-only merge with a matching condition on a unique key.
正解:E
解説:
To deduplicate data against previously processed records as it is inserted into a Delta table, you can use the merge operation with an insert-only clause. This allows you to insert new records that do not match any existing records based on a unique key, while ignoring duplicate records that match existing records. For example, you can use the following syntax:
MERGE INTO target_table USING source_table ON target_table.unique_key = source_table.unique_key WHEN NOT MATCHED THEN INSERT * This will insert only the records from the source table that have a unique key that is not present in the target table, and skip the records that have a matching key. This way, you can avoid inserting duplicate records into the Delta table.
質問 # 99
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
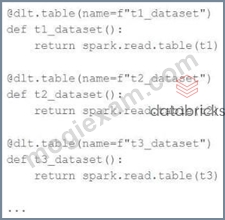
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
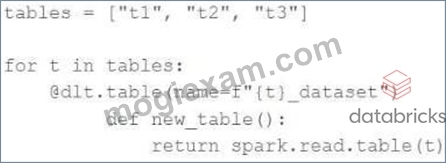
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- B. Wrap the for loop inside another table definition, using generalized names and properties to replace with those from the inner table definition.
- C. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- D. Move the table definition into a separate function, and make calls to this function using different input parameters inside the for loop.
正解:D
解説:
In the provided refactored code, the for loop dynamically attempts to define multiple tables, but the use of a loop within the DLT (@dlt.table) decorator does not work properly because it results in a single function reference being overwritten for each iteration. This leads to an incorrect DAG because all the table definitions end up pointing to the last iteration of the loop.
質問 # 100
A data engineer is performing a join operating to combine values from a static userlookup table with a streaming DataFrame streamingDF.
Which code block attempts to perform an invalid stream-static join?
- A. streamingDF.join(userLookup, ["user_id"], how="left")
- B. userLookup.join(streamingDF, ["userid"], how="inner")
- C. streamingDF.join(userLookup, ["user_id"], how="outer")
- D. streamingDF.join(userLookup, ["userid"], how="inner")
- E. userLookup.join(streamingDF, ["user_id"], how="right")
正解:C
解説:
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html#support- matrix-for-joins-in-streaming-queries
質問 # 101
......
あなたはMogiExamが提供したDatabricksのDatabricks-Certified-Data-Engineer-Professional認定試験の問題集だけ利用して合格することが問題になりません。ほかの人を超えて業界の中で最大の昇進の機会を得ます。もしあなたはMogiExamの商品がショッピング車に入れて24のインターネットオンライン顧客サービスを提供いたします。問題があったら気軽にお問いください、
Databricks-Certified-Data-Engineer-Professional教育資料: https://www.mogiexam.com/Databricks-Certified-Data-Engineer-Professional-exam.html
- Databricks-Certified-Data-Engineer-Professional日本語版受験参考書 🏂 Databricks-Certified-Data-Engineer-Professional対応資料 ❤️ Databricks-Certified-Data-Engineer-Professional PDF問題サンプル 🚅 [ Databricks-Certified-Data-Engineer-Professional ]を無料でダウンロード⮆ www.passtest.jp ⮄で検索するだけDatabricks-Certified-Data-Engineer-Professional認証pdf資料
- 試験の準備方法-効率的なDatabricks-Certified-Data-Engineer-Professional模擬試験問題集試験-有難いDatabricks-Certified-Data-Engineer-Professional教育資料 🤜 検索するだけで{ www.goshiken.com }から⇛ Databricks-Certified-Data-Engineer-Professional ⇚を無料でダウンロードDatabricks-Certified-Data-Engineer-Professional試験情報
- Databricks-Certified-Data-Engineer-Professional予想試験 💒 Databricks-Certified-Data-Engineer-Professional試験情報 ⛲ Databricks-Certified-Data-Engineer-Professional試験関連赤本 💉 ウェブサイト「 www.goshiken.com 」を開き、“ Databricks-Certified-Data-Engineer-Professional ”を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional資料的中率
- Databricks-Certified-Data-Engineer-Professional対応問題集 😦 Databricks-Certified-Data-Engineer-Professional認証pdf資料 📝 Databricks-Certified-Data-Engineer-Professional認定資格試験問題集 ⚽ 今すぐ✔ www.goshiken.com ️✔️を開き、➽ Databricks-Certified-Data-Engineer-Professional 🢪を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional試験関連赤本
- Databricks-Certified-Data-Engineer-Professional認定資格試験問題集 🦁 Databricks-Certified-Data-Engineer-Professional日本語版受験参考書 🍇 Databricks-Certified-Data-Engineer-Professional練習問題 🛴 ➥ Databricks-Certified-Data-Engineer-Professional 🡄の試験問題は➤ www.it-passports.com ⮘で無料配信中Databricks-Certified-Data-Engineer-Professional試験関連赤本
- 試験の準備方法-効率的なDatabricks-Certified-Data-Engineer-Professional模擬試験問題集試験-有難いDatabricks-Certified-Data-Engineer-Professional教育資料 🦘 ☀ www.goshiken.com ️☀️には無料の⮆ Databricks-Certified-Data-Engineer-Professional ⮄問題集がありますDatabricks-Certified-Data-Engineer-Professional試験関連赤本
- ユニーク-最新のDatabricks-Certified-Data-Engineer-Professional模擬試験問題集試験-試験の準備方法Databricks-Certified-Data-Engineer-Professional教育資料 🏕 サイト▶ www.mogiexam.com ◀で「 Databricks-Certified-Data-Engineer-Professional 」問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional予想試験
- 素晴らしいDatabricks-Certified-Data-Engineer-Professional模擬試験問題集 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional教育資料 | 信頼できるDatabricks-Certified-Data-Engineer-Professional真実試験 ⚔ { www.goshiken.com }サイトにて最新➡ Databricks-Certified-Data-Engineer-Professional ️⬅️問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional予想試験
- Databricks-Certified-Data-Engineer-Professional日本語版問題解説 🚴 Databricks-Certified-Data-Engineer-Professional認証pdf資料 🚞 Databricks-Certified-Data-Engineer-Professional試験復習赤本 🗳 【 www.it-passports.com 】にて限定無料の➥ Databricks-Certified-Data-Engineer-Professional 🡄問題集をダウンロードせよDatabricks-Certified-Data-Engineer-Professional試験関連赤本
- 試験の準備方法-効率的なDatabricks-Certified-Data-Engineer-Professional模擬試験問題集試験-有難いDatabricks-Certified-Data-Engineer-Professional教育資料 💺 ✔ www.goshiken.com ️✔️は、⏩ Databricks-Certified-Data-Engineer-Professional ⏪を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Data-Engineer-Professional練習問題
- Databricks-Certified-Data-Engineer-Professional復習攻略問題 🛥 Databricks-Certified-Data-Engineer-Professional技術問題 🟠 Databricks-Certified-Data-Engineer-Professional PDF問題サンプル 😾 《 www.passtest.jp 》は、✔ Databricks-Certified-Data-Engineer-Professional ️✔️を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Data-Engineer-Professional試験時間
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, telegra.ph, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
ちなみに、MogiExam Databricks-Certified-Data-Engineer-Professionalの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1GBnJMCA7YQUOP-_ouAJh6O7V-WxjWPA5