BTW, DOWNLOAD part of Exam4Free MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1u66meFIl60tZBJZ4GhAV1u_E9c2ZxJPV
One of the best features of Amazon MLA-C01 exam dumps is its AWS Certified Machine Learning Engineer - Associate exam passing a money-back guarantee. Now with Exam4Free MLA-C01 exam dumps your investment is secured with a money-back guarantee. If you fail in Amazon MLA-C01 Exam despite using Exam4Free Exam Questions you can claim your paid amount.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: ML Model Development | 26% | - Select appropriate modeling approach
|
| Topic 2: Deployment and Orchestration of ML Workflows | 22% | - Automate and orchestrate ML pipelines
|
| Topic 3: Data Preparation for Machine Learning | 28% | - Ingest and store data
|
| Topic 4: ML Solution Monitoring, Maintenance, and Security | 24% | - Secure ML solutions and resources
|
All these three Exam4Free AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam questions formats are easy to use and perfectly work with all devices, operating systems, and the latest web browsers. So rest assured that with the MLA-C01 Exam Dumps you will get everything that you need to learn, prepare and pass the challenging MLA-C01 exam with good scores.
NEW QUESTION # 36
A company has a large, unstructured dataset. The dataset includes many duplicate records across several key attributes.
Which solution on AWS will detect duplicates in the dataset with the LEAST code development?
Answer: A
NEW QUESTION # 37
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
* Feature splitting
* Logarithmic transformation
* One-hot encoding
* Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)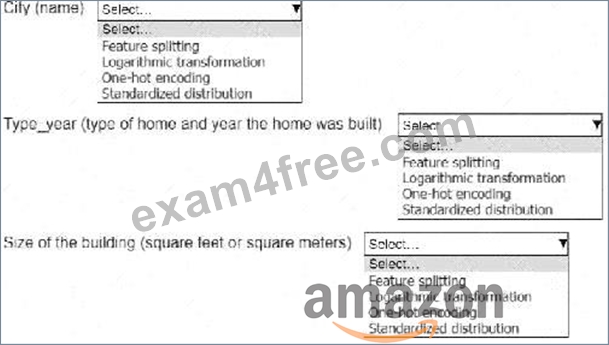
Answer:
Explanation: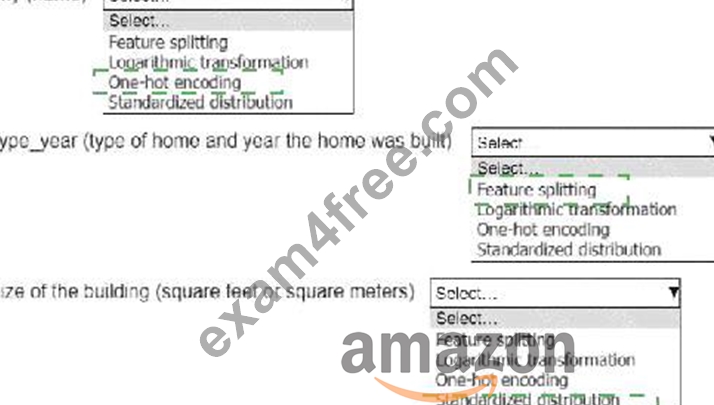
Explanation:
City (name): One-hot encoding
Type_year (type of home and year the home was built): Feature splitting Size of the building (square feet or square meters): Standardized distribution City (name): One-hot encoding Why? The " City " is a categorical feature (non-numeric), so one-hot encoding is used to transform it into a numeric format. This encoding creates binary columns for each unique category (e.g., cities like " New York " or " Los Angeles " ), which the model can interpret.
Type_year (type of home and year the home was built): Feature splitting Why? " Type_year " combines two pieces of information into one column, which could confuse the model.
Feature splitting separates this column into two distinct features: " Type of home " and " Year built, " enabling the model to process each feature independently.
Size of the building (square feet or square meters): Standardized distribution Why? Size is a continuous numerical variable, and standardization (scaling the feature to have a mean of 0 and a standard deviation of 1) ensures that the model treats it fairly compared to other features, avoiding bias from differences in feature scale.
By applying these feature engineering techniques, the ML engineer can ensure that the input data is correctly formatted and optimized for the model to make accurate predictions.
NEW QUESTION # 38
An ML engineer has developed a binary classification model outside of Amazon SageMaker. The ML engineer needs to make the model accessible to a SageMaker Canvas user for additional tuning.
The model artifacts are stored in an Amazon S3 bucket. The ML engineer and the Canvas user are part of the same SageMaker domain.
Which combination of requirements must be met so that the ML engineer can share the model with the Canvas user? (Choose two.)
Answer: C,D
Explanation:
The SageMaker Canvas user needs permissions to access the Amazon S3 bucket where the model artifacts are stored to retrieve the model for use in Canvas.
Registering the model in the SageMaker Model Registry allows the model to be tracked and managed within the SageMaker ecosystem. This makes it accessible for tuning and deployment through SageMaker Canvas.
This combination ensures proper access control and integration within SageMaker, enabling the Canvas user to work with the model.
NEW QUESTION # 39
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company must implement a manual approval-based workflow to ensure that only approved models can be deployed to production endpoints.
Which solution will meet this requirement?
Answer: D
Explanation:
To implement a manual approval-based workflow ensuring that only approved models are deployed to production endpoints, Amazon SageMaker provides integrated tools such asSageMaker Pipelinesand the SageMaker Model Registry.
SageMaker Pipelinesis a robust service for building, automating, and managing end-to-end machine learning workflows. It facilitates the orchestration of various steps in the ML lifecycle, including data preprocessing, model training, evaluation, and deployment. By integrating with theSageMaker Model Registry, it enables seamless tracking and management of model versions and their approval statuses.
Implementation Steps:
* Define the Pipeline:
* Create a SageMaker Pipeline encompassing steps for data preprocessing, model training, evaluation, and registration of the model in the Model Registry.
* Incorporate aCondition Stepto assess model performance metrics. If the model meets predefined criteria, proceed to the next step; otherwise, halt the process.
* Register the Model:
* Utilize theRegisterModelstep to add the trained model to the Model Registry.
* Set the ModelApprovalStatus parameter to PendingManualApproval during registration. This status indicates that the model awaits manual review before deployment.
* Manual Approval Process:
* Notify the designated approver upon model registration. This can be achieved by integrating Amazon EventBridge to monitor registration events and trigger notifications via AWS Lambda functions.
* The approver reviews the model's performance and, if satisfactory, updates the model's status to Approved using the AWS SDK or through the SageMaker Studio interface.
* Deploy the Approved Model:
* Configure the pipeline to automatically deploy models with an Approved status to the production endpoint. This can be managed by adding deployment steps conditioned on the model's approval status.
Advantages of This Approach:
* Automated Workflow:SageMaker Pipelines streamline the ML workflow, reducing manual interventions and potential errors.
* Governance and Compliance:The manual approval step ensures that only thoroughly evaluated models are deployed, aligning with organizational standards.
* Scalability:The solution supports complex ML workflows, making it adaptable to various project requirements.
By implementing this solution, the company can establish a controlled and efficient process for deploying models, ensuring that only approved versions reach production environments.
References:
* Automate the machine learning model approval process with Amazon SageMaker Model Registry and Amazon SageMaker Pipelines
* Update the Approval Status of a Model - Amazon SageMaker
NEW QUESTION # 40
An ML model is deployed in production. The model has performed well and has met its metric thresholds for months.
An ML engineer who is monitoring the model observes a sudden degradation. The performance metrics of the model are now below the thresholds.
What could be the cause of the performance degradation?
Answer: A
Explanation:
A sudden drop in model performance after a long period of stability is a classic indicator of data drift.
According to AWS ML documentation, production data distribution drift occurs when the statistical properties of incoming data change over time compared to the training dataset.
This drift can be caused by changes in user behavior, market conditions, seasonal trends, or upstream data pipelines. When drift occurs, the model's learned patterns no longer align with real-world data, leading to degraded accuracy and other performance metrics.
Lack of training data (Option A) and overfitting (Option D) are issues that typically manifest during initial training, not after months of stable production performance. Compute constraints (Option C) may affect latency but do not usually cause sustained accuracy degradation.
AWS recommends using SageMaker Model Monitor to detect such drift and trigger retraining workflows.
Therefore, drift in the production data distribution is the most likely cause of the observed performance degradation.
NEW QUESTION # 41
......
The Exam4Free is a trusted and reliable platform that has been helping the AWS Certified Machine Learning Engineer - Associate (MLA-C01) certification exam candidates for many years. Over this long time period, the Exam4Free MLA-C01 exam practice questions have helped the MLA-C01 exam candidates in their preparation and enabled them to pass the challenging exam on the first attempt. You can also trust Exam4Free MLA-C01 Exam Practice questions and start preparation with complete peace of mind and satisfaction.
Exam MLA-C01 Course: https://www.exam4free.com/MLA-C01-valid-dumps.html
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by Exam4Free: https://drive.google.com/open?id=1u66meFIl60tZBJZ4GhAV1u_E9c2ZxJPV