First and foremost, you can get the latest version of our AI-500 study materials for free during the whole year. Second, our responsible after sale service staffs are available in twenty four hours a day, seven days a week, so if you have any problem after purchasing AI-500 study materials, you can contact our after sale service staffs anywhere at any time. Finally, we have installed the most advanced operation machines in our website, so you can use credit for payment in the process of trading and register your personal information under a safe payment environment. Do not waver any more, the most effective and the Latest AI-500 Study Materials is right here waiting for you.
| Section | Weight | Objectives |
|---|---|---|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Deploy multi-agent solutions to Azure
|
| Develop multi-agent solutions in Azure | 30-35% | - Build and integrate tool ecosystems
|
| Architect multi-agent solutions | 15-20% | - Specify technology components for multi-agent solutions
|
>> Latest AI-500 Test Notes <<
We have three versions of AI-500 practice questions for you to choose: PDF version, Soft version and APP version. PDF version of AI-500 training materials is legible to read and remember, and support printing request, so you can have a print and practice in papers. Software version of AI-500 practice materials supports simulation test system, and give times of setup has no restriction. Remember this version support Windows system users only. App online version of AI-500 Exam Questions is suitable to all kinds of equipment or digital devices and supportive to offline exercise on the condition that you practice it without mobile data.
NEW QUESTION # 74
You have a multi-agent solution in Microsoft Foundry. Every request begins with the same 1,800-token instruction block and Model Context Protocol (MCP) tool definitions, and then appends a unique user message.
Input-token costs and Time to First Token (TTFT) increase during peak hours.
You need to reduce the input-token costs and TTFT for requests that share common instructions and tool definitions. The solution must meet the following requirements:
Reuse cached work only when the common prefix matches exactly.
Generate a new completion for each user request.
Minimize application changes.
Which type of caching should you use?
Answer: C
Explanation:
Prompt caching is designed for requests that share a long, identical prefix but still require a new completion for the unique user input. Azure OpenAI prompt caching reuses computation for matching prompt prefixes, reducing the effective input cost and improving Time to First Token for supported models. The stable 1,800- token instruction and MCP tool-definition block is large enough to benefit from this mechanism, and the unique user message can remain at the end so each request still generates a fresh response. Response caching would reuse an old completion, which violates the requirement. Semantic caching matches similar meaning rather than exact prompt prefixes, and retrieval caching applies to knowledge retrieval rather than model prompt processing. Because prompt caching is handled automatically for supported deployments, it also minimizes application changes. Therefore D is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Azure OpenAI - Prompt caching
NEW QUESTION # 75
You have a Microsoft Foundry resource that hosts Azure OpenAI model deployments for three projects. Each project is for a different business unit. The projects share the same Foundry resource.
You need to implement a Microsoft Cost Management view that separates the shared model spend by the project The solution must meet the following requirements:
* Use cost data that can be reconciled by using Azure Cost Management.
* Minimize manual tagging.
What should you use?
Answer: C
Explanation:
When multiple projects share one Foundry resource, grouping costs only by Azure resource cannot distinguish project consumption because the resource boundary is shared. Microsoft Foundry integrates with Azure Cost Management by attributing model usage to project metadata/tags, allowing a Cost Analysis view to filter shared resource spending by project. This supports showback or chargeback without requiring administrators to manually tag every usage event. Subscription-level service filters or meter grouping identify the service or billing meter but not which of the three business-unit projects generated the usage. Therefore a Foundry-resource-scoped Cost Analysis view filtered by the project tag is the configuration that both reconciles to Azure Cost Management and minimizes manual tagging. D remains correct. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - Manage costs
NEW QUESTION # 76
You are designing Microsoft Foundry multi-agent solution. The agents will use Agent-to-Agent (A2A) delegation and access separate Azure Storage containers within a lesource group named RG1.
You need to recommend identity components for the design. The solution must meet the following requirements:
* Eliminate stored application secrets.
* Limit the impact of a compromised agent or deployment.
Solution: Use a shared single-tenant application registration for the agents Assign Azure roles at the subscription scope. Does this meet the goal?
Answer: B
Explanation:
A shared single-tenant application registration combined with subscription-wide role assignments creates an excessively broad trust and authorization boundary. It also does not, by itself, guarantee elimination of stored credentials because an app registration can still authenticate with a client secret or certificate unless federation is configured. More importantly, compromise of any agent using the shared identity could expose resources well beyond that agent ' s assigned Storage container. Microsoft guidance favors distinct workload/agent identities and the narrowest practical Azure RBAC scope, ideally at the resource or data-resource level required by each agent. Because the proposed design uses both a shared identity and subscription-level access, it fails the blast-radius requirement and least-privilege principle. Therefore B, No, is correct. Least privilege remains the governing principle: grant only the identity, data, tool, or deployment access required for the specific operation. The selected answer preserves that boundary while still allowing the workflow to satisfy its functional requirement.
Official Microsoft reference: Microsoft Foundry agent identity
NEW QUESTION # 77
You have a Microsoft Foundry multi-agent customer support solution that retrieves grounding data from a shared vector index. The indexed corpus contains product runbooks in Markdown and support articles in HTML Both document types use a consistent hierarchical markup.
You discover that current fixed-size token chunking creates chunks that cross section boundaries.
You need to recommend a chunking approach for the ingestion pipeline. The solution must preserve existing document structure boundaries and minimize custom chunking code.
What should you recommend?
Answer: B
Explanation:
The corpus already contains reliable document hierarchy in Markdown and HTML, so the ingestion pipeline should preserve those author-defined boundaries rather than infer new ones from token counts or topic shifts.
Format-specific header splitters can divide Markdown by heading levels and HTML by structural headers, producing chunks that align with meaningful sections. This directly solves the current problem of fixed-size token chunks crossing section boundaries and requires less custom logic than building a semantic topic-shift chunker. Recursive character splitting can be configured with structure-aware separators, but it remains a more generic fallback when format-specific structure is already available. Microsoft Azure AI Search guidance recommends exploiting document structure such as headings when chunking. Therefore B is the most direct and maintainable approach. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure AI Search - structure-aware chunking and Markdown indexing
NEW QUESTION # 78
You have a production-readiness review that includes the following Microsoft Foundry Agent Service Model Context Protocol (MCP) tool configuration, discovered MCP tool metadata, and quality-gate rules.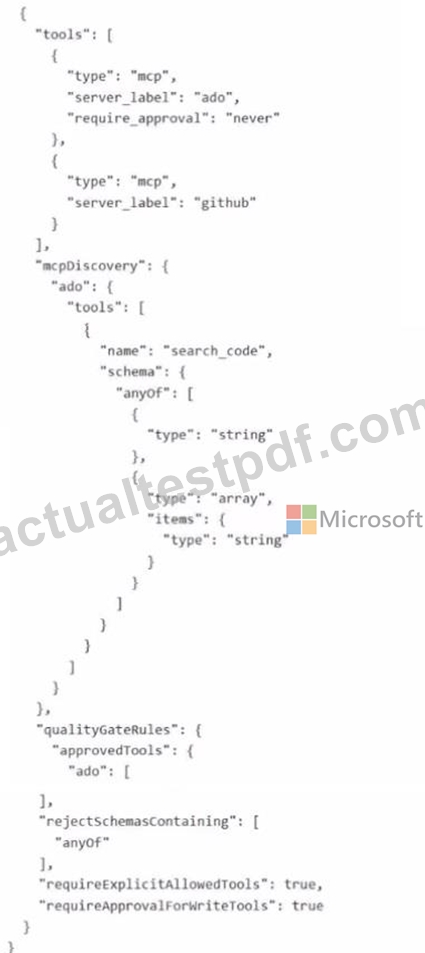
For each of the following statements, select Yes if the statement is true Otherwise, select No.
NOTE: Each correct selection is worth one point.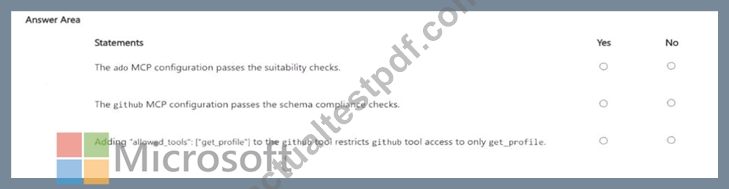
Answer:
Explanation: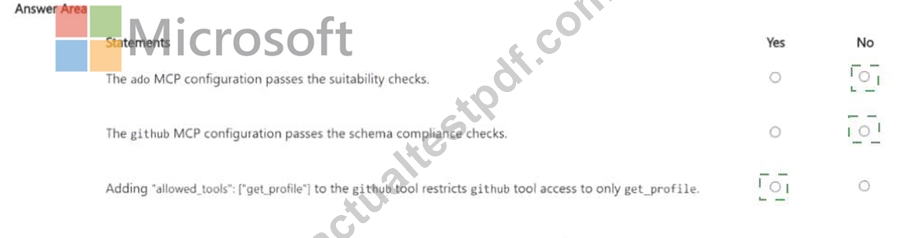
Explanation:
No / No / Yes
The ADO MCP configuration does not satisfy the stated production gate because it lacks the required allowed- tool restriction and disables approval; its discovered schema also conflicts with the gate ' s schema restrictions. The GitHub configuration likewise cannot be considered schema-compliant based on the shown metadata. The third statement, however, is true: Microsoft Foundry MCP tool configuration supports an
`allowed_tools` allowlist that limits which discovered MCP tools are exposed to the agent. Adding ` " allowed_tools " : [ " get_profile " ]` therefore restricts the GitHub MCP integration to that tool, assuming the name matches the discovered tool exactly. This control is materially stronger tha n relying on prompt instructions because excluded tools are not presented as available choices. The corrected sequence is No, No, Yes. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry agents - Model Context Protocol tools
NEW QUESTION # 79
......
Microsoft AI-500 learning materials are new but increasingly popular choices these days which incorporate the newest information and the most professional knowledge of the practice exam. All points of questions required are compiled into our Designing and Implementing Multi-Agent AI Solutions AI-500 Preparation quiz by experts. By the way, the AI-500certificate is of great importance for your future and education.
Reliable AI-500 Exam Cram: https://www.actualtestpdf.com/Microsoft/AI-500-practice-exam-dumps.html