Certified-Data-Engineer-Professional Real Questions | Certified-Data-Engineer-Professional Valid Real Test

The Certified-Data-Engineer-Professional online exam simulator is the best way to prepare for the Certified-Data-Engineer-Professional exam. RealValidExam has a huge selection of Certified-Data-Engineer-Professional dumps and topics that you can choose from. The Databricks Exam Questions are categorized into specific areas, letting you focus on the Certified-Data-Engineer-Professional subject areas you need to work on. Additionally, Databricks Certified-Data-Engineer-Professional exam dumps are constantly updated with new Certified-Data-Engineer-Professional questions to ensure you're always prepared for Certified-Data-Engineer-Professional exam.
| Section | Objectives |
|---|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
|
>> Certified-Data-Engineer-Professional Real Questions <<
Free PDF Pass-Sure Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Real Questions
Success in the Databricks Certified-Data-Engineer-Professional Exam paves the way toward high-paying jobs, promotions, and skills verification. Hundreds of Databricks Certified-Data-Engineer-Professional test takers don't get success because of using Databricks outdated dumps. Due to failure, they lose money, time, and confidence. All these losses can be prevented by using updated and real Databricks Dumps of RealValidExam.
Databricks Certified Data Engineer Professional Sample Questions (Q163-Q168):
NEW QUESTION # 163
Which Python variable contains a list of directories to be searched when trying to locate required modules?
- A. importlib.resource path
- B. sys.path
- C. pylib.source
- D. pypi.path
- E. os.path
Answer: B
Explanation:
sys. path is a built-in variable within the sys module. It contains a list of directories that the interpreter will search in for the required module.
NEW QUESTION # 164
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.
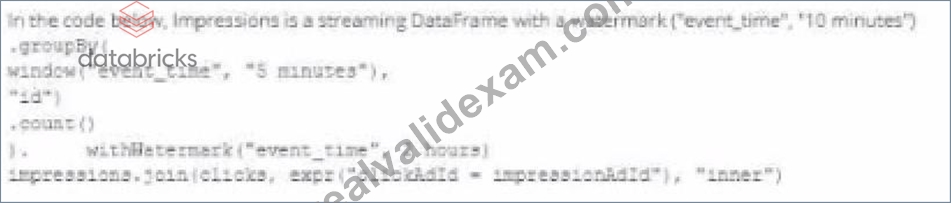
Which solution would improve the performance?
Answer: C
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 165
Which statement describes the default execution mode for Databricks Auto Loader?
- A. New files are identified by listing the input directory; new files are incrementally and idempotently loaded into the target Delta Lake table.
- B. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- C. New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
- D. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; the target table is materialized by directly querying all valid files in the source directory.
- E. Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
Answer: A
Explanation:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake.
The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
NEW QUESTION # 166
A data governance team at a large enterprise is improving data discoverability across its organization. The team has hundreds of tables in their Databricks Lakehouse with thousands of columns that lack proper documentation. Many of these tables were created by different teams over several years, with missing context about column meanings and business logic. The data governance team needs to quickly generate comprehensive column descriptions for all existing tables to meet compliance requirements and improve data literacy across the organization. They want to leverage modern capabilities to automatically generate meaningful descriptions rather than manually documenting each column, which would take months to complete. Which approach should the team use in Databricks to automatically generate column comments and descriptions for existing tables?
- A. Write custom PySpark code using df.describe() and df.schema to programmatically generate basic statistical descriptions for each column.
- B. Navigate to the table in Databricks Catalog Explorer, select the table schema view, and use the AI Generate option which leverages artificial intelligence to automatically create meaningful column descriptions based on column names, data types, sample values, and data patterns.
- C. Use Delta Lake's DESCRIBE HISTORY command to analyze table evolution and infer column purposes from historical changes.
- D. Use the DESCRIBE TABLE command to extract existing schema information and manually write descriptions based on column names and data types.
Answer: B
Explanation:
The Catalog Explorer provides an AI-powered "AI Generate" capability that automatically creates intelligent column descriptions by analyzing column names, data types, sample values, and observed data patterns. This approach enables rapid, scalable documentation of existing tables, significantly improving data discoverability and compliance without manual effort.
NEW QUESTION # 167
A data engineer is configuring a pipeline that will potentially see late-arriving, duplicate records.
In addition to de-duplicating records within the batch, which of the following approaches allows the data engineer to deduplicate data against previously processed records as it is inserted into a Delta table?
- A. Perform a full outer join on a unique key and overwrite existing data.
- B. Rely on Delta Lake schema enforcement to prevent duplicate records.
- C. VACUUM the Delta table after each batch completes.
- D. Perform an insert-only merge with a matching condition on a unique key.
- E. Set the configuration delta.deduplicate = true.
Answer: D
Explanation:
To deduplicate data against previously processed records as it is inserted into a Delta table, you can use the merge operation with an insert-only clause. This allows you to insert new records that do not match any existing records based on a unique key, while ignoring duplicate records that match existing records. For example, you can use the following syntax:
MERGE INTO target_table USING source_table ON target_table.unique_key = source_table.unique_key WHEN NOT MATCHED THEN INSERT * This will insert only the records from the source table that have a unique key that is not present in the target table, and skip the records that have a matching key. This way, you can avoid inserting duplicate records into the Delta table.
NEW QUESTION # 168
......
You will be able to assess your shortcomings and improve gradually without having anything to lose in the actual Databricks Certified Data Engineer Professional exam. You will sit through mock exams and solve actual Databricks Certified-Data-Engineer-Professional dumps. In the end, you will get results that'll improve each time you progress and grasp the concepts of your syllabus. The desktop-based Databricks Certified-Data-Engineer-Professional Practice Exam software is only compatible with Windows.
Certified-Data-Engineer-Professional Valid Real Test: https://www.realvalidexam.com/Certified-Data-Engineer-Professional-real-exam-dumps.html
- Certificate Certified-Data-Engineer-Professional Exam 😐 Certified-Data-Engineer-Professional New Learning Materials 🥅 Certified-Data-Engineer-Professional Study Reference 🪕 Search on 《 www.troytecdumps.com 》 for 「 Certified-Data-Engineer-Professional 」 to obtain exam materials for free download 🦆Certified-Data-Engineer-Professional Pdf Dumps
- Databricks Certified Data Engineer Professional Practice Exam - Certified-Data-Engineer-Professional Pdf Questions - Databricks Certified Data Engineer Professional Torrent Vce ⬇ Download 《 Certified-Data-Engineer-Professional 》 for free by simply entering ▷ www.pdfvce.com ◁ website 😈Certificate Certified-Data-Engineer-Professional Exam
- Pass Guaranteed Quiz 2026 Databricks High Hit-Rate Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Real Questions 🖊 Download 《 Certified-Data-Engineer-Professional 》 for free by simply entering ( www.examcollectionpass.com ) website ⌨Certified-Data-Engineer-Professional New Learning Materials
- Latest Certified-Data-Engineer-Professional Exam Practice 📸 Simulated Certified-Data-Engineer-Professional Test 😥 Certified-Data-Engineer-Professional Original Questions 🌕 Simply search for ➽ Certified-Data-Engineer-Professional 🢪 for free download on ➥ www.pdfvce.com 🡄 🛀New Certified-Data-Engineer-Professional Test Labs
- Pass Guaranteed Quiz 2026 Databricks High Hit-Rate Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Real Questions 🎉 ☀ www.examcollectionpass.com ️☀️ is best website to obtain “ Certified-Data-Engineer-Professional ” for free download 🚈Certified-Data-Engineer-Professional Passed
- Certified-Data-Engineer-Professional Original Questions 🤬 Certified-Data-Engineer-Professional Reliable Test Prep 👜 VCE Certified-Data-Engineer-Professional Dumps 🎂 Easily obtain ☀ Certified-Data-Engineer-Professional ️☀️ for free download through 《 www.pdfvce.com 》 🚦Sample Certified-Data-Engineer-Professional Questions Pdf
- Certified-Data-Engineer-Professional Original Questions ♥ Certified-Data-Engineer-Professional Passed ▶ New Certified-Data-Engineer-Professional Test Labs 🕉 The page for free download of [ Certified-Data-Engineer-Professional ] on ⮆ www.examdiscuss.com ⮄ will open immediately 🙏New Certified-Data-Engineer-Professional Test Labs
- Certificate Certified-Data-Engineer-Professional Exam 🕜 VCE Certified-Data-Engineer-Professional Dumps 🧙 Latest Certified-Data-Engineer-Professional Exam Practice 🎫 Enter ( www.pdfvce.com ) and search for ⮆ Certified-Data-Engineer-Professional ⮄ to download for free 😝Certified-Data-Engineer-Professional Detail Explanation
- Latest Certified-Data-Engineer-Professional Exam Practice 😂 Certified-Data-Engineer-Professional Reliable Test Forum ➕ Certified-Data-Engineer-Professional Pass Test Guide 👌 Copy URL ➥ www.prepawaypdf.com 🡄 open and search for 《 Certified-Data-Engineer-Professional 》 to download for free 🎼Certified-Data-Engineer-Professional Pdf Dumps
- Databricks Certified Data Engineer Professional Practice Exam - Certified-Data-Engineer-Professional Pdf Questions - Databricks Certified Data Engineer Professional Torrent Vce 🚙 Search for 「 Certified-Data-Engineer-Professional 」 and download it for free on ✔ www.pdfvce.com ️✔️ website 📟Certificate Certified-Data-Engineer-Professional Exam
- 100% Pass 2026 Databricks Valid Certified-Data-Engineer-Professional Real Questions 🚕 Enter ✔ www.exam4labs.com ️✔️ and search for ▶ Certified-Data-Engineer-Professional ◀ to download for free 🐨Certified-Data-Engineer-Professional Study Reference
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes



