To pass the Microsoft DP-750 Exam is a dream who are engaged in IT industry. If you want to change the dream into reality, you only need to choose the professional training. FreePdfDump is a professional website that providing IT certification training materials. Select FreePdfDump, it will ensure your success. No matter how high your pursuit of the goal, FreePdfDump will make your dreams become a reality.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 3: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 4: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
Based on our years of experience, taking the Microsoft DP-750 exam without proper preparation is such a suicidal move. The Implementing Data Engineering Solutions Using Azure Databricks is not easy to achieve because you first need to pass the Implementing Data Engineering Solutions Using Azure Databricks DP-750 exam. The only way to be successful with your Implementing Data Engineering Solutions Using Azure Databricks exam is by preparing it well with Microsoft DP-750 Dumps. This Implementing Data Engineering Solutions Using Azure Databricks DP-750 exam is not even easy to go through. Most people failed it due to a lack of preparation.
NEW QUESTION # 37
You have an Azure Databricks workspace that is enabled for Unity Catalog You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
* New data must be available in near-real time (NRT).
* The data must be stored in managed Delta tables.
* The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: D
Explanation:
The correct answer is A - Auto Loader.
Auto Loader is exactly the right tool for this scenario: new CSV files land in ADLS Gen2, and they need to be ingested into managed Delta tables in near-real time with minimal custom code. Auto Loader uses file-system notifications or incremental directory listing to detect new arrivals, processes only the newly added files (skipping previously ingested ones), and writes results into Delta tables - all with schema inference and evolution support built in.
Option B (scheduled Spark batch jobs) adds latency tied to the schedule interval and requires custom 'what files have I already processed' tracking. Option C (external table referencing CSV files) exposes the raw files for querying but doesn't load data into managed Delta tables - it also can't provide NRT updates as files change. Option D (Azure Data Factory pipeline) introduces external orchestration overhead and is a heavier solution for something Auto Loader handles natively in a few lines of PySpark.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 38
What ensures failure recovery in Databricks Structured Streaming?
Answer: C
Explanation:
Checkpointing stores streaming state and progress, allowing recovery after failures without data loss or duplication. Auto scaling adjusts compute resources but does not ensure reliability.
Partition pruning improves query performance. Broadcast joins optimize joins but are unrelated to recovery.
NEW QUESTION # 39
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
What should trigger a notification?
Answer: D
Explanation:
The correct answer is B - a job failure.
The requirement draws a clear line: non-critical task failures should be logged silently; notifications should only fire when a critical failure causes the whole job to stop. Configuring the alert on 'Job Failure' achieves this precisely - the notification triggers when the job itself reaches a Failed terminal state, which only happens when at least one critical task has failed and the job cannot complete.
Option A (task failure) would send a notification for every task-level failure, including non-critical ones.
That's exactly the noise the question wants to avoid. Option C (job success) would never alert on failures at all. Option D (task success) confirms completion but doesn't catch failures.
Setting alerting at the job level rather than the task level is also simpler to configure - you don't need to mark individual tasks as critical or non-critical in the notification settings.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/alerts
NEW QUESTION # 40
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.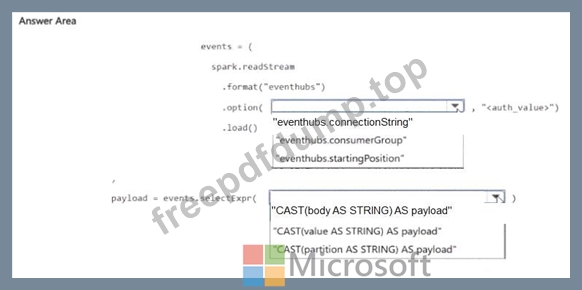
Answer:
Explanation: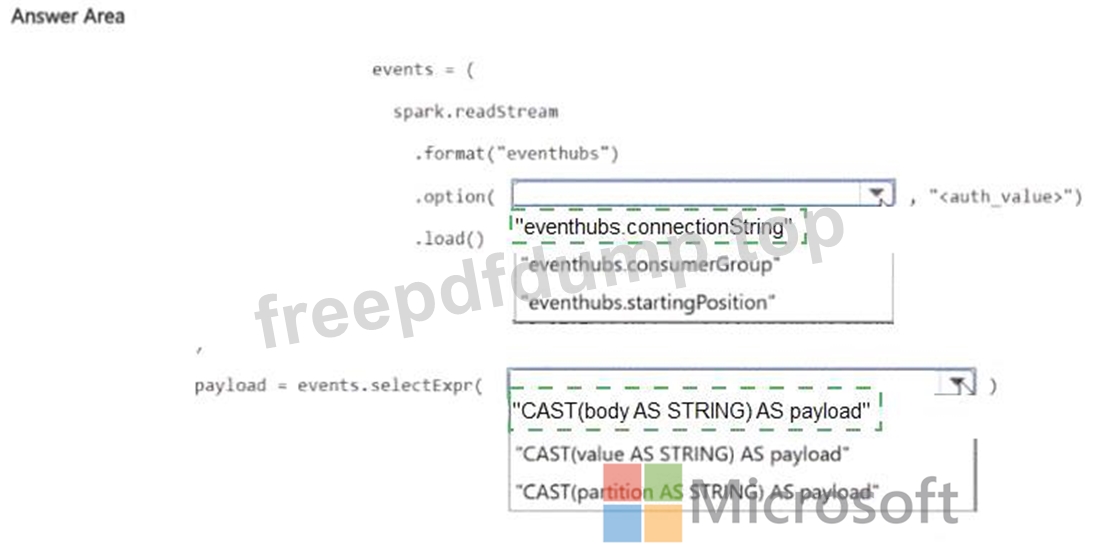
Explanation:
Reading from Azure Event Hubs in Spark Structured Streaming requires three things:
An EventHubsConf object built with the Event Hubs connection string (eventhubs.connectionString). This object is then converted to a map with .toMap before being passed to Spark.
spark.readStream.format( ' eventhubs ' ).options(**ehConf).load() to create the streaming DataFrame. The ' eventhubs ' format is provided by the azure-eventhubs-spark connector library.
A cast( ' string ' ) on the body column to decode the binary payload. Event Hubs delivers messages with the raw event bytes in a column called body - without the cast, you get binary data rather than the readable JSON or text payload.
This is the standard, documented integration pattern for connecting Azure Databricks to Event Hubs with Structured Streaming, providing the checkpoint-based exactly-once semantics required by the Contoso telemetry pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/storage/events/eventhubs
NEW QUESTION # 41
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job1 that processes data continuously and fails periodically due to transient errors.
You need to ensure that Job1 meets the following requirements:
- Resumes processing from the point that Job1 failed
- Minimizes how long it takes to restart Job1
- Minimizes the costs to restart Job1
What should you do?
Answer: A
Explanation:
You must use checkpointing.
Checkpointing is the native Apache Spark mechanism designed specifically to handle failures in Structured Streaming jobs. It saves the exact execution state and progress to cloud storage (like Azure Data Lake Storage), allowing the job to resume precisely where it left off without data loss.
Resumes from Failure Point: The checkpoint directory stores the stream offsets. When restarted, Spark reads these offsets to pick up exactly where it failed.
Minimizes Restart Time: By saving the state, Spark does not need to recompute historical streaming data or re-evaluate the entire stream architecture from scratch.
Minimizes Restart Costs: It prevents the reprocessing of duplicate data, saving valuable cluster compute time and reducing cloud infrastructure costs.
Reference:
https://www.linkedin.com/posts/shilpa-das-ln_what-is-checkpointing-in-spark-checkpointing- activity-7297113790393815041-AhPg
NEW QUESTION # 42
......
Microsoft Certification evolves swiftly, and a practice test may become obsolete within weeks of its publication. We provide free updates for Implementing Data Engineering Solutions Using Azure Databricks DP-750 exam questions after the purchase to ensure you are studying the most recent solutions. Furthermore, FreePdfDump is a very responsible and trustworthy platform dedicated to certifying you as a specialist. We provide a free sample before purchasing Microsoft DP-750 valid questions so that you may try and be happy with its varied quality features.
DP-750 Test Engine: https://www.freepdfdump.top/DP-750-valid-torrent.html