Databricks - Databricks-Certified-Data-Analyst-Associate High Hit-Rate Training Materials
DOWNLOAD the newest Fast2test Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1C4hSJli8jpgqsi7CCBBQTCFVABiyALh-
Our company is open-handed to offer benefits at intervals, with Databricks-Certified-Data-Analyst-Associate learning questions priced with reasonable prices. Almost all kinds of working staffs can afford our price, even the students. And we will give some discounts from time to time. Although our Databricks-Certified-Data-Analyst-Associate practice materials are reasonably available, their value is in-estimate. We offer hearty help for your wish of certificate of the Databricks-Certified-Data-Analyst-Associate exam.
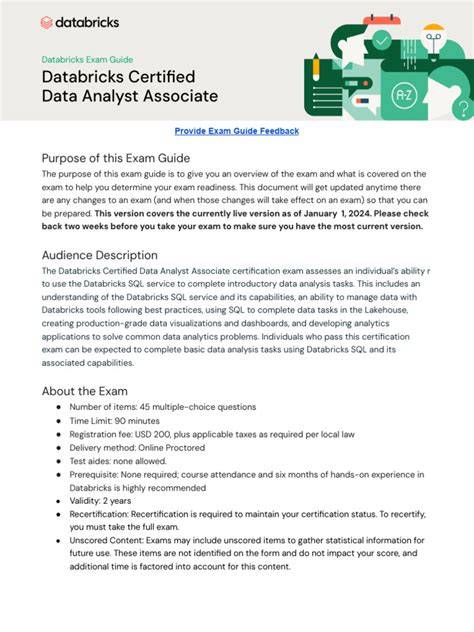
Databricks Databricks-Certified-Data-Analyst-Associate Exam Overview:
>> Databricks-Certified-Data-Analyst-Associate Training Materials <<
New Databricks-Certified-Data-Analyst-Associate Exam Vce - Databricks-Certified-Data-Analyst-Associate Detailed Answers
Will you feel nervous while facing a real exam environment? If you do choose us, we will provide you the most real environment through the Databricks-Certified-Data-Analyst-Associate exam dumps. Our soft online test version will stimulate the real environment, through this, you will know the process of the real exam. Databricks-Certified-Data-Analyst-Associate Exam Dumps will build up your confidence as well as reduce the mistakes. If you need the practice just like this, just contact us.
| Topic | Details |
|---|
| Topic 1 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
| Topic 2 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| Topic 3 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| Topic 4 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| Topic 5 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
Databricks Certified Data Analyst Associate Exam Sample Questions (Q84-Q89):
NEW QUESTION # 84
In a healthcare provider organization using Delta Lake to store electronic health records, a data analyst needs to analyze a snapshot of the patient_records table from two weeks ago before some recent data corrections were applied.
What approach should the Data Engineer take to allow the analyst to query that specific prior version?
- A. Use the VACUUM command to remove all versions of the table older than two weeks, then the analyst can query the remaining version.
- B. Identify the version number corresponding to two weeks ago from the Delta transaction log, share that version number with the analyst to query using VERSION AS OF syntax, or export that version to a new Delta table for the analyst to query.
- C. Restore the table to the version from two weeks ago using the RESTORE command, and have the analyst query the restored table.
- D. Truncate the table to remove all data, then reload the data from two weeks ago into the truncated table for the analyst to query.
Answer: B
Explanation:
Option B is correct. Delta Lake supports time travel, which allows users to query previous table versions by timestamp or version number. The version can be obtained from table history and queried using VERSION AS OF. Restoring the table would change the current table state for everyone, which is not necessary when the analyst only needs to analyze a historical snapshot. VACUUM would remove old data files and can prevent time travel. Official Databricks extract: time travel supports "querying previous table versions," and the syntax includes SELECT * FROM people10m VERSION AS OF 123. Databricks also states that the version can be obtained from DESCRIBE HISTORY. Note: the two-week snapshot is queryable only if the required log and data files are still retained.
NEW QUESTION # 85
A data analyst has a managed table table_name in database database_name. They would now like to remove the table from the database and all of the data files associated with the table. The rest of the tables in the database must continue to exist.
Which of the following commands can the analyst use to complete the task without producing an error?
- A. DELETE TABLE database_name.table_name;
- B. DELETE TABLE table_name FROM database_name;
- C. DROP DATABASE database_name;
- D. DROP TABLE table_name FROM database_name;
- E. DROP TABLE database_name.table_name;
Answer: E
Explanation:
The DROP TABLE command removes a table from the metastore and deletes the associated data files. The syntax for this command is DROP TABLE [IF EXISTS] [database_name.] table_name;. The optional IF EXISTS clause prevents an error if the table does not exist. The optional database_name. prefix specifies the database where the table resides. If not specified, the current database is used. Therefore, the correct command to remove the table table_name from the database database_name and all of the data files associated with it is DROP TABLE database_name.table_name;. The other commands are either invalid syntax or would produce undesired results. References: Databricks - DROP TABLE
NEW QUESTION # 86
A data analyst is working with gold-layer tables to complete an ad-hoc project. A stakeholder has provided the analyst with an additional dataset that can be used to augment the gold-layer tables already in use.
Which of the following terms is used to describe this data augmentation?
- A. Data enhancement
- B. Data testing
- C. Last-mile
- D. Last-mile ETL
- E. Ad-hoc improvements
Answer: A
Explanation:
Data enhancement is the process of adding or enriching data with additional information to improve its quality, accuracy, and usefulness. Data enhancement can be used to augment existing data sources with new data sources, such as external datasets, synthetic data, or machine learning models. Data enhancement can help data analysts to gain deeper insights, discover new patterns, and solve complex problems. Data enhancement is one of the applications of generative AI, which can leverage machine learning to generate synthetic data for better models or safer data sharing1.
In the context of the question, the data analyst is working with gold-layer tables, which are curated business-level tables that are typically organized in consumption-ready project-specific databases234. The gold-layer tables are the final layer of data transformations and data quality rules in the medallion lakehouse architecture, which is a data design pattern used to logically organize data in a lakehouse2. The stakeholder has provided the analyst with an additional dataset that can be used to augment the gold-layer tables already in use. This means that the analyst can use the additional dataset to enhance the existing gold-layer tables with more information, such as new features, attributes, or metrics. This data augmentation can help the analyst to complete the ad-hoc project more effectively and efficiently.
Reference:
What is the medallion lakehouse architecture? - Databricks
Data Warehousing Modeling Techniques and Their Implementation on the Databricks Lakehouse Platform | Databricks Blog What is the medallion lakehouse architecture? - Azure Databricks What is a Medallion Architecture? - Databricks Synthetic Data for Better Machine Learning | Databricks Blog
NEW QUESTION # 87
Which of the following Structured Streaming queries is performing a hop from a Silver table to a Gold table?
- A. ( spark.readStream.load(rawSalesLocation) .writeStream .option( " checkpointLocation " , checkpointPath) .outputMode( " append " ) .table( " newSales " ))
- B. Option A
- C. ( spark.table( " sales " ) .groupBy( " store " ) .agg(sum( " sales " )) .writeStream .option( " checkpointLocation " , checkpointPath) .outputMode( " complete " ) .table( " newSales " ))
- D. ( spark.table( " sales " ) .withColumn( " avgPrice " , col( " sales " ) / col( " units " )) .writeStream .option ( " checkpointLocation " , checkpointPath) .outputMode( " append " ) .table( " newSales " ))
- E. Option B
- F. Option D
- G. ( spark.table( " sales " ) .filter(col( " units " ) > 0) .writeStream .option( " checkpointLocation " , checkpointPath) .outputMode( " append " ) .table( " newSales " ))
- H. Option C
- I. ( spark.table( " sales " ) .withColumn( " avgPrice " , col( " sales " ) / col( " units " )) .writeStream .option ( " checkpointLocation " , checkpointPath) .outputMode( " append " ) .table( " newSales " ))
- J. Option E
Answer: C
Explanation:
Option E is correct. A Silver-to-Gold hop typically reads cleaned/refined Silver data and writes aggregated, analytics-ready Gold data. The query reads from sales, groups by store, and aggregates sum( " sales " ), producing a summary table suitable for reporting or dashboarding. That matches the Gold layer. Option A reads from a raw location, which is not Silver-to-Gold. Option D filters invalid units, which is a cleaning step associated with Silver. Options B and C add a derived column but do not create a Gold-level aggregated table.
Official Databricks medallion architecture documentation states that Silver is where data cleanup and validation are performed, while the Gold layer "consists of aggregated data tailored for analytics and reporting." Databricks Structured Streaming documentation also shows .writeStream.outputMode( " complete
" ).toTable(...) as a valid output mode pattern for stateful streaming aggregations.
NEW QUESTION # 88
Consider the following two statements:
Statement 1:

Statement 2:

Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
- A. The first statement will return all data from the customers table and matching data from the orders table. The second statement will return all data from the orders table and matching data from the customers table. Any missing data will be filled in with NULL.
- B. When the first statement is run, only rows from the customers table that have at least one match with the orders table on customer_id will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
- C. There is no difference between the result sets for both statements.
- D. When the first statement is run, all rows from the customers table will be returned and only the customer_id from the orders table will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
- E. Both statements will fail because Databricks SQL does not support those join types.
Answer: B
Explanation:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id). Therefore, the result sets for the two statements will differ in the following way:
The first statement will return a subset of the customers table that contains only the customers who have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table.
The other options are not correct because:
A) The first statement will not return all data from the customers table, as it will exclude the customers who have no orders. The second statement will not return all data from the orders table, as it will exclude the orders that have a matching customer. Neither statement will fill in any missing data with NULL, as they do not return any columns from the other table.
C) There is a difference between the result sets for both statements, as explained above. The LEFT SEMI JOIN and the LEFT ANTI JOIN are not equivalent operations and will produce different outputs.
D) Both statements will not fail, as Databricks SQL does support those join types. Databricks SQL supports various join types, including INNER, LEFT OUTER, RIGHT OUTER, FULL OUTER, LEFT SEMI, LEFT ANTI, and CROSS. You can also use NATURAL, USING, or LATERAL keywords to specify different join criteria.
E) The first statement will not return only the customer_id from the orders table, as it will return all columns from the customers table. The second statement is correct, but it is not the only difference between the result sets.
NEW QUESTION # 89
......
New Databricks-Certified-Data-Analyst-Associate Exam Vce: https://www.fast2test.com/Databricks-Certified-Data-Analyst-Associate-premium-file.html
- Latest Released Databricks Databricks-Certified-Data-Analyst-Associate Training Materials: Databricks Certified Data Analyst Associate Exam 🔧 The page for free download of ➤ Databricks-Certified-Data-Analyst-Associate ⮘ on ⇛ www.prep4sures.top ⇚ will open immediately 🙌Databricks-Certified-Data-Analyst-Associate Exam Study Solutions
- Pass Guaranteed Quiz 2026 Databricks Marvelous Databricks-Certified-Data-Analyst-Associate: Databricks Certified Data Analyst Associate Exam Training Materials 🔜 Open ➽ www.pdfvce.com 🢪 and search for ➠ Databricks-Certified-Data-Analyst-Associate 🠰 to download exam materials for free ☀Exam Databricks-Certified-Data-Analyst-Associate Collection Pdf
- Databricks Excellent Databricks-Certified-Data-Analyst-Associate Training Materials – Pass Databricks-Certified-Data-Analyst-Associate First Attempt 🏖 ☀ www.pdfdumps.com ️☀️ is best website to obtain ⮆ Databricks-Certified-Data-Analyst-Associate ⮄ for free download 🌎Databricks-Certified-Data-Analyst-Associate New Question
- Databricks-Certified-Data-Analyst-Associate Exam Study Solutions ⛄ Databricks-Certified-Data-Analyst-Associate Reliable Braindumps Files 💡 Databricks-Certified-Data-Analyst-Associate Free Practice 🐉 Go to website ➽ www.pdfvce.com 🢪 open and search for 《 Databricks-Certified-Data-Analyst-Associate 》 to download for free 🖍Databricks-Certified-Data-Analyst-Associate Valid Exam Simulator
- Quiz Databricks-Certified-Data-Analyst-Associate - Perfect Databricks Certified Data Analyst Associate Exam Training Materials ⬛ Search for ➠ Databricks-Certified-Data-Analyst-Associate 🠰 and download it for free on ▷ www.troytecdumps.com ◁ website 🍞Databricks-Certified-Data-Analyst-Associate New Question
- Databricks-Certified-Data-Analyst-Associate Reliable Exam Testking 🦰 Databricks-Certified-Data-Analyst-Associate Latest Dumps 🐨 Databricks-Certified-Data-Analyst-Associate New Study Materials 🏔 Search for ( Databricks-Certified-Data-Analyst-Associate ) and download exam materials for free through ➥ www.pdfvce.com 🡄 💉Pass4sure Databricks-Certified-Data-Analyst-Associate Study Materials
- Databricks-Certified-Data-Analyst-Associate Reliable Braindumps Files 🍲 Training Databricks-Certified-Data-Analyst-Associate Online 🚛 Databricks-Certified-Data-Analyst-Associate Free Practice 🕣 Easily obtain 「 Databricks-Certified-Data-Analyst-Associate 」 for free download through ⇛ www.prepawaypdf.com ⇚ 🤒Training Databricks-Certified-Data-Analyst-Associate Online
- Databricks Excellent Databricks-Certified-Data-Analyst-Associate Training Materials – Pass Databricks-Certified-Data-Analyst-Associate First Attempt 🍳 Search on ➡ www.pdfvce.com ️⬅️ for { Databricks-Certified-Data-Analyst-Associate } to obtain exam materials for free download 🔫Reliable Databricks-Certified-Data-Analyst-Associate Test Guide
- Exam Databricks-Certified-Data-Analyst-Associate Collection Pdf 🦕 Reliable Databricks-Certified-Data-Analyst-Associate Test Guide 🗯 Databricks-Certified-Data-Analyst-Associate Best Practice 👣 Simply search for [ Databricks-Certified-Data-Analyst-Associate ] for free download on “ www.easy4engine.com ” 🍳Databricks-Certified-Data-Analyst-Associate Reliable Braindumps Files
- Databricks Excellent Databricks-Certified-Data-Analyst-Associate Training Materials – Pass Databricks-Certified-Data-Analyst-Associate First Attempt 🟪 Simply search for { Databricks-Certified-Data-Analyst-Associate } for free download on “ www.pdfvce.com ” 🤵Exam Databricks-Certified-Data-Analyst-Associate Quizzes
- Databricks-Certified-Data-Analyst-Associate Valid Exam Simulator 🍝 Training Databricks-Certified-Data-Analyst-Associate Online 🥞 Databricks-Certified-Data-Analyst-Associate Latest Dumps 👶 Search for 【 Databricks-Certified-Data-Analyst-Associate 】 and download exam materials for free through ▷ www.practicevce.com ◁ 🦧Databricks-Certified-Data-Analyst-Associate Valid Exam Simulator
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, mayagriffiths253.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.chordie.com, www.callcentersindia.co.in, Disposable vapes
BTW, DOWNLOAD part of Fast2test Databricks-Certified-Data-Analyst-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1C4hSJli8jpgqsi7CCBBQTCFVABiyALh-