Databricks-Certified-Data-Analyst-Associate Exam Actual Tests | 100% Free Databricks Certified Data Analyst Associate Exam Discount Code

BONUS!!! Download part of TrainingDump Databricks-Certified-Data-Analyst-Associate dumps for free: https://drive.google.com/open?id=1KNF9PclXQ1IyYkNRU1jcUmTVWSpwKoJm
This free Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) exam questions demo download facility is available in all three Databricks-Certified-Data-Analyst-Associate exam dumps formats. Just choose the best TrainingDump Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) exam demo questions format and download it quickly. If you think that Databricks-Certified-Data-Analyst-Associate exam dumps can work for you then take your buying decision.
| Topic | Details |
|---|
| Topic 1 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| Topic 2 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| Topic 3 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
| Topic 4 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| Topic 5 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
>> Databricks-Certified-Data-Analyst-Associate Exam Actual Tests <<
Databricks Databricks-Certified-Data-Analyst-Associate Exam Dumps - Pass Exam With Ease [2026]
You have to put in some extra effort, time, and investment and prepare well to pass this milestone. Do you have a plan to get success in the Databricks Databricks-Certified-Data-Analyst-Associate certification exam? Are you looking for the right study material that ensures your success in the TrainingDump new real Databricks Databricks-Certified-Data-Analyst-Associate Exam Questions on your first attempt? If your answer is yes then you just need to get help from TrainingDump practice exam questions.
Databricks Certified Data Analyst Associate Exam Sample Questions (Q60-Q65):
NEW QUESTION # 60
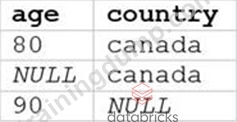
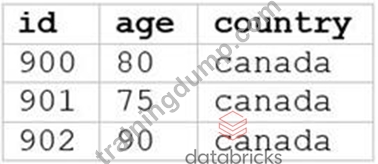
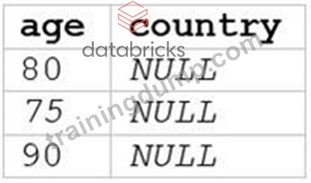
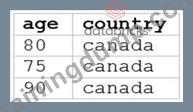
A data analyst runs the following command:
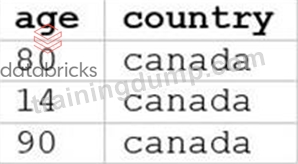
SELECT age, country
FROM my_table
WHERE age >= 75 AND country = 'canada';
Which of the following tables represents the output of the above command?
Answer: D
Explanation:
The SQL query provided is designed to filter out records from "my_table" where the age is 75 or above and the country is Canada. Since I can't view the content of the links provided directly, I need to rely on the image attached to this question for context. Based on that, Option E (the image attached) represents a table with columns "age" and "country", showing records where age is 75 or above and country is Canada. Reference: The answer can be inferred from understanding SQL queries and their outputs as per Databricks documentation: Databricks SQL
NEW QUESTION # 61
A data scientist wants to tune a set of hyperparameters for a machine learning model. They have wrapped a Spark ML model in the objective function objective_function, and they have defined the search space search_space.
As a result, they have the following code block:
num_evals = 100
trials = SparkTrials()
best_hyperparam = fmin(
fn=objective_function,
space=search_space,
algo=tpe.suggest,
max_evals=num_evals,
trials=trials
)
Which of the following changes do they need to make to the above code block in order to accomplish the task?
- A. Remove the algo=tpe.suggest argument
- B. Reduce num_evals to be less than 10
- C. Remove the trials=trials argument
- D. Change SparkTrials() to Trials()
- E. Change fmin() to fmax()
Answer: D
Explanation:
Option A is correct. The model being tuned is a Spark ML model, which is already distributed. SparkTrials is intended to distribute independent single-machine trials across Spark workers. For distributed ML algorithms such as Spark MLlib/Spark ML, Hyperopt should run trials from the driver so each trial can access the full cluster resources. Therefore, SparkTrials() should be changed to Trials(). Official Databricks documentation explains that this setup works for distributed machine learning algorithms including Apache Spark MLlib, and the Databricks notebook guidance states that SparkTrials is incompatible for that distributed-training pattern because each trial must be evaluated on the driver node.
NEW QUESTION # 62
A data analyst at an e-commerce company needs to process daily sales data. The data consists of approximately 50,000 records stored in a single CSV file, totaling about 20 MB. The analyst needs to perform aggregations and generate a summary report.
Which approach could the data analyst use in this situation?
- A. Use a local Python script with the pandas library to read and analyze the CSV file.
- B. Set up a Hadoop ecosystem with HDFS and MapReduce for distributed processing.
- C. Implement Apache Spark with a distributed cluster to process the data in parallel.
- D. Deploy a real-time streaming solution using Spark Streaming to process incoming data.
Answer: A
Explanation:
Option B is correct. A 20 MB CSV file with about 50,000 records is small enough for a local pandas workflow. A real-time streaming solution, a distributed Spark cluster, or Hadoop MapReduce would add unnecessary complexity for a small single-file batch analysis. Databricks documentation explains that pandas is available in Databricks Runtime and can be used for data analysis, while pandas API on Spark is useful when pandas-style workloads need to scale beyond smaller datasets. Databricks also notes that pandas does not scale out to big data, which is exactly why Spark or pandas API on Spark is used for larger workloads, not for a small 20 MB file.
NEW QUESTION # 63
A data analyst has created a Query in Databricks SQL, and now wants to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.
Which step will the data analyst need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?
- A. Alter the Query to return two separate sets of results.
- B. Add two separate visualizations to the dashboard based on the same Query.
- C. Copy the Query and create one data visualization per query.
- D. Decide on a single data visualization to add to the dashboard.
Answer: B
Explanation:
Databricks SQL allows you to create multiple visualizations from a single query result. These visualizations can be customized independently and each can be added to a dashboard. This feature is explicitly supported and recommended in Databricks' documentation on dashboards and visualization workflows, enabling flexible reporting without duplicating queries.
NEW QUESTION # 64
A data analyst has set up a SQL query to run every four hours on a SQL endpoint, but the SQL endpoint is taking too long to start up with each run.
Which of the following changes can the data analyst make to reduce the start-up time for the endpoint while managing costs?
- A. Increase the minimum scaling value
- B. Use a Serverless SQL endpoint
- C. Reduce the SQL endpoint cluster size
- D. Increase the SQL endpoint cluster size
- E. Turn off the Auto stop feature
Answer: B
Explanation:
A Serverless SQL endpoint is a type of SQL endpoint that does not require a dedicated cluster to run queries. Instead, it uses a shared pool of resources that can scale up and down automatically based on the demand. This means that a Serverless SQL endpoint can start up much faster than a SQL endpoint that uses a cluster, and it can also save costs by only paying for the resources that are used. A Serverless SQL endpoint is suitable for ad-hoc queries and exploratory analysis, but it may not offer the same level of performance and isolation as a SQL endpoint that uses a cluster. Therefore, a data analyst should consider the trade-offs between speed, cost, and quality when choosing between a Serverless SQL endpoint and a SQL endpoint that uses a cluster. Reference: Databricks SQL endpoints, Serverless SQL endpoints, SQL endpoint clusters
NEW QUESTION # 65
......
The Databricks Databricks-Certified-Data-Analyst-Associate certification exam also enables you to stay updated and competitive in the market which will help you to gain more career opportunities. Do you want to gain all these Databricks-Certified-Data-Analyst-Associate certification exam benefits? Looking for the quick and complete Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) exam dumps preparation way that enables you to pass the Databricks Certified Data Analyst Associate Exam in Databricks-Certified-Data-Analyst-Associate certification exam with good scores?
Databricks-Certified-Data-Analyst-Associate Discount Code: https://www.trainingdump.com/Databricks/Databricks-Certified-Data-Analyst-Associate-practice-exam-dumps.html
- Reliable Databricks-Certified-Data-Analyst-Associate Exam Dumps ✔ Databricks-Certified-Data-Analyst-Associate Reliable Dumps Book 🔀 Latest Databricks-Certified-Data-Analyst-Associate Exam Price 💛 Open website { www.pdfdumps.com } and search for ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ for free download 💗Databricks-Certified-Data-Analyst-Associate Study Guide Pdf
- Marvelous Databricks-Certified-Data-Analyst-Associate Exam Actual Tests - Leading Offer in Qualification Exams - Trusted Databricks-Certified-Data-Analyst-Associate Discount Code 🏇 Download ☀ Databricks-Certified-Data-Analyst-Associate ️☀️ for free by simply searching on ( www.pdfvce.com ) 🛴New Databricks-Certified-Data-Analyst-Associate Exam Book
- Unparalleled Databricks-Certified-Data-Analyst-Associate Exam Actual Tests - Passing Databricks-Certified-Data-Analyst-Associate Exam is No More a Challenging Task 🚞 Download ( Databricks-Certified-Data-Analyst-Associate ) for free by simply entering ➠ www.pdfdumps.com 🠰 website 📼Databricks-Certified-Data-Analyst-Associate Valid Test Sims
- Databricks-Certified-Data-Analyst-Associate Latest Exam Fee 🧾 Databricks-Certified-Data-Analyst-Associate Actualtest 🆎 Databricks-Certified-Data-Analyst-Associate Valid Test Materials 🚟 Easily obtain free download of ( Databricks-Certified-Data-Analyst-Associate ) by searching on ▶ www.pdfvce.com ◀ 🧹New Databricks-Certified-Data-Analyst-Associate Exam Book
- Databricks-Certified-Data-Analyst-Associate Valid Exam Guide 🏤 Databricks-Certified-Data-Analyst-Associate Valid Test Sims 🎇 Practice Databricks-Certified-Data-Analyst-Associate Exams 📅 Download ☀ Databricks-Certified-Data-Analyst-Associate ️☀️ for free by simply searching on 「 www.pass4test.com 」 🈺Databricks-Certified-Data-Analyst-Associate Valid Exam Guide
- Practice Databricks-Certified-Data-Analyst-Associate Exams 🔬 Practice Databricks-Certified-Data-Analyst-Associate Exams 🦹 Databricks-Certified-Data-Analyst-Associate Latest Study Materials 🤯 Search on ⏩ www.pdfvce.com ⏪ for ➡ Databricks-Certified-Data-Analyst-Associate ️⬅️ to obtain exam materials for free download 🐆Databricks-Certified-Data-Analyst-Associate Key Concepts
- New Databricks-Certified-Data-Analyst-Associate Exam Book 💳 Databricks-Certified-Data-Analyst-Associate Study Guide Pdf 🚏 Databricks-Certified-Data-Analyst-Associate Valid Test Sims 🍭 Download ▛ Databricks-Certified-Data-Analyst-Associate ▟ for free by simply entering ⇛ www.vce4dumps.com ⇚ website 🥳Databricks-Certified-Data-Analyst-Associate Actualtest
- Enhance Your Success Rate with Pdfvce's Databricks-Certified-Data-Analyst-Associate Exam Dumps 🚘 Open ▛ www.pdfvce.com ▟ enter “ Databricks-Certified-Data-Analyst-Associate ” and obtain a free download 🚪Databricks-Certified-Data-Analyst-Associate Latest Exam Labs
- Databricks-Certified-Data-Analyst-Associate Latest Exam Fee 👓 Databricks-Certified-Data-Analyst-Associate Valid Exam Guide 😻 Study Materials Databricks-Certified-Data-Analyst-Associate Review 🦩 The page for free download of ☀ Databricks-Certified-Data-Analyst-Associate ️☀️ on ⇛ www.prep4sures.top ⇚ will open immediately 🙌Online Databricks-Certified-Data-Analyst-Associate Training
- Databricks-Certified-Data-Analyst-Associate Valid Test Materials 🌭 Valid Databricks-Certified-Data-Analyst-Associate Torrent ☸ New Databricks-Certified-Data-Analyst-Associate Exam Book 🔃 Open ➥ www.pdfvce.com 🡄 and search for ➡ Databricks-Certified-Data-Analyst-Associate ️⬅️ to download exam materials for free 🍩Databricks-Certified-Data-Analyst-Associate Free Updates
- 100% Pass 2026 Reliable Databricks Databricks-Certified-Data-Analyst-Associate Exam Actual Tests 🟠 Download { Databricks-Certified-Data-Analyst-Associate } for free by simply entering ➤ www.easy4engine.com ⮘ website 🟪Latest Databricks-Certified-Data-Analyst-Associate Exam Price
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
DOWNLOAD the newest TrainingDump Databricks-Certified-Data-Analyst-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1KNF9PclXQ1IyYkNRU1jcUmTVWSpwKoJm