BTW, DOWNLOAD part of Fast2test Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1WR4mrXU8g6O3Z12x1u5NZc5vwG6L_O65
We understand your enthusiasm of effective practice materials, because they are the most hopeful tools help us gain more knowledge with the least time to achieve success, and we have been in your shoes. Our Databricks-Generative-AI-Engineer-Associate exam questions can help you achieve that dreams easily. Whatever you want to master about this exam, our experts have compiled into them for your reference. A growing number of exam candidates are choosing our Databricks-Generative-AI-Engineer-Associate Exam Questions, why are you still hesitating? As long as you have make up your mind, our Databricks Certified Generative AI Engineer Associate study question is available in five minutes, so just begin your review now! This could be a pinnacle in your life.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Databricks-Generative-AI-Engineer-Associate Practice Tests <<
Just the same as the free demo, we have provided three kinds of versions of our Databricks Databricks-Generative-AI-Engineer-Associate preparation exam, among which the PDF version is the most popular one. It is understandable that many people give their priority to use paper-based Databricks-Generative-AI-Engineer-Associate Materials rather than learning on computers, and it is quite clear that the PDF version is convenient for our customers to read and print the contents in our Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate study guide.
NEW QUESTION # 52
A Generative Al Engineer is developing a RAG application and would like to experiment with different embedding models to improve the application performance.
Which strategy for picking an embedding model should they choose?
Answer: C
Explanation:
The task involves improving a Retrieval-Augmented Generation (RAG) application's performance by experimenting with embedding models. The choice of embedding model impacts retrieval accuracy, which is critical for RAG systems. Let's evaluate the options based on Databricks Generative AI Engineer best practices.
* Option A: Pick an embedding model trained on related domain knowledge
* Embedding models trained on domain-specific data (e.g., industry-specific corpora) produce vectors that better capture the semantics of the application's context, improving retrieval relevance. For RAG, this is a key strategy to enhance performance.
* Databricks Reference : " For optimal retrieval in RAG systems, select embedding models aligned with the domain of your data " ( " Building LLM Applications with Databricks, " 2023).
* Option B: Pick the most recent and most performant open LLM released at the time
* LLMs are not embedding models; they generate text, not embeddings for retrieval. While recent LLMs may be performant for generation, this doesn't address the embedding step in RAG. This option misunderstands the component being selected.
* Databricks Reference : Embedding models and LLMs are distinct in RAG workflows: " Embedding models convert text to vectors, while LLMs generate responses " ( " Generative AI Cookbook " ).
* Option C: Pick the embedding model ranked highest on the Massive Text Embedding Benchmark (MTEB) leaderboard hosted by HuggingFace
* The MTEB leaderboard ranks models across general tasks, but high overall performance doesn't guarantee suitability for a specific domain. A top-ranked model might excel in generic contexts but underperform on the engineer's unique data.
* Databricks Reference : General performance is less critical than domain fit: " Benchmark rankings provide a starting point, but domain-specific evaluation is recommended " ( " Databricks Generative AI Engineer Guide " ).
* Option D: Pick an embedding model with multilingual support to support potential multilingual user questions
* Multilingual support is useful only if the application explicitly requires it. Without evidence of multilingual needs, this adds complexity without guaranteed performance gains for the current use case.
* Databricks Reference : " Choose features like multilingual support based on application requirements " ( " Building LLM-Powered Applications " ).
Conclusion : Option A is the best strategy because it prioritizes domain relevance, directly improving retrieval accuracy in a RAG system-aligning with Databricks' emphasis on tailoring models to specific use cases.
NEW QUESTION # 53
A Generative Al Engineer has successfully ingested unstructured documents and chunked them by document sections. They would like to store the chunks in a Vector Search index. The current format of the dataframe has two columns: (i) original document file name (ii) an array of text chunks for each document.
What is the most performant way to store this dataframe?
Answer: B
Explanation:
* Problem Context: The engineer needs an efficient way to store chunks of unstructured documents to facilitate easy retrieval and search. The current dataframe consists of document filenames and associated text chunks.
* Explanation of Options:
* Option A: Splitting into train and test sets is more relevant for model training scenarios and not directly applicable to storage for retrieval in a Vector Search index.
* Option B: Flattening the dataframe such that each row contains a single chunk with a unique identifier is the most performant for storage and retrieval. This structure aligns well with how data is indexed and queried in vector search applications, making it easier to retrieve specific chunks efficiently.
* Option C: Creating a unique identifier for each document only does not address the need to access individual chunks efficiently, which is critical in a Vector Search application.
* Option D: Storing each chunk as an independent JSON file creates unnecessary overhead and complexity in managing and querying large volumes of files.
OptionBis the most efficient and practical approach, allowing for streamlined indexing and retrieval processes in a Delta table environment, fitting the requirements of a Vector Search index.
NEW QUESTION # 54
A Generative AI Engineer is creating an LLM-powered application that will need access to up-to-date news articles and stock prices.
The design requires the use of stock prices which are stored in Delta tables and finding the latest relevant news articles by searching the internet.
How should the Generative AI Engineer architect their LLM system?
Answer: C
Explanation:
To build an LLM-powered system that accesses up-to-date news articles and stock prices, the best approach is tocreate an agentthat has access to specific tools (option D).
* Agent with SQL and Web Search Capabilities:By using an agent-based architecture, the LLM can interact with external tools. The agent can query Delta tables (for up-to-date stock prices) via SQL and perform web searches to retrieve the latest news articles. This modular approach ensures the system can access both structured (stock prices) and unstructured (news) data sources dynamically.
* Why This Approach Works:
* SQL Queries for Stock Prices: Delta tables store stock prices, which the agent can query directly for the latest data.
* Web Search for News: For news articles, the agent can generate search queries and retrieve the most relevant and recent articles, then pass them to the LLM for processing.
* Why Other Options Are Less Suitable:
* A (Summarizing News for Stock Prices): This convoluted approach would not ensure accuracy when retrieving stock prices, which are already structured and stored in Delta tables.
* B (Stock Price Volatility Queries): While this could retrieve relevant information, it doesn't address how to obtain the most up-to-date news articles.
* C (Vector Store): Storing news articles and stock prices in a vector store might not capture the real-time nature of stock data and news updates, as it relies on pre-existing data rather than dynamic querying.
Thus, using an agent with access to both SQL for querying stock prices and web search for retrieving news articles is the best approach for ensuring up-to-date and accurate responses.
NEW QUESTION # 55
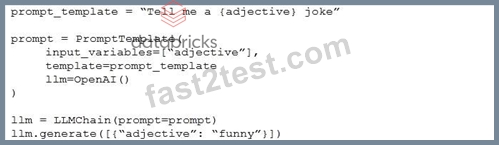
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.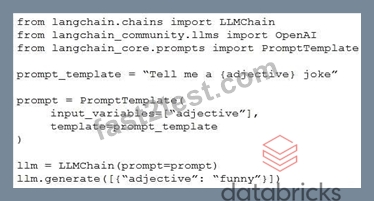
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
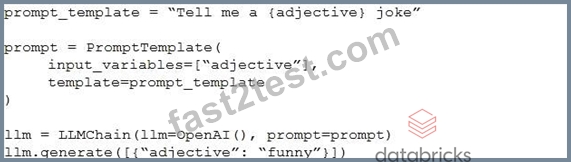
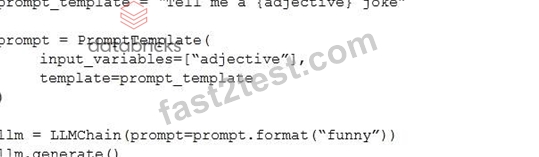
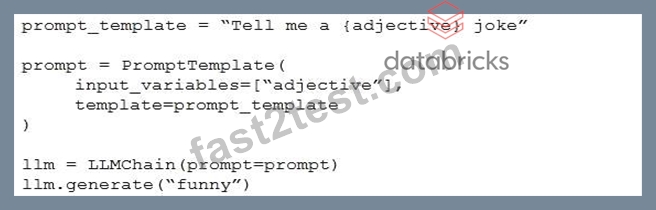
Answer: D
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 56
After changing the response generating LLM in a RAG pipeline from GPT-4 to a model with a shorter context length that the company self-hosts, the Generative AI Engineer is getting the following error:
What TWO solutions should the Generative AI Engineer implement without changing the response generating model? (Choose two.)
Answer: A,E
Explanation:
* Problem Context: After switching to a model with a shorter context length, the error message indicating that the prompt token count has exceeded the limit suggests that the input to the model is too large.
* Explanation of Options:
* Option A: Use a smaller embedding model to generate- This wouldn't necessarily address the issue of prompt size exceeding the model's token limit.
* Option B: Reduce the maximum output tokens of the new model- This option affects the output length, not the size of the input being too large.
* Option C: Decrease the chunk size of embedded documents- This would help reduce the size of each document chunk fed into the model, ensuring that the input remains within the model's context length limitations.
* Option D: Reduce the number of records retrieved from the vector database- By retrieving fewer records, the total input size to the model can be managed more effectively, keeping it within the allowable token limits.
* Option E: Retrain the response generating model using ALiBi- Retraining the model is contrary to the stipulation not to change the response generating model.
OptionsCandDare the most effective solutions to manage the model's shorter context length without changing the model itself, by adjusting the input size both in terms of individual document size and total documents retrieved.
NEW QUESTION # 57
......
We are not only offering you the best Databricks-Generative-AI-Engineer-Associate torrent VCE but also the foremost customer service. If you search for the best high pass-rate study materials, our Databricks-Generative-AI-Engineer-Associate practice test questions will be your best select. Please rest assured that your money and information will be strictly protected and safe on our website. You have no need to worry anything while purchasing. After purchasing our products you can get 100%-pass-rate Databricks-Generative-AI-Engineer-Associate Real Questions to help you pass exam immediately at first attempt. Choosing our products will be your cleaver action for clearing Databricks-Generative-AI-Engineer-Associate exam.
Sample Databricks-Generative-AI-Engineer-Associate Questions Answers: https://www.fast2test.com/Databricks-Generative-AI-Engineer-Associate-premium-file.html
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Fast2test: https://drive.google.com/open?id=1WR4mrXU8g6O3Z12x1u5NZc5vwG6L_O65