Save Time And Use Databricks Certified-Data-Engineer-Professional PDF Dumps Format For Qucik Preparation

In addition to the Certified-Data-Engineer-Professional study materials, our company also focuses on the preparation and production of other learning materials. If you choose our Certified-Data-Engineer-Professional study materials this time, I believe you will find our products unique and powerful. Then you don't have to spend extra time searching for information when you're facing other exams later, just choose us again. As long as you face problems with the exam, our company is confident to help you solve. Give our Certified-Data-Engineer-Professional Study Materials a choice is to give you a chance to succeed.
| Section | Objectives |
|---|
| Cost & Performance Optimisation | - Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Apply anonymization and pseudonymization techniques
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Configure Databricks-to-Databricks Sharing
- 3. Share live Lakehouse data with external computing platforms
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Develop unit and integration tests for data processing code
- 2. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 3. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 4. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 5. Use control flow operators in pipeline components
- 6. Configure environments, dependencies, memory, and retry behavior
- 7. Compare streaming tables and materialized views
- 8. Use APPLY CHANGES APIs for change data capture
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Design and implement scalable data models using Delta Lake
- 3. Optimize data layout using Liquid Clustering
|
>> Certified-Data-Engineer-Professional Valid Test Sample <<
Quiz Databricks First-grade Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Valid Test Sample
Because Databricks Certified-Data-Engineer-Professional exam is concerning the future and the destiny of IT people, they pay more attention to the certification. When you decide to choosing IT industry, you have proved your ability. However, what we learn is not enough at all. Databricks Certified-Data-Engineer-Professional Certification will be a big challenge for the candidates. If you decide to join our Getcertkey, we guarantee your success in the first attempt. If you fail, FULL REFUND!
Databricks Certified Data Engineer Professional Sample Questions (Q198-Q203):
NEW QUESTION # 198
A data engineering team has a time-consuming data ingestion job with three data sources. Each notebook takes about one hour to load new data. One day, the job fails because a notebook update introduced a new required configuration parameter. The team must quickly fix the issue and load the latest data from the failing source. Which action should the team take?
- A. Update the task by adding the missing task parameter, and manually run the job.
- B. Repair the run with the new parameter.
- C. Share the analysis with the failing notebook owner so that they can fix it quickly.
- D. Repair the run with the new parameter, and update the task by adding the missing task parameter.
Answer: D
Explanation:
The repair run capability in Databricks Jobs allows re-execution of failed tasks without re-running successful ones. When a parameterized job fails due to missing or incorrect task configuration, engineers can perform a repair run to fix inputs or parameters and resume from the failed state.
This approach saves time, reduces cost, and ensures workflow continuity by avoiding unnecessary recomputation. Additionally, updating the task definition with the missing parameter prevents future runs from failing.
Running the job manually (B) loses run context; (C) alone does not prevent recurrence; (D) delays resolution. Thus, A follows the correct operational and recovery practice.
NEW QUESTION # 199
The following code has been migrated to a Databricks notebook from a legacy workload:
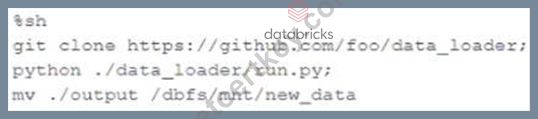
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
- B. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- C. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- D. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- E. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
Answer: C
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 200
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed. Which configuration should be set to enable this?
- A. mergeSchema
- B. partitionBy
- C. checkpointLocation
- D. overwriteSchema
Answer: C
Explanation:
When working with Delta Lake streaming ingestion, checkpointing is critical for maintaining fault tolerance and ensuring exactly-once data processing semantics.
The checkpointLocation parameter defines the directory where Spark Structured Streaming stores progress information, offsets, and metadata. This allows the engine to resume processing from the last committed offset without reprocessing previously ingested data.
Without checkpointing, each stream restart would reprocess all data, leading to duplicates.
Parameters like partitionBy or schema options (mergeSchema / overwriteSchema) affect table structure, not data lineage tracking. Therefore, the correct and required configuration for efficient streaming state management is checkpointLocation.
NEW QUESTION # 201
A Data Engineer is building a fraud detection pipeline that calls out to Open AI, via a Python library, and needs to include an access token when using the API. Which Databricks CLI command should the Data Engineer use to create the secret?
- A. databricks tokens put-token KEY SCOPE; dbutils.secrets.get (KEY, SCOPE)
- B. databricks secrets put-secret KEY SCOPE; dbutils.secrets.get (KEY, SCOPE)
- C. databricks tokens put-token SCOPE KEY; dbutils.tokens.get (SCOPE, KEY)
- D. databricks secrets put-secret SCOPE KEY; dbutils.secrets.get (SCOPE, KEY)
Answer: D
Explanation:
The Databricks CLI command databricks secrets put-secret <scope> <key> is used to securely store sensitive values such as API access tokens in a secret scope. The secret can then be retrieved at runtime using dbutils.secrets.get(scope, key), ensuring credentials are not hard- coded and remain protected.
NEW QUESTION # 202
A company processes semi-structured JSON files from an external source using Auto Loader in a classic Databricks job. Occasionally, records arrive with null critical fields, invalid types, or unexpected nested schema variations. The engineer must ensure that malformed or non- conforming records are not dropped silently and are captured in a separate quarantine table. The pipeline should continue processing good records into the Bronze layer without failing the job, and the approach must support both batch and streaming ingestion.
The data engineer needs to build a robust ingestion pattern that automatically routes bad records to a quarantine Delta table, while still ingesting good records into the Bronze layer for further processing.
Which approach fulfills the quarantine mechanism in this ingestion architecture?
- A. Create a notebook job with inferSchema=True, write a streaming query with .foreachBatch() and catch exceptions using try/except to redirect failed batches to quarantine.
- B. Use Lakeflow Spark Declarative Pipelines with a SQL pipeline; configure it to drop rows with nulls using where critical_fields is not null, and rely on audit logs for malformed data.
- C. Use Auto Loader with LDP and implement an EXPECT () constraint with a record audit logic to route bad records.
- D. Use Auto Loader with failFast mode to set to false, and enable schema evolution; invalid records will be silently ignored during ingestion.
Answer: C
Explanation:
Lakeflow Spark Declarative Pipelines provide built-in support for data quality enforcement using EXPECT clauses. By defining expectations on critical fields and configuring the pipeline to audit or quarantine failed records, malformed or non-conforming JSON records are automatically routed to a quarantine Delta table while valid records continue flowing into the Bronze layer. This approach is robust, auditable, works for both batch and streaming ingestion, and avoids silently dropping bad data or failing the pipeline.
NEW QUESTION # 203
......
Our Certified-Data-Engineer-Professional study prep has inspired millions of exam candidates to pursuit their dreams and motivated them to learn more high-efficiently. Many customers get manifest improvement. Certified-Data-Engineer-Professional simulating exam will inspire your potential. And you will be more successful with the help of our Certified-Data-Engineer-Professional training guide. Just imagine that when you have the certification, you will have a lot of opportunities to come to the bigger companies and get a higher salary.
Certified-Data-Engineer-Professional Interactive Course: https://www.getcertkey.com/Certified-Data-Engineer-Professional_braindumps.html
- Updated Certified-Data-Engineer-Professional Demo 🐗 Reliable Certified-Data-Engineer-Professional Test Syllabus 🥎 Composite Test Certified-Data-Engineer-Professional Price 🍅 Search on ▶ www.troytecdumps.com ◀ for ▛ Certified-Data-Engineer-Professional ▟ to obtain exam materials for free download 🛕Reliable Certified-Data-Engineer-Professional Test Syllabus
- Certified-Data-Engineer-Professional Well Prep 🛂 Test Certified-Data-Engineer-Professional Voucher ✨ Sample Certified-Data-Engineer-Professional Questions Pdf 🖌 Open website ➤ www.pdfvce.com ⮘ and search for ➠ Certified-Data-Engineer-Professional 🠰 for free download 🎇Reliable Certified-Data-Engineer-Professional Test Pass4sure
- Certified-Data-Engineer-Professional Simulations Pdf 😿 Reliable Study Certified-Data-Engineer-Professional Questions 🦽 Certified-Data-Engineer-Professional New Guide Files ⏪ Download ☀ Certified-Data-Engineer-Professional ️☀️ for free by simply searching on ➤ www.vce4dumps.com ⮘ 😶Study Certified-Data-Engineer-Professional Center
- Databricks Certified-Data-Engineer-Professional Valid Test Sample Exam Pass Certify | Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 🗳 Open ▛ www.pdfvce.com ▟ and search for ( Certified-Data-Engineer-Professional ) to download exam materials for free 👓Composite Test Certified-Data-Engineer-Professional Price
- New Certified-Data-Engineer-Professional Test Discount 🍈 Certified-Data-Engineer-Professional Reliable Mock Test 🌑 Reliable Certified-Data-Engineer-Professional Test Syllabus 🍓 The page for free download of { Certified-Data-Engineer-Professional } on ▷ www.troytecdumps.com ◁ will open immediately ✏Sample Certified-Data-Engineer-Professional Questions Pdf
- Certified-Data-Engineer-Professional Valid Test Sample Exam Instant Download | Updated Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 👹 Download ➽ Certified-Data-Engineer-Professional 🢪 for free by simply searching on 「 www.pdfvce.com 」 👴Valid Braindumps Certified-Data-Engineer-Professional Book
- 100% Pass Trustable Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Valid Test Sample 🕟 Search for “ Certified-Data-Engineer-Professional ” and download it for free on ▷ www.dumpsquestion.com ◁ website 🗣Valid Braindumps Certified-Data-Engineer-Professional Book
- Pass Guaranteed Databricks - Certified-Data-Engineer-Professional - High Pass-Rate Databricks Certified Data Engineer Professional Valid Test Sample 🐐 Open ▛ www.pdfvce.com ▟ enter { Certified-Data-Engineer-Professional } and obtain a free download 🕴Reliable Certified-Data-Engineer-Professional Test Pass4sure
- Certified-Data-Engineer-Professional Study Tool - Certified-Data-Engineer-Professional Test Torrent -amp; Databricks Certified Data Engineer Professional Guide Torrent 💘 Download 《 Certified-Data-Engineer-Professional 》 for free by simply searching on 【 www.pdfdumps.com 】 🤬Valid Braindumps Certified-Data-Engineer-Professional Book
- New Certified-Data-Engineer-Professional Test Discount 👰 Certified-Data-Engineer-Professional Reliable Mock Test ☔ Reliable Certified-Data-Engineer-Professional Test Pass4sure ⛰ Easily obtain 《 Certified-Data-Engineer-Professional 》 for free download through ➤ www.pdfvce.com ⮘ 🧕Certified-Data-Engineer-Professional New Guide Files
- Book Certified-Data-Engineer-Professional Free 🐲 Test Certified-Data-Engineer-Professional Voucher ✔ Certified-Data-Engineer-Professional New Guide Files 🎐 Search for ➠ Certified-Data-Engineer-Professional 🠰 and easily obtain a free download on ⏩ www.pdfdumps.com ⏪ 👡Certified-Data-Engineer-Professional Well Prep
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes