You only need 20-30 hours to practice our software materials and then you can attend the exam. It costs you little time and energy. The AI-200 exam questions are easy to be mastered and simplified the content of important information. The Developing AI Cloud Solutions on Azure test guide conveys more important information with amount of answers and questions, thus the learning for the examinee is easy and highly efficient. The language which is easy to be understood and simple, AI-200 Exam Questions are suitable for any learners no matter he or she is a student or the person who have worked for many years with profound experiences. So it is convenient for the learners to master the AI-200 guide torrent and pass the exam in a short time. The amount of the examinee is large.
| Section | Objectives |
|---|---|
| Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
| Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Plan security and compliance requirements - Monitor and optimize AI solutions |
| Implement Azure AI solutions | - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions - Implement computer vision solutions - Implement knowledge mining with Azure AI Search |
This Developing AI Cloud Solutions on Azure (AI-200) practice exam software is easily accessible on all Windows laptops and computers. You do not require an active internet connection after installation of the Developing AI Cloud Solutions on Azure (AI-200) practice exam software. Repetitive attempts of Developing AI Cloud Solutions on Azure (AI-200) exam dumps boosts confidence and provide familiarity with the AI-200 actual exam format.
NEW QUESTION # 53
Hotspot Question
You have a web service that is used to pay for food deliveries. The web service uses Azure Cosmos DB as the data store.
You plan to add a new feature that allows users to set a tip amount. The new feature requires that a property named tip on the document in Azure Cosmos DB must be present and contain a numeric value.
There are many existing websites and mobile apps that use the web service that will not be updated to set the tip property for some time.
How should you complete the trigger?
NOTE: Each correct selection is worth one point.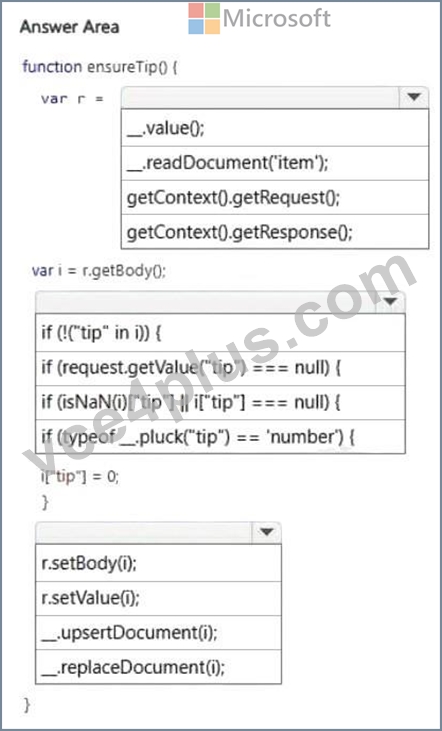
Answer:
Explanation: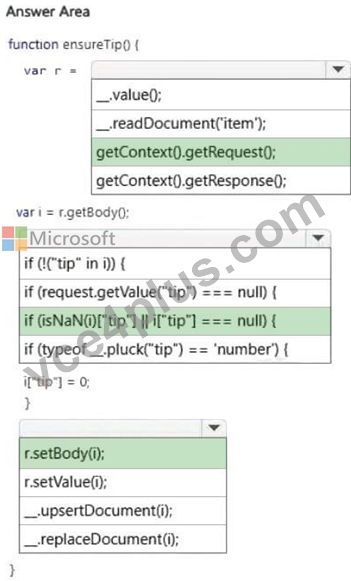
Explanation:
Box 1: getContext().getRequest();
Y: if (!i["tip"]) { (or alternatively: depending on your specific exam question version)Z:
Box 2: if (isNaN(i["tip"]) || i["tip"] === null) {
Box 3: r.setBody(i);
NEW QUESTION # 54
Drag and Drop Question
You are investigating high latency in an AI search application that processes millions of requests daily. Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
- Include only data from the last 24 hours.
- Filter for failed requests only.
- Calculate the average duration of dependencies, grouped by operation.
The query must be optimized for performance by minimizing the initial data scan.
You need to create the query.
Which five actions should you perform in sequence? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.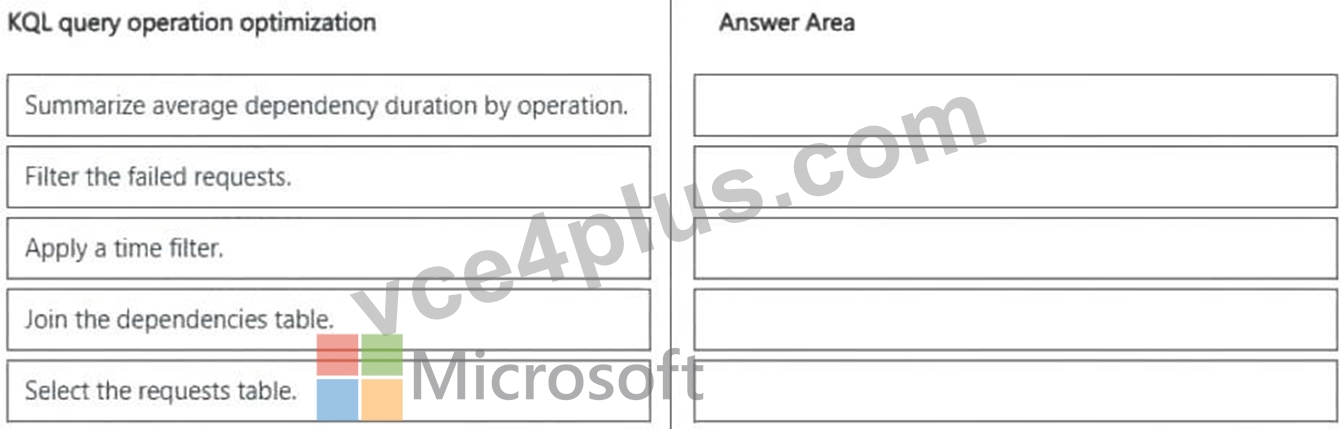
Answer:
Explanation: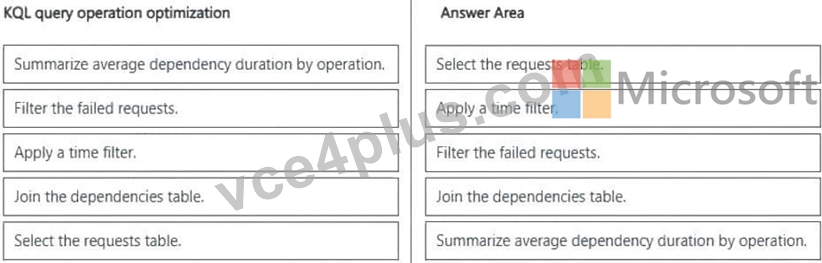
Explanation:
Step 1: Select the requests table
Starts the query stream with the primary base table.
Step 2: Apply a time filter
Such as (where timestamp >= ago(1d))
Restricts the dataset to the last 24 hours immediately to optimize performance by reducing the scan size.
Step 3: Filter the failed requests
where success == false or resultCode checks
Narrows down rows to only failures before performing resource-heavy operations.
Step 4: Join the dependencies table
(join AppDependencies): Correlates the filtered request subset with dependency data using common tracking identifiers.
Step 5: Summarize average dependency duration by operation (summarize avg(duration) by operation) Computes the final aggregated metrics grouped by the operation name.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/logs/get-started-queries
NEW QUESTION # 55
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to optimize secure database connectivity from the containerized Recommendation API.
How should you configure the application? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.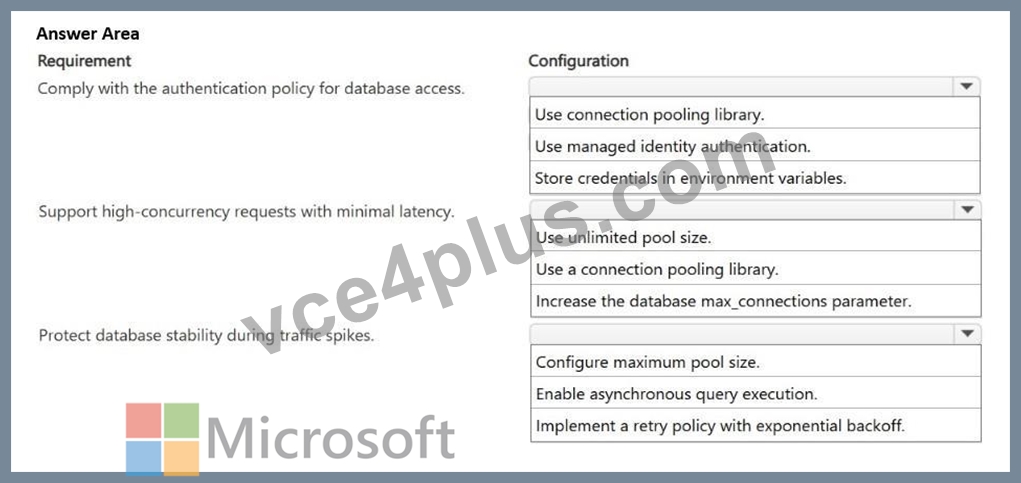
Answer:
Explanation: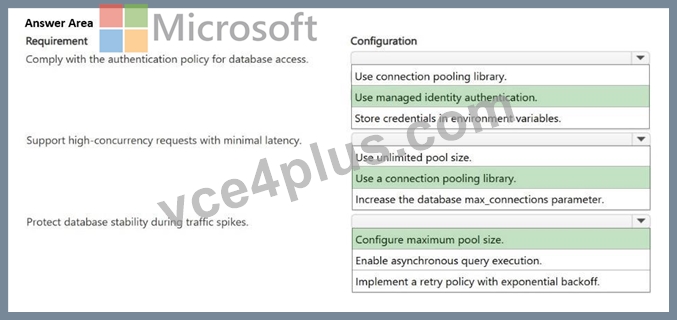
Explanation:
Box 1: Use managed identity authentication.
Scenario: Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited.' Box 2: Use a connection pooling library Scenario: Environment: Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
To support high-concurrency requests with minimal latency on Azure Database for PostgreSQL, the best action is to use a connection pooling library (or leverage Azure's built-in PgBouncer feature).
Eliminates Connection Overhead:
PostgreSQL utilizes a process-per-connection model. Forking a new backend process for every incoming request introduces substantial CPU and memory overhead, severely degrading latency under high concurrency. A connection pool keeps a warm set of reusable database sessions active.
Optimized for Azure: Microsoft provides a built-in managed PgBouncer integration for Azure Database for PostgreSQL. Enabling it in transaction mode allows the database to accept thousands of concurrent client connections while keeping actual backend processes lean and stable Box 3: Configure a maximum pool size Configure a maximum pool size is the best action to directly protect database stability during sudden traffic spikes.
Prevents Resource Exhaustion: Traffic spikes naturally lead to a surge in connection requests.
Unchecked connections consume substantial RAM and CPU overhead, which can crash the database or trigger severe latency. Limiting the pool size stops the "thundering herd" problem Acts as a Shock Absorber: When the pool hits its maximum limit, extra client requests are safely queued at the application or connection pooling layer (like Azure's built-in PgBouncer proxy) rather than overwhelming the database backend Reference:
https://docs.azure.cn/en-us/postgresql/connectivity/concepts-pgbouncer
https://learn.microsoft.com/en-au/answers/questions/5884412/best-practise-azure-postgresql-flexible-server-max
NEW QUESTION # 56
You are developing an AI search API that caches semantic search results in Redis.
Search results must remain cached for 10 minutes. If the underlying data changes, cached entries must NOT be returned.
You need to implement a cache aside strategy to ensure data consistency.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
Detailed Explanation: The cache-aside design needs both bounded lifetime and explicit invalidation. A ten- minute TTL ensures cached search results do not persist indefinitely, while deleting related keys when source data changes prevents known-stale entries from being returned during that ten-minute window. Sliding expiration would extend lifetime based on access and can preserve stale data. Keyspace notifications report Redis key events; they do not replace application logic that invalidates entries when the authoritative source changes.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Managed Redis documentation
NEW QUESTION # 57
A large retail company operates online and physical stores. The company tracks inventory levels in real time to manage stock efficiently across all locations. You develop an Azure Event Grid solution to handle events generated by the inventory management system deployed to Azure.
You need to implement a subscription filter that dynamically adjusts to seasonal changes in product demand.
Which event filter should you use?
Answer: D
Explanation:
To handle dynamic, seasonal changes in product demand within Azure Event Grid, you should use Advanced Filters with a string or numeric comparison that evaluates event data attributes, typically paired with an automated external process (like an Azure Function or Logic App) to dynamically update the subscription filter rules via the Event Grid management API as seasons change Reference:
https://techcommunity.microsoft.com/blog/analyticsonazure/a-technical-implementation-guide-for-multi-store-retail-environments/4488418
NEW QUESTION # 58
......
If you buy our AI-200 study materials, then you can enjoy free updates for one year. After you start learning, I hope you can set a fixed time to check emails. If the content of the AI-200 practice guide or system is updated, we will send updated information to your e-mail address. Of course, you can also consult our e-mail on the status of the product updates. I hope we can work together to make you better use our AI-200 simulating exam.
Exam AI-200 Consultant: https://www.vce4plus.com/Microsoft/AI-200-valid-vce-dumps.html