What's more, part of that ITPassLeader HPE7-J01 dumps now are free: https://drive.google.com/open?id=1p6vEJWw08fYeOM7t354clySGk5py5wIU
In recent years, fierce competition agitates the forwarding IT industry in the world. And IT certification has become a necessity. If you want to get a good improvement in your career, The method that using the ITPassLeader’s HP HPE7-J01 Exam Training materials to obtain a certificate is very feasible. Our exam materials are including all the questions which the exam required. So the materials will be able to help you to pass the exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deployment and Integration | 20% | - Networking and connectivity
|
| Topic 2: Emerging Technologies and Solutions | 10% | - Software-defined storage and modern architectures
|
| Topic 3: Storage Architecture and Design | 30% | - Design principles for enterprise storage
|
| Topic 4: Management and Optimization | 15% | - Monitoring and administration
|
| Topic 5: Data Protection and Availability | 25% | - Backup and recovery strategies
|
Many customers may doubt the quality of our HP HPE7-J01 learning quiz since they haven't tried them. But our HPE7-J01 training engine is reliable. What you have learnt on our Advanced HPE Storage Architect Solutions Written Exam HPE7-J01 Exam Materials are going through special selection. The core knowledge of the real exam is significant.
NEW QUESTION # 24
A storage administrator will be implementing the HPE Peer Persistence feature between many arrays at many different sites across the company. The administrator will be using the Quorum Witness (QW) solution to determine when automatic failover will occur between the primary and secondary arrays. Which statement is correct regarding the use of this feature?
Answer: C
Explanation:
The HPE Quorum Witness (QW) is a critical component for facilitating Automatic Transparent Failover (ATF) in Peer Persistence, Active Peer Persistence, and Active Sync Replication configurations. Its primary architectural purpose is to act as an independent "tie-breaker" during a split-brain scenario--a situation where the storage arrays lose their heartbeat/replication links and both attempt to claim primary ownership of the volumes.
According to HPE documentation, the Quorum Witness must be installed at a third, neutral site that is geographically separate and failure-independent from the sites hosting the primary and secondary arrays. This "Third Site" placement ensures that if either site hosting an array experiences a total power or network failure, the remaining array can still reach the Quorum Witness via the network to obtain a "quorum vote" and safely assume the primary role without manual intervention. If the QW were placed at the same site as one of the arrays, a failure at that site would take down both the storage and the witness, preventing the surviving array at the other site from achieving quorum for an automatic failover. Connectivity to the Quorum Witness is strictly over IP (Ethernet); it does not require Fibre Channel (FC) connectivity.
NEW QUESTION # 25
Refer to the exhibit.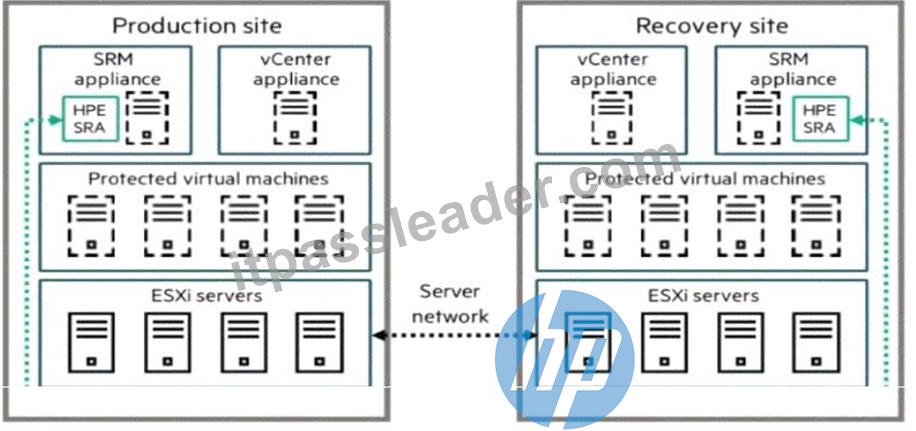
A company is implementing a disaster recovery solution. The Asynchronous Remote Copy feature has been implemented between the HPE AUetra 9000 arrays at both sites. The customer Is interested in providing a disaster recovery (DR) solution that allows for business connectivity of their VMware VMs.
Which VMware solution should the company implement?
Answer: D
Explanation:
To provide automated orchestration and business continuity for VMware virtual machines in a disaster recovery scenario, the industry-standard solution integrated with HPE storage is VMware Live Site Recovery (formerly known as VMware Site Recovery Manager or SRM).
When a customer utilizes Asynchronous Remote Copy on HPE Alletra 9000 arrays, the storage layer handles the data replication between the production and recovery sites. However, the storage array alone cannot automate the re-registration of virtual machines, the mapping of network port groups, or the specific power-on sequencing required for complex applications at the secondary site. VMware Live Site Recovery serves as the orchestration engine that bridges this gap. It works in conjunction with a Storage Replication Adapter (SRA) provided by HPE. The HPE SRA allows the VMware software to communicate directly with the Alletra 9000 arrays to initiate tasks such as promoting recovery volumes to a read-write state, taking temporary snapshots for DR testing, and automating the "failover" and "failback" workflows.
As shown in the exhibit (image_6601ef.jpg), a complete solution requires an SRM appliance and a vCenter appliance at both the production and recovery sites. This architecture ensures that even if the primary site is completely lost, the recovery site has all the necessary metadata and orchestration instructions to bring the business-critical VMs online with minimal manual intervention. Option A (Lifecycle Management) is for patching and updates, Option D (Storage DRS) is for load balancing within a cluster, and Option C refers to operational monitoring rather than disaster recovery orchestration. For a customer already invested in Alletra
9000 Remote Copy, VMware Live Site Recovery is the "Better Together" choice for achieving low Recovery Time Objectives (RTO).
NEW QUESTION # 26
An HPE Partner is talking to a potential customer about the HPE Alletra MP B10000 storage array solution.
What is an important feature the partner should share with the customer?
Answer: C
Explanation:
The HPE Alletra MP B10000 (Block storage) represents a paradigm shift in HPE's high-end storage strategy by utilizing a modular, disaggregated architecture. One of the most significant technical advantages of this platform is its Advanced Erasure Coding and the way it handles data layout across the disaggregated NVMe capacity.
According to the HPE Alletra MP technical deep-dive documents, the system does not use traditional fixed RAID groups. Instead, it uses a massive, distributed stripe mechanism. The software is capable of varying the stripe width dynamically based on the number of available drives and nodes in the cluster. This allows the system to achieve industry-leading capacity efficiency. Specifically, the system can utilize stripe sizes ranging from a minimum of 16+3 to a maximum of 146+3. This high data-to-parity ratio (e.g., 146 data segments for every 3 parity segments) allows customers to realize significantly higher usable capacity from their raw NVMe investment compared to traditional RAID 6 (6+2 or 8+2) or even typical erasure coding in competitive mid-range arrays.
Option A is technically incorrect because, in the Alletra MP, data is typically committed to persistent NVMe media or SCM (Storage Class Memory) in a way that doesn't rely on legacy battery-backed volatile DRAM in the same manner as older controllers. Option C is incorrect because Locally Decodable Erasure Coding is actually designed to reduce rebuild times by requiring fewer IOPS to reconstruct a missing fragment. Option D, while "Workload Simulator" is a tool used in sizing (NinjaStars), the most "important" architectural feature listed that differentiates the Alletra MP's efficiency is its unique and massive scaling stripe width.
NEW QUESTION # 27
An administrator is setting up Zerto for data protection. The Zerto Virtual Manager <ZVM> has been installed and configured. The administrator is ready to deploy the Zerto Virtual Replication Appliances (VRAs) Use your cursor to place a + on the ZVM screen to deploy the VRAs.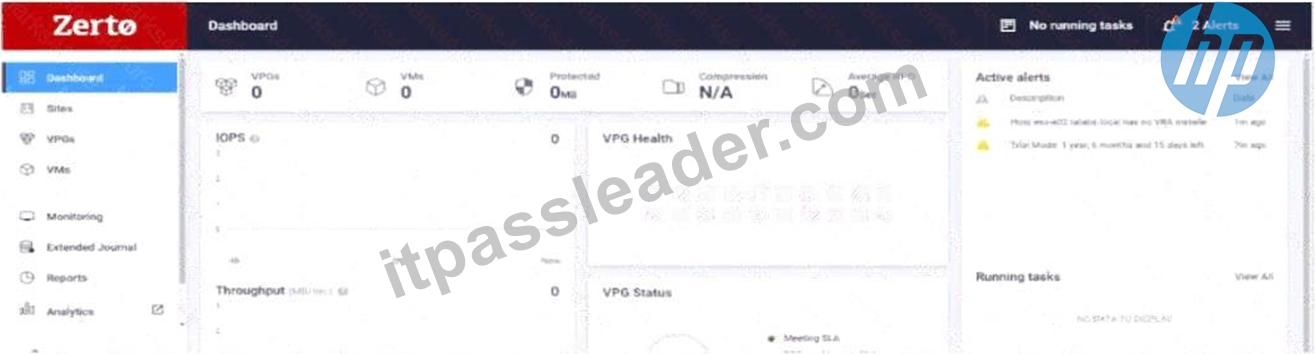
Answer:
Explanation: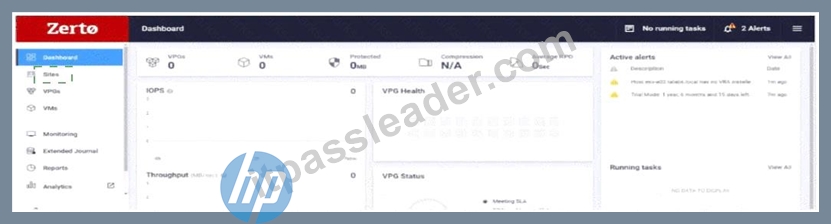
Explanation:
Sites
The Zerto Virtual Replication Appliance (VRA) is a critical architectural component of the Zerto solution.
It is a lightweight Linux-based virtual machine that must be installed on every hypervisor host (ESXi or Hyper-V) in both the production and recovery sites that will host protected virtual machines. The VRA is responsible for intercepting the I/O writes from the VMs and asynchronously replicating them to the recovery site.
In the Zerto Virtual Manager (ZVM) web interface shown in the exhibit (image_649973.png), the management of site-level infrastructure is centralized within the "Sites" tab. By clicking on this tab, the administrator accesses the view for both local and paired remote sites. Within the Local Site details, there is a sub-tab for "VRAs" or "Hosts" where the administrator can see a list of all hosts managed by the connected vCenter or SCVMM.
To deploy a VRA, the administrator selects the host(s) currently missing the appliance and clicks the "Install" button. The ZVM then automates the deployment, configuring the VRA with the necessary network settings and registering it with the hypervisor. Notably, the "Active alerts" window in the exhibit explicitly provides a hint: it shows an alert stating that "Host esx-e02.telabs.local has no VRA installed". Clicking on the "Sites" tab is the foundational step to resolve this alert and finalize the infrastructure setup required to begin creating Virtual Protection Groups (VPGs).
NEW QUESTION # 28
A customer intentionally removes all three drives from a JBOF from an HPE Alletra MP X10000 used in an HPE GreenLake for File Storage solution. What is the correct description of the result of this action?
Answer: B
Explanation:
The HPE Alletra MP X10000, which powers HPE GreenLake for File Storage, utilizes a disaggregated shared-everything (DASE) architecture based on VAST Data software. Unlike traditional RAID, this architecture uses highly advanced locally decodable erasure coding.
While the system is designed to be incredibly resilient-often surviving multiple concurrent drive failures across the cluster-the removal of three drives simultaneously from a single JBOF (Just a Bunch of Flash) chassis can exceed the immediate "vertical" stripe protection thresholds, especially in smaller cluster configurations. In the Alletra MP File architecture, the metadata and data are distributed with specific redundancy parameters. Intentionally pulling three drives at once is treated as a multi-point catastrophic failure rather than a standard drive wear-out event.
When such an event occurs, the system enters a "Fail-Stop" state to protect data integrity and prevent file system corruption. Because the system cannot guarantee the consistency of the data stripes or the underlying V-Trees (metadata structures), it will cease I/O services. Simply reinserting the drives (Option B) will not automatically bring the file system back online because the system likely marked those drives as "failed" or
"stale" the moment they were removed. Recovery requires HPE Level 3 Support and Engineering to perform a manual "forced mount" or metadata reconstruction process to verify that no partial writes occurred during the removal. This is a high-touch recovery scenario designed to ensure that when the data becomes available again, it is 100% consistent.
NEW QUESTION # 29
......
Our worldwide after sale staffs will provide the most considerate after-sale service for you in twenty four hours a day, seven days a week, that is to say, no matter you are or whenever it is, as long as you have any question about our HPE7-J01 exam torrent or about the exam or even about the related certification,you can feel free to contact our after sale service staffs who will always waiting for you on the internet. Wherever you are in the world we will provide you with the most useful and effectively HPE7-J01 Guide Torrent in this website, which will help you to pass the exam as well as getting the related certification with a great ease.
Test HPE7-J01 Pass4sure: https://www.itpassleader.com/HP/HPE7-J01-dumps-pass-exam.html
2026 Latest ITPassLeader HPE7-J01 PDF Dumps and HPE7-J01 Exam Engine Free Share: https://drive.google.com/open?id=1p6vEJWw08fYeOM7t354clySGk5py5wIU