無料でクラウドストレージから最新のJapancert DP-100 PDFダンプをダウンロードする:https://drive.google.com/open?id=1Envkly4WjjcHg__mJ7QbLnK6K6aBHmKs
JapancertのMicrosoftのDP-100試験資料は同じシラバスに従って研究されたのです。それに、資料もずっとアップグレードしていますから、実際の試験問題とよく似ています。Japancertの試験合格率も非常に高いことは否定することができない事実です。JapancertのMicrosoftのDP-100試験トレーニング資料の値段は手頃で、IT認証の受験生のみなさんによく適用します。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Designing and Implementing a Data Science Solution on Azure |
| Exam Number: | DP-100 |
| Exam Price: | USD 165 (varies by region) |
| Related Certifications: | Microsoft Certified: Azure Data Scientist Associate |
| Passing Score: | 700/1000 |
| Certificate Validity Period: | 1 year (renewable through Microsoft certification renewal assessment) |
| Exam Duration: | 100-120 |
| Real Exam Qty: | 40-60 |
| Exam Format: | Drag and drop, Hands-on lab tasks, Case studies, Multiple response, Multiple choice |
| Available Languages: | Korean, Spanish, Russian, English, Portuguese (Brazil), Simplified Chinese, German, French, Japanese |
| Recommended Training: | Microsoft Learn - DP-100 Learning Path Azure Machine Learning Documentation |
| Exam Registration: | Official Microsoft Certification Page Pearson VUE Registration |
| Sample Questions: | Microsoft DP-100 Sample Questions |
| Exam Way: | Online proctored or in-person at authorized testing centers (Pearson VUE) |
| Pre Condition: | No mandatory prerequisites. Recommended familiarity with Python, machine learning concepts, and Azure fundamentals. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/azure-data-scientist/ |
ほかの人はあちこちMicrosoftのDP-100試験の資料を探しているとき、あなたは問題集の勉強を始めました。準備の段階であなたはリーダーしています。我々Japancertの提供するMicrosoftのDP-100試験のソフトは豊富な試験に関する資源を含めてあなたに最も真実のMicrosoftのDP-100試験環境で体験させます。
Microsoft DP-100 認定試験は、Azure プラットフォーム上でのデータサイエンスソリューションの設計と実装におけるスキルと知識を証明したいデータサイエンスプロフェッショナルにとって、貴重な認定資格です。データサイエンスやAzureのツールやサービスに関連する幅広いトピックをカバーしており、求人市場での差別化や収益性の向上に役立ちます。適切な準備をすれば、試験に合格して、Azure上の認定データサイエンスプロフェッショナルとなることができます。
質問 # 40
You use Azure Machine Learning designer to create a training pipeline for a regression model.
You need to prepare the pipeline for deployment as an endpoint that generates predictions asynchronously for a dataset of input data values.
What should you do?
正解:C
解説:
You must first convert the training pipeline into a real-time inference pipeline. This process removes training modules and adds web service inputs and outputs to handle requests.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/tutorial-designer-automobile-price-deploy
https://docs.microsoft.com/en-us/azure/machine-learning/algorithm-module-reference/enter-data-manually
質問 # 41
You have the following Azure subscriptions and Azure Machine Learning service workspaces:
You need to obtain a reference to the mi-protect workspace
Solution: Run the following Python code.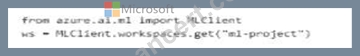
Does the solution meet the goal?
正解:A
質問 # 42
You are building an intelligent solution using machine learning models.
The environment must support the following requirements:
Data scientists must build notebooks in a cloud environment
Data scientists must use automatic feature engineering and model building in machine learning pipelines.
Notebooks must be deployed to retrain using Spark instances with dynamic worker allocation.
Notebooks must be exportable to be version controlled locally.
You need to create the environment.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.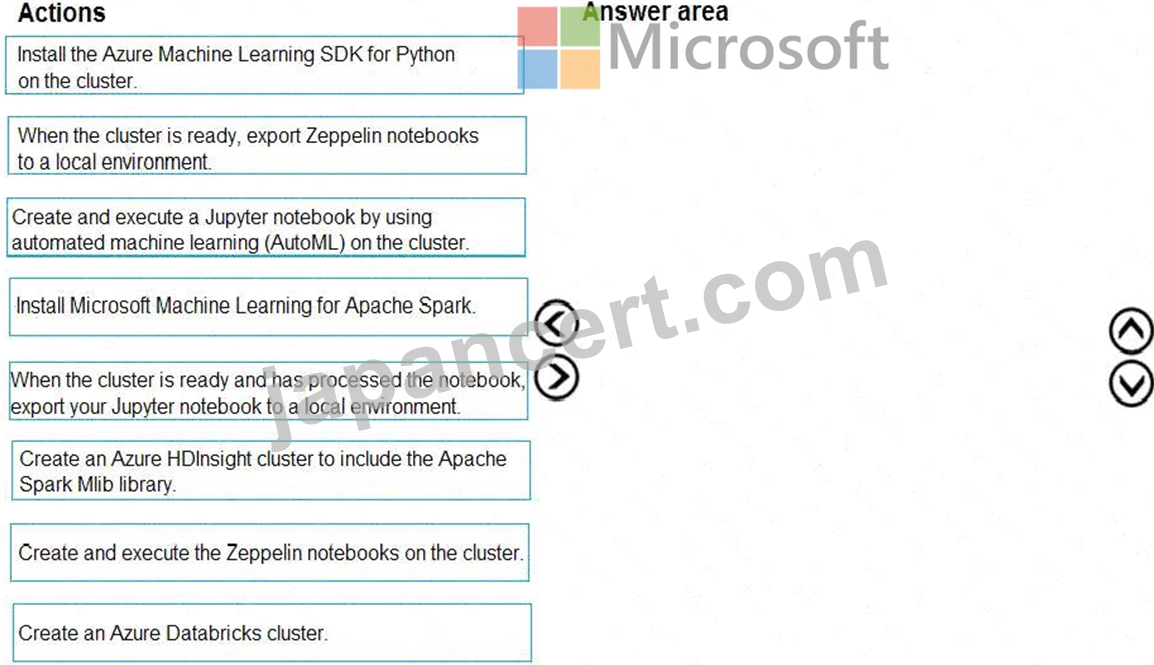
正解:
解説: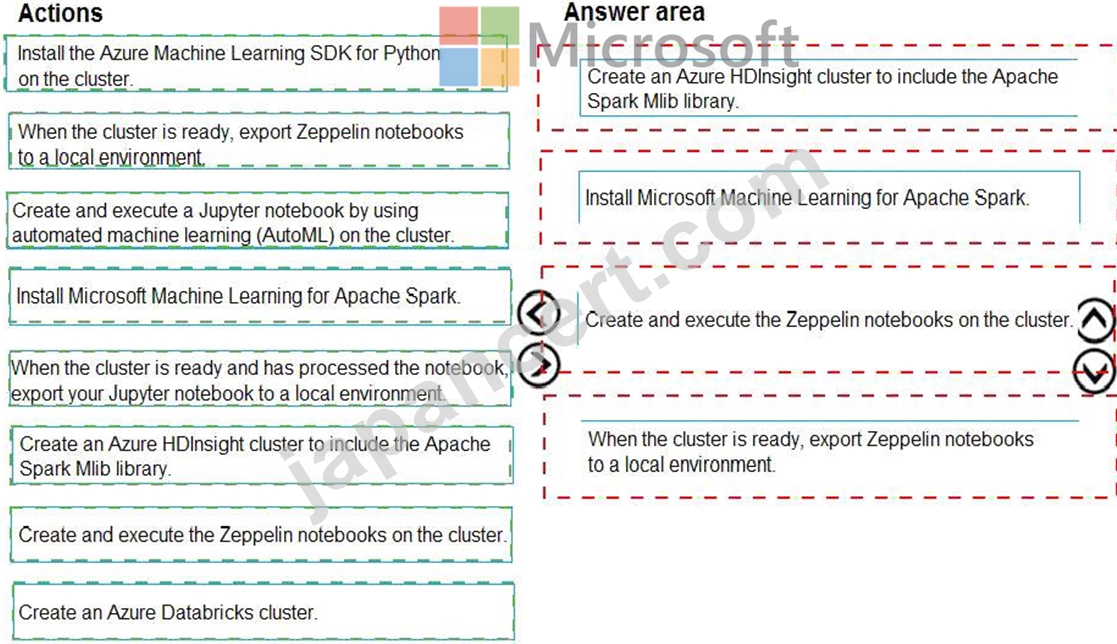
Explanation: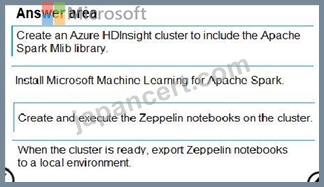
Step 1: Create an Azure HDInsight cluster to include the Apache Spark Mlib library Step 2: Install Microsot Machine Learning for Apache Spark You install AzureML on your Azure HDInsight cluster.
Microsoft Machine Learning for Apache Spark (MMLSpark) provides a number of deep learning and data science tools for Apache Spark, including seamless integration of Spark Machine Learning pipelines with Microsoft Cognitive Toolkit (CNTK) and OpenCV, enabling you to quickly create powerful, highly-scalable predictive and analytical models for large image and text datasets.
Step 3: Create and execute the Zeppelin notebooks on the cluster
Step 4: When the cluster is ready, export Zeppelin notebooks to a local environment.
Notebooks must be exportable to be version controlled locally.
References:
https://docs.microsoft.com/en-us/azure/hdinsight/spark/apache-spark-zeppelin-notebook
https://azuremlbuild.blob.core.windows.net/pysparkapi/intro.html
質問 # 43
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You use Azure Machine Learning designer to load the following datasets into an experiment: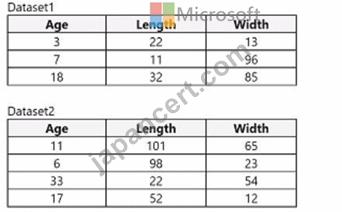
You need to create a dataset that has the same columns and header row as the input datasets and contains all rows from both input datasets.
Solution: Use the Join Data module.
Does the solution meet the goal?
正解:A
質問 # 44
You create a classification model with a dataset that contains 100 samples with Class A and
10,000 samples with Class B
The variation of Class B is very high.
You need to resolve imbalances.
Which method should you use?
正解:C
質問 # 45
......
DP-100認定テキスト: https://www.japancert.com/DP-100.html
P.S. JapancertがGoogle Driveで共有している無料かつ新しいDP-100ダンプ:https://drive.google.com/open?id=1Envkly4WjjcHg__mJ7QbLnK6K6aBHmKs