IT인증자격증을 취득하는 것은 IT업계에서 자신의 경쟁율을 높이는 유력한 수단입니다. 경쟁에서 밀리지 않으려면 자격증을 많이 취득하는 편이 안전합니다.하지만 IT자격증취득은 생각보다 많이 어려운 일입니다. Microsoft인증 DP-750시험은 인기자격증을 취득하는데 필요한 시험과목입니다. Itexamdump는 여러분이 자격증을 취득하는 길에서의 없어서는 안될 동반자입니다. Itexamdump의Microsoft인증 DP-750덤프로 자격증을 편하게 취득하는게 어떨가요?
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 2: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 3: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
Itexamdump는 많은 IT인사들이Microsoft인증시험에 참가하고 완벽한DP-750인증시험자료로 응시하여 안전하게Microsoft DP-750인증시험자격증 취득하게 하는 사이트입니다. Pass4Tes의 자료들은 모두 우리의 전문가들이 연구와 노력 하에 만들어진 것이며.그들은 자기만의 지식과 몇 년간의 연구 경험으로 퍼펙트하게 만들었습니다.우리 덤프들은 품질은 보장하며 갱신 또한 아주 빠릅니다.우리의 덤프는 모두 실제시험과 유사하거나 혹은 같은 문제들임을 약속합니다.Itexamdump는 100% 한번에 꼭 고난의도인Microsoft인증DP-750시험을 패스하여 여러분의 사업에 많은 도움을 드리겠습니다.
질문 # 63
You have an Azure Databricks workspace
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically. You need to configure compute for the pipeline. The solution must minimize operational costs and effort. What should you use?
정답:C
설명:
The correct answer is C - a job cluster that uses autoscaling.
Job clusters (also called pipeline clusters in the SDP context) are created exclusively for a pipeline run and terminated when the pipeline stops. You pay only for what the pipeline uses, and there's no idle cost between runs. Autoscaling on a job cluster lets the pipeline expand during heavy processing and contract during lighter stages - the combination of on-demand lifecycle and elastic scaling gives the lowest operational cost.
Option A (all-purpose cluster) runs at a higher DBU rate and persists beyond the pipeline's lifecycle, meaning you're paying for it even when the pipeline isn't running. Option B (SQL warehouse) is optimised for interactive BI and ad-hoc queries, not for the batch/streaming workloads SDP pipelines run. Option D (single- node all-purpose) has no scaling, runs at the all-purpose DBU rate, and is capped at one node - unsuitable for any production pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/configure-pipeline
질문 # 64
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Tabid.
Table! is written by batch jobs every hour and is queried frequently by filtering two columns named Customerld and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.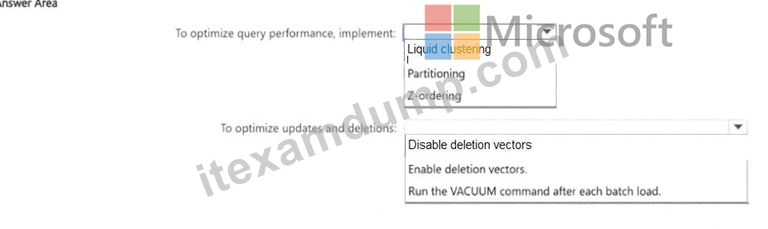
정답:
설명: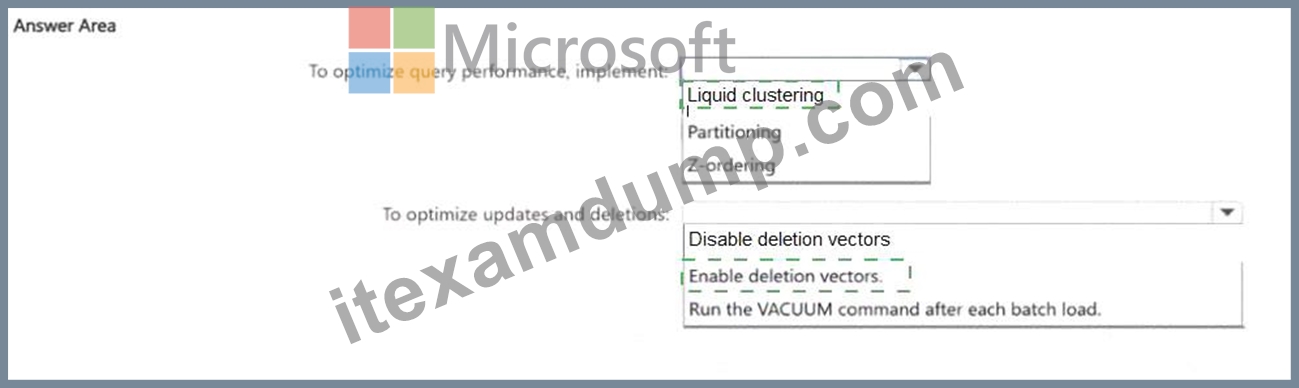
Explanation:
Two features work together to keep performance consistent and update costs low:
OPTIMIZE with ZORDER BY (CustomerId, EventDate). Z-Ordering co-locates rows with the same CustomerId and EventDate values in the same Parquet files. When a query filters on those columns, the Delta engine uses file statistics to skip files that can't possibly contain matching rows (data skipping). As the table grows, skipping scales proportionally - query time stays consistent.
Deletion Vectors (delta.enableDeletionVectors = true). When a row is updated or deleted, instead of rewriting the entire Parquet file, Delta marks the affected row in a small companion deletion vector file. This dramatically reduces write amplification for the frequent compliance-driven updates and deletions the question describes. Actual file rewrites are deferred to the next OPTIMIZE run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/data-skipping
질문 # 65
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job! that processes data continuously and fails periodically due to transient errors You need to ensure that Job! meets the following requirements
* Resumes processing from the point that Job1 failed
* Minimizes how long it takes to restart Job!
* Minimizes the costs to restart Job!
What should you do?
정답:D
설명:
The correct answer is B - implement checkpointing.
A checkpoint is a durable record of the streaming job's progress written to ADLS Gen2 or DBFS after each successfully committed micro-batch. When the job restarts after a transient failure, it reads the checkpoint to find the last committed offset and resumes from that exact point - no data is reprocessed, no data is lost.
This satisfies all three requirements directly: checkpointing enables resumption from the failure point (not from the beginning), restart is fast because there's no replay overhead, and costs are minimised because no compute is wasted reprocessing records already handled.
Option A (decrease retry interval) makes the job retry sooner but doesn't control where it resumes from.
Option C (alert and manual restart) adds human latency and doesn't prevent reprocessing without a checkpoint. Option D (increase minimum nodes) reduces the likelihood of resource-related failures but increases cost and doesn't address the recovery behaviour itself.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
질문 # 66
Which feature helps reduce data scan during query execution in Delta Lake?
정답:C
설명:
Delta Lake uses data skipping based on file-level statistics (min/max values). This reduces unnecessary file scans and improves query performance. VACUUM removes old files but does not improve query speed. Cluster restart has no impact on query optimization.
질문 # 67
You use Declarative Automation Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements:
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
정답:C
설명:
The targets mapping defines environment-specific deployment configurations within one databricks.yml file.
Development and production targets can apply different resource settings or exclusions while sharing the bundle's common definitions. This allows the app to be deployed to both environments and limits the development deployment to the required job without maintaining duplicate configuration files. Separate YAML files would duplicate shared settings and increase maintenance effort. The resources mapping declares jobs, pipelines, apps, and other Databricks resources but does not independently provide environment-specific deployment behavior. Variables provide reusable values and substitutions; they are not the primary mechanism for defining deployment environments. Declarative Automation Bundle targets are explicitly intended to model configurations such as development, staging, and production in a single bundle. Microsoft Learn
질문 # 68
......
Itexamdump에서 Microsoft DP-750 덤프를 다운받아 공부하시면 가장 적은 시간만 투자해도Microsoft DP-750시험패스하실수 있습니다. Itexamdump에서Microsoft DP-750시험덤프를 구입하시면 퍼펙트한 구매후 서비스를 제공해드립니다. Microsoft DP-750덤프가 업데이트되면 업데이트된 최신버전을 무료로 제공해드립니다. 시험에서 불합격성적표를 받으시면 덤프구매시 지불한 덤프비용은 환불해드립니다.
DP-750인증시험대비 덤프공부: https://www.itexamdump.com/DP-750.html