Use Real Databricks Databricks-Certified-Data-Engineer-Associate Exam Questions [2026] To Gain Brilliant Result

BTW, DOWNLOAD part of ValidTorrent Databricks-Certified-Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=13PhLHv9PrKvaa6tzL9WM-eJEc3iSU4Sf
If you want to prepare for your exam in a paper version, our Databricks-Certified-Data-Engineer-Associate test materials can do that for you. Databricks-Certified-Data-Engineer-Associate PDF version is printable and you can print them into hard one, and take some notes on them. In addition, we offer you free demo to have a try, so that you can have a better understanding of what you are going to buy. We are pass guarantee and money back guarantee for Databricks-Certified-Data-Engineer-Associate Exam Dumps, if you fail to pass the exam, we will give you full refund. Online and offline chat service are available, if you have any questions about Databricks-Certified-Data-Engineer-Associate exam materials, you can have a conversation with us, and we will give you reply soon as possible.
| Section | Objectives |
|---|
| Data Ingestion and ELT Development | - ETL patterns and transformations
- Handling structured and semi-structured data
- Data ingestion using Spark SQL and PySpark
|
| Productionizing Data Pipelines | - Pipeline deployment and operationalization
- Databricks Workflows / Jobs orchestration
- Scheduling and monitoring jobs
|
| Databricks Lakehouse Platform Fundamentals | - Clusters, notebooks, and basic Databricks environment usage
- Workspace, architecture, and core platform concepts
|
| Data Governance and Quality | - Data quality concepts and management
- Data access control and governance
- Unity Catalog basics
|
| Data Processing and Transformations | - Apache Spark SQL operations (joins, aggregations, filtering)
- User-defined functions (UDFs)
- PySpark DataFrame transformations
- Delta Lake fundamentals (tables, transactions, optimization)
|
>> Instant Databricks-Certified-Data-Engineer-Associate Access <<
Databricks Databricks-Certified-Data-Engineer-Associate Pass Guaranteed | Updated Databricks-Certified-Data-Engineer-Associate Demo
If you feel nervous about the exam, then you can try the Databricks-Certified-Data-Engineer-Associate exam dumps of us. It will help you to release your nerves. Databricks-Certified-Data-Engineer-Associate Soft test engine can stimulate the real exam environment, if you use this version, it will help you know the procedures of the exam. In addition, Databricks-Certified-Data-Engineer-Associate Exam Materials are verified by experienced experts, and the quality can be guaranteed. Databricks-Certified-Data-Engineer-Associate exam dumps have both questions and answers, and they may benefit your practice.
Databricks Certified Data Engineer Associate Exam Sample Questions (Q294-Q299):
NEW QUESTION # 294
A Databricks single-task workflow fails due to an error in a notebook. The data engineer fixes the mistake in the notebook.
What should the data engineer do to rerun the workflow?
- A. Restart the Cluster
- B. Repair the task
- C. Swap the cluster
- D. Repair the run
Answer: D
Explanation:
Rerunning a failed workflow after fixing the notebook requires repairing the run so the task is re- executed with the updated code, without recreating the entire workflow or changing cluster configuration.
NEW QUESTION # 295
Which of the following SQL keywords can be used to convert a table from a long format to a wide format?
- A. SUM
- B. PIVOT
- C. TRANSFORM
- D. WHERE
- E. CONVERT
Answer: B
Explanation:
The SQL keyword that can be used to convert a table from a long format to a wide format is PIVOT. The PIVOT clause is used to rotate the rows of a table into columns of a new table1. The PIVOT clause can aggregate the values of a column based on the distinct values of another column, and use those values as the column names of the new table1. The PIVOT clause can be useful for transforming data from a long format, where each row represents an observation with multiple attributes, to a wide format, where each row represents an observation with a single attribute and multiple values2. For example, the PIVOT clause can be used to convert a table that contains the sales of different products by different regions into a table that contains the sales of each product by each region as separate columns1.
The other options are not suitable for converting a table from a long format to a wide format. CONVERT is a function that can be used to change the data type of an expression3. WHERE is a clause that can be used to filter the rows of a table based on a condition4. TRANSFORM is a keyword that can be used to apply a user- defined function to a group of rows in a table5. SUM is a function that can be used to calculate the total of a numeric column.
:
1: PIVOT | Databricks on AWS
2: Reshaping Data - Long vs Wide Format | Databricks on AWS
3: CONVERT | Databricks on AWS
4: WHERE | Databricks on AWS
5: TRANSFORM | Databricks on AWS
6: [SUM | Databricks on AWS]
NEW QUESTION # 296
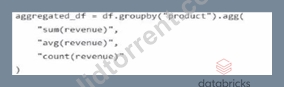
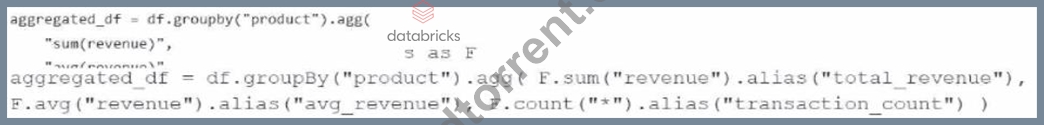
A data engineer has been provided a PySpark DataFrame named df with columns product and revenue. The data engineer needs to compute complex aggregations to determine each product's total revenue, average revenue, and transaction count.
Which code snippet should the data engineer use?
Answer: D
NEW QUESTION # 297
What are the transformations typically included in building the Bronze layer ?
- A. Include columns Load date/time, process ID
- B. Business rules and transformations
- C. Aggregate data from multiple sources
- D. Perform extensive data cleansing
Answer: A
Explanation:
In the Medallion Architecture promoted by Databricks, the Bronze layer represents the raw ingestion layer where data is stored in its original form with minimal transformation. The primary goal is to ensure data fidelity and traceability , not to apply business logic or heavy transformations. Typical operations in the Bronze layer include schema inference (or enforcement), ingestion of raw data, and the addition of metadata columns such as ingestion timestamp, load date/time, and process identifiers. These metadata fields help track lineage, enable debugging, and support incremental processing downstream. Extensive data cleansing (A), aggregations (B), and business transformations (C) are intentionally deferred to the Silver and Gold layers , where data is refined and structured for analytics. By keeping Bronze data close to the source and append-only, organizations maintain a reliable audit trail and can reprocess data if needed. Therefore, adding operational metadata like load timestamps and process IDs is the correct characteristic of Bronze layer transformations.
=========
NEW QUESTION # 298
A Delta Live Table pipeline includes two datasets defined using STREAMING LIVE TABLE.
Three datasets are defined against Delta Lake table sources using LIVE TABLE.
The table is configured to run in Development mode using the Continuous Pipeline Mode.
Assuming previously unprocessed data exists and all definitions are valid, what is the expected outcome after clicking Start to update the pipeline?
- A. All datasets will be updated once and the pipeline will shut down. The compute resources will persist to allow for additional testing.
- B. All datasets will be updated once and the pipeline will shut down. The compute resources will be terminated.
- C. All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will persist to allow for additional testing.
- D. All datasets will be updated once and the pipeline will persist without any processing. The compute resources will persist but go unused.
- E. All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will persist until the pipeline is shut down.
Answer: C
NEW QUESTION # 299
......
If you buy our Databricks-Certified-Data-Engineer-Associate preparation questions, we can promise that you can use our study materials for study in anytime and anywhere. Because our study system can support you study when you are in an offline state. In addition, Our Databricks-Certified-Data-Engineer-Associate training quiz will be very useful for you to improve your learning efficiency, because you can make full use of your all spare time to do test. It will bring a lot of benefits for you beyond your imagination if you buy our Databricks-Certified-Data-Engineer-Associate Study Materials.
Databricks-Certified-Data-Engineer-Associate Pass Guaranteed: https://www.validtorrent.com/Databricks-Certified-Data-Engineer-Associate-valid-exam-torrent.html
- Unparalleled Instant Databricks-Certified-Data-Engineer-Associate Access - Win Your Databricks Certificate with Top Score 🔀 Open ➤ www.validtorrent.com ⮘ and search for ➠ Databricks-Certified-Data-Engineer-Associate 🠰 to download exam materials for free 🐦Valid Exam Databricks-Certified-Data-Engineer-Associate Preparation
- New Databricks-Certified-Data-Engineer-Associate Test Syllabus ⛅ Valid Databricks-Certified-Data-Engineer-Associate Test Book 😽 Original Databricks-Certified-Data-Engineer-Associate Questions 🙆 Download ✔ Databricks-Certified-Data-Engineer-Associate ️✔️ for free by simply entering ▛ www.pdfvce.com ▟ website 🏬Online Databricks-Certified-Data-Engineer-Associate Tests
- Databricks-Certified-Data-Engineer-Associate exams cram PDF, Databricks Databricks-Certified-Data-Engineer-Associate dumps PDF files 👖 Search for ⏩ Databricks-Certified-Data-Engineer-Associate ⏪ and download it for free immediately on ➠ www.prepawayexam.com 🠰 🍧Pass Databricks-Certified-Data-Engineer-Associate Guarantee
- Unparalleled Instant Databricks-Certified-Data-Engineer-Associate Access - Win Your Databricks Certificate with Top Score 🚹 Easily obtain free download of ▷ Databricks-Certified-Data-Engineer-Associate ◁ by searching on ➠ www.pdfvce.com 🠰 🤠Databricks-Certified-Data-Engineer-Associate Certification Materials
- Unparalleled Instant Databricks-Certified-Data-Engineer-Associate Access - Win Your Databricks Certificate with Top Score 🌤 Search for { Databricks-Certified-Data-Engineer-Associate } and download it for free immediately on ▶ www.pass4test.com ◀ 🦃Valid Dumps Databricks-Certified-Data-Engineer-Associate Book
- Online Databricks-Certified-Data-Engineer-Associate Tests 🌷 Latest Databricks-Certified-Data-Engineer-Associate Training 🥨 Databricks-Certified-Data-Engineer-Associate Certification Materials 🌐 Copy URL ▛ www.pdfvce.com ▟ open and search for ▛ Databricks-Certified-Data-Engineer-Associate ▟ to download for free 🤥Latest Databricks-Certified-Data-Engineer-Associate Training
- Pass Your Databricks Databricks-Certified-Data-Engineer-Associate: Databricks Certified Data Engineer Associate Exam Exam with Correct Instant Databricks-Certified-Data-Engineer-Associate Access Surely 📠 Search for [ Databricks-Certified-Data-Engineer-Associate ] and download exam materials for free through { www.pdfdumps.com } 🐕Latest Databricks-Certified-Data-Engineer-Associate Training
- Unparalleled Instant Databricks-Certified-Data-Engineer-Associate Access - Win Your Databricks Certificate with Top Score 🚄 Simply search for ➽ Databricks-Certified-Data-Engineer-Associate 🢪 for free download on ▶ www.pdfvce.com ◀ ⭐Databricks-Certified-Data-Engineer-Associate Latest Braindumps Pdf
- Online Databricks-Certified-Data-Engineer-Associate Tests 🍸 Latest Databricks-Certified-Data-Engineer-Associate Training 😀 New Databricks-Certified-Data-Engineer-Associate Test Syllabus 🕋 Search for 【 Databricks-Certified-Data-Engineer-Associate 】 and download it for free on ( www.dumpsquestion.com ) website 🙇Databricks-Certified-Data-Engineer-Associate Valid Exam Book
- Quiz Trustable Databricks - Instant Databricks-Certified-Data-Engineer-Associate Access 📳 Copy URL ▶ www.pdfvce.com ◀ open and search for { Databricks-Certified-Data-Engineer-Associate } to download for free 🥼New Databricks-Certified-Data-Engineer-Associate Test Syllabus
- Valid Dumps Databricks-Certified-Data-Engineer-Associate Book 🔉 Valid Databricks-Certified-Data-Engineer-Associate Test Book 🧓 Latest Databricks-Certified-Data-Engineer-Associate Training 💓 The page for free download of ▶ Databricks-Certified-Data-Engineer-Associate ◀ on ⮆ www.easy4engine.com ⮄ will open immediately 🔘Latest Databricks-Certified-Data-Engineer-Associate Training
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, telegra.ph, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Download part of ValidTorrent Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=13PhLHv9PrKvaa6tzL9WM-eJEc3iSU4Sf