If you are not certain whether the DP-750 prep guide from our company is suitable for you or not, so you are hesitate to buy and use our study materials. Do not worry, in order to help you solve your problem and let you have a good understanding of our DP-750 study practice dump, the experts and professors from our company have designed the trial version for all people. You can have a try of using the DP-750 Prep Guide from our company before you purchase it. We believe that the trial version provided by our company will help you know about our study materials well and make the good choice for yourself. More importantly, the trial version of the DP-750 exam questions from our company is free for all people. We believe that the trial version will help you a lot.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 4: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
In the era of informational globalization, the world has witnessed climax of science and technology development, and has enjoyed the prosperity of various scientific blooms. In 21st century, every country had entered the period of talent competition, therefore, we must begin to extend our DP-750 personal skills, only by this can we become the pioneer among our competitors. At the same time, our competitors are trying to capture every opportunity and get a satisfying job. In this case, we need a professional DP-750 Certification, which will help us stand out of the crowd and knock out the door of great company.
NEW QUESTION # 77
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group1.
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
- Can create tables in schema1
- Can modify and query tables
- Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.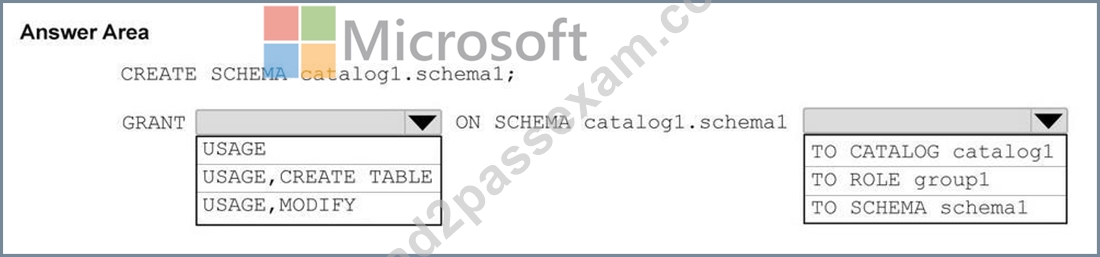
Answer:
Explanation: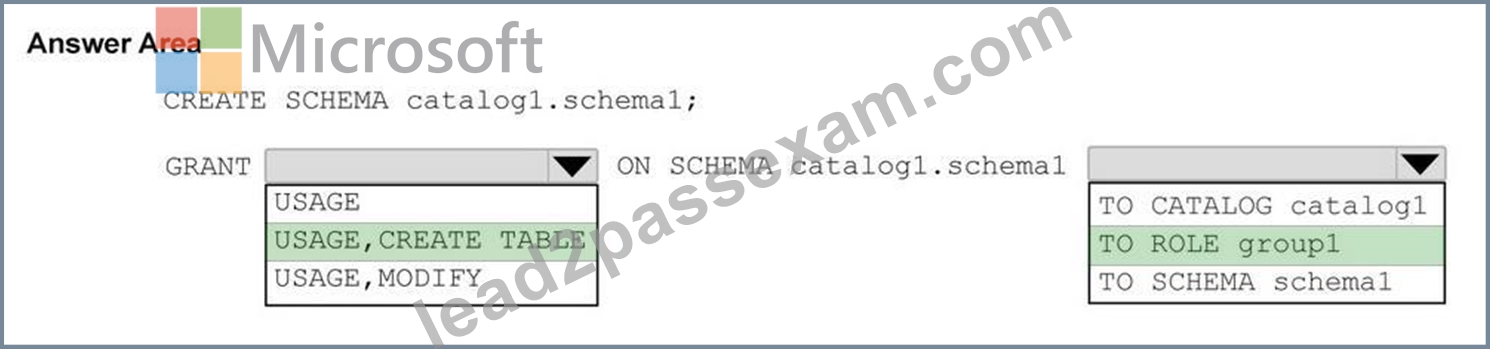
NEW QUESTION # 78
What improves join performance for small lookup tables?
Answer: A
Explanation:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
NEW QUESTION # 79
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
- Ensure that authentication does NOT require storing credentials in
Databricks.
- Ensure that users can access the files, but NOT modify the files.
- Follow the principle of least privilege.
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.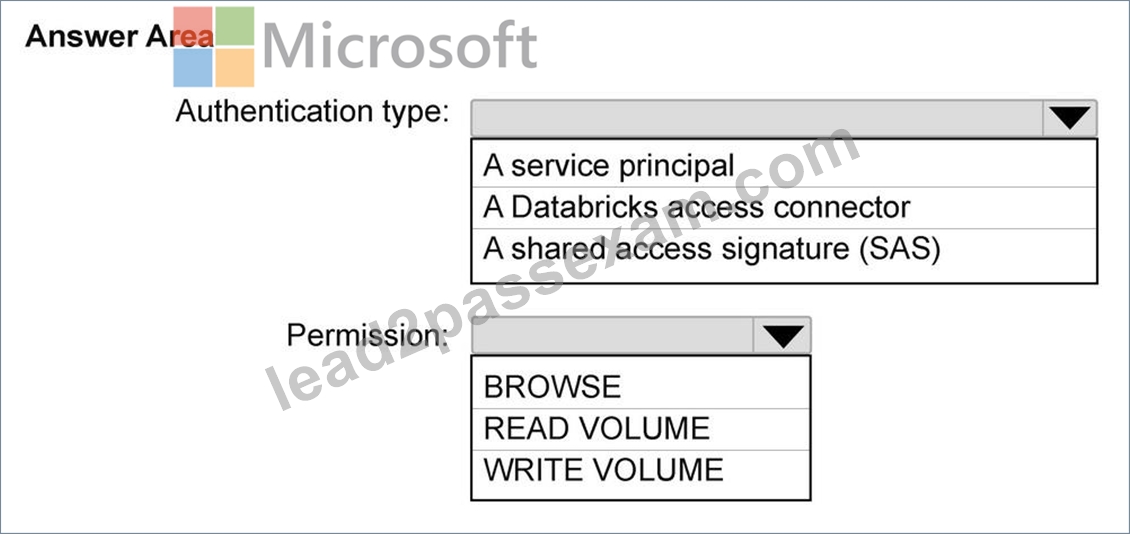
Answer:
Explanation: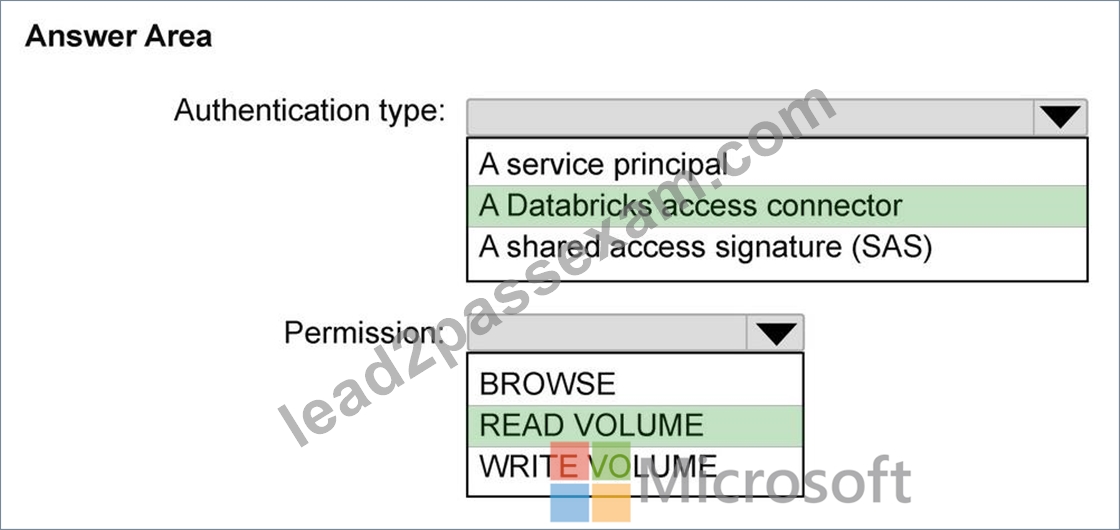
NEW QUESTION # 80
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have an Apache Spark Structured Streaming job that writes data to a Delta table.
After the cluster restarts, the streaming job reprocesses previously ingested data.
You need to prevent the streaming job from reprocessing the data after the cluster restarts.
What should you do?
Answer: A
Explanation:
To prevent your Apache Spark Structured Streaming job from reprocessing previously ingested data after a cluster restart, you must configure a streaming checkpoint directory.
Core Solution
Enable Checkpointing: Define the checkpointLocation option in your streaming write configuration.
Track Progress: Spark uses this directory to save the exact offset ranges of processed data.
Automatic Recovery: Upon restart, the engine reads the checkpoint and resumes precisely where it left off.
Implementation Example in python
# Configure the streaming write with a checkpoint path
(df.writeStream
.format("delta")
.outputMode("append")
.option("checkpointLocation",
"/Volumes/catalog/schema/volume_name/checkpoints/job_name")
.toTable("catalog.schema.target_table"))
Reference:
https://medium.com/@salah.uddin_75300/architecture-of-a-streaming-machine-learning-data- pipeline-042200c8e7ff
NEW QUESTION # 81
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
A foreign catalog created through Lakehouse Federation in Catalog Explorer is the correct solution for all three requirements. Here's why it works:
The schemas and tables of DB1 can be queried in Databricks - Lakehouse Federation pushes the query down to the external SQL Server and returns results, so analysts write normal SQL in Databricks.
They appear alongside other Unity Catalog objects - the foreign catalog sits in the same three-tier hierarchy as native catalogs, schemas, and tables, visible in Catalog Explorer alongside all other Unity Catalog assets.
The data is NOT copied into Databricks-managed storage - foreign catalogs query data in place at the source; nothing is replicated or materialised in Databricks storage.
This is exactly the scenario Lakehouse Federation was built for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 82
......
Many IT certification exam dumps providers spend a lot of money and spirit on advertising and promotion about Microsoft DP-750 exam lab questions but pay little attention on improving products' quality and valid information resource. They prefer low price strategy with low price rather than excellent valid and high-quality DP-750 Exam Lab Questions with a little more cost. I think high passing rate products is what you need in fact.
DP-750 Study Guide Pdf: https://www.lead2passexam.com/Microsoft/valid-DP-750-exam-dumps.html