What's more, part of that Real4Prep MLA-C01 dumps now are free: https://drive.google.com/open?id=1KMAcSKQLmQv9gfNBu4pIB0sSb-DQVeke
Without no doubt that accuracy of information is of important for a MLA-C01 study material. It can be said exactly that the precision and accuracy of our Real4Prep’s MLA-C01 study materials are beyond question. All questions and answers have passed the test of time and are approved by experienced professionals who recommend them as the easiest route to certification testing. Every customer who has used our MLA-C01 Study Materials consider this to be a material that changes their life a lot, so they recommend it as the easiest way to pass the certification test. Our MLA-C01 study materials are constantly updated by our experts and improved according to the changing standards of the actual examination standards. We can guarantee that the information on our questions is absolutely true and valid.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
Looking for top-notch Implementing and Operating AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam questions? You've come to the right place! Real4Prep offers a comprehensive and affordable solution for all your MLA-C01 exam needs. Our MLA-C01 Exam Questions are regularly updated, and we provide a range of attractive features to enhance your preparation, including PDF format, an online practice test engine.
NEW QUESTION # 53
A company has developed a new ML model. The company requires online model validation on 10% of the traffic before the company fully releases the model in production. The company uses an Amazon SageMaker endpoint behind an Application Load Balancer (ALB) to serve the model.
Which solution will set up the required online validation with the LEAST operational overhead?
Answer: C
Explanation:
Scenario:The company wants to perform online validation of a new ML model on 10% of the traffic before fully deploying the model in production. The setup must have minimal operational overhead.
Why Use SageMaker Production Variants?
* Built-In Traffic Splitting:Amazon SageMaker endpoints support production variants, allowing multiple models to run on a single endpoint. You can direct a percentage of incoming traffic to each variant by adjusting the variant weights.
* Ease of Management:Using production variants eliminates the need for additional infrastructure like separate endpoints or custom ALB configurations.
* Monitoring with CloudWatch:SageMaker automatically integrates with CloudWatch, enabling real- time monitoring of model performance and invocation metrics.
Steps to Implement:
* Deploy the New Model as a Production Variant:
* Update the existing SageMaker endpoint to include the new model as a production variant. This can be done via the SageMaker console, CLI, or SDK.
Example SDK Code:
import boto3
sm_client = boto3.client('sagemaker')
response = sm_client.update_endpoint_weights_and_capacities(
EndpointName='existing-endpoint-name',
DesiredWeightsAndCapacities=[
{'VariantName': 'current-model', 'DesiredWeight': 0.9},
{'VariantName': 'new-model', 'DesiredWeight': 0.1}
]
)
* Set the Variant Weight:
* Assign a weight of 0.1 to the new model and 0.9 to the existing model. This ensures 10% of traffic goes to the new model while the remaining 90% continues to use the current model.
* Monitor the Performance:
* Use Amazon CloudWatch metrics, such as InvocationCount and ModelLatency, to monitor the traffic and performance of each variant.
* Validate the Results:
* Analyze the performance of the new model based on metrics like accuracy, latency, and failure rates.
Why Not the Other Options?
* Option B:Setting the weight to 1 directs all traffic to the new model, which does not meet the requirement of splitting traffic for validation.
* Option C:Creating a new endpoint introduces additional operational overhead for traffic routing and monitoring, which is unnecessary given SageMaker's built-in production variant capability.
* Option D:Configuring the ALB to route traffic requires manual setup and lacks SageMaker's seamless variant monitoring and traffic splitting features.
Conclusion:Using production variants with a weight of 0.1 for the new model on the existing SageMaker endpoint provides the required traffic split for online validation with minimal operational overhead.
References:
* Amazon SageMaker Endpoints
* SageMaker Production Variants
* Monitoring SageMaker Endpoints with CloudWatch
NEW QUESTION # 54
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
After the data is aggregated, the ML engineer must implement a solution to automatically detect anomalies in the data and to visualize the result.
Which solution will meet these requirements?
Answer: A
Explanation:
Amazon SageMaker Data Wrangler is a comprehensive tool that streamlines the process of data preparation and offers built-in capabilities for anomaly detection and visualization.
Key Features of SageMaker Data Wrangler:
* Data Importation: Connects seamlessly to various data sources, including Amazon S3 and on- premises databases, facilitating the aggregation of transaction logs, customer profiles, and MySQL tables.
* Anomaly Detection: Provides built-in analyses to detect anomalies in time series data, enabling the identification of outliers that may indicate fraudulent activities.
* Visualization: Offers a suite of visualization tools, such as histograms and scatter plots, to help understand data distributions and relationships, which are crucial for feature engineering and model development.
Implementation Steps:
* Data Aggregation:
* Import data from Amazon S3 and on-premises MySQL databases into SageMaker Data Wrangler.
* Utilize Data Wrangler's data flow interface to combine and preprocess datasets, ensuring a unified dataset for analysis.
* Anomaly Detection:
* Apply the anomaly detection analysis feature to identify outliers in the dataset.
* Configure parameters such as the anomaly threshold to fine-tune the detection sensitivity.
* Visualization:
* Use built-in visualization tools to create charts and graphs that depict data distributions and highlight anomalies.
* Interpret these visualizations to gain insights into potential fraud patterns and feature interdependencies.
Advantages of Using SageMaker Data Wrangler:
* Integrated Workflow: Combines data preparation, anomaly detection, and visualization within a single interface, streamlining the ML development process.
* Operational Efficiency: Reduces the need for multiple tools and complex integrations, thereby minimizing operational overhead.
* Scalability: Handles large datasets efficiently, making it suitable for extensive transaction logs and customer profiles.
By leveraging SageMaker Data Wrangler, the ML engineer can effectively detect anomalies and visualize results, facilitating the development of a robust fraud detection model.
References:
* Analyze and Visualize - Amazon SageMaker
* Transform Data - Amazon SageMaker
NEW QUESTION # 55
A company uses Amazon SageMakerAI to support ML workflows such as model training and deployment.
Select the correct registry from the following list to meet the requirements for each use case with the LEAST operational overhead. Each registry should be selected one or more times. (Select FOUR.)
* Amazon Elastic Container Registry (Amazon ECR)
* SageMaker Model Registry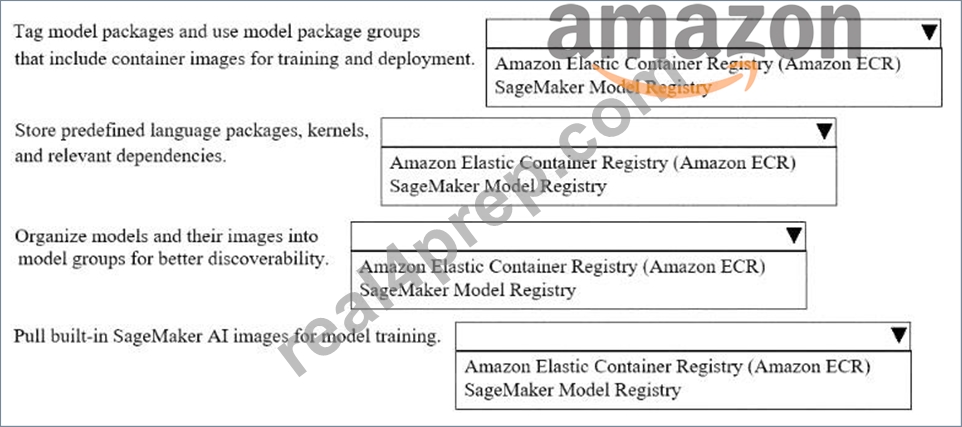
Answer:
Explanation: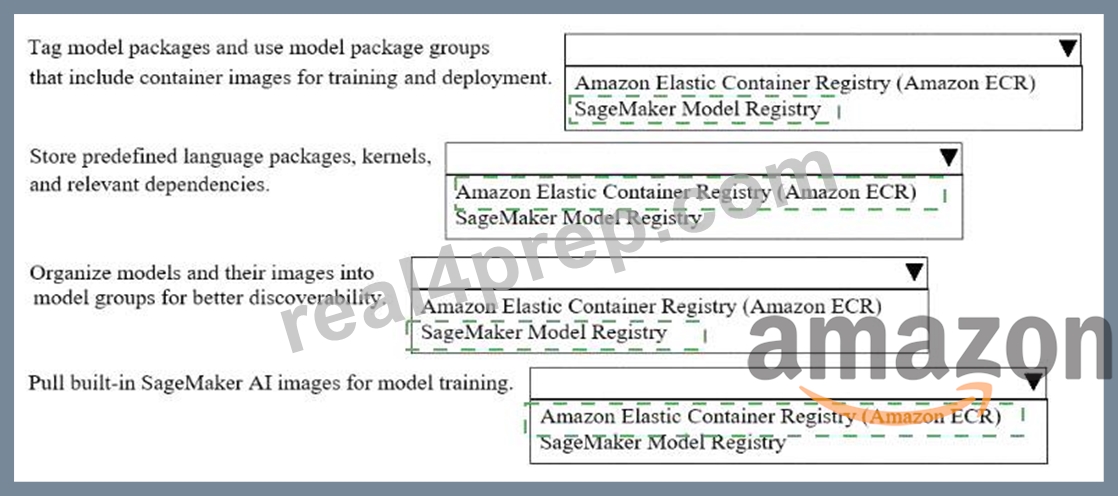
Explanation:
* Tag model packages and use model package groups that include container images for training and deployment # SageMaker Model Registry
* Store predefined language packages, kernels, and relevant dependencies # Amazon Elastic Container Registry (Amazon ECR)
* Organize models and their images into model groups for better discoverability # SageMaker Model Registry
* Pull built-in SageMaker AI images for model training # Amazon Elastic Container Registry (Amazon ECR) The correct hotspot mapping is based on the different purposes of SageMaker Model Registry and Amazon ECR.
For model packages, model package groups, and model discoverability, the correct choice is SageMaker Model Registry. AWS documentation states that a model package group is a collection of versioned model packages, and each version can contain the model artifacts, metadata, and container information used for deployment. AWS also documents that registered models can be organized into groups to support governance, discoverability, and lifecycle management. That is why both "tag model packages and use model package groups" and "organize models and their images into model groups" map to SageMaker Model Registry.
For storing software environments and pulling training images, the correct choice is Amazon ECR. AWS documentation says SageMaker uses Docker container images, and these images contain the software stack such as frameworks, language packages, kernels, and dependencies. AWS also states that SageMaker provides prebuilt Docker images for training and inference, and these are referenced through Amazon ECR image URIs. Therefore, both "store predefined language packages, kernels, and relevant dependencies" and
"pull built-in SageMaker AI images for model training" map to Amazon ECR.
NEW QUESTION # 56
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company must implement a manual approval-based workflow to ensure that only approved models can be deployed to production endpoints.
Which solution will meet this requirement?
Answer: D
Explanation:
To implement a manual approval-based workflow ensuring that only approved models are deployed to production endpoints, Amazon SageMaker provides integrated tools such asSageMaker Pipelinesand the SageMaker Model Registry.
SageMaker Pipelinesis a robust service for building, automating, and managing end-to-end machine learning workflows. It facilitates the orchestration of various steps in the ML lifecycle, including data preprocessing, model training, evaluation, and deployment. By integrating with theSageMaker Model Registry, it enables seamless tracking and management of model versions and their approval statuses.
Implementation Steps:
* Define the Pipeline:
* Create a SageMaker Pipeline encompassing steps for data preprocessing, model training, evaluation, and registration of the model in the Model Registry.
* Incorporate aCondition Stepto assess model performance metrics. If the model meets predefined criteria, proceed to the next step; otherwise, halt the process.
* Register the Model:
* Utilize theRegisterModelstep to add the trained model to the Model Registry.
* Set the ModelApprovalStatus parameter to PendingManualApproval during registration. This status indicates that the model awaits manual review before deployment.
* Manual Approval Process:
* Notify the designated approver upon model registration. This can be achieved by integrating Amazon EventBridge to monitor registration events and trigger notifications via AWS Lambda functions.
* The approver reviews the model's performance and, if satisfactory, updates the model's status to Approved using the AWS SDK or through the SageMaker Studio interface.
* Deploy the Approved Model:
* Configure the pipeline to automatically deploy models with an Approved status to the production endpoint. This can be managed by adding deployment steps conditioned on the model's approval status.
Advantages of This Approach:
* Automated Workflow:SageMaker Pipelines streamline the ML workflow, reducing manual interventions and potential errors.
* Governance and Compliance:The manual approval step ensures that only thoroughly evaluated models are deployed, aligning with organizational standards.
* Scalability:The solution supports complex ML workflows, making it adaptable to various project requirements.
By implementing this solution, the company can establish a controlled and efficient process for deploying models, ensuring that only approved versions reach production environments.
References:
* Automate the machine learning model approval process with Amazon SageMaker Model Registry and Amazon SageMaker Pipelines
* Update the Approval Status of a Model - Amazon SageMaker
NEW QUESTION # 57
An ML engineer is analyzing potential biases in a customer dataset before training an ML model. The dataset contains customer age (numeric), product reviews (text), and purchase outcomes (categorical).
Which statistical metrics should the ML engineer use to identify potential biases in the dataset before model training?
Answer: D
Explanation:
Bias detection is a critical step in responsible machine learning and is emphasized in AWS documentation, particularly in Amazon SageMaker Clarify. When analyzing structured datasets that include sensitive or influential attributes such as age, AWS recommends evaluating label distribution fairness and group-based outcome differences before training a model.
The class imbalance metric helps identify whether certain outcomes (for example, purchase vs. no purchase) are overrepresented or underrepresented. Severe imbalance can cause models to favor majority classes, leading to biased predictions. AWS explicitly highlights class imbalance as a key issue to assess during data exploration.
The Difference in Proportions of Labels (DPL) is a fairness metric supported by SageMaker Clarify that measures whether outcome labels are disproportionately distributed across different groups, such as age ranges. DPL compares the proportion of favorable outcomes between groups, making it especially effective for identifying demographic bias in categorical labels.
Options A and D focus on descriptive statistics or correlations, which are useful for data understanding but do not directly measure bias or fairness. Option B partially addresses imbalance and sentiment but sentiment analysis of reviews alone does not quantify demographic bias tied to outcomes.
AWS documentation strongly recommends using group fairness metrics, including DPL, alongside class imbalance checks to identify bias before training. These metrics provide actionable insights into whether a dataset may lead to unfair or skewed model behavior.
Therefore, Option C is the most appropriate and AWS-aligned choice.
NEW QUESTION # 58
......
With the development of society and the perfection of relative laws and regulations, the MLA-C01 certificate in our career field becomes a necessity for our countryPassing the MLA-C01 and obtaining the certificate may be the fastest and most direct way to change your position and achieve your goal. And we are just right here to give you help. Being considered the most authentic brand in this career, our professional experts are making unremitting efforts to provide our customers the latest and valid MLA-C01 Exam simulation.
MLA-C01 Instant Discount: https://www.real4prep.com/MLA-C01-exam.html
BTW, DOWNLOAD part of Real4Prep MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1KMAcSKQLmQv9gfNBu4pIB0sSb-DQVeke