2026 Latest TorrentExam Workday-Pro-Integrations PDF Dumps and Workday-Pro-Integrations Exam Engine Free Share: https://drive.google.com/open?id=1zCQ5vGmzxWloQS1ouS12ypZiimP02doJ
TorrentExam offers affordable Workday Pro Integrations Certification Exam exam preparation material. You don't have to go beyond your budget to buy Updated Workday-Pro-Integrations Dumps. To make your Workday-Pro-Integrations exam preparation material smooth, a bundle pack is also available that includes all the 3 formats of dumps questions. TorrentExam offers 365 days updates.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> New Workday-Pro-Integrations Test Materials <<
We offer you free update for one year for Workday-Pro-Integrations study guide, namely, in the following year, you can obtain the latest version for free. And the latest version for Workday-Pro-Integrations exam dumps will be sent to your email automatically. In addition, Workday-Pro-Integrations exam materials are high quality, since we have experienced experts to compile and verify them, therefore the quality and accuracy can be guaranteed, so you can use them at ease. We have online and offline chat service, and if you have any questions about Workday-Pro-Integrations Exam Dumps, you can consult us, and we will give you reply as quickly as possible.
NEW QUESTION # 72
The following XML code was generated through a RaaS that will be used in an EIB.
You want to use predicated templates that will process USA workers one way, GBR workers another way, and all other countries a standard way.
What XML code will create these templates?
Answer: C
Explanation:
Predicated templates use XPath predicates inside square brackets to match only specific source nodes. The template must match the wd:Report_Entry node and then apply a predicate against the child value wd:
Country_Code. Option A correctly creates three separate template matches: one for USA records, one for GBR records, and one fallback template for records where the country code is neither USA nor GBR. This is the cleanest XSLT pattern because each template processes a specific population of report entries. Options B and D incorrectly place the predicate or comparison after navigating directly to wd:Country_Code, which does not properly match the full report entry node. Option C combines USA and GBR in the first template and would not separate processing correctly.
NEW QUESTION # 73
Refer to the following XML and example transformed output to answer the question below.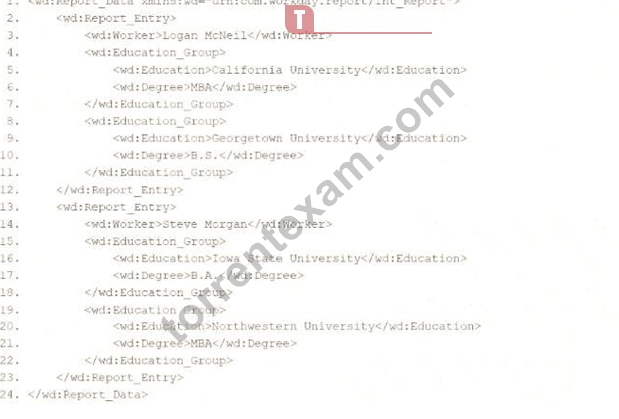
Example transformed wd:Report_Entry output;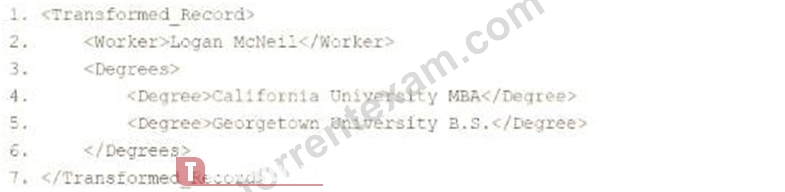
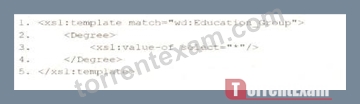
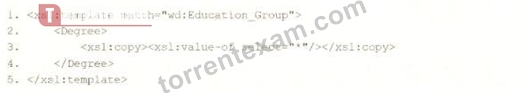
What is the XSLT syntax tor a template that matches on wd: Educationj3roup to produce the degree data in the above Transformed_Record example?
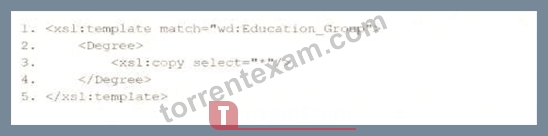
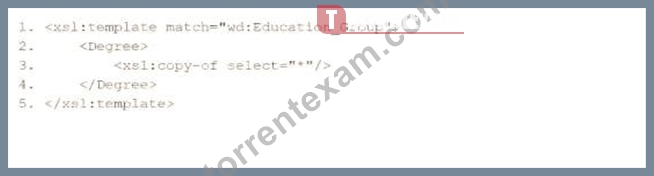
Answer: B
Explanation:
In Workday integrations, XSLT is used to transform XML data, such as the output from a web service- enabled report or EIB, into a desired format for third-party systems. In this scenario, you need to create an XSLT template that matches the wd:Education_Group element in the provided XML and transforms it to produce the degree data in the format shown in the Transformed_Record example. The goal is to output each degree (e.g., " California University MBA " and " Georgetown University B.S. " ) as a < Degree > element within a < Degrees > parent element.
Here's why option A is correct:
* Template Matching: The < xsl:template match= " wd:Education_Group " > correctly targets the wd:
Education_Group element in the XML, which contains multiple wd:Education elements, each with a wd:Degree child, as shown in the XML snippet (e.g., < wd:Education > California University < /wd:
Education > < wd:Degree > MBA < /wd:Degree > ).
* Transformation Logic:
* < Degree > creates the outer < Degree > element for each education group, matching the structure in the Transformed_Record example (e.g., < Degree > California University MBA < /Degree > ).
* < xsl:copy > < xsl:value-of select= " * " / > < /xsl:copy > copies the content of the child elements (wd:Education and wd:Degree) and concatenates their values into a single string. The select= " *
" targets all child elements of wd:Education_Group, and xsl:value-of outputs their text content (e.
g., " California University " and " MBA " become " California University MBA " ).
* This approach ensures that each wd:Education_Group is transformed into a single < Degree > element with the combined text of the wd:Education and wd:Degree values, matching the example output.
* Context and Output: The template operates on each wd:Education_Group, producing the nested structure shown in the Transformed_Record (e.g., < Degrees > < Degree > California University MBA
< /Degree > < Degree > Georgetown University B.S. < /Degree > < /Degrees > ), assuming a parent template or additional logic wraps the < Degree > elements in < Degrees > .
Why not the other options?
* B.
xml
WrapCopy
< xsl:template match= " wd:Education_Group " >
< Degree >
< xsl:value-of select= " * " / >
< /Degree >
< /xsl:template >
This uses < xsl:value-of select= " * " / > without < xsl:copy > , which outputs the concatenated text of all child elements but does not preserve any XML structure or formatting. It would produce plain text (e.g., " California UniversityMBACalifornia UniversityB.S. " ) without the proper < Degree > tags, failing to match the structured output in the example.
* C.
xml
WrapCopy
< xsl:template match= " wd:Education_Group " >
< Degree >
< xsl:copy select= " * " / >
< /Degree >
< /xsl:template >
This uses < xsl:copy select= " * " / > , but < xsl:copy > does not take a select attribute-it simply copies the current node. This would result in an invalid XSLT syntax and fail to produce the desired output, making it incorrect.
* D.
xml
WrapCopy
< xsl:template match= " wd:Education_Group " >
< Degree >
< xsl:copy-of select= " * " / >
< /Degree >
< /xsl:template >
This uses < xsl:copy-of select= " * " / > , which copies all child nodes (e.g., wd:Education and wd:Degree) as- is, including their element structure, resulting in output like < Degree > < wd:Education > California University < /wd:Education > < wd:Degree > MBA < /wd:Degree > < /Degree > . This does not match the flattened, concatenated text format in the Transformed_Record example (e.g., < Degree > California University MBA < /Degree > ), making it incorrect.
To implement this in XSLT for a Workday integration:
* Use the template from option A to match wd:Education_Group, apply < xsl:copy > < xsl:value-of select= " * " / > < /xsl:copy > to concatenate and output the wd:Education and wd:Degree values as a single < Degree > element. This ensures the transformation aligns with the Transformed_Record example, producing the required format for the integration output.
Workday Pro Integrations Study Guide: Section on " XSLT Transformations for Workday Integrations " - Details the use of < xsl:template > , < xsl:copy > , and < xsl:value-of > for transforming XML data, including handling grouped elements like wd:Education_Group.
Workday EIB and Web Services Guide: Chapter on " XML and XSLT for Report Data " - Explains the structure of Workday XML (e.g., wd:Education_Group, wd:Education, wd:Degree) and how to use XSLT to transform education data into a flattened format.
Workday Reporting and Analytics Guide: Section on " Web Service-Enabled Reports " - Covers integrating report outputs with XSLT for transformations, including examples of concatenating and restructuring data for third-party systems.
NEW QUESTION # 74
Which features must all XSLT files contain to be considered valid?
Answer: C
Explanation:
A valid XSLT file must include the following key components:
Root Element: <xsl:stylesheet> or <xsl:transform>
Namespace Declaration: Usually xmlns:xsl="http://www.w3.org/1999/XSL/Transform" At Least One <xsl:template> to define transformation behavior From W3C and Workday documentation:
"A valid XSLT file must contain a stylesheet root element, a namespace, and at least one template to be considered executable." Why others are incorrect:
A . Prefix and header are not structural requirements.
B . "Transformation" is vague; it's the template that implements it.
C . Headers and footers are not required or defined elements in XSLT.
NEW QUESTION # 75
A vendor needs an EIB that uses a custom report to output a list of new hires and their child dependent(s). You have been asked to create a calculated field that will be used to add only child dependent(s).
Which calculated field functions do you need to accomplish this?
Answer: A
Explanation:
In this case, you're asked to create a calculated field that:
Filters dependent records
Includes only child relationships
This means:
The worker has multiple dependents (a multi-instance field).
You need to extract only those dependent(s) where the relationship is "Child".
To achieve this in Workday, use:
True/False Condition → check if the relationship descriptor = "Child"
Extract Multi-Instance → filters the multi-instance field (Dependents) using the above condition to return only matching records This two-step logic filters multi-instance relationships correctly.
Why the other options are incorrect:
A and B are missing Extract Multi-Instance, which is required to filter multi-values.
C includes Text Constant unnecessarily - only True/False Condition and Extract Multi-Instance are required.
NEW QUESTION # 76
Refer to the following scenario to answer the question below.
You need to configure a Core Connector: Candidate Outbound integration for your vendor. The connector requires the data initialization service (DIS).
The vendor needs a value on the output file which contains the average number of jobs a candidate applied to.
This value is not delivered by Workday so you have identified that you will need to build a calculated field to generate this value.
What steps do you follow to output the calculated field?
Answer: C
Explanation:
The scenario involves a Core Connector: Candidate Outbound integration requiring a calculated field for the average number of jobs a candidate applied to, which isn't a delivered Workday field. The task is to output this calculated field in the integration file. Core Connectors in Workday use predefined templates but allow customization through various configuration options. Let's evaluate the steps:
* Context:
* Core Connector: Candidate Outbound uses the Data Initialization Service (DIS) to extract candidate data.
* A calculated field must be created (e.g., averaging the " Number of Job Applications " field across a candidate's records).
* This value needs to be included in the output file sent to the vendor.
* Integration Field Overrides:In Core Connectors, calculated fields are typically incorporated into the output by defining integration field overrides. This feature allows you to map a calculated field to a specific field in the connector's output structure, overriding the default delivered value (or adding a new field). The calculated field is built separately (e.g., in Report Writer or Calculated Fields) and then referenced in the integration configuration.
* Option Analysis:
* A. Configure a custom field override service to output the calculation: Incorrect. There's no " custom field override service " in Workday Core Connectors. This might confuse with integration field overrides, but it's not a distinct service.
* B. Configure integration attributes to output the calculation: Incorrect. Integration attributes define metadata or settings for the integration (e.g., file name, delivery method), not specific field mappings for output data.
* C. Configure integration field attributes to output the calculation: Incorrect. " Integration field attributes " isn't a precise Workday term for this purpose; it may confuse with field-level settings, but field overrides are the correct mechanism.
* D. Configure integration field overrides to output the calculation: Correct. This is the standard method in Core Connectors to include calculated fields in the output file by overriding or adding to the delivered field structure.
* Implementation:
* Create a calculated field (e.g., " Average Job Applications " ) using functions like Arithmetic Calculation to average job application counts.
* In the Core Connector configuration, navigate to the Integration Field Overrides section.
* Define a new field or override an existing one, mapping it to the calculated field.
* Test the integration to ensure the calculated value appears in the output file.
References from Workday Pro Integrations Study Guide:
* Core Connectors & Document Transformation: Section on " Configuring Integration Field Overrides " explains mapping calculated fields to output files.
* Integration System Fundamentals: Details how Core Connectors extend delivered functionality with custom calculations.
NEW QUESTION # 77
......
Only if you pass the exam can you get a better promotion. And if you want to pass it more efficiently, we must be the best partner for you. Because we are professional Workday-Pro-Integrations questions torrent provider, we are worth trusting; because we make great efforts, we do better. Here are some reasons to choose us. The Workday-Pro-Integrations Exam Torrent can prove your ability to let more big company to attention you. Then you have more choice to get a better job and going to suitable workplace.
Best Workday-Pro-Integrations Practice: https://www.torrentexam.com/Workday-Pro-Integrations-exam-latest-torrent.html
2026 Latest TorrentExam Workday-Pro-Integrations PDF Dumps and Workday-Pro-Integrations Exam Engine Free Share: https://drive.google.com/open?id=1zCQ5vGmzxWloQS1ouS12ypZiimP02doJ