Our AI-103 study materials can come today. With so many loyal users, our good reputation is not for nothing. To buy our AI-103 exam braindumps, you don't have to worry about information leakage. Selecting a brand like AI-103 learning guide is really the most secure. And we are responsible and professional to protact your message as well. At the same time, if you have any problem when you buy or download our AI-103 Practice Engine, just contact us and we will help you in a minute.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement generative AI and agentic solutions | 30–35% | - Build generative AI applications
|
| Topic 2: Implement text and speech analysis solutions | 10–15% | - Implement speech capabilities
|
| Topic 3: Plan and manage Azure AI solutions | 25–30% | - Design Azure AI infrastructure
|
| Topic 4: Implement information extraction and knowledge mining | 10–15% | - Build knowledge bases and search solutions
|
| Topic 5: Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
>> Valid AI-103 Practice Questions <<
Candidates all around the globe use their full potential only to get Microsoft AI-103 certification. Once the candidate is a Microsoft certified, he gets multiple good career opportunities in the Microsoft sector. To pass the AI-103 Certification Exam a candidate needs to be updated and reliable Developing AI Apps and Agents on Azure (AI-103) prep material. There is a ton of AI-103 prep material available on the internet.
NEW QUESTION # 35
You are building a customer support web app named App1 in Microsoft Foundry that uses a GPT realtime model.
App1 must support:
- Live, low-latency voice conversations that use Azure OpenAI
- Streaming audio input from users and playback audio responses
You need to configure a connection method that supports real-time audio streaming in client application and targets approximately 100 ms latency.
Which connection method should you use?
Answer: D
Explanation:
WebSockets is the best connection method for this application because it enables full-duplex, bi- directional streaming over a single TCP connection, meeting the strict ~100 ms latency requirement for real-time audio.
Reference:
https://www.chat-data.com/blog/implement-openai-realtime-api-for-chatgpt-voice
NEW QUESTION # 36
Hotspot Question
You have a Microsoft Foundry project that contains an agent.
The agent uses tools to retrieve internal content and call external APIs. The agent is configured to let the model decide when to call the tools.
You need to publish the agent for a compliance workflow. The solution must meet the following requirements:
- Each workflow run must include a retrieval step before generating a
response.
- Tool calls must authenticate by using the published agent's own
identity.
- Tool access must use an identity isolated from other project
resources.
- Tool access must use support audit tracing.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.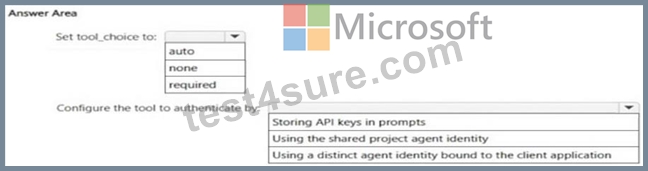
Answer:
Explanation: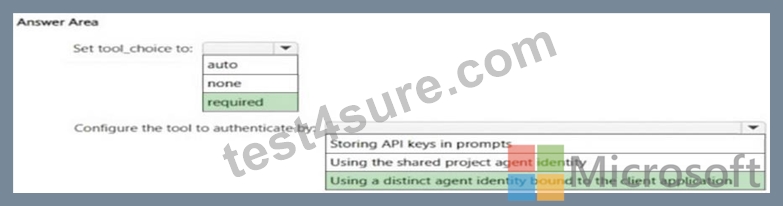
NEW QUESTION # 37
You have a Microsoft Foundry project that contains a customer support agent built on a deployed chat model.
The agent responses are validated by using an automated testing system that compares generated answers to stored expected outputs. Identical prompts must return consistent response to prevent automated test failures.
You need to reduce response variability, without modifying the prompt or reducing factual accuracy.
What should you do for the model?
Answer: C
Explanation:
To reduce response variability and ensure identical prompts return consistent answers, you should decrease the temperature parameter.
Temperature controls the randomness of the model's output. Setting the temperature closer to 0 makes the model deterministic. It forces the model to choose the highest-probability words every time, ensuring that identical prompts consistently yield identical or near-identical responses to pass your automated testing.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/agents/concepts/runtime-components
NEW QUESTION # 38
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have a Microsoft Foundry project that contains an agent. The agent generates summaries from retrieved policy documents.
Users report that some responses omit required regulatory clauses, even when the clauses are present in the retrieved content.
You need to improve response completeness.
Solution: You increase the value of the max_tokens parameter.
Does this meet the goal?
Answer: B
Explanation:
The solution does not meet the goal. Increasing max_tokens only raises the maximum number of tokens the model is allowed to generate. Microsoft's Azure OpenAI reference defines max_tokens as the maximum number of tokens allowed for the generated answer, and the quota guidance notes that increasing it can help when responses are being truncated.
In this scenario, the problem is not described as output truncation. The required regulatory clauses are already present in the retrieved policy documents, but the agent omits them during summarization. That is a response completeness issue: Microsoft Foundry RAG evaluator guidance defines response completeness as the recall aspect of the response, meaning the response should not miss critical information compared with expected content or ground truth.
A larger token budget might permit a longer answer, but it does not force the model to identify, verify, or include each mandatory clause. It can also increase cost and latency. The appropriate control is a reflection or completeness verification pass that checks the draft against the retrieved policy clauses and regenerates or revises the response when required content is missing. Reference topics: RAG response completeness, model output limits, max_tokens, reflection, and response validation.
NEW QUESTION # 39
You have a Microsoft Foundry project that contains an agent.
The agent uses a knowledge source built from documents stored in Azure Blob Storage. The documents include digitally scanned PDFs that contain multipage tables.
You have an ingestion job that extracts only plain text, causing loss of table structure, headings, and page-number metadata.
Users frequently ask questions that require the retrieval of specific table rows across the pages.
You need to configure an ingestion job for a Retrieval Augmented Generation (RAG) pipeline that performs optical character recognition (OCR) on scanned PDFs, preserves tables and headings as structure-aware chunks, and stores page-number metadata with each chunk.
How should you configure the ingestion job?
Answer: B
Explanation:
Use OCR and page-level chunking.
Structure Preservation: OCR combined with document layout analysis (such as layout-aware or page-level chunking) detects visual structures like tables, headers, and reading order.
Row-Level Granularity: Page-level chunking retains the boundaries and context of multipage tables, enabling the RAG system to isolate and retrieve specific rows effectively.
Metadata Enrichment: Processing documents page-by-page allows the ingestion pipeline to automatically tag each extracted text chunk with its source page-number metadata.
Incorrect:
[not C]
Use page-level OCR extraction and store each page as a single chunk:
While this captures page numbers, storing an entire page as a single chunk introduces too much noise. It prevents the model from pinpointing specific table rows and often exceeds the optimal context window size for precise RAG retrieval.
[Not D]
Use basic parsing and fixed-size chunking:
Basic parsing cannot read digitally scanned PDFs, resulting in empty or completely garbled text.
Furthermore, fixed-size chunking splits text at arbitrary character limits, which destroys table structures and splits individual rows across different chunks.
Reference:
https://pub.towardsai.net/unlocking-key-technologies-in-document-parsing-81bfe20d741b
NEW QUESTION # 40
......
There are a lot of advantages of our APP online version. On one hand, the online version of our AI-103 exam questions can apply in all kinds of the eletronic devices. In addition, the online version of our AI-103 training materials can work in an offline state. If you buy our products, you have the chance to use our study materials for preparing your exam when you are in an offline state. We believe that you will like the online version of our AI-103 Exam Questions.
Latest AI-103 Demo: https://www.test4sure.com/AI-103-pass4sure-vce.html